google sheet sort fundamentally revolutionizes how we perceive raw numerical chaos, transforming scattered digital information into breathtaking masterpieces of absolute clarity. Across modern workspaces, the journey of data organization has evolved dynamically from dusty, leather-bound accounting ledgers into lightning-fast, collaborative cloud environments where a single command can orchestrate thousands of complex variables.
When you align rows and columns with precision, you are not merely organizing numbers; you are actively reshaping cognitive perception and uncovering profound insights hidden beneath the surface. As we investigate these sophisticated computational frameworks, you will discover the transformative power of systematic sequencing, unlocking unprecedented levels of productivity and structural harmony within your daily workflow.
How arranging digital spreadsheets transforms chaotic data into harmonious digital masterpieces

Source: softwareaccountant.com
Every digital dataset begins its life as a wild frontier of unbridled numbers, stray characters, and misplaced decimal points. When left to accumulate without structure, information behaves much like a physical storm, burying critical insights beneath layers of digital debris. Transforming this raw, untamed chaos into a sleek, functional matrix requires more than basic data entry; it demands an architectural vision that elevates raw figures into a symphony of actionable intelligence.
Visual alignment fundamentally alters human cognitive perception by leveraging the brain’s innate preference for pattern recognition and spatial harmony. When rows and columns are meticulously arranged, cognitive load drops precipitously, allowing the human eye to parse complex relationships in milliseconds rather than minutes. Traditional psychology of perception dictates that proximity and alignment signal relationship; thus, disciplined grids trick our neural pathways into processing massive arrays of numbers as a unified, coherent narrative.
Instead of forcing the cerebral cortex to hunt for anomalies across a sprawling wasteland of unformatted cells, structured layouts create visual pathways that guide decision-makers directly to core trends, outliers, and operational bottlenecks. This spatial choreography turns intimidating statistical mountains into accessible foothills, drastically reducing mental fatigue and error rates in high-stakes corporate environments. As the eye sweeps across uniform typography and balanced cell padding, the brain ceases its defensive struggle against clutter and instead enters a state of focused clarity, where strategic insights emerge naturally from the visual rhythm of the page.
The journey of spreadsheet organization spans centuries, evolving from the tangible weight of physical parchment to the instantaneous velocity of cloud computing. Long before the glowing monitor existed, scribes and merchants relied on heavy ledger books bound in leather, utilizing hand-ruled ink columns to balance trade deficits and track inventory assets. Every adjustment required painstaking recalculation, and a single spilled drop of ink meant hours of meticulous correction.
The dawn of the personal computer era shattered these physical constraints with the introduction of electronic grid software, replacing physical pages with static computer screens that could calculate formulas automatically. However, these early digital files remained trapped on local hard drives, vulnerable to hardware failures and isolated from collaborative workflows. Today, modern cloud grids dissolve geographical boundaries entirely, transforming spreadsheets into living, breathing ecosystems where global teams can manipulate millions of data points simultaneously in real-time.
This historical trajectory reflects humanity’s relentless drive to conquer complexity, turning rigid paper ledgers into fluid, intelligent canvases that power the global economy.
Historical evolution of spreadsheet organization from ledger books to modern cloud grids
The progression of data management reflects the relentless human quest for speed, accuracy, and collaborative synergy across technological eras. To understand how contemporary cloud architectures handle massive datasets, one must trace the milestones that transitioned humanity from physical ink to distributed server networks.
- The era of physical ledgers dominated international commerce for centuries, relying on manual ink entries, physical index tabs, and human calculation to audit financial transactions.
- The software revolution introduced desktop electronic grids in the late twentieth century, liberating professionals from manual math but locking files inside isolated desktop environments.
- The contemporary cloud computing paradigm integrates distributed processing, real-time multi-user editing, and automated algorithmic sorting into browser-based environments accessible from any corner of the globe.
Reviewing the operational differences between human-driven organization and machine-driven processing reveals why technological adoption is essential for modern enterprise scalability.
| Metric | Manual Sorting Methods | Automated Algorithms |
|---|---|---|
| Processing Speed | Hours of painstaking human review and physical manipulation. | Milliseconds of computational execution for millions of rows. |
| Error Rate | High susceptibility to human fatigue, distraction, and typo generation. | Zero deviation, ensuring absolute consistency across identical datasets. |
| Scalability | Severely limited by human stamina and physical screen or paper space. | Virtually limitless, capable of handling petabytes of distributed data. |
Imagine a sprawling, desolate digital wasteland where millions of rogue data points float aimlessly in a suffocating fog of mismatched fonts, garbled timestamps, and fragmented customer records. Suddenly, a powerful algorithmic pulse sweeps across the virtual canvas, instantly magnetizing the chaos into a breathtaking, perfectly balanced matrix. Harsh, glaring empty cells dissolve, replaced by alternating bands of serene turquoise and crisp, breathable white rows that stretch infinitely into the horizon.
Every numerical value snaps into its rightful column, aligned with mathematical precision, while headers glow with authoritative clarity. The once-deafening digital noise subsides into a serene, architectural masterpiece of information, proving that raw data, when properly disciplined, possesses a stunning aesthetic beauty all its own.
Precision in data arrangement is the silent architect of enterprise success, turning chaotic numbers into a definitive compass for the future.
Unleashing the hidden mathematical sequencing powers inside collaborative cloud-based workbooks

Source: surferseo.art
Mastering google sheet sort transforms chaotic data into a vibrant, structured masterpiece of clarity. Yet, true organization demands security, making cell protection excel techniques vital safeguards for your hard work against accidental chaos. Once your critical information remains safely locked away, you can seamlessly return to perfecting your google sheet sort for ultimate productivity.
Beneath the clean interface of modern cloud-hosted grids lies a sophisticated computational engine engineered to process millions of data points simultaneously. When multiple team members interact with shared financial ledgers, the underlying infrastructure executes complex algorithmic sorting protocols to transform raw values into intelligible patterns.
The computational mechanics governing ascending and descending row rearrangements rely heavily on sorting algorithms optimized for distributed memory architecture, such as Timsort or parallelized quicksort variants. When a user commands a range to sequence, the browser communicates through secure WebSockets to remote server clusters where the heavy lifting occurs. The engine first evaluates the data types within the selected column, identifying whether the inputs are numeric floating points, chronological timestamps, or localized text strings.
For ascending configurations, the algorithm maps out a permutation vector that establishes a strictly non-decreasing sequence, assigning each row an index based on numerical magnitude or alphabetical Unicode values. Descending operations invert this permutation vector, placing the highest numerical values or reverse-alphabetical text at the apex of the viewport. In collaborative environments, operational transformation protocols ensure that these sorting actions are safely queued and broadcasted across all active client sessions in real time.
This synchronization prevents race conditions where simultaneous edits might corrupt the structural integrity of the dataset. As the backend recalculates cell references, dependent formulas dynamically adjust their pointer offsets, ensuring that sum totals and percentage variances remain mathematically accurate despite the spatial relocation of individual records.
Psychological comfort experienced during financial analysis
Navigating through chaotic, unorganized fiscal reports often triggers cognitive fatigue and decision paralysis among corporate analysts. Establishing structural clarity through systematic data organization profoundly impacts mental well-being and analytical focus.
- Reduction of visual clutter immediately lowers cortisol levels, allowing analysts to interpret performance metrics without sensory distraction.
- Predictable vertical progression fosters a sense of cognitive control, mitigating the anxiety associated with missing critical budget discrepancies.
- Logical alignment of revenue streams and expenditure columns builds an intuitive mental model, accelerating the speed of executive decision-making.
- Elimination of manual scanning fatigue preserves mental stamina during high-pressure quarterly earnings audits and multi-million-dollar forecasting sessions.
Philosophical perspective on structure and disorder, Google sheet sort
True progress in data architecture is not the eradication of chaos, but the mastery of the invisible threads that bind disorderly numbers into harmonious truth.
Keyboard navigation sequences for multi-level range restructuring
Executing complex data restructuring operations without relying on peripheral input devices demands precise tactile execution and adherence to standard accessibility shortcuts. Mastering these keystrokes transforms routine data grooming into a fluid, uninterrupted workflow.
To initiate a multi-level range restructuring using strictly keyboard commands within a modern spreadsheet application, begin by navigating to the target data table. Depress the Control key alongside the A key on Windows, or Command plus A on macOS, to highlight the active data region. Next, summon the sorting menu by pressing Alt plus D followed by S on Windows, or by accessing the top application menu via Control plus Option plus M on macOS to open the contextual range management interface.
Mastering a quick google sheet sort transforms chaotic rows into crystal clear insights, empowering your workflow with brilliant momentum. Picture seamlessly navigating intricate details by deploying a tailored na company legal tracker customer framework directly into your workspace. Ultimately, returning to a dependable google sheet sort ensures every critical data point shines brightly on your screen.
Within the dialog box, use the Tab key to cycle through the primary sort criteria dropdown menus. Press the Alt key combined with the Down Arrow to expand the sorting options, allowing the selection of the primary column by utilizing the up and down arrow keys. To introduce secondary and tertiary sorting parameters, tab forward to the add another sort column button and activate it by pressing the Spacebar.
Once all hierarchical levels are properly configured, press the Enter key to commit the computational sequence, instantly triggering the backend algorithm to rearrange the dataset across the collaborative cloud architecture.
Decoding the secret syntax of dynamic formula-driven row sequencing without touching menus

Source: geeksforgeeks.org
The evolution of modern digital architecture has fundamentally shifted how professionals interact with vast arrays of information, replacing manual point-and-click interface navigation with the elegant precision of computational logic. Beneath the clean, static surface of every collaborative cloud grid lies a pulsing engine of mathematical sequencing, waiting to transform chaotic records into pristine hierarchies through the sheer force of formula syntax.
Master analysts no longer rely on mouse-driven drop-down menus; instead, they command the canvas using targeted expressions that dictate exactly how rows cascade, intersect, and align.
When engineering advanced spreadsheets, function arguments act as the ultimate architects of data hierarchy, translating human intent into strict computational laws. Every parameter passed into a sorting function carries immense weight, dictating not merely the direction of the arrangement, but the multi-layered priority by which disparate data points establish their vertical dominance. Understanding this precise syntax unlocks an invisible layer of control, turning static rows into living, breathing ecosystems of synchronized intelligence that react instantly to real-time inputs without requiring a single manual keystroke.
Functional mechanics of hierarchical data arrangement
The anatomy of a dynamic sorting function relies on a tripartite structure where data ranges, sort indices, and ascending or descending boolean values collaborate in strict sequence. The primary argument establishes the source array, capturing every cell that requires evaluation. Following this, the secondary argument, known as the sort index, points the grid engine toward the specific column number—represented by an integer rather than a letter—that will serve as the compass for the entire operation.
If an analyst wishes to sort by the fourth column of a designated range, the function demands the numeral four, ignoring traditional grid coordinates to maintain mathematical purity.
The hierarchy deepens exponentially when introducing tertiary arguments, which dictate the sorting direction through binary logic. Entering a value of true enforces an ascending cascade from the lowest numerical value or earliest alphabetical character to the highest, whereas false commands a descending plunge. In advanced scenarios involving multi-column sorting, arrays of indices and sort orders can be nested inside curly braces, forcing the computational engine to evaluate secondary and tertiary conditions simultaneously.
For instance, sorting a corporate roster first by department ascending, and then by salary descending, requires an array within the argument structure that tells the engine precisely which rule takes precedence when primary values match identically. Function arguments thus act as a strict legal code for the spreadsheet, leaving no room for ambiguity as millions of calculations execute in milliseconds across cloud servers.
To visualize the architectural impact of these arguments, picture a massive, high-contrast digital dashboard glowing against the dark glass of a high-rise office window at midnight. Vibrant cyan and emerald rows of financial data ripple and slide into place across the screen like cascading columns of digital rain, instantly snapping from disorganized chaos into perfect mathematical alignment the exact microsecond a closing parenthesis is added to the formula bar.
The visual feedback is immediate, hypnotic, and entirely automated, painting a picture of absolute operational harmony driven purely by textual syntax rather than physical mouse manipulation.
| Syntax Variation | Output Behavior | Error Type | Fallback Solution |
|---|---|---|---|
=SORT(A2:D100, 2, TRUE) |
Arranges the dataset in ascending order based on the values in the second column. | #VALUE! if the range contains mismatched data types. | Wrap the sort range in an IFERROR wrapper or clean the column data types. |
=SORT(A2:D100, 2, 3, TRUE, FALSE) |
Executes a multi-level sort, ordering column 2 ascending and column 3 descending. | #N/A if array dimensions mismatch or arguments contain uneven lengths. | Ensure all nested array brackets match precisely in dimension and criteria count. |
=SORT(A2:D100, 5, TRUE) |
Attempts to sort by a non-existent fifth column within a four-column range. | #REF! due to an out-of-bounds column reference index. | Adjust the index number to correspond with a valid column inside the array. |
Operational crisis management through nested computational logic
The true power of formula-driven sequencing reveals itself not in calm, controlled environments, but during moments of high-stakes operational crisis when traditional interface menus fail under the crushing weight of emergency data processing. Consider a tense scenario at a major global logistics hub during an annual end-of-quarter midnight inventory audit. A corrupted database export had dumped forty thousand rows of unorganized stock numbers, erratic timestamps, and fragmented fulfillment statuses into a single cloud spreadsheet just two hours before the federal compliance deadline.
The visual scene inside the control room was palpable: exhausted auditors pacing under harsh fluorescent lights, coffee cups multiplying on desks, and the standard point-and-click sorting menus freezing entirely due to the sheer volume of unsorted records clashing with live cloud synchronization protocols.
Manual sorting was completely dead; every attempt to use the graphical interface resulted in a spinning loading wheel and a dreaded browser timeout error. Amidst the rising panic, a senior data engineer leaned over the glowing terminal and bypassed the frozen menus entirely, deploying a masterclass in nested formula architecture. By combining dynamic sorting logic with filtering parameters directly into a single cell, the engineer commanded the grid to isolate damaged SKUs, sequence them by critical priority weight, and push them to the top of the spreadsheet in one unbroken computational breath.
The formula sliced through the digital noise like a scalpel, ignoring corrupt rows while instantly restructuring the remaining inventory items into a flawless, auditable hierarchy.
Precision in syntax is the ultimate antidote to procedural chaos, transforming a frozen, unresponsive workspace into an instantaneous engine of absolute operational clarity.
Within seconds, the chaotic wall of data stabilized into glowing green rows of verified inventory, saving the facility from catastrophic compliance penalties and countless hours of manual reconstruction. The midnight audit was rescued not by hardware upgrades or IT intervention, but by the quiet, unyielding power of formula syntax operating beneath the user interface.
Understanding how the spreadsheet engine evaluates individual characters requires examining the strict logical tests executed beneath the grid’s surface. Before any visual arrangement occurs, the underlying processor performs a rigorous series of evaluations to categorize and weigh every single entry.
- The grid engine initiates a type-check protocol, scanning every cell to distinguish between strict numeric digits, boolean values, error codes, and text strings.
- For text strings, the engine strips formatting and evaluates character values based on strict Unicode sequence standards, ensuring capital and lowercase letters adhere to predetermined collation rules.
- Numerical values bypass alphabetical collation entirely, weighed instead by their absolute mathematical magnitude rather than string length.
- Mixed data columns trigger an automatic hierarchy rule where numbers are consistently prioritized above text strings, preventing calculation faults during sorting operations.
- Blank cells and empty strings are evaluated last, automatically relegated to the bottom of ascending sequences or the top of descending sequences unless explicitly filtered out by preceding logical arguments.
Protecting interdependent cell relationships while executing massive structural data realignments
In the quiet ecosystem of a shared cloud workspace, a single uncoordinated click can trigger a silent avalanche across thousands of financial records and operational metrics. Maintaining absolute integrity across connected rows is the defining line between seamless collaborative intelligence and catastrophic systemic failure in modern digital operations.
Executing a large-scale data reordering operation without proper boundaries often results in a terrifying cascading fracture throughout the entire workbook architecture. Imagine a dense project management ledger tracking global supply chains, where thousands of inventory units, shipping dates, and financial valuations rely on precise row-by-row alignment. When an operator inadvertently selects only a single primary column of dates to sort—perhaps attempting to chronologicalize a delivery schedule—while leaving the adjacent revenue columns and client identifiers completely unselected, the grid undergoes instant data corruption.
The shipping dates effortlessly slide to the top, but the corresponding invoice numbers, supplier names, and capital allocations remain stubbornly anchored in their original geographic spots. Within milliseconds, millions of dollars in financial forecasts are hopelessly mismatched, matching multi-million-dollar purchase orders with entirely unrelated vendors. This silent disaster goes unnoticed until automated reporting scripts generate wildly impossible financial deficits, leading to halted shipments, furious stakeholders, and hours of painstaking manual forensic auditing to reconstruct the fractured database.
Preventative measures for structural grid integrity
Deploying strict defensive protocols before initiating any structural shift guarantees that relational dependencies remain completely unbroken and safeguarded against accidental sorting anomalies.
- Enforce complete range selection manually or programmatically across every populated column before activating the sort menu to prevent single-column isolation.
- Establish named ranges and freeze header rows to create rigid visual and computational boundaries that restrict sorting functions from disrupting top-tier metadata.
- Utilize native data protection settings in cloud-based spreadsheets to lock critical historical archives against unauthorized or accidental ad-hoc sorting modifications.
- Generate real-time cryptographic version backups or automated revision history checkpoints immediately prior to executing complex multi-tiered sorting algorithms.
- Audit all dependent cross-sheet references to ensure external formulas are insulated from local sheet reordering sequences.
Understanding how different referencing mechanisms behave during a shuffle is vital for preserving the mathematical heartbeat of an advanced cloud workbook. The following comparison highlights the structural mechanics of various cell linking strategies during a live sort operation.
| Reference Type | Behavior During Grid Shuffle | Structural Vulnerability |
|---|---|---|
| Locked Ranges | Boundaries remain stationary while internal rows reorder according to defined multi-column sort keys. | High risk of boundary truncation if sorting parameters do not encompass the entire defined array. |
| Floating Formulas | Cell coordinates adapt dynamically relative to the new physical position of the parent row. | Extremely susceptible to orphan errors if adjacent lookup tables are displaced during the shuffle. |
| Absolute References | Pointers remain rigidly fixed to exact coordinate addresses regardless of surrounding row movement. | Can cause severe logical disconnects by pulling static data into newly repositioned calculation streams. |
Visualizing the aftermath of a properly executed structural realignment reveals a stunning transformation across the digital canvas. Consider a master project timeline mapping the simultaneous construction phases of three international architectural marvels across a vast grid of fifty thousand rows. When the primary milestone date column is meticulously sorted in ascending order alongside its securely bound resource and budgetary companions, the visual cascade is breathtaking.
The chaotic, jagged landscape of overlapping deadlines instantly snaps into a sleek, harmonious chronological cascade, resembling an immaculate waterfall of synchronized progress bars. Gantt-style conditional formatting rules ripple downward in clean, descending gradients of vibrant blues and greens, perfectly illustrating the seamless transition from foundational excavation phases straight through to final structural glazing. Every dependent budget projection, labor allocation metric, and material procurement tracker glides fluidly into its new chronological home without dropping a single decimal point, proving that mathematical precision and visual elegance can coexist perfectly within the cloud.
Mastering a quick google sheet sort brings crystal-clear order to chaotic rows, perfectly mirroring how evaluating choices through springly vs bloomerang empowers nonprofits to streamline donor tracking. Embracing these brilliant organizational shifts transforms overwhelming data landscapes into inspiring pathways for success, ensuring every digital workspace remains beautifully structured and efficiently optimized for your next big breakthrough.
=ARRAYFORMULA(SORT(IF(ISBLANK(A2:Z), “”, A2:Z), 1, TRUE))
Orchestrating multi-tiered hierarchy parameters to establish intricate parent-child data ecosystems
Stepping beyond the realm of basic row arrangements reveals a sophisticated digital landscape where information behaves less like static text and more like living architecture. When thousands of global transactions intersect within cloud-hosted sheets, relying on a single sorting rule invites operational chaos. Mastering the art of multi-tiered hierarchy parameters transforms disjointed records into resilient parent-child ecosystems, breathing logic and clarity into massive operational matrices.
Building this level of structural integrity demands a deliberate shift in cognitive strategy. Analysts must mentally visualize data not as a flat grid, but as a cascading tree where every parent node anchors multiple dependent branches. Prioritizing secondary and tertiary sorting criteria requires a disciplined mental framework that anticipates how downstream decisions cascade upward through the entire workbook.
Cognitive Architecture for Multi-Level Sorting Hierarchies
Approaching complex data sorting demands a rigorous analytical mindset capable of holding multiple operational dimensions in active memory simultaneously. The human brain naturally gravitates toward linear patterns, yet effective spreadsheet engineering requires an architectural perspective that weighs trade-offs between overarching corporate objectives and granular record categorization. When establishing a three-tier sorting protocol, an analyst must first dissect the macro-level objective—such as quarterly regional profitability—before identifying the exact operational levers that drive those numbers.
The cognitive load intensifies when transitioning from the primary anchor to secondary and tertiary parameters. This mental process relies heavily on deductive prioritization, forcing the architect to ask which variables hold absolute systemic weight versus those that merely refine local performance. For instance, if the primary sort organizes data by geographical region, the secondary sort might evaluate product lines, while the tertiary sort addresses inventory turnover rates.
Navigating this hierarchy without disrupting dependent cell formulas requires deep mental mapping of how data groups interact under pressure. An error in judgment at the tertiary level can inadvertently fracture parent-child relationships, rendering subsequent calculations entirely invalid. Developing this mental acuity transforms the spreadsheet from a passive ledger into a dynamic diagnostic instrument.
Accurate primary keys serve as the immutable anchor of any enterprise-grade dataset; without an uncompromising, error-free identifier at the structural foundation, every subsequent secondary and tertiary sorting rule merely compounds existing anomalies into systemic operational failure.
Mastering data organization through a precise google sheet sort transforms chaotic spreadsheets into crystal clear insights, much like streamlining your digital correspondence during the anytime mailbox black friday sale where every urgent message finds its proper home. Ultimately, embracing this clean structure empowers your daily workflow, ensuring that every upcoming analytical project benefits from a perfectly executed google sheet sort.
Operational complexity in modern enterprises frequently demands simultaneous execution of three-tiered sorting logic to maintain regulatory compliance, logistical efficiency, and financial accountability. Department heads across various industries rely on this exact sequencing to interpret sprawling, high-stakes datasets without manual intervention.
- Global supply chain directors sequence inventory sheets by fulfillment hub as the primary criterion, transit urgency as the secondary condition, and supplier reliability score as the tertiary rule to prevent critical stockouts.
- Corporate finance leaders organize global expense reports by fiscal quarter first, departmental cost center second, and individual expense approval status third to accelerate audit procedures.
- Human resources executives structure workforce databases by office location as the primary anchor, performance review tier as the secondary condition, and tenure length as the tertiary parameter for targeted talent retention initiatives.
Translating these multi-tiered parameters into a functional digital workspace requires a clear visual and logical roadmap. The following matrix illustrates how distinct criteria interact across a responsive data ecosystem to produce harmonious, highly organized outcomes.
| Primary Criteria | Secondary Conditions | Tertiary Sorting Rules | Final Visual Outcomes |
|---|---|---|---|
| Geographic Region (Ascending A-Z) | Product Category (Alphabetical) | Sales Volume (Descending High-Low) | Regional clusters cleanly separated with top-performing products grouped visibly at the top of each category. |
| Fiscal Quarter (Chronological) | Cost Center ID (Numerical) | Expense Amount (Descending High-Low) | Budgets grouped by time period, systematically detailed by department, highlighting largest expenditures instantly. |
| Fulfillment Hub (Alphabetical) | Shipping Priority (Urgent to Standard) | Inventory Weight (Ascending Light-Heavy) | Operational hubs clearly isolated, immediately prioritizing expedited dispatches sorted by logistical load. |
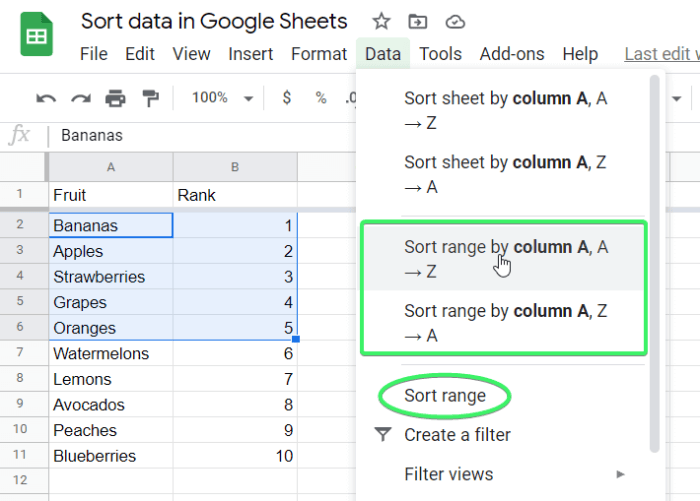
Automating repetitive data realignment routines through customized script architectures and macro triggers: Google Sheet Sort
Source: coupler.io
The dawn of every business day brings a familiar ritual of digital preparation, where raw, unrefined streams of information demand immediate structural order before corporate decisions can take shape. Eliminating the friction of manual curation requires transitioning from routine button-clicking to intelligent, behind-the-scenes orchestration that protects data integrity from the fatigue of repetitive human intervention.
Background automation serves as the ultimate safeguard against the inevitable oversights that plague manual morning recordkeeping tasks. When operational teams rely solely on human memory to execute daily sorting routines, misplaced rows, broken formula references, and skipped parameters inevitably creep into the workflow, compounding over time into costly discrepancies. By deploying customized script architectures, organizations remove the margin for human error entirely.
As the clock strikes the designated hour, cloud-based triggers execute meticulously tested sorting algorithms in milliseconds, ensuring that inventory levels, financial ledgers, and attendance logs align perfectly before the first team member opens the interface. This invisible layer of algorithmic precision guarantees that every single data point resides precisely where it belongs, fostering absolute trust in organizational reporting without requiring a single keystroke from the staff.
True operational excellence is achieved when the infrastructure works silently in the background, transforming chaos into clarity before human eyes even witness the dashboard.
Operational execution sequence for initialization triggers
Establishing a seamless morning routine relies on a precise sequence of logical events that occur the moment a cloud-based workbook is accessed. The following execution framework details how background code interprets user presence and initiates structural realignment safely and instantaneously.
- The authentication token verifies user credentials upon document access, initiating the secure loading phase of the cloud workbook interface.
- The active sheet environment fires an initialization event listener, signaling the underlying script engine that the document is fully rendered and ready for processing.
- The custom sorting algorithm evaluates current timestamp markers against the last recorded modification to determine if a fresh daily realignment cycle is necessary.
- Data arrays are ingested into memory, bypassing sluggish cell-by-cell interface rendering to optimize processing speed during massive structural reordering.
- Multi-tiered hierarchy rules are applied sequentially, locking parent-child relationships in place while subordinate rows cascade into their designated chronological or alphabetical positions.
- The finalized array writes back to the active worksheet in a single transaction, refreshing the visual display while logging a success status in the administrative audit trail.
Midnight data synchronization architecture
Deep within the subterranean levels of the enterprise data center, the physical environment hums with a steady, low-frequency resonance. Rows of sleek black server racks stand in rigid formation, their internal cooling fans spinning in synchronized harmony to maintain a crisp, climate-controlled chill. Tiny emerald green LED status indicators pulse in steady rhythms, casting fleeting reflections against polished metallic chassis panels.
Inside these densely packed silicon processors, a silent storm of electrons executes a background script across thousands of global sales figures simultaneously. Without a single human hand touching a mouse, incoming transactional data streams from Tokyo, London, and New York are instantly evaluated, cross-referenced, and sorted into pristine hierarchical ledgers. The architecture operates with ruthless efficiency, realigning millions of data cells in the blink of an eye, preparing a flawless landscape of synchronized analytics long before the sun rises over the first regional office.
Methodology comparison for document realignment systems
Choosing the appropriate structural realignment technique depends heavily on operational scale, maintenance overhead, and the complexity of interdependent cell relationships across modern collaborative workbooks.
| Evaluation Criteria | Manual Menu Clicks | Macro Recordings | Custom Coded Automation Loops |
|---|---|---|---|
| Execution Speed | Slow; highly dependent on human reaction time and interface loading delays. | Moderate; mimics interface navigation steps sequentially at fixed speeds. | Instantaneous; processes entire data arrays directly within server memory. |
| Error Vulnerability | High; frequent typos, accidental range selections, and skipped sorting tiers. | Medium; brittle when interface layouts change or column headers shift. | Near Zero; handles dynamic exceptions and validates arrays programmatically. |
| Scalability | Poor; unsustainable for large datasets exceeding thousands of rows daily. | Limited; struggles with variable data volumes and cross-sheet dependencies. | Infinite; easily scales to millions of records across multiple cloud databases. |
Concluding Remarks
Mastering these advanced structural realignment techniques empowers you to conquer digital chaos with absolute confidence and unwavering precision. By embracing the brilliant synergy of automated formulas, multi-tiered hierarchies, and custom scripts, you elevate your data management from a tedious chore into a powerful engine of visionary success.
