remedy ticketing system stands at the pulsing heart of modern enterprise service management, bridging the chasm between operational chaos and absolute synchronization. Across sprawling corporate landscapes, support engineers navigate complex digital ecosystems where every single incoming request carries the weight of business continuity. We embark on a journey through the intricate machinery of advanced IT service desks, where lines of code and structured databases breathe order into relentless floods of user issues.
Behind the glossy interface lies a sophisticated architecture designed to alleviate human fatigue and streamline every workflow. Practitioners continually dissect the mechanics of asynchronous routing, ergonomic interface layouts, and resilient cloud containers that keep global enterprises humming. As organizations balance fiscal realities with stringent security mandates, understanding these underlying dynamics becomes paramount for sustained technological evolution and peak productivity.
Practitioners frequently debate how BMC Remedy transforms chaotic helpdesk environments into synchronized operational hubs

Source: express-desk.com
Modern enterprise ecosystems constantly battle the relentless influx of IT support requests, where uncoordinated trouble tickets historically triggered massive operational bottlenecks. Within high-stakes corporate environments, the transition from fragmented support desks to streamlined command centers relies heavily on advanced architectural engineering and intelligent automation. Industry professionals continuously analyze the mechanics that elevate standard IT service management platforms into mission-critical engines of productivity.
This evolution relies on eliminating manual intervention bottlenecks and optimizing underlying data layers to ensure instantaneous response capabilities during peak operational stress.
As enterprise helpdesks experience surges in incoming support tickets during peak operational hours, asynchronous ticket routing mechanisms act as the invisible backbone that preserves system stability. These intelligent distribution systems operate independently of immediate human intervention by utilizing background queue workers and event-driven architecture to ingest, parse, and assign incoming incidents. When thousands of end-users simultaneously report infrastructure anomalies, the asynchronous engine places payloads into persistent message queues, such as Apache Kafka or native database-backed queues, preventing thread starvation on application servers.
Background processing workers continuously poll these queues, applying predefined business rules, skill-based routing matrices, and machine learning classification models to dispatch tickets directly to the most qualified available technician. By decoupling the ticket submission action from the immediate routing execution, the platform absorbs massive traffic spikes without dropping requests or freezing the user interface. Human dispatchers no longer waste valuable minutes manually reviewing and assigning incoming queues, which drastically reduces mean-time-to-assignment metrics.
Furthermore, intelligent load balancing algorithms distribute workloads evenly across global support tiers, ensuring that operational latency remains practically negligible even when enterprise support volumes multiply exponentially during system-wide outages.
Intelligent asynchronous routing eliminates human bottlenecks, transforming frantic support desks into mathematically synchronized operational hubs.
Database Schema Optimization Techniques for Enterprise Helpdesks
Delivering sub-second query retrieval times across massive enterprise helpdesks managing millions of historical and active records requires rigorous database schema optimization. Enterprise-grade relational database management systems underpinning the platform leverage sophisticated indexing strategies, such as composite B-tree indexes on frequently filtered columns like incident status, assignment group, and creation timestamp. Partitioning strategies further enhance performance by dividing colossal transactional tables into smaller, more manageable physical segments based on date ranges or regional business units, which allows database engines to perform partition pruning during query execution.
Denormalization of specific reporting attributes reduces the necessity for expensive multi-table joins during real-time dashboard generation, significantly lowering CPU utilization on database servers. Caching frequently accessed configuration items and user profiles within distributed in-memory data grids minimizes disk I/O operations. Database administrators continuously analyze execution plans and apply table compression algorithms to optimize storage footprints while maintaining rapid read and write throughput during peak operational cycles.
The structural integrity and operational efficiency of enterprise service management platforms depend entirely on standardized categorization, prioritization, escalation, and resolution frameworks. The following structured comparison Artikels the foundational parameters governing enterprise ticket lifecycles across diverse operational tiers.
Modern service desks rely heavily on the remedy ticketing system to resolve critical IT hurdles efficiently. As organizations upgrade their digital infrastructure, leveraging a strategic netlify discount code empowers development teams to deploy scalable web solutions without exceeding budgets. Ultimately, mastering this financial optimization revitalizes workflow productivity, ensuring the remedy ticketing system remains the backbone of seamless enterprise operations.
| Incident Categorization Hierarchy | Priority Matrix Levels | Escalation Triggers | Resolution SLAs |
|---|---|---|---|
| Tier 1: Infrastructure, Software, Hardware, Network | Priority 1: Critical (Enterprise Outage) | Immediate Notification to Major Incident Manager | 1 Hour Resolution Window |
| Tier 2: Application Access, Database Errors, Peripheral Faults | Priority 2: High (Departmental Impact) | 50% SLA Time Elapsed Without Assignment | 4 Hours Resolution Window |
| Tier 3: General Inquiries, Software Installation Requests | Priority 3: Medium (Single User Operational Block) | 75% SLA Time Elapsed Pending Action | 8 Hours Resolution Window |
| Tier 4: Informational Guidance, Documentation Requests | Priority 4: Low (Minor Inconvenience) | 90% SLA Time Elapsed Approaching Breach | 24 Hours Resolution Window |
Visual Telemetry Patterns in Real-Time Agent Workload Distribution Dashboards
Observing real-time agent workload distribution through modern visual telemetry dashboards provides stakeholders with immediate, intuitive insights into floor-level operational health. The graphical interface utilizes dynamic heat maps and color-coded node networks to represent individual agent capacity, shifting fluidly from soothing emerald green for normal operational loads to amber and pulsing crimson as queue densities approach critical thresholds. Concentric circular progress meters pulsate gently to display active chat and ticket-handling ratios, allowing floor supervisors to instantly spot overworked specialists or underutilized support pods.
Modern service desks rely heavily on a robust remedy ticketing system to restore order amid digital chaos. Reporters note that when urgent technical roadblocks suddenly stall daily operations, professionals quickly dial the arterra.lt customer service phone number to unlock immediate solutions. Ultimately, combining dedicated human support with an efficient remedy ticketing system transforms frustrating hurdles into stepping stones for lasting success.
Interactive treemaps visually scale agent avatar blocks in direct proportion to their active incident counts and severity weights, creating a vivid topographical map of human capital deployment across the floor. As ticket influxes surge, animated particle streams flow across the digital canvas from incoming queue repositories toward specific departmental clusters, physically depicting the velocity and volume of operational demand in real time.
This rich visual storytelling empowers management teams to make instantaneous redistribution decisions without wading through dense numerical spreadsheets, maintaining absolute synchronization across the entire enterprise support ecosystem.
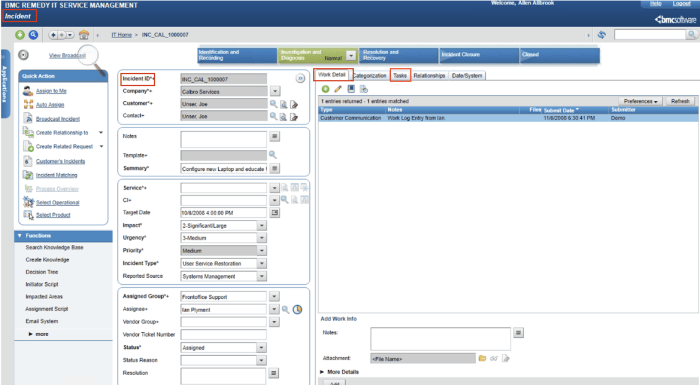
Organizations often overlook the hidden cognitive friction experienced by support engineers navigating legacy service management interfaces.
Source: mulesoft.com
Deep within the glowing boundaries of enterprise control rooms, analysts wage a silent war against outdated technology that drains their mental clarity and physical endurance. While corporate dashboards project an illusion of streamlined efficiency, the human operators behind the screens endure a daily barrage of antiquated software design choices. These legacy environments impose a heavy burden, turning routine incident resolution into an exhausting battle of endurance against poorly structured digital workspaces.
Modern workplace ergonomics extends far beyond adjustable chairs and standing desks, demanding a critical evaluation of the software architecture that demands thousands of daily mouse clicks and keystrokes from tier-two analysts. When user interfaces are cluttered with redundant data fields and fragmented navigation trees, engineers experience continuous micro-interruptions that fracture their focus and deplete their cognitive reserves. Addressing this invisible friction requires a fundamental redesign of digital workspaces to protect the physical and mental well-being of technical professionals.
Ergonomic Layout Philosophies for Physical and Ocular Health
Combatting the physical toll of high-intensity technical support requires implementing advanced ergonomic layout philosophies tailored specifically to reduce repetitive strain injuries and ocular fatigue among tier-two analysts. By strategically redesigning the spatial arrangement of enterprise service management interfaces, organizations can foster a healthier and more sustainable working environment.
Modern service desks rely heavily on the remedy ticketing system to resolve daily operational friction with clinical precision. Much like analyzing digital visibility through serpstat vs semrush vs ahrefs to uncover hidden growth metrics, tracking digital support queues transforms chaotic user requests into clear pathways for success, empowering teams to elevate organizational performance continuously through the remedy ticketing system.
Reducing physical strain starts with optimizing the visual hierarchy of the workspace. Designers utilize dark-mode aesthetics paired with high-contrast, adaptive color palettes to mitigate the damaging effects of blue light exposure during extended shifts. Studies from occupational health authorities indicate that reducing luminance contrast between the monitor and the surrounding environment decreases eye strain by up to forty percent. Furthermore, interface elements are meticulously mapped to natural gaze patterns, ensuring that critical telemetry data resides within the optimal central field of vision without requiring excessive head or neck movement.
Minimizing repetitive strain injuries demands a radical departure from mouse-dependent navigation through the integration of comprehensive, context-aware keyboard shortcuts and macro commands. When analysts can execute complex ticket routing and status updates through streamlined keystroke combinations, wrist and forearm muscles experience significantly fewer micro-movements. Ergonomic software design also incorporates fluid, touch-optimized target zones that adapt dynamically to user input methods, preventing the cramping and tendonitis frequently associated with relentless, pinpoint cursor placement across legacy multi-pane windows.
Designing digital infrastructure with human physiological limits in mind is not merely a comfort upgrade; it is a vital operational strategy that preserves organizational knowledge by preventing analyst burnout.
Procedural Workarounds for Restrictive Field Validation Rules
During catastrophic network outages, rigid software validation rules can transform a responsive ticketing platform into an administrative roadblock that delays critical incident resolution. When seconds dictate the boundary between minor disruption and catastrophic financial loss, support teams must rely on authorized procedural workarounds to bypass unnecessary data gatekeeping without compromising overall system integrity.
The following procedural adjustments provide safe, rapid pathways for entering urgent incident data when standard validation protocols threaten to stall emergency response efforts:
- Utilizing pre-scripted API ingestion templates allows engineers to inject raw JSON payloads directly into the incident database, completely bypassing front-end form validation scripts while preserving mandatory audit trail markers.
- Leveraging designated emergency override profiles grants temporary administrative clearance to submit tickets with placeholder characters in non-essential categorical fields, which are automatically flagged for mandatory post-incident data enrichment during the retrospective review phase.
- Deploying lightweight command-line interface utilities enables tier-two specialists to log core infrastructure failures using minimal-requirement syntax, securely bypassing complex graphical user interface trees until network stability is fully restored.
Psychological Impact of Audio-Visual Alert Fatigue
The relentless barrage of high-priority incident notifications within enterprise support suites inflicts a severe psychological toll on support engineers, manifesting as chronic stress, desensitization, and diminished situational awareness. When every minor network fluctuation triggers the same frantic audio-visual alarm as a catastrophic server failure, the human brain undergoes a process of sensory overload known as alert fatigue. Over time, analysts develop a physiological defense mechanism against the constant noise, inadvertently ignoring critical warnings buried beneath a mountain of false positives.
This perpetual state of hyper-vigilance keeps the central nervous system locked in a continuous fight-or-flight response, leading to emotional exhaustion and cognitive tunneling. Visual processing centers become overwhelmed by flashing banners and shifting color codes, while auditory cortices suffer from relentless chime repetition. Real-world implementations in major financial sector data centers have demonstrated that replacing indiscriminate audio alerts with contextually tiered haptic feedback and soft acoustic cues dramatically lowers resting heart rates among operators, restoring their capacity to accurately assess and prioritize genuine network emergencies.
Comprehensive Method for Customizing Notification Templates, Remedy ticketing system
Eliminating redundant text from notification templates transforms chaotic alert streams into precise, actionable streams of intelligence that empower rapid remediation. Modernizing these communication structures ensures that support engineers receive immediately digestible data without wading through walls of extraneous administrative metadata.
Implementing a streamlined notification architecture requires a deliberate, step-by-step approach to template refinement across the entire enterprise support suite:
- Audit all existing notification rules to catalog every triggered alert type, identifying and permanently deleting boilerplate legal disclaimers, redundant system signatures, and repetitive status text that adds zero operational value.
- Restructure the remaining informational hierarchy by placing the core error code, impacted service tier, and affected geographical region within the absolute first line of the notification payload for instantaneous comprehension.
- Integrate dynamic deep-link hyperlinking directly into the template body, allowing analysts to transition from the notification interface straight to the pre-filtered incident resolution console with a single interactive action.
- Incorporate automated remediation runbook suggestions as embedded, clickable command snippets within the notification layout, bridging the gap between problem identification and execution speed.
- Conduct controlled simulation testing by broadcasting synthetic high-priority incidents to a pilot group of tier-two engineers, measuring the time reduction achieved in reading, interpreting, and acknowledging the newly streamlined notification format.
Modern enterprise architects continually challenge traditional monolithic deployment models in favor of containerized incident management frameworks.

Source: xmatters.com
The digital nerve center of the modern enterprise rarely rests, driving technology leaders to rethink how helpdesk ecosystems handle relentless waves of user requests. Heavy, monolithic architectures that once anchored service management are giving way to agile, containerized frameworks where every incident response component breathes independently. Behind this structural shift lies a relentless pursuit of speed, resilience, and operational clarity that transforms rigid IT environments into living, breathing digital organisms.
Deploying distributed service desk microservices across sprawling hybrid cloud environments introduces profound engineering hurdles that demand meticulous operational oversight. When thousands of concurrent support tickets cascade through containerized clusters spanning private data centers and public cloud providers, network latency and state synchronization become critical fault lines. Orchestrating these dynamic workloads requires sophisticated traffic management and automated healing mechanisms to prevent cascading failures during peak operational hours.
Enterprise teams must navigate the delicate balance between resource autonomy and global coherence, ensuring that regional outages do not fracture the unified support landscape.
Orchestration Complexities in Hybrid Cloud Service Desk Environments
Managing microservice lifecycles across diverse infrastructure layers exposes hidden friction points in resource allocation and security governance. As support ticket volumes surge unpredictably, container orchestrators must rapidly provision pods without breaching strict compliance boundaries or exhausting underlying hypervisor capacities. Below is the operational baseline detailing the technical parameters required to maintain stability across distributed incident management nodes.
| Container Resource Allocation Thresholds | Memory Footprint Limits | CPU Throttling Metrics | Network Egress Boundaries |
|---|---|---|---|
| Standard tier: 2 vCPU, 4GB RAM per ticketing pod | Hard limit at 85% of allocated node memory capacity | Maximum allowable throttle time of 15ms per 100ms window | Strict limit of 1Gbps per cluster interconnect tunnel |
| Burst tier: 4 vCPU, 8GB RAM for high-volume queues | Warning threshold triggered at 70% utilization rate | Context switch latency capped below 2 microseconds | Isolated VLAN tagging for cross-region data replication |
| Background worker tier: 1 vCPU, 2GB RAM | Swap memory explicitly disabled to prevent latency spikes | CPU shares prioritized for real-time chat and alert ingestion | Encrypted TLS 1.3 tunnels for all external API calls |
Message Broker Synchronization Architecture Across Distributed Clusters
Bridging the geographical divide between disparate service desk nodes relies on resilient event-driven architectures powered by advanced message brokers. The following architectural blueprint details the precise data pathway utilized to achieve real-time state consistency across multi-region deployments.
- Edge ingestion nodes capture incoming incident telemetry and immediately serialize the payload into immutable JSON event streams.
- Distributed message brokers, configured in a multi-active replication mesh, ingest the streams and assign sequential vector clocks to guarantee causal ordering.
- Partition leaders across geographic zones consume the event streams, applying optimistic concurrency control to update local read replicas without locking the primary database.
- WebSocket gateways instantly push the synchronized ticket state to active support engineers, ensuring zero perceptible latency regardless of their physical location on the globe.
- Dead-letter queues automatically capture malformed or conflicted transactions, routing them to an automated remediation service while the main operational pipeline remains unaffected.
Automated Rolling Updates for Zero-Downtime Database Schema Migrations
Executing structural database changes while millions of active support sessions depend on uninterrupted uptime represents one of engineering’s most delicate balancing acts. Modern container platforms resolve this tension through backward-compatible schema evolutions paired with canary deployment strategies that shield end-users from underlying infrastructural shifts. When an enterprise like Global Logistics Inc. upgraded its core incident tracking database last quarter, the engineering division utilized a multi-phase expansion-migration-contraction pattern.
During the expansion phase, new nullable columns were introduced alongside legacy fields, allowing older microservice versions to write data without disruption. Subsequently, dual-write adapters synchronized incoming ticket attributes across both schema versions while background workers backfilled historical records. Finally, once all containerized service nodes were successfully upgraded to the new software release, the legacy database columns were safely decommissioned without dropping a single active connection or delaying a priority-one incident response.
Operational resilience is not achieved by eliminating failure, but by architecting systems that gracefully absorb turbulence and maintain continuous forward momentum.
When remedy ticketing system workflows stall under heavy burdens, visionary teams pivot toward integrated solutions. Introducing crm with inventory management bridges critical operational gaps with striking clarity and precision. By fusing customer insights with real-time stock tracking, organizations unlock unprecedented momentum, ensuring every remedy ticketing system request resolves swiftly to empower lasting enterprise success.
Security auditors scrutinize the cryptographic integrity safeguarding sensitive client credentials stored within historical incident logs

Source: slideserve.com
Deep inside the digital archives of enterprise support ecosystems, historical incident logs quietly record the mechanical heartbeat of corporate IT. Security evaluators now hold these repositories under a glaring magnifying glass, demanding absolute proof that hidden client passwords, API keys, and proprietary tokens remain shielded from prying eyes. Every completed ticket tells a story of resolution, yet it also risks exposing sensitive data remnants if left unprotected.
Modern service management platforms must evolve past simple storage lockers and function as impenetrable vaults where historical data rests securely. When compliance officers inspect archival dumps, they look beyond surface-level metrics to examine the raw mathematical defense mechanisms shielding valuable intellectual property. This rigorous examination ensures that past troubleshooting sessions never transform into future security vulnerabilities.
Role Based Access Control Paradigms for Intellectual Property Protection
Safeguarding proprietary source code, architectural blueprints, and confidential customer attachments hidden deep inside historical ticket attachments requires a meticulous multi-tiered defensive strategy. Within high-stakes enterprise environments, traditional flat-permission models fail completely because they often grant broad visibility across departmental boundaries. Role-based access control paradigms step into this breach by enforcing strict, context-aware boundaries that dictate precisely who can view, edit, or download sensitive proprietary intellectual property linked to specific service requests.
Imagine a digital fortress constructed with concentric walls; mere tier-one helpdesk personnel patrol the outer courtyards to address routine software glitches, while only senior security engineers and designated compliance officers possess the specialized cryptographic keys required to breach the inner sanctum housing proprietary client secrets. This architecture relies heavily on dynamic attribute-based evaluations, meaning system access adjusts automatically based on real-time factors such as the user’s geographic location, network security posture, and active clearance status.
Furthermore, granular permission matrices ensure that even if an internal user successfully opens a historical ticket detailing a critical infrastructure failure, any proprietary patch files or unmasked API credentials remain completely obscured behind secondary authorization prompts. Enterprises like financial institutions and healthcare providers implement these strict isolation boundaries to prevent lateral movement by malicious actors or compromised insider accounts. By stripping away default visibility and enforcing the principle of least privilege, organizations ensure that confidential attachments remain strictly confined to the authorized eyes explicitly cleared for that specific operational scope, thereby preserving enterprise trust and regulatory standing.
Cryptographic Hashing Algorithms for Archival Data Obfuscation
To prevent sensitive personally identifiable information from leaking during routine database backups or long-term archival exports, system administrators must transform raw text into unreadable mathematical signatures. The implementation of robust hashing mechanisms guarantees that historical records retain their utility for auditing purposes without exposing vulnerable personal data to unauthorized observers. The following cryptographic standards provide the foundational layer for modern archival data obfuscation:
- Secure Hash Algorithm 256-bit generates a unique fixed-size output that makes reversing the original user credentials computationally impossible for modern hardware.
- Secure Hash Algorithm 512-bit delivers an expanded digest length, providing an exceptionally high security margin against brute-force collision attacks in enterprise archives.
- BLAKE2b offers superior processing speeds alongside cryptographic strength, making it ideal for rapidly obscuring massive volumes of legacy service desk logs without degrading system performance.
- Argon2 serves as a memory-hard password hashing standard that successfully thwarts specialized hardware cracking attempts targeting historical credential dumps.
Forensic Audit Trails Generated During Service Level Agreement Overrides
When an administrator makes the executive decision to forcibly override an assigned service level agreement countdown timer, the platform instantly awakens its internal recording machinery to document the event. This administrative intervention bypasses standard operational flows, making it an event of extreme interest for compliance investigators tracking potential SLA manipulation. The resulting forensic audit trail captures a comprehensive, immutable ledger containing the exact timestamp of the override, the unique digital identifier of the administrator, and the mandatory justification code entered into the system prompt.
Behind the scenes, the database logs the pre-override timer state alongside the newly forced metric, creating a permanent delta that highlights the exact duration of the manual adjustment. Security information and event management systems ingest these specific log entries in real-time, cross-referencing them against active change management tickets to verify legitimate business necessity. For instance, in a real-world scenario involving a major telecommunications outage, an incident manager might legally override a closing timer to properly document a cascading network failure; the resulting audit trail instantly proves that standard operating procedures were respected despite the manual clock alteration.
This meticulous level of logging prevents internal fraud, ensures absolute accountability across IT leadership teams, and provides unassailable proof during external regulatory audits.
Immutable forensic trails transform administrative discretion from a blind spot into a transparent pillar of enterprise governance.
Compliance Checklist for Purging Obsolete Incident Records
Managing the lifecycle of enterprise data requires a delicate balance between maintaining operational history and complying with stringent global privacy mandates such as the General Data Protection Regulation and the California Consumer Privacy Act. Retaining obsolete client records past their legally mandated retention window introduces unnecessary liability and invites severe regulatory penalties. The implementation of a structured purging protocol ensures that historical databases remain lean, secure, and fully aligned with international privacy standards.
- Identify and classify all historical tickets containing personally identifiable information that have exceeded the statutory retention period established by regional legal frameworks.
- Verify that no active litigation holds, open compliance investigations, or pending customer disputes are currently tied to the targeted archival records.
- Execute cryptographically secure data shredding protocols that overwrite physical storage sectors multiple times to guarantee complete data irrecoverability.
- Generate and securely store a permanent compliance certificate detailing the exact timestamp, record count, and destruction methodology for auditing validation.
Enterprise finance directors regularly evaluate the total cost of ownership associated with maintaining on-premises incident tracking infrastructure versus managed cloud alternatives.
When the ledger meets the server room, the true cost of enterprise IT support reveals itself in layers far deeper than initial purchase orders suggest. Finance executives across major global corporations constantly weigh the heavy anchors of localized hardware against the agile horizons of cloud service models. Beneath the gleaming surface of corporate balance sheets lies a complex ecosystem of continuous capital expenditure and operational drain that demands rigorous financial dissection.
Transitioning from legacy localized servers to dynamic cloud frameworks requires a fundamental shift in how organizations perceive enterprise value and technological investment. Every hardware rack humming in a basement facility carries an invisible financial footprint that extends far beyond the original vendor invoice. Leadership teams must look past nominal software price tags to uncover the sustained monetary velocity required to keep mission-critical helpdesk environments operational day and night.
Comprehensive Calculation of Hidden Operational Expenditures
Uncovering the true financial gravity of on-premises incident tracking infrastructure demands a forensic examination of expenses that routinely evade standard quarterly budget reports. Hardware depreciation alone erodes asset value at an aggressive pace, often rendering enterprise-grade servers obsolete within a strict forty-eight-month window. This rapid decline is further compounded by the relentless electrical draw required to power and cool dense server deployments in climate-controlled facilities.
Specialized database administration personnel command top-tier salaries, yet a significant portion of their highly compensated hours is consumed by routine maintenance, emergency patching, and physical hardware replacement rather than strategic innovation.
True operational expenditure is not merely what an organization pays for an invoice, but the continuous financial hemorrhage sustained by maintaining aging physical assets in-house.
To accurately capture these hidden operational drains, enterprise accountants must factor in several critical cost components:
- Physical hardware depreciation curves scaling aggressively over standard multi-year fiscal depreciation schedules.
- Continuous power consumption and facility HVAC cooling overhead tied directly to rack density and server uptime requirements.
- Specialized database administration staffing costs, factoring in premium talent retention and emergency on-call compensation.
- Unplanned physical component failures requiring expedited shipping, emergency contractor deployment, and subsequent operational downtime.
Financial Amortization Timelines of Software Deployment Models
Evaluating the monetary trajectory of perpetual software licensing versus subscription-based software-as-a-service models exposes stark contrasts in corporate cash flow management. Perpetual licensing demands a massive upfront capital expenditure, locking organizations into legacy deployments while amortizing costs across five to seven years. Conversely, subscription models distribute expenses predictably across operating budgets, instantly scaling with organizational growth but carrying a perpetual financial obligation that accumulates significantly over long-term horizons.
Financial strategists analyze these divergent models through the lens of liquidity preservation and agility against long-term cumulative expenditure. While perpetual licenses eventually transition into maintenance-only phases, the compounding costs of internal support infrastructure often outpace the predictable, all-inclusive nature of modern cloud subscriptions. Organizations must carefully balance their immediate capital availability against long-term fiscal predictability when mapping out their multi-year software acquisition strategies.
Enterprise Incident Management Licensing Tiers and Operational Costs
Navigating the complex pricing matrices of enterprise service management platforms requires a granular understanding of user limits, API thresholds, and module scalability. The following comprehensive structural overview details standard industry pricing frameworks across various deployment tiers.
| Licensing Tier | Concurrent User Limits | External API Call Fees | Custom Development Module Pricing |
|---|---|---|---|
| Standard Enterprise | Up to 500 active users | $0.001 per request over baseline | $15,000 per bespoke module |
| Advanced Professional | Up to 2,500 active users | Included up to 5M monthly calls | $35,000 enterprise package |
| Global Unlimited | Enterprise-wide concurrent access | Unlimited frictionless throughput | Custom negotiated statement of work |
Financial Forecasting Methodology for Enterprise Helpdesk Expansion
Predicting the financial trajectory of a growing corporate helpdesk over a rolling thirty-six-month fiscal window requires a multi-variate algorithmic approach that accounts for workforce scaling, ticket volume velocity, and infrastructure elasticity. Organizations like global logistics leader DHL have successfully modeled similar expansions by integrating historical support ticket growth rates with predictive macroeconomic indicators. By establishing a baseline cost-per-ticket metric and correlating it with projected corporate headcount growth, financial directors can construct highly accurate rolling forecasts that mitigate budgetary surprises.
Implementing this forward-looking methodology involves mapping distinct operational variables into a cohesive predictive framework designed to adapt to shifting market conditions and internal restructuring.
- Establish historical cost baselines by dividing total annual helpdesk operational expenditure by the aggregate volume of resolved incidents.
- Incorporate projected enterprise headcount growth percentages into the algorithmic model to determine future concurrent user license scaling requirements.
- Factor in historical inflation indices and anticipated vendor subscription price adjustments over the targeted thirty-six-month forecasting horizon.
- Simulate various demand spikes, such as seasonal retail surges or major corporate acquisitions, to test the fiscal resilience of the projected budget model.
System administrators frequently encounter intricate dependency loops when integrating legacy customer relationship management platforms with contemporary helpdesk modules.
Bridging the architectural chasm between aging customer relationship frameworks and modern, agile helpdesk platforms often resembles performing open-heart surgery on a running locomotive. System administrators step into a high-stakes arena where every single API call carries the weight of operational continuity, battling fragile connection webs and rigid data schemas that refuse to speak the same digital language. Behind the sleek glass dashboards of contemporary incident management tools lie deeply entrenched, archaic databases that guard customer histories with stubborn persistence.
When unexpected support surges hit the digital queue, these patched-together integration points routinely threaten to collapse under the crushing weight of simultaneous data writes. Engineers must deploy sophisticated buffering mechanisms and razor-sharp parsing logic to ensure that a sudden influx of thousands of customer service requests transforms into an orderly, synchronized stream of actionable intelligence rather than cascading system failures.
Asynchronous Webhook Queuing Strategies for Massive Inbound Ticket Floods
Picture a torrential downpour hitting a dry, compacted landscape; without proper drainage channels, water simply erodes everything in its path. Similarly, when a massive inbound ticket flood strikes an enterprise helpdesk, synchronous direct database writes will instantly overwhelm server resources, trigger catastrophic connection timeouts, and drop critical customer communications into the digital abyss. To prevent these paralyzing data synchronization bottlenecks, resilient enterprise architectures rely on asynchronous webhook queuing strategies that act as intelligent shock absorbers for digital infrastructure.
At the heart of this resilient design is a decoupled message broker architecture, utilizing enterprise-grade queuing technologies like Apache Kafka or RabbitMQ. When an external CRM platform dispatches a webhook notification about a high-priority customer ticket, the modern helpdesk endpoint does not immediately process the transaction. Instead, it captures the raw payload, issues an instant HTTP 202 Accepted response back to the sender, and safely drops the event into a persistent, high-throughput message queue.
This rapid acknowledgment frees up inbound connection threads instantly, shielding the core application servers from traffic spikes.
Once safely inside the buffer, worker nodes consume the queued events at a controlled, sustainable rate that matches the underlying database’s maximum write capacity. If a sudden surge brings fifty thousand concurrent webhook events, the queue gracefully stretches, holding the data securely in distributed memory and disk storage until processing resources become available. This method introduces a profound operational shift, turning chaotic, unpredictable tidal waves of incoming support traffic into a steady, manageable flow of structured tasks.
Furthermore, these advanced queuing mechanisms incorporate exponential backoff retry algorithms and dead-letter exchanges. If a downstream database deadlock occurs while processing a specific ticket insertion, the worker node does not crash or discard the payload. It routes the failing message to a quarantine queue, systematically retries the operation after increasing intervals, and alerts system administrators without disrupting the broader flow of incoming service requests.
Resilient asynchronous queuing transforms volatile traffic spikes into predictable, controlled data streams, ensuring zero packet loss during peak operational hours.
Visualizing this process reveals a multi-tiered digital highway system. At the entry point, a load balancer distributes incoming webhook traffic across a cluster of stateless ingestion nodes. These nodes quickly serialize incoming JSON or XML payloads and push them into dedicated message queues separated by priority tiers. Downstream worker pools pull messages from these queues, execute data cleansing routines, and perform bulk database insertions, ensuring optimal throughput and absolute system stability under extreme loads.
Common API Authentication Handshake Failures and Programmatic Resolutions
Navigating the treacherous waters of cross-platform integration requires flawless security handshakes, yet administrative teams constantly stumble over silent authentication failures that halt data flow entirely. Securing the perimeter while maintaining seamless interoperability demands absolute precision in cryptographic validation and token lifecycle management.
-
Expired OAuth 2.0 Access Tokens: When an automated integration script attempts to push ticket updates using a token that has passed its expiration window, the authorization server rejects the request with a standard HTTP 401 Unauthorized status.
Programmatic Resolution: Implement an automatic interceptor pattern within the HTTP client library that catches 401 responses, utilizes a securely stored refresh token to request a fresh access credential from the authorization endpoint, and seamlessly replays the original failed transaction without human intervention. -
Cryptographic Signature Mismatches in HMAC Webhooks: Webhook providers sign payloads using a shared secret key via Hash-based Message Authentication Codes to verify authenticity, but slight deviations in raw body parsing or character encoding cause signature verification to fail, resulting in dropped events.
Programmatic Resolution: Configure the API middleware to capture the incoming payload strictly as an unparsed raw byte stream before any JSON body-parsing middleware alters the formatting, then compute the local HMAC hash using the exact same hashing algorithm for direct cryptographic comparison. -
Mutual TLS Certificate Chain Validation Failures: Enterprise environments enforcing strict zero-trust security utilize mutual TLS where both client and server exchange certificates, but outdated root certificate authorities or expired client certificates break the secure tunnel during the initial TCP handshake.
Programmatic Resolution: Establish an automated certificate monitoring daemon that tracks expiration dates thirty days in advance, coupled with an orchestration script that safely hot-swaps enterprise trust stores and reloads the API gateway without incurring system downtime.
Data Transformation Lifecycle for Hierarchical Payload Conversion
Legacy enterprise systems speak an older dialect of enterprise architecture, frequently wrapping critical customer incident data within deeply nested, verbose XML structures that modern relational and NoSQL databases cannot ingest natively. Transforming these bulky hierarchical documents into streamlined, flat JSON objects requires a rigorous, multi-stage data transformation lifecycle designed to strip away redundant markup while preserving structural integrity and relational context.
The transformation pipeline begins at the extraction phase, where the integration engine ingests the raw XML string from the legacy CRM export. The system passes this string through an event-based streaming parser, such as a Simple API for XML reader, which efficiently reads the document node by node without loading the entire heavy DOM tree into active memory. This prevents memory leaks when processing multi-megabyte enterprise payload exports containing thousands of historical ticket records.
Next, the parsing engine maps XML elements and attributes to a predefined schema model using an intermediate transformation mapping configuration. During this mapping phase, complex nested parent-child nodes—such as customer contact lists embedded within historical ticket logs—are flattened or restructured into clean, standardized arrays and key-value pairs suitable for modern JSON consumption. Data type casting also occurs at this juncture, converting string-represented boolean values, timestamps, and integer identifiers into their proper programmatic types to prevent downstream database schema validation errors.
Finally, the sanitized and flattened JSON payload undergoes a validation check against an enterprise schema definition language, such as JSON Schema, ensuring that all mandatory fields are present and correctly formatted. Once validated, the payload is serialized into a compact string format and transmitted to the database ingestion layer. This meticulous lifecycle guarantees that historical customer data is accurately preserved, easily searchable, and instantly accessible to support engineers operating within contemporary helpdesk environments.
Error Handling Protocol for Corrupted Hardware Identification Strings
External asset discovery tools are tireless digital watchdogs, constantly scanning enterprise networks and transmitting hardware inventory data directly into the service repository, but they are far from infallible. When a corrupted hardware identification string—such as a mangled MAC address containing illegal characters, a truncated serial number, or a null-padded asset tag—infiltrates the data pipeline, it can corrupt relational database integrity indexes and disrupt automated asset tracking workflows.
To neutralize this threat, the service repository enforces a strict, multi-layered error-handling protocol the exact moment an incoming asset payload crosses the ingestion boundary. The ingestion gateway passes every incoming hardware identifier through a rigorous regular expression validation filter designed to match only authorized format patterns. If the incoming string violates the expected schema rules, the integration framework immediately halts the direct ingestion pipeline for that specific record.
Instead of crashing the entire batch upload or inserting corrupted data into production tables, the system triggers a automated remediation workflow. The malformed payload is intercepted, encapsulated with detailed diagnostic metadata including the source IP of the discovery tool and the exact timestamp of failure, and safely routed to a dedicated quarantine table within the staging database. Simultaneously, the system generates an automated incident ticket assigned to the IT infrastructure monitoring team, detailing the specific syntax error detected in the hardware string.
Concurrently, the error-handling protocol attempts a programmatic healing heuristic for minor anomalies, such as stripping leading whitespace, correcting common optical character recognition typos in serial numbers, or normalizing case sensitivity. If the healing heuristic successfully rectifies the string, the record bypasses quarantine, undergoes a secondary validation pass, and successfully merges into the live configuration management database. This proactive protocol ensures that the central service repository remains pristine, reliable, and completely free of toxic data artifacts.
Ending Remarks: Remedy Ticketing System
Ultimately, mastering the architecture and financial realities of modern service management empowers organizations to turn potential operational bottlenecks into engines of resilience and growth. By blending cutting-edge cloud infrastructure with thoughtful user-centric design, enterprises secure both their data and their operational momentum. The path forward demands continuous adaptation, strategic foresight, and an unwavering commitment to operational excellence that ensures every ticket resolved brings the business one step closer to its highest aspirations.
