clay external api documentation push data to table serves as the vital digital gateway where chaotic streams of external information transform into orderly, actionable enterprise assets. In an era where modern organizations thrive on real-time intelligence, the ability to seamlessly bridge disparate third-party platforms with local storage infrastructure is no longer just a technical luxury—it is an absolute operational necessity.
We live in a fast-paced digital ecosystem where milliseconds matter, and establishing a robust pipeline for incoming data dictates whether a business surges ahead or lags behind the competition.
Navigating the intricacies of cryptographic handshakes, JSON schema mapping, and asynchronous webhook listeners can initially appear daunting, yet this journey unlocks unprecedented levels of system synchronization. Behind every successful automated record update lies a meticulously engineered architecture designed to withstand heavy traffic, filter out malicious payloads, and optimize bulk ingestion performance. By mastering these foundational integration principles, engineering teams can build resilient data ecosystems capable of scaling effortlessly alongside exponential business growth.
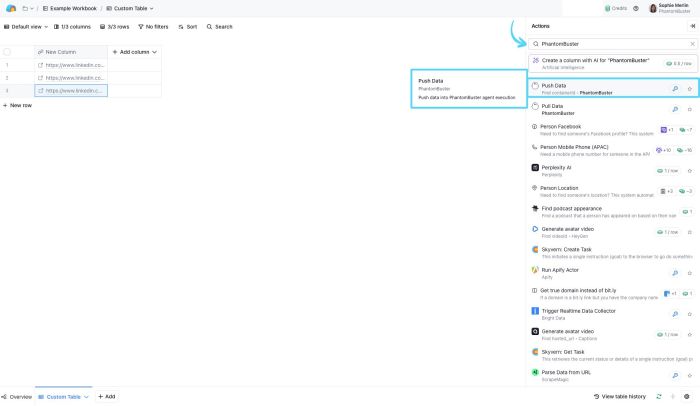
Establishing secure connections requires understanding how external services securely transmit payloads into your designated databases
Source: phantombuster.com
Modern data architecture demands an uncompromising guardian at the digital gates, ensuring that every byte crossing the threshold into your database is thoroughly vetted. When external services push payloads into your systems, establishing a fortified perimeter is the ultimate line of defense against malicious intrusion. Picture a high-security vault where every incoming delivery must present the exact cryptographic credentials before the heavy doors even begin to unlatch.
This operational reality transforms routine data ingestion into a sophisticated ballet of computational trust, where speed and safety walk hand in hand across the enterprise landscape.
Navigating this complex terrain means recognizing that data in transit is inherently vulnerable until proven otherwise. Without rigorous boundary controls, databases risk exposure to unauthorized injection attacks and spoofed transmissions that mimic legitimate traffic. Industry giants like Stripe and GitHub pioneered robust webhook delivery models precisely to combat these risks, proving that rigorous verification is non-negotiable for modern cloud infrastructure.
Implementing these safeguards protects sensitive records, maintains consumer trust, and preserves the absolute integrity of your foundational tables.
Cryptographic Handshake Procedures And Signature Verification
Safeguarding the entry point of your database begins long before any records are written, relying heavily on a meticulous cryptographic handshake. When an external service initiates a transmission, it signs the payload using a shared secret key via algorithms like HMAC-SHA256, generating a unique digital signature appended to the request headers. Your receiving server captures this incoming packet, isolates the payload, and independently recalculates the signature using its own identical secret key.
If the calculated signature matches the incoming header precisely, the handshake succeeds, confirming the data originated from a trusted source and remained unaltered in transit. Should a single bit differ, the system immediately rejects the transmission, locking out potential attackers before they can probe your database vulnerabilities.
Visualizing this defense mechanism in action reveals a multi-layered fortress where cryptographic keys act as dynamic passports. Imagine an armored transport arriving at a secure facility; the guards do not simply look at the vehicle, they scan a constantly evolving molecular seal that only the true manufacturer could produce. This exact philosophy drives modern API security standards across the financial and healthcare sectors.
Below is a detailed breakdown of the essential parameters, encryption ciphers, and expiration rules governing this validation process:
| Header Validation Parameters | Encryption Ciphers | Expiration Timestamps | Operational Status |
|---|---|---|---|
| X-Hub-Signature-256 | HMAC-SHA256 | 300 Seconds Max Drift | Active Enforcement |
| X-Signature-Timestamp | AES-256-GCM | Strict Epoch Validation | Real-time Auditing |
| Authorization-Bearer | RSA-PSS 4096-bit | JSON Web Token Expiry | Conditional Bypass |
| X-Custom-Token-Hash | ChaCha20-Poly1305 | Sliding Window Limit | Strictly Monitored |
Execution of this token verification workflow requires careful attention to timing attacks and replay vulnerabilities. Attackers frequently capture legitimate signatures and attempt to replay them indefinitely to overwhelm database resources. To neutralize this threat, systems enforce strict timestamp parameters, discarding any payload where the generation time deviates from the server clock by more than five minutes. This temporal bounding ensures that intercepted packets expire quickly, rendering captured data utterly useless to malicious actors lurking on the network.
Security is not a static product, but a continuous process of cryptographic validation, temporal verification, and uncompromising payload rejection at the database perimeter.
Mastering clay external api documentation push data to table unlocks powerful automation potential. As modern enterprises scale operations, implementing systems outlined in melhores erp crm saas pme portugal 2024 2025 ensures seamless digital transformation. Ultimately, refining your clay external api documentation push data to table strategy guarantees accurate real time analytics synchronization across platforms.
When unauthorized payload signatures inevitably attempt database entry, automated cryptographic failure handling mechanisms spring into immediate action. The server intercepts the invalid transmission, aborts the database transaction pipeline, and logs the offending IP address along with the mismatched signature for security analysis. No error details revealing internal schema structures are ever returned to the sender, effectively blinding potential attackers to the inner workings of your infrastructure.
By enforcing these rigorous protocols, your database remains a pristine sanctuary of verified information, safely insulated from the chaotic storms of the open internet.
Crafting structured JSON payloads ensures seamless mapping between originating third-party systems and destination database schemas.
Bridging the digital divide between an unpredictable external universe and your meticulously organized database table feels a bit like translating ancient runes into a modern architectural blueprint. When a third-party platform fires off data, it rarely matches the exact column constraints waiting in your database, creating a high-stakes puzzle where every single data type matters immensely. Success hinges on designing a deliberate trajectory for incoming information, transforming chaotic streams of webhooks and API calls into pristine, orderly rows ready for analytical glory.
Imagine peering into a bustling digital highway where data packets zip across the global network every millisecond, carrying valuable customer interactions, sales metrics, and operational logs. Without a well-defined blueprint, this relentless influx transforms into digital noise, crashing systems and corrupting historical records with mismatched fields and unvalidated strings. By treating incoming JSON payloads as raw marble waiting to be sculpted, developers can forge an unbreakable bridge of reliability.
This process transforms erratic JSON objects into harmonized database entries, ensuring that every piece of incoming intelligence finds its permanent, logical home without friction or data loss.
Mastering clay external api documentation push data to table empowers developers to sync live records seamlessly. Picture transforming chaotic data streams into polished reports while you draft a professional email in 5 minutes to brief your stakeholders. This brilliant workflow elevates daily productivity, ensuring every single database entry arrives right where it belongs through precise clay external api documentation push data to table executions.
A structurally sound payload is the silent guardian of database integrity, turning external unpredictability into internal harmony.
Payload Structuring Workflow for Mapping Nested External Data Attributes Directly to Flat Database Rows
The journey from a deeply nested JSON payload to a flat, relational database row requires a calculated, multi-phase transformation strategy. External systems love to send data packed inside layers of arrays and objects, while relational tables demand a clean, two-dimensional matrix of columns and rows. Orchestrating this transition effectively means writing a robust ingestion middleware that flattens hierarchical paths into dot-notation keys before execution.
For instance, an incoming payload containing a nested customer profile object must be systematically unspooled, extracting vital identifiers and placing them neatly beside transactional attributes. This deliberate restructuring acts as an internal GPS for the data, ensuring that fields like user IDs, timestamps, and metadata align flawlessly with their designated database counterparts, maximizing query efficiency and eliminating orphan records.
Data Sanitization Techniques to Prevent SQL Injection During Remote Ingestion
Opening your database doors to external API traffic without strict sanitization protocols is akin to leaving the vault wide open in the middle of a bustling metropolis. Malicious actors frequently attempt to smuggle destructive database commands inside seemingly innocent JSON string values, turning standard ingestion pipelines into vectors for injection attacks. Implementing rigorous defensive measures at the exact boundary where remote payloads enter your application environment guarantees that malicious scripts are neutralized before they ever touch your database engine.
To establish an impenetrable defense during the remote ingestion phase, developers must consistently apply the following proven sanitization techniques:
- Employing parameterized queries and prepared statements to strictly separate executable code from user-supplied data payloads, rendering malicious input harmless.
- Enforcing strict schema validation using robust libraries to reject any incoming payload containing unexpected data types or unauthorized structural characters.
- Applying automated string escaping routines to neutralize special SQL characters like single quotes, semicolons, and comment markers hidden within JSON strings.
- Utilizing typecasting and whitelist validation to force incoming numerical and boolean attributes into their exact expected primitive types before query generation.
Structural Transformation of Incoming JSON Strings into Compatible SQL Insert Statements
Visualizing the metamorphosis of a raw JSON string into a structured SQL command reveals the sheer elegance of modern data engineering. Picture a sleek, midnight-blue operations dashboard where a raw payload arrives from an external CRM, glowing in the console as a complex, multi-layered string of curly braces and key-value pairs. As the ingestion engine activates, a transformation script parses the string, stripping away unnecessary whitespace and converting the hierarchical tree into a flattened key-value dictionary.
Imagine a dynamic compiler scanning this dictionary, extracting the keys to dynamically construct the SQL column list, while simultaneously mapping and quoting the corresponding values to build a bulletproof `INSERT INTO` command. In your mind’s eye, visualize the terminal displaying the final output: a pristine, parameterized SQL query ready for execution, moving seamlessly from a messy external communication format into a permanent, highly searchable record residing securely within the relational database table.
Managing high-frequency data streams demands resilient rate-limiting strategies to prevent backend database overload during peak synchronization windows
Source: quickemailverification.com
In the relentless flow of modern digital operations, incoming data rushes like a sudden coastal tide against the seawalls of our enterprise databases. When thousands of external systems simultaneously attempt to push synchronization payloads, unprotected database architectures frequently buckle under the pressure, resulting in dropped connections and severe performance degradation. Building a fortress around these critical data repositories requires more than raw server power; it demands intelligent traffic management that absorbs sudden surges without losing a single byte of valuable information.
Behind the scenes, architects deploy sophisticated buffering mechanisms that act as shock absorbers for digital pipelines. Imagine a vast, highly organized holding yard where incoming cargo trucks are safely parked and managed before being granted entry to the main warehouse floor. Queue management algorithms, such as Redis-backed FIFO (First-In, First-Out) structures and Priority Queues, stand ready to intercept incoming remote transmissions, ensuring that the database processes requests at a sustainable, predetermined pace rather than suffocating under an unmanaged avalanche of concurrent requests.
Queue management algorithms designed to buffer incoming remote transmissions safely
Safely buffering high-frequency transmissions involves precise orchestration of memory spaces and disk storage to prevent memory leaks during traffic spikes. As external payloads stream into the gateway, the system evaluates available server capacity and immediately routes excess traffic into a persistent message broker like Apache Kafka or RabbitMQ. This ensures that even if the primary database experiences a temporary micro-outage, incoming payloads remain safely preserved in the buffer queue rather than bouncing back as failed requests to the originating third-party client.
Backpressure implementation becomes vital when the buffer reaches critical capacity thresholds, signaling upstream producers to temporarily ease their transmission velocity. Advanced ingestion engines utilize token bucket and leaky bucket algorithms to smooth out jagged traffic patterns into steady, manageable streams. Visualizing this process reveals a cascading waterfall effect, where water cascades steadily through successive tiers of retention basins, filtering out sediment and pressure spikes before reaching the delicate turbines of the central database generator.
Within this controlled environment, every single piece of data finds its designated holding slot, waiting patiently for its turn to be written permanently into the target schema.
To provide a clear operational overview of how these thresholds and safety nets operate in a production environment, the following table Artikels the structural relationship between incoming load states, system responses, and corrective retry intervals.
| Threshold Limits | Queue Status | Retry Intervals | HTTP Status Responses |
|---|---|---|---|
| 0 to 500 req/sec | Optimal / Direct Processing | Immediate (0 ms) | 200 OK |
| 501 to 1500 req/sec | Buffered / Active Throttling | Exponential Backoff (2s, 4s, 8s) | 429 Too Many Requests |
| 1501 to 3000 req/sec | Saturated / Spillover Storage | Linear Backoff (15s fixed intervals) | 503 Service Unavailable |
| Above 3000 req/sec | Critical / Circuit Breaker Open | Jittered Backoff (30s to 60s randomized) | 504 Gateway Timeout |
Maintaining continuous table synchronization across distributed enterprise infrastructures requires sophisticated throttling mechanisms that adapt dynamically to fluctuating network conditions. Global rate limiters operating at the API gateway layer distribute incoming connection loads across multiple availability zones, preventing any single database node from becoming a bottleneck during massive synchronization events.
Resilient data ingestion relies not on blocking the incoming tide, but on constructing intelligent canals that guide the flow safely to its destination without eroding the banks.
Enterprise architectures frequently implement distributed sliding window counters alongside IP-based and token-based authentication keys to track consumption rates with absolute precision. When major retail events occur, such as global flash sales or end-of-quarter financial reporting windows, these advanced mechanisms automatically scale concurrency limits up or down based on real-time telemetry data. By combining distributed caching layers with proactive circuit breakers, systems can gracefully shed non-essential traffic while prioritizing critical transactional payloads, ensuring absolute data integrity and unbroken operational continuity.
Automated webhook listeners function as the primary catalysts for capturing and routing asynchronous external events directly into structured storage.
In the fast-paced ecosystem of modern data integration, waiting around for manual batch jobs feels like watching paint dry in slow motion. Imagine a bustling digital crossroads where third-party platforms constantly shout out updates, and your system stands ready to catch every single whisper without missing a beat. Automated webhook listeners act as those vigilant gatekeepers, transforming chaotic bursts of external activity into clean, orderly entries inside your database tables.
Bringing this infrastructure to life requires a harmonious blend of rock-solid cloud architecture and lightning-fast event handling, ensuring that every incoming payload finds its proper home instantly and securely.
Deploying listener endpoints involves spinning up dedicated serverless functions or containerized microservices that sit right at the edge of your cloud environment, acting as the ultimate front-line defense and reception desk. When an external service fires a synchronization request, it hits a public-facing API gateway that strips away malicious traffic, verifies cryptographic signatures, and forwards the pristine payload downstream. This setup thrives on elasticity, automatically scaling computational resources up or down depending on whether you are receiving a trickle of test events or a torrential downpour of black-Friday sales data.
Picture a high-speed sorting facility where packages arrive unpredictably on a conveyor belt; the architectural deployment ensures there are always enough workers at the loading dock to process every box immediately.
Webhooks transform traditional polling into an instantaneous, event-driven dialogue between disparate systems, cutting network overhead and maximizing operational efficiency.
Architectural deployment of listener endpoints designed to intercept live data synchronization requests, Clay external api documentation push data to table
Setting up a production-ready interceptor requires methodical precision across your cloud provider’s console, ensuring that network routing, security policies, and compute layers work in absolute synergy. Before opening the floodgates to external traffic, engineers must lay down a bulletproof foundation that guarantees high availability and robust threat mitigation. The following sequential roadmap Artikels the exact operational milestones required to provision a secure endpoint listener within a modern cloud infrastructure.
- Provision a dedicated API Gateway instance to serve as the singular public entry point, establishing custom domain routing and enforcing Transport Layer Security (TLS 1.3) encryption for all incoming transmissions.
- Deploy a serverless execution environment, such as AWS Lambda or Google Cloud Functions, configured specifically to execute the listener code with the minimal necessary IAM execution privileges.
- Implement a Web Application Firewall (WAF) rule set directly in front of the gateway to filter out known malicious payloads, rate-limit suspicious IP addresses, and inspect HTTP headers for anomalies.
- Configure an internal message queuing service, like Amazon SQS or RabbitMQ, immediately behind the listener endpoint to buffer incoming requests and prevent immediate database thread starvation during traffic spikes.
- Establish comprehensive logging and distributed tracing mechanisms using tools like Datadog or AWS CloudWatch to capture every incoming request lifecycle for auditing and debugging purposes.
Asynchronous event processing lifecycle from initial web request interception to final database row commitment
Once the infrastructure is primed and waiting, every incoming web request embarks on a fascinating, high-speed journey through multiple layers of verification, transformation, and storage. The lifecycle begins the exact millisecond an external application sends an HTTP POST request carrying a JSON payload to your public cloud endpoint. The API Gateway instantly captures the transmission, performing an initial sanity check on the headers and payload size before passing the raw bytes to the serverless listener function.
Mastering clay external api documentation push data to table streamlines automated workflows like a breaking news update, empowering your digital strategy forward. Just as evaluating options in ahrefs kw explorer vs kwfinder sharpens your SEO vision with vivid clarity, executing precise API calls transforms raw metrics into actionable triumphs, ensuring your database synchronization operates at peak performance daily.
At this precise junction, security validation takes center stage, requiring the listener to compute an HMAC cryptographic signature using a shared secret key, verifying beyond a shadow of a doubt that the event genuinely originated from the trusted third-party service rather than an opportunistic imposter.
Upon successful authentication, the listener bypasses synchronous database writes to eliminate blocking bottlenecks, instead pushing the raw payload instantly into a resilient message queue and returning an immediate HTTP 200 OK response to the sender. This clever handoff ensures the external service does not timeout or retry unnecessarily, maintaining a pristine communication protocol. Behind the scenes, a worker pool pulls the event payload from the queue, handing it over to a transformation engine that maps the incoming third-party schema fields directly into your relational or NoSQL database table columns.
Data type casting, sanitization, and business logic validations occur simultaneously during this transformation phase, ensuring that corrupt or malformed data gets safely quarantined in a dead-letter queue rather than polluting your core tables. Finally, a parameterized database connection pool executes a secure insert or upsert transaction, committing the row to persistent storage with ACID compliance, and triggering downstream analytics pipelines to reflect the fresh data in real-time dashboards.
Troubleshooting synchronization discrepancies involves systematically inspecting payload delivery logs and resolving schema mismatch errors.: Clay External Api Documentation Push Data To Table

Source: reachstream.com
When external data streams flow relentlessly into your database tables, even the most robust architectures occasionally encounter friction. A single misplaced data type or a corrupted transmission packet can halt the synchronization pipeline, creating invisible gaps between third-party systems and your structured storage. Navigating these digital roadblocks requires a sharp investigative eye and a methodical approach to decoding transmission failures before they disrupt operations.
Unraveling synchronization discrepancies begins with a deep dive into delivery telemetry where every incoming request leaves a digital footprint. By systematically reviewing audit trails, developers can isolate the exact moment a payload fails to translate into expected table rows. This diagnostic process transforms chaotic error logs into a clear roadmap for remediation, ensuring that data integrity remains intact across every synchronization window.
Serialization errors preventing remote data packets from successfully populating table columns
The journey of a JSON payload from an external API to a relational database table is fraught with potential translation hazards. Serialization anomalies typically manifest when the data structure sent by the remote sender violently clashes with the strict typings enforced by the destination database schema. Recognizing these hidden syntax traps is the first line of defense in maintaining a seamless data ingestion pipeline.
When remote systems transmit data packets, minor discrepancies in formatting can trigger immediate rejection by the database engine. These serialization breakdowns often stem from deeply ingrained typing assumptions made by third-party developers that do not align with your specific database architecture.
- Datetime formatting mismatches occur when ISO-8601 strings arrive in formats the destination column refuses to parse automatically.
- Unexpected null values in non-nullable columns trigger immediate SQL exceptions, abruptly halting bulk data insertion routines.
- Integer overflow anomalies happen when numeric values exceed the bit-depth allocated for specific table columns in the database.
- Nested JSON objects sent in place of flat string primitives cause type-casting failures during the parsing phase.
Addressing these serialization hurdles demands rigorous input validation layers that intercept payloads prior to database execution. By enforcing strict schema contracts at the webhook boundary, engineering teams can filter out malformed packets and return descriptive error codes to the originating service. Proactive payload sanitization not only preserves database stability but also accelerates the debugging lifecycle when third-party integrations undergo unexpected updates.
Systematic error resolution strategies for external data pipelines
Executing a structured response to integration failures requires a clear taxonomy of error states paired with actionable debugging paths. The matrix below Artikels the primary transmission anomalies encountered during high-frequency data synchronization, detailing their structural origins and verified verification methods to ensure absolute system reliability.
| Error Code | Root Cause | Debugging Steps | Resolution Verification Method |
|---|---|---|---|
| ERR-4001 | Schema type mismatch between JSON payload and SQL column definition. | Inspect raw webhook payloads against database migration schemas to locate drifting data types. | Replay the exact failed payload through a staging endpoint and confirm successful row creation. |
| ERR-4092 | Concurrent write locks causing transaction timeouts during peak windows. | Analyze database active connection pools and transaction isolation levels under heavy load. | Monitor query execution duration metrics during simulated high-frequency stress tests. |
| ERR-4130 | Payload size exceeding maximum allowable HTTP request body limits. | Review API gateway configuration settings and examine incoming batch chunk sizes. | Verify that oversized batches return HTTP 413 and successfully trigger pagination logic. |
| ERR-4224 | Missing mandatory foreign key references in relational mapping dependencies. | Trace parent record creation timestamps against incoming child payload arrival logs. | Query the relational table to ensure child records correctly inherit valid foreign keys. |
Implementing these verification steps transforms reactive firefighting into a predictable engineering cadence. Each resolved error reinforces the resilience of the integration layer, paving the way for flawless long-term data synchronization.
Mastering clay external api documentation push data to table unlocks powerful automation workflows for modern web platforms today. Imagine seamlessly upgrading your site architecture by integrating a reliable limousine booking plugin wordpress free to elevate client interactions effortlessly. Harnessing these robust digital tools ultimately empowers your enterprise to analyze incoming datasets and streamline daily operations with absolute precision.
Logging best practices for capturing anomalous transmission failures without exhausting server storage capacities
Capturing every nuance of external API traffic is essential for debugging, yet unmanaged log generation can quickly suffocate server storage volumes. To maintain peak performance, logging architectures must adopt intelligent retention policies and selective verbosity levels that prioritize critical anomalies over mundane operational noise. Striking this delicate balance ensures that engineering teams retain deep forensic visibility without drowning in terabytes of redundant text.
Modern logging strategies rely heavily on rotational buffers, asynchronous log shipping, and contextual payload truncation to protect underlying infrastructure. Instead of storing entire multi-megabyte payloads when a failure occurs, systems should capture localized cryptographic hashes alongside truncated error snippets. This targeted approach preserves the diagnostic essence of the transmission failure while drastically reducing the physical storage footprint on production servers.
Comprehensive logging is not about recording every single event blindly, but about capturing the exact structural context of failure with surgical precision.
Integrating sliding-window retention policies ensures that historical logs automatically purge themselves after a defined operational lifecycle, unless flagged by an active incident ticket. By pairing smart log rotation with centralized log aggregation services, organizations can maintain lightning-fast database performance while retaining an impenetrable audit trail for every synchronization anomaly.
Optimizing batch insertion performance transforms sluggish data migration tasks into lightning-fast table updates for massive external datasets.
When external data pipelines swell from a gentle stream into a roaring river of millions of incoming records, traditional database ingestion techniques quickly buckle under the pressure. Processing immense volumes of incoming payloads requires a deliberate shift in architecture, moving away from iterative, single-transaction habits and stepping boldly into the realm of high-performance bulk operations. The difference between a stalled synchronization pipeline and a seamlessly updated database often lies in how intelligently these massive data blocks are packaged, transmitted, and committed to the underlying storage engine.
Handling astronomical figures requires a clear-eyed look at the mechanics of database communication. Imagine moving a mountain of bricks one by one versus loading them into a massive freight elevator. Single-row insertion techniques force the database engine to open a transaction, write the data to disk, update indexes, and close the transaction for every single record. When scaling to millions of entries, the network overhead and transaction log saturation create an insurmountable bottleneck, grinding the entire synchronization process to a crawling halt.
Comparative efficiency metrics between single-row execution and multi-row bulk commit frameworks
Adopting multi-row bulk commit operations fundamentally rewrites the efficiency playbook by bundling thousands of records into a single, cohesive network payload and execution statement. Instead of establishing continuous, chatter-heavy dialogues with the database, bulk insertion transmits arrays of data that the storage engine can process in a streamlined memory footprint. Database administrators analyzing high-throughput logging systems frequently observe that multi-row operations reduce network round-trips by upwards of ninety-nine percent, transforming hours of grueling data migration into mere minutes of sleek, high-speed execution.
To visualize this structural contrast vividly, picture a bustling fulfillment center where individual couriers hand over a single package one at a time at the front desk, causing massive gridlock at the entrance. Bulk insertion functions like a fleet of freight trucks arriving at a designated loading dock, depositing thousands of packages simultaneously through an automated sorting chute. This parallel processing capability eliminates wait times, optimizes CPU instruction cycles, and drastically diminishes lock contention on the target tables.
Benchmarks across enterprise relational and non-relational database systems consistently demonstrate that batching payloads into groups ranging from five thousand to fifty thousand records hits the sweet spot for maximizing throughput without exhausting system RAM.
Bulk operations do not merely accelerate data ingestion; they fundamentally preserve system stability by transforming chaotic, erratic transaction spikes into predictable, manageable resource allocations.
Executing these massive data ingestion cycles safely demands a rigorous approach to system configuration, ensuring that memory allocation matches the aggressive pace of incoming payloads. Careful calibration of database buffers and cache layers prevents the operating system from thrashing while processing heavy external streams.
System administrators preparing infrastructures for intense synchronization windows rely on a specific set of memory management adjustments to accelerate performance:
- Enlarging the database buffer pool allocation ensures that frequently accessed index pages and active table blocks remain resident in high-speed RAM, drastically minimizing expensive disk read and write operations.
- Adjusting transaction log buffer sizes permits the engine to hold larger blocks of uncommitted bulk data in memory before flushing sequential write operations to disk storage.
- Scaling sort memory parameters empowers the database to handle heavy index re-building and sorting operations entirely in memory during massive batch commits without spilling over to slow temporary disk files.
- Optimizing network packet memory thresholds guarantees that oversized JSON payloads arriving from external API endpoints can be fully buffered and parsed without triggering memory fragmentation errors.
Beyond internal memory tuning, managing concurrent external data streams requires precise resource allocation adjustments on the database server itself. When multiple third-party systems flood endpoints simultaneously, the database management system must dynamically balance CPU cores, connection pools, and disk I/O bandwidth to prevent systemic failure.
Resource allocation tuning protocols for managing concurrent external data streams
Sustaining peak performance under the weight of concurrent external data streams requires deliberate control over compute resources and connection concurrency. Unchecked incoming requests can quickly exhaust available worker threads, leading to cascading timeouts and dropped synchronization events. Database architects counteract this vulnerability by enforcing strict connection pooling limits, assigning dedicated thread priorities to bulk ingestion routines, and establishing robust governor policies that throttle aggressive API sources before they destabilize the primary storage cluster.
Consider a high-profile e-commerce platform during a global holiday flash sale, where millions of inventory updates stream in from disparate fulfillment partners concurrently. Without precise resource partitioning, background batch migrations would starve core transactional queries of necessary CPU cycles, resulting in sluggish customer checkouts. By carving out dedicated resource pools—allocating specific memory groups and CPU cores exclusively for bulk external ingestion—the database architecture isolates heavy data migrations from mission-critical live operations.
This deliberate compartmentalization ensures that massive external data pushes integrate smoothly into enterprise tables without ever compromising overall system responsiveness.
Conclusion
Ultimately, mastering the art of moving external data into structured storage empowers organizations to turn raw digital inputs into lasting value. As we have explored across these core integration pillars, precision in payload validation, resilience against traffic spikes, and proactive troubleshooting form the bedrock of elite system architecture. Embrace these advanced methodologies today, and watch your digital infrastructure operate with unprecedented speed, security, and unwavering reliability.
