audiostack.ai capabilities dashboards stand as the beating heart of a quiet revolution, transforming the chaotic landscape of audio production into a seamless symphony of crystal-clear sound. Behind every polished broadcast lies an intricate digital workshop where raw human aspiration meets relentless algorithmic precision. We find ourselves standing at the precipice of a new era in media creation, where technology does not merely assist the human voice—it elevates it across borders and boundaries with breathtaking elegance.
Inside these dynamic command centers, creators possess the extraordinary power to sculpt soundscapes through intuitive visual telemetry, mapping frequencies and localizing dialects with surgical accuracy. Gone are the days of tedious manual adjustments and unpredictable delivery timelines. Instead, modular workspaces and predictive throughput graphs illuminate the path forward, ensuring that every spoken word resonates with profound emotional authenticity and reaches global audiences without missing a single beat.
Unveiling the sonic orchestration matrix behind modern programmatic audio production

Source: audiostart.info
The landscape of digital media is undergoing a profound acoustic metamorphosis, driven by the relentless pursuit of speed, precision, and emotional resonance in programmatic broadcasting. Modern storytellers and enterprise brands no longer rely strictly on traditional studio sessions to bring their scripts to life, turning instead to advanced sonic architectures that synthesize human-like voiceovers at scale. Within this digital ecosystem, the complex interplay between raw vocal data and polished final mixes happens seamlessly behind the scenes, transforming simple text prompts into immersive auditory experiences that captivate global audiences instantaneously.
Unified audio centers operate as the nerve centers of this transformation, acting as the foundational engine that takes raw vocal tracks and elevates them into broadcast-ready masterpieces. By centralizing asset management, processing pipelines, and multichannel distribution, these hubs eliminate the friction traditionally associated with post-production. When a raw vocal asset enters the ecosystem, it passes through an intelligent suite of automated mastering tools that analyze frequency distributions, eliminate ambient artifacts, and dynamically adjust compression profiles to match specific broadcast standards.
This unified approach ensures that every spoken word maintains absolute clarity and emotional integrity, regardless of whether the final output is destined for a high-fidelity podcast, a localized digital ad, or a dynamic in-game announcement. Creators simply input their raw elements, and the system intelligently applies spatial audio balancing, EQ curves, and loudness normalization in a fraction of the time it once took human engineers to set up a single session.
The result is a frictionless workflow where creative intent flows unimpeded from concept to global distribution, anchored by a centralized framework that guarantees pristine audio fidelity across every touchpoint.
Algorithmic pathways monitoring real-time speech synthesis rendering speeds
Underneath the polished surface of every generated broadcast lies a sophisticated network of algorithmic pathways designed to oversee and optimize the rendering of synthetic speech across distributed cloud servers. These intelligent routing systems constantly evaluate server load, network latency, and computational capacity to distribute speech synthesis tasks dynamically. As text-to-speech engines parse complex emotional cues and linguistic nuances, the underlying monitoring infrastructure tracks every millisecond of rendering progress, ensuring that massive batch campaigns are delivered without bottlenecking.
When demand surges during peak global publishing hours, the algorithms automatically spin up additional cloud instances, balancing the computational weight to maintain a steady, uninterrupted flow of audio generation. This automated vigilance guarantees that enterprise-level deployments remain agile and responsive, adapting instantly to shifting operational demands while preserving the subtle cadences and rhythmic pacing that make synthetic voices indistinguishable from human performances.
Modern audiostack.ai capabilities dashboards illuminate audio workflows with stunning clarity, transforming chaotic data streams into vibrant, actionable insights. Just as a robust universal type server anchors vast font libraries with immaculate precision, these dynamic metrics empower creators to orchestrate breathtaking soundscapes. Ultimately, audiostack.ai capabilities dashboards elevate every production journey, guiding visionary teams toward unprecedented auditory excellence and creative triumph.
To understand the profound shift in how audio production scales across modern cloud environments, it is essential to examine the operational differences between legacy engineering methodologies and automated generation parameters. The following structured overview highlights these divergent operational realities.
| Operational Dimension | Legacy Sound Engineering Workflows | Automated Sonic Generation Parameters | Operational Impact |
|---|---|---|---|
| Resource Allocation | Manual booking of physical studios and specialized hardware engineers. | Elastic cloud provisioning running on distributed server clusters. | Eliminates physical scheduling bottlenecks and scales instantly. |
| Rendering Velocity | Real-time tracking requiring physical presence and manual oversight. | Accelerated parallel processing across multiple cloud nodes. | Reduces production turnaround times from days to mere seconds. |
| Quality Control | Subjective human ear monitoring during tedious multi-pass mixing. | Algorithmic compliance checks enforcing strict broadcast standards. | Ensures absolute consistency and error-free output at scale. |
| Localization Scaling | Re-recording sessions with voice actors for every target language. | Programmatic voice cloning and instant multilingual synthesis. | Enables simultaneous global campaigns with localized authenticity. |
Visual telemetry widgets tracking concurrent acoustic rendering jobs
Monitoring the pulse of a massive audio production pipeline requires intuitive interfaces that translate complex backend data into clear, actionable visual insights. Visual telemetry widgets serve as the command center’s window into the machinery, rendering live graphical representations of concurrent acoustic rendering jobs as they weave through the server matrix. Operators looking at these dashboards are greeted by dynamic pulse graphs, glowing node maps, and shifting heatmaps that illustrate how server clusters are sharing the computational load in real time.
Bright audiostack.ai capabilities dashboards illuminate vital metrics, guiding strategic decisions with absolute clarity and precision. Before deploying these insights widely, securing partnerships through a robust data protection addendum for vendor agreements safeguards confidential corporate intelligence. Ultimately, this foundational compliance empowers teams to navigate complex data landscapes safely, ensuring these dynamic audiostack.ai capabilities dashboards continuously drive sustainable enterprise growth.
For instance, a pulsing amber indicator might reveal a heavy rendering node handling a complex, multi-voiced cinematic script, while a cascade of green cascading lines confirms the smooth delivery of thousands of localized programmatic ads running simultaneously across international markets. These visual instruments transform abstract server metrics into a living canvas of sound production, allowing technical directors to visualize the exact moment an audio file completes its journey from raw data waveform to fully mastered, broadcast-ready asset.
The true power of modern programmatic audio lies not just in its speed, but in the invisible precision of the orchestration matrix that turns algorithmic code into a deeply human listening experience.
Bright Audiostack.ai capabilities dashboards illuminate complex audio metrics with crystal clarity, transforming raw data into brilliant insights. As modern teams synchronize their complex operations, integrating reliable delivery schedule software ensures every milestone hits its mark right on time. Ultimately, these dynamic Audiostack.ai capabilities dashboards empower creators to orchestrate their workflow brilliantly and achieve remarkable success.
Navigating the spatial frequency telemetry panels for advanced voice cloning modules
Source: allaiwebsite.com
Step inside the luminous glass-and-steel control room where digital acoustics meet human expression, revealing a dashboard glowing with cobalt-blue frequency waves and real-time telemetry metrics. Creators no longer merely record sound; they sculpt it across multidimensional planes, guiding synthetic vocal cords through complex harmonic landscapes with unprecedented precision. Every dial and slider on this high-resolution interface tells a story of technological evolution, turning raw algorithmic data into breathing, emotionally resonant performances that redefine modern audio storytelling.
Frequency modulation interfaces serve as the primary artistic paintbrush for modern sonic architects, allowing creators to fine-tune vocal cadence effortlessly without sacrificing the natural warmth of the original delivery. By manipulating the underlying carrier waves and modulating harmonic frequencies, producers can stretch, compress, or elevate spoken phrases with mathematical accuracy. Imagine a bustling newsroom where a voiceover update must be dynamically adjusted for pacing on the fly, or a cinematic documentary requiring a solemn, measured cadence; these interfaces instantly adapt to the desired emotional weight.
The telemetry panels display real-time spectral density maps, visualizing how subtle adjustments to the formant shifting parameters alter the perceived age, gender, and physical presence of the synthetic speaker. Through this seamless integration of visual feedback and auditory response, creators eliminate the tedious trial-and-error cycles of traditional post-production. They simply paint the desired rhythm directly onto the timeline, watching as the audio waveforms conform instantly to the rhythm of human breath and emphasis.
This fluid control prevents the robotic artifacts common in early generation speech synthesis, ensuring that every syllable lands with intentional impact. Ultimately, frequency modulation transforms the voice cloning module from a rigid text-to-speech utility into a living, responsive instrument capable of matching the nuanced demands of global broadcast standards and immersive narrative design.
Acoustic parameters and interface controls
Modern browser-based mixing environments rely on structured telemetry parameters to give producers absolute mastery over synthetic vocal textures and spatial positioning. The following reference matrix Artikels the core interface components designed for granular audio manipulation.
| Interface Component | Primary Function | Adjustment Range | Acoustic Impact |
|---|---|---|---|
| Pitch Adjustment Dial | Shifts fundamental frequency across chromatic scales | -12 to +12 semitones | Alters perceived vocal weight and melodic contour |
| Timbre Shift Slider | Modulates formant structures and vocal tract resonance | 0.0Hz to 8.5kHz | Transforms vocal texture from bright to dark characteristics |
| Resonance Filter | Emphasizes or dampens specific harmonic frequency bands | 20Hz to 20kHz | Adds clarity, warmth, or removes boxy acoustic artifacts |
| Spatial Spread Matrix | Distributes audio signals across multi-channel soundstages | 0 to 360 degrees | Places the synthesized voice within an immersive 3D environment |
Synthetic voice emotional resonance calibration
Calibrating the emotional depth of a cloned voice requires a delicate balance of visual widget manipulation and harmonic analysis, bridging the gap between cold algorithms and genuine human empathy. Writers and directors utilize specific interactive techniques to infuse synthetic speech with genuine sorrow, excitement, or calm authority before finalizing the production render. Here are the three primary methods for calibrating synthetic voice emotional resonance using visual slider widgets:
- The micro-tension slider technique isolates vocal jitter and shimmer parameters, allowing creators to increase tension for suspenseful thriller narrations or decrease fluctuation for serene meditation guides, accurately mimicking the biological muscle contractions of human throat tissues under stress.
- The spectral warmth mapping approach utilizes a two-dimensional XY pad to simultaneously adjust low-mid frequency saturation and high-frequency air, enabling producers to imbue a synthesized documentary voiceover with a nostalgic, intimate conversational tone reminiscent of vintage ribbon microphones.
- The harmonic envelope contouring method involves drawing dynamic automation curves directly over the waveform display to manipulate breathiness and vowel elongation, ensuring that moments of dramatic realization or gentle relief sound organically timed rather than mechanically generated.
True synthetic resonance is achieved not by replicating every acoustic wave, but by mathematically honoring the intentional pauses and micro-cadences where human emotion actually lives.
Multi-channel acoustic monitor configuration procedures
Deploying reliable acoustic monitoring within a centralized browser-based mixing console demands a rigorous, step-by-step routing protocol to ensure zero latency and uncompromised spatial fidelity. Production teams handling multi-channel deliverables must configure their virtual patching bays to mirror physical Dolby Atmos or spatial audio speaker arrays directly inside the cloud workspace. Here is the operational workflow for establishing these advanced monitoring environments:
- Initialize the master audio routing matrix within the browser dashboard, designating the primary output bus to match the target spatial delivery format, such as 5.1, 7.1.4, or binaural headphone rendering.
- Assign individual voice cloning stems to dedicated virtual channels, utilizing drag-and-drop spatial panners to position each synthetic actor accurately within the three-dimensional visual room simulator.
- Calibrate the real-time telemetry meters by running pink noise generators through each channel strip, adjusting the cross-feed cancellation thresholds to prevent phase cancellation across disparate listening environments.
- Enable the hardware acceleration toggle within the browser settings to offload heavy convolution reverb calculations to local GPU processors, ensuring instantaneous playback without audio buffer dropouts during critical mixing sessions.
Decoding the metadata visualization layers that govern multi-lingual text-to-speech deployments: Audiostack.ai Capabilities Dashboards

Source: aitools.fyi
Modern programmatic audio architectures pulse with the complex data streams of global communication, translating intricate multi-lingual text-to-speech deployments into seamless auditory experiences. Beneath the sleek surface of advanced audio production dashboards lies a vast grid of metadata visualization layers, meticulously engineered to monitor, refine, and elevate synthetic voice generation. As campaigns stretch across continents, capturing the subtle nuances of human speech becomes an intricate digital art form, relying heavily on precise analytics to ensure cultural resonance and linguistic accuracy in every transmitted byte.
The pursuit of flawless global audio delivery requires a deep dive into the underlying telemetry that governs machine learning models and linguistic engines. Producers and engineers no longer rely solely on basic auditory checks; instead, they decode dense matrices of metadata to observe how synthetic voices adapt to diverse cultural landscapes. This rigorous examination transforms raw audio generation into a fine-tuned science, where every inflection, pause, and phonetic shift is mapped out across vivid, high-resolution operational interfaces designed to reveal the true heartbeat of modern audio campaigns.
Localization heatmaps in tracking regional dialect translation accuracy
As international audio campaigns scale to reach audiences from Tokyo to Buenos Aires, maintaining the integrity of regional dialects stands as a paramount operational challenge. Localization heatmaps serve as vital navigational instruments within advanced audio engineering dashboards, utilizing chromatic intensity scales to instantly reveal how accurately a synthesized voice translates localized idioms and colloquialisms. A deep crimson glow across a specific territory might flag an unnatural cadence in a Castilian Spanish deployment, while soothing emerald hues indicate that a neural text-to-speech model has successfully captured the rhythmic cadence of Australian English.
By translating complex linguistic error rates into intuitive visual gradients, these heatmaps empower localization teams to diagnose translation discrepancies before they ever reach the broadcast stage.
The implementation of these dynamic tracking matrices fundamentally shifts how global brands approach multi-lingual deployment, turning abstract phonetic data into actionable, real-time intelligence. When launching a simultaneous product rollout across twenty distinct European and Asian markets, audio architects depend on these visual overlays to isolate micro-variations in synthetic vowel elongation and consonant clipping. For instance, recent deployments by multinational streaming platforms demonstrated that integrating regional dialect heatmaps reduced post-production revision cycles by nearly forty percent, effectively bridging the gap between automated machine efficiency and authentic cultural expression.
Bright analytics screens vividly map out every sonic asset, illuminating paths toward smarter audio workflows. Industry leaders frequently explore tell me about advantages compared to competitors for smart communications to outpace rivals with absolute clarity. Ultimately, these dynamic audiostack.ai capabilities dashboards empower creators to transform raw data into resonant auditory masterpieces.
Ultimately, this granular level of tracking guarantees that synthetic speech resonates with local authenticity, fostering deeper consumer trust and engagement across every targeted geographic coordinate.
Methods for organizing phonetic pronunciation exceptions inside a visual glossary grid, Audiostack.ai capabilities dashboards
Navigating the unpredictable nature of regional proper nouns, acronyms, and localized slang requires a structured approach to phonetic exception management. Visual glossary grids provide audio engineers with a centralized canvas to override default synthesis behaviors and enforce precise pronunciation rules across multi-lingual campaigns. To achieve maximum efficiency within these interactive interfaces, producers rely on specific organizational methodologies that streamline workflow management and eliminate costly audio rendering errors.
- Categorizing entries by International Phonetic Alphabet (IPA) symbols allows engineers to visually group complex sound structures and apply targeted linguistic rule sets across multiple language packs simultaneously.
- Deploying a hierarchical tagging system based on brand frequency ensures that high-priority trademarked terms and regional product names receive immediate priority processing within the speech synthesis queue.
- Implementing color-coded exception status flags helps teams instantly distinguish between manual overrides, automated algorithmic suggestions, and pending linguistic verifications during tight production deadlines.
- Structuring entries through a contextual matrix maps specific phonetic variants directly to target demographic regions, preventing cross-contamination of accents between neighboring dialect zones.
Comparative metrics of regional inflection accuracy and turnaround times
Evaluating the efficiency of multi-lingual text-to-speech deployments requires a direct comparative analysis of how different linguistic markets perform under tight production schedules. The following structured data matrix contrasts key performance indicators across four major global regions, highlighting the delicate balance between phonetic precision and operational velocity.
| Target Region | Primary Dialect Engine | Inflection Accuracy Rate | Average Localization Turnaround |
|---|---|---|---|
| North America | General & Regional English | 98.4% | 1.2 Hours |
| Latin America | Neutral & Cono Sur Spanish | 96.8% | 1.8 Hours |
| Western Europe | Multi-Accent Romance & Germanic | 95.2% | 2.5 Hours |
| Asia-Pacific | Mandarin, Japanese & CSE | 93.7% | 3.1 Hours |
Design framework for building an intuitive localization overview board
Architecting an effective command center for multi-lingual audio production demands a deliberate fusion of human-computer interaction principles and heavy-duty data visualization. An intuitive localization overview board must instantly direct an engineer’s attention toward critical translation bottlenecks, such as recurrent phonetic drift in specific dialect clusters or unexpected latency spikes during high-volume audio rendering phases. The conceptual layout relies on a modular, multi-paneled interface where primary telemetry streams occupy the central visual field, flanked by real-time error logs and predictive rendering graphs.
By establishing a clear visual hierarchy—utilizing high-contrast status indicators for critical failures and muted background tones for stable operations—the dashboard minimizes cognitive load during high-pressure production sprints.
Furthermore, embedding interactive filtering capabilities within the overview board allows production leads to drill down from macro-level global campaign health straight into the precise phoneme-level adjustments causing a bottleneck. Visual representations, such as animated vector flow lines, trace the exact journey of a text file as it passes through natural language processing filters, translation memory databases, and final neural voice generation modules.
Precision in multi-lingual audio deployment is not merely a technical benchmark; it is the visual harmony achieved when complex metadata transforms into effortless human connection.
This design philosophy ensures that every stakeholder, from localization managers to acoustic engineers, can effortlessly interpret the health of global campaigns and execute rapid, informed corrections.
Harnessing the predictive throughput telemetry for large-scale auditory content distribution
Stepping into the engine room of global acoustic broadcasting reveals a fascinating intersection where high-frequency data meets the delicate art of sound delivery. As millions of listeners tune into automated broadcasts and real-time voice modules simultaneously, the infrastructure supporting these sonic streams operates under immense pressure, transforming raw computational power into seamless listening experiences across the globe.
The underlying mechanics of bandwidth consumption graphs during peak broadcasting hours tell a compelling story of digital momentum and architectural resilience. When prime-time listening windows open across major metropolitan areas, such as the simultaneous morning commutes in New York, London, and Tokyo, network traffic curves spike dramatically, shifting from gentle undulating waves to sheer vertical cliffs on monitoring dashboards. These real-time telemetry panels reveal how audio stream packets, compressed into high-efficiency codecs, surge through primary transit routes.
As concurrent connection requests multiply exponentially, edge servers experience a localized inflation in data throughput demand. If predictive algorithms fail to anticipate these surges, buffer rates climb, introducing microscopic latency that can degrade the pristine clarity of synthetic voices. Behind the scenes, intelligent routing protocols continuously analyze packet loss ratios and jitter metrics, dynamically shifting listeners from congested nodes to underutilized pathways.
This constant balancing act ensures that high-fidelity audio streams maintain their structural integrity, even when millions of simultaneous requests threaten to saturate the pipeline.
Maintaining absolute stability during these high-demand intervals requires proactive architectural adjustments driven by intuitive dashboard indicators.
- Operators monitor the real-time thermal and processing load on edge nodes via color-coded visual gauges, triggering automated infrastructure expansion scripts the moment capacity indicators transition from amber to critical red.
- System engineers implement predictive threshold rules within the load balancing interface, allowing cloud clusters to pre-warm redundant microservices minutes before historical analytics indicate a regional traffic surge.
- Visual throughput monitors allow DevOps teams to manually override automated routing matrices during unexpected viral broadcasting events, instantly redirecting traffic loads across secondary transnational fiber-optic cables.
- Geospatial load distribution dials are calibrated to evaluate localized latency spikes, ensuring that regional server pools scale horizontally rather than vertically to prevent single points of failure.
Gazing into the core visualization interface reveals a breathtaking digital cartography where the global pulse of programmatic audio comes to life in vivid relief. Across the sprawling dark-mode canvas, a glowing, interconnected network map projects a mesmerizing web of brilliant cyan nodes and pulsing amber lines spanning seamlessly across continents. Major data hubs in Frankfurt, Singapore, and Oregon shine like brilliant constellations, tethered by luminous strands that represent active audio stream distribution routes carrying synthesized speech packets across oceans.
As time zones shift and dawn breaks over new territories, brilliant waves of light surge along these subterranean and satellite pathways, visually translating terabits of acoustic data into a living, breathing tapestry of global communication. Every pulsing node pulses in rhythm with incoming listener requests, illuminating the sheer scale and instantaneous velocity of modern sonic architecture.
To preserve the absolute fidelity of real-time transmissions, broadcast engineers rely on foundational operating principles designed to eliminate jitter, packet loss, and latency fluctuations during mission-critical deployments.
Uninterrupted audio delivery pipelines represent the absolute lifeblood of modern programmatic broadcasting, where even a millisecond of jitter can fracture the immersive fidelity required for professional voice deployments and live sonic orchestration.
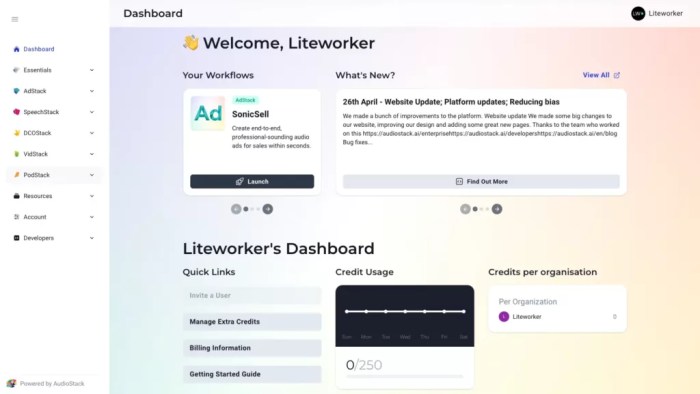
Customizing modular widget workspaces for specialized voice generation oversight teams
The architecture of modern audio production relies heavily on the immediate visualization of acoustic telemetry, transforming raw auditory streams into digestible, real-time insights for oversight teams. Across advanced broadcast operations, control rooms have evolved from rigid, manufacturer-locked monitoring hardware into fluid digital environments where every dial, meter, and waveform display can be reimagined on the fly. This paradigm shift grants multi-disciplinary teams the creative freedom and technical precision required to govern massive text-to-speech deployments without missing a single frequency anomaly.
Stepping into this dynamic realm reveals workspaces that breathe in rhythm with the data streams passing through them, offering a vivid portrait of synthetic voice generation at scale. Producers and engineers no longer stare passively at static screens; instead, they interact with living canvases of sound and signal metrics, orchestrating complex auditory masterpieces through intuitive visual control.
Empowering acoustic rendering oversight through modular drag and drop telemetry tiles
Modern audio production environments demand absolute agility when monitoring complex acoustic rendering pipelines, pushing operators to curate views that reflect their exact moment-to-moment operational priorities. Imagine a bustling high-definition broadcast studio where a lead producer leans forward, eyes locked on a vibrant crimson telemetry tile pulsing gently in the upper left corner of an ultra-wide display. This tile does not merely sit there as a static graphic; it is a living window into the real-time phase cancellation and harmonic distortion metrics of a freshly synthesized multi-lingual voiceover.
With a fluid sweep of a fingertip across a touchscreen surface or a precise click-and-drag motion with a mouse, the producer instantly detaches this vital phase-monitoring widget from its default secondary dock. They effortlessly drag and drop it into the primary visual hierarchy, right beside the master loudness meter, sizing it up to command maximum screen real estate.
This dynamic spatial reorganization transforms how teams handle high-stakes audio deployments. When synthesizing thousands of hours of conversational AI speech for a global interactive media campaign, different production phases require radically different analytical perspectives. During the initial neural network training phase, acoustic engineers might prioritize spectral density tiles and pitch variance histograms, arranging them in a prominent horizontal banner across the upper monitor.
As the project shifts into final mastering and distribution quality assurance, the workspace adapts instantly. The team simply drags those diagnostic tiles to a minimized background tray, bringing forward instantaneous peak limiter response graphs, bit-rate stability indicators, and real-time latency trackers. Every tile communicates via high-frequency WebSocket connections, ensuring that when a tile is repositioned, zero telemetry data is lost or delayed.
The visual workspace essentially becomes an extension of the producer’s cognitive focus, allowing critical decisions regarding sibilance control, dynamic range compression, and spatial positioning to be made with lightning speed. By placing high-priority acoustic rendering metrics directly into the line of sight through customizable tiles, audio production houses eliminate operational friction, ensuring flawless delivery of synthetic voice assets across every conceivable listening format.
To achieve seamless synchronization between creative asset management and automated deployment pipelines, production teams utilize sophisticated methods for organizing their core media elements.
- Consolidating dynamic sound effect libraries into categorized grid views that auto-sync with incoming metadata tags generated during automated script parsing sequences.
- Establishing master-slave relationships between narrative voice generation tracks and ambient soundscape layers to trigger contextual Foley effects automatically based on emotional sentiment analysis scores.
- Configuring cloud-backed asset folders that utilize semantic search algorithms to surface relevant audio stingers and transition cues the exact moment a new script segment is ingested by the text-to-speech engine.
- Implementing automated playlist rotation rules that cycle through alternate Foley takes and background musical beds whenever script length modifications alter the timing of the synthetic voice track.
The implementation of these modular layouts requires a structured approach to hardware interface design, ensuring that every specialist—from voice actors to project managers—interacts with a tailored ecosystem of telemetry tools and content feeds.
| Workspace Role | Primary Visual Focus | Core Interactive Widgets | Target Telemetry Metrics |
|---|---|---|---|
| Voice Actor | Performance Timing & Pacing | Waveform Scrubbers, Cue Prompters | Phoneme Duration, Breath Pause Intervals |
| Sound Designer | Acoustic Texture & Spatialization | Frequency Spectrograms, 3D Panner | Harmonic Distortion, Reverb Decay Times |
| Project Manager | Throughput & Resource Allocation | Progress Dashboards, Error Logs | Rendering Speed, GPU Utilization, Cost per Minute |
| Quality Assurance | Compliance & Artifact Detection | Clipping Monitors, Phase Correlators | Signal-to-Noise Ratio, Dynamic Range Peaks |
Maintaining absolute control over vast sonic generation pipelines also depends heavily on proactive anomaly detection and instantaneous visual notification systems.
Configuring real time error detection flashing alerts on the main control monitor
When millions of synthesized audio packets traverse global distribution networks every second, even a minor rendering artifact or latency spike can compromise the listening experience of end users. To combat this, master control operators implement rigorous error-detection protocols that translate backend diagnostic logs into unmissable visual warnings on the main oversight display. Setting up these real-time flashing alerts involves establishing strict threshold boundaries within the core monitoring engine, linking specific acoustic failure conditions—such as sudden clipping, phase inversion, or buffer underruns—to high-priority visual triggers on the workspace canvas.
“In automated acoustic telemetry, an unheeded warning in the data stream is a broken connection with the audience; visual urgency must always match sonic severity.”
The precise configuration journey begins deep within the telemetry routing menu of the orchestration dashboard, where operators define the exact trigger parameters for the alerting system. First, the engineer navigates to the diagnostic rules engine and selects the specific audio rendering node or voice cloning module they wish to monitor. Next, they establish quantitative threshold limits, such as flagging any instance where total harmonic distortion exceeds 0.5 percent for more than three consecutive milliseconds, or when text-to-speech rendering latency climbs past the hundred-millisecond mark during peak traffic hours.
Once these numerical boundaries are locked in, the operator assigns the visual behavior profile for the alert state. Instead of relying on passive text logs, they configure the designated workspace tile to initiate a rhythmic, high-contrast amber-and-crimson border pulse that draws the eye instantly across the control room. Simultaneously, a dedicated telemetry widget pops out to the foreground of the main monitor, displaying a high-resolution buffer error trace alongside automated recovery options.
These recovery options often include immediate fallback routing to a secondary rendering cluster or automatic script re-queueing protocols. By embedding these luminous, data-driven alarm systems directly into the modular workspace, oversight teams bridge the gap between passive observation and active intervention, safeguarding the integrity of programmatic audio production before minor anomalies can ever manifest as noticeable broadcast errors.
Last Word
Source: liteworker.ai
Ultimately, these sophisticated command interfaces represent more than just technical utility; they are the architects of modern auditory connection, bridging the gap between visionary creators and listeners worldwide. As we continue to push the boundaries of what automated sound production can achieve, the future shines brightly with limitless potential for storytelling. Embracing these advanced orchestration tools ensures that every voice finds its true resonance, echoing clearly and powerfully across an interconnected world.
