accuranker vs ahrefs stands at the crossroads of modern digital visibility, where data architecture meets the relentless pace of algorithmic evolution. Beneath the polished dashboards and humming server racks lies a profound clash of philosophies regarding how search engine positions are captured, analyzed, and leveraged for maximum market impact. Every single query logged and every movement recorded tells a story of digital ambition, shaping the destiny of brands navigating the turbulent waters of search engine result pages.
As modern enterprises demand uncompromising precision, understanding the foundational mechanics of these two digital titans becomes essential for anyone serious about conquering the digital landscape.
Originally forged in distinct corners of the search marketing ecosystem, both platforms have grown far beyond their humble origins into comprehensive powerhouses. They now command the daily workflows of thousands of digital strategists who rely on their deep insights to decode the intentions of global audiences. Through sophisticated infrastructure and relentless innovation, these suites transform raw, chaotic internet data into crystal-clear pathways for growth.
Stepping into this arena means unlocking the secrets of search intelligence, empowering teams to move forward with unwavering confidence.
Understanding the core tracking philosophy behind AccuRanker and Ahrefs reveals distinctly different approaches to monitoring digital visibility.
The digital landscape shifts beneath the feet of marketers every single second, demanding precision and unwavering accuracy from the tools designed to chart visibility. Behind every single data point lies a complex philosophy of metric capture that dictates how professionals interpret their online footprint. Navigating the modern search engine results page requires looking past the surface numbers to grasp the mechanical heartbeat powering each platform’s tracking engine.
While evaluating AccuRanker against Ahrefs reveals sharp SEO insights, modern digital growth truly accelerates when you optimize your twindo.ai solutions page keywords to capture high-value search traffic. Mastering these targeted terms bridges the exact gap between raw rank tracking data and comprehensive backlink intelligence, ultimately steering your brand toward unprecedented online visibility and lasting digital triumph.
Diving into the architectural blueprints of these software giants illuminates a fascinating divergence in digital DNA. One system was forged in the fires of laser-focused rank tracking, while the other expanded outward from a massive repository of backlink intelligence. Recognizing these foundational blueprints empowers digital strategists to harness each application’s greatest strengths, transforming raw telemetry into actionable market dominance.
Foundational tracking methodologies of AccuRanker and Ahrefs
The architectural foundation of AccuRanker is built upon a philosophy of hyper-focused, on-demand rank tracking that treats position monitoring as a real-time art form. By leveraging a distributed cloud infrastructure, AccuRanker queries search engines dynamically, pulling fresh data moments before a user logs into the dashboard. This approach prioritizes immediate velocity, ensuring that algorithm updates or sudden volatility appear on the screen almost as they happen in the wild.
The platform operates on a dedicated rank-tracking engine designed to handle massive volumes of s simultaneously without breaking a sweat, feeding hungry enterprise clients with continuous streams of precise local and global data.
Ahrefs approaches the digital visibility landscape through the lens of comprehensive web crawling and historical link mapping. Its tracking methodology is deeply intertwined with a colossal index of the internet, where positions are calculated as a secondary layer built upon a robust foundation of backlink and traffic estimation data. Instead of focusing solely on instantaneous on-demand queries, Ahrefs sweeps through millions of s on scheduled cycles, updating massive batches of ranking data according to predefined database refresh rates.
This structural difference means that visibility metrics in Ahrefs serve as panoramic overviews of overall domain health, connecting organic shifts directly to link acquisition campaigns and structural site modifications over extended timelines.
AccuRanker prioritizes instantaneous, on-demand visibility velocity, whereas Ahrefs anchors its ranking insights within a vast, interconnected ecosystem of web-wide link intelligence.
Visualizing this operational contrast brings the distinct engineering marvels of both systems into sharp focus. Imagine a high-precision digital observatory housing two radically different telescopes scanning the same vast digital cosmos. The first telescope functions like a specialized, agile interceptor lens mounted on a motorized gimbal, capable of instantly snapping clear, high-definition close-ups of specific target stars the exact moment a celestial shift occurs.
The second telescope operates as a massive, sweeping astronomical array that maps entire galaxies by continuously processing the gravitational pull of billions of interconnected light sources, plotting broad structural movements across the entire night sky over steady, measured intervals.
Data retrieval frequency and daily ranking observations
Data retrieval frequency dictates the rhythm of daily optimization routines, transforming raw database queries into actionable morning intelligence for modern search engine optimization teams. The temporal cadence at which a platform refreshes its indexes fundamentally alters how practitioners perceive sudden market fluctuations and competitor movements. Continuous daily retrieval fosters an agile operational environment where sudden drops are met with immediate investigative responses, while scheduled batch updates encourage a more macro-level, trend-focused strategic patience.
High-frequency data extraction eliminates the blind spots that typically plague traditional periodic monitoring cycles, preventing crucial ranking anomalies from slipping past unnoticed during critical campaign launches. When an algorithm update rolls out across search engine results pages, platforms with rapid data synchronization capture the exact trajectory of the turbulence. This immediate feedback loop allows digital marketing professionals to validate optimization hypotheses within hours rather than waiting days for the next scheduled system-wide index refresh, ultimately safeguarding revenue streams and stabilizing organic traffic acquisition.
Comparative metrics of update speeds and server infrastructure
Evaluating the underlying technical specifications requires examining how processing power and database architecture directly influence the speed and reliability of delivered metrics. The following comparative breakdown Artikels the key infrastructural differences governing how each platform processes and delivers ranking data to the end user.
| Platform Metric | AccuRanker Infrastructure | Ahrefs Infrastructure | Operational Impact |
|---|---|---|---|
| Update Mechanism | On-demand and scheduled daily real-time pulls | Scheduled database refreshes on set cycle loops | Determines immediacy versus macro-trend visibility |
| Server Architecture | Elastic cloud nodes optimized for concurrent API execution | Massive proprietary web crawler clusters and index hubs | Drives query speed and handling of massive volumes |
| Data Focus | Granular rank tracking and share of voice | Integrated metrics combining links, traffic, and ranks | Shapes whether the user sees localized precision or holistic scope |
| Refresh Latency | Near-zero latency during manual data refreshes | Standardized intervals varying by search volume | Affects how quickly sudden algorithm volatility is detected |
Historical evolution from separate niches into overlapping search marketing suites
The journey of both platforms represents a classic tale of specialized digital tools expanding their horizons to meet the ever-growing demands of enterprise-level search engine optimization. Understanding this evolution requires tracing their origins back to eras when search marketing tools were strictly segmented by utility, forcing practitioners to stitch together disparate software solutions to manage a single campaign effectively.
AccuRanker emerged in the European market as a direct response to the sluggish, unreliable nature of legacy rank trackers that forced users to wait days for stale reports. By prioritizing a clean user interface and lightning-fast API integrations, it captured the loyalty of agencies demanding absolute precision in monitoring. Over time, the platform expanded its feature set to include advanced metrics like Share of Voice, automated reporting, and robust integrations, evolving from a simple position-checking utility into a comprehensive visibility management suite.
Ahrefs began its market journey as a groundbreaking backlink analysis tool designed to map the hidden web of inbound link juice powering search engine authority. As its web-crawling capabilities scaled to unprecedented global proportions, the development team recognized the immense strategic value of pairing link data with position metrics. By introducing a massive organic search index and traffic valuation algorithms, Ahrefs systematically bridged the gap between technical link building and performance, transforming itself into an all-in-one marketing powerhouse that naturally overlapped with dedicated rank-tracking specialists.
Navigating the user interface and dashboard layout significantly alters daily workflow efficiency for professional search marketers.
Source: onehourprofessor.com
Stepping into the digital workspace of an enterprise-grade platform each morning sets the psychological and operational tone for an entire search marketing team. The architecture of a dashboard acts as the command center where colossal sets of algorithmic data transform into actionable human decisions, making the layout a critical factor in daily productivity.
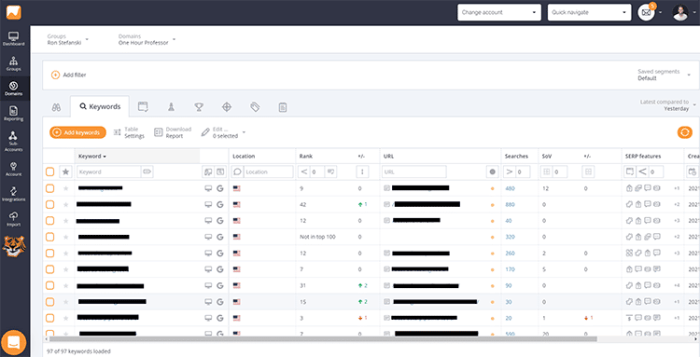
First impressions upon authenticating into AccuRanker reveal an interface engineered specifically for unyielding speed and laser-focused rank tracking. The visual hierarchy immediately directs the user’s gaze toward a clean, uncluttered canvas dominated by high-contrast metrics, where pastel green and soft red indicators flash subtle yet urgent fluctuations in positions. The sidebar menu acts as a minimalist anchor, stripping away distracting peripheral tools to keep the focus strictly on domains, lists, and immediate competitor movements.
Conversely, initiating a session within Ahrefs opens the gates to an expansive, sprawling intelligence metropolis. The screen greets the analyst with a heavily populated overview featuring modular, movable widget cards that aggregate backlink profiles, organic traffic estimations, and technical site health scores simultaneously. The navigation bar stretches boldly across the top, functioning like the dashboard of a modern aircraft with drop-down menus cascading into dozens of granular sub-reports.
While AccuRanker embraces a monochromatic, data-dense minimalism that prioritizes rapid-fire rank checks, Ahrefs envelops the practitioner in a vibrant, multi-layered ecosystem where every pixel invites deep exploratory mining of the broader search landscape.
Interface Customization and Shortcut Mechanisms
Managing multiple client portfolios or massive enterprise domains requires sophisticated shortcuts and personalized workspace configurations to prevent operational bottlenecks.
Professional agencies leverage these built-in navigational enhancements to drastically reduce repetitive mouse clicks during high-pressure audits.
- Keyboard shortcut overlays activated by pressing the question mark key allow instant jumping between specific domain overviews and tag filters without touching the trackpad.
- Customizable client-tagging filters enable enterprise teams to instantly segment thousands of s by geographical location, device type, or product category with a single click.
- Custom workspace views can be saved as default landing pages, ensuring that local specialists bypass macro-level metrics to land directly on localized map-pack rankings.
- Bulk action command bars permit administrators to select hundreds of disparate URLs or assets simultaneously for labeling, exporting, or priority re-checking.
Cognitive Load Reduction Through Alert Streamlining and Metric Pinboards
Bombarding analysts with constant data fluctuations drains mental stamina and obscures critical strategic pivots behind a wall of digital noise. Taming this information deluge demands strategic curation of notification parameters and the intentional architecture of custom-tailored metric pinboards.
Clarity in data presentation transforms reactive panic into proactive strategy, allowing search marketers to focus on algorithmic evolution rather than dashboard babysitting.
Establishing strict threshold-based alerts ensures that only statistically significant ranking movements—such as a sudden drop outside the top ten positions or a massive surge in local pack visibility—trigger immediate notifications via email or Slack integrations. By filtering out the day-to-day micro-volatility inherent in modern search engines, teams protect their cognitive bandwidth for high-level campaign structuring. Furthermore, constructing dedicated metric pinboards allows practitioners to pin only the Key Performance Indicators that directly align with current client quarterly goals.
Instead of scanning sprawling multi-column tables, an enterprise strategist opens a bespoke canvas where localized rank distributions, share of voice percentages, and immediate competitor displacement metrics sit side by side in clean, digestible visual modules. This deliberate compartmentalization eliminates visual clutter and fast-tracks the transition from raw data ingestion to executive-level decision making.
Visual Aesthetic and Architecture of Primary Reporting Canvases
The artistic and structural design of the primary reporting canvases dictates how effortlessly complex quantitative stories can be translated to stakeholders who demand immediate clarity.
The primary reporting canvas unfolds like a meticulously curated financial ledger designed for creative strategists, utilizing sweeping, unbroken line graphs that trace historical visibility trends against algorithmic update timelines. Soft gradients of slate gray and crisp white form the foundational backdrop, allowing luminous accent colors to highlight massive traffic potential gains or sudden ranking cliffs. Data tables within these canvases feature alternating row shading and generous padding, eliminating the claustrophobic feeling often associated with dense data repositories.
Subtle tooltips expand smoothly upon hover, offering micro-contextual insights without forcing the user to navigate away from the primary view. The layout breathes organically, giving heavy data points the visual weight they deserve while relegating ancillary metadata to collapsible accordion menus. This careful balance of whitespace and typography ensures that whether an analyst is reviewing a quick morning health check or presenting a multi-million-dollar organic growth forecast to a corporate board, the visual journey remains intuitive, elegant, and profoundly authoritative.
Evaluating historical ranking data storage and retrieval speeds highlights the technical boundaries of massive database management.
Delving into the digital archives of premier search intelligence platforms reveals a staggering engineering feat operating quietly behind the glowing screens of modern marketers. Every single day, billions of data points representing positions, search volumes, and fluctuating visibility metrics flow into vast, centralized server farms. Preserving this relentless deluge of digital footprints demands an intricate choreography of distributed architecture, cold-storage tiers, and lightning-fast indexing mechanisms.
When professionals demand to look backward across years of volatile algorithm updates, they rely on robust archival systems designed to compress historical records without sacrificing the granular integrity required for enterprise-level forecasting and competitive analysis.
The mechanical heartbeat of multi-year performance archiving relies heavily on a tiered data storage strategy that balances lightning-fast operational memory with cost-effective, long-term persistence layers. Active tracking data from the past several months typically resides in high-performance, in-memory databases or heavily indexed Solid State Drive arrays, enabling instantaneous access for routine dashboard interactions. As these records age past specific temporal thresholds, sophisticated automated scripts initiate a compression sequence, migrating older weekly and monthly aggregates into columnar storage formats like Apache Parquet or optimized distributed data lakes.
This transformation significantly reduces the physical footprint of massive portfolios while maintaining the relational integrity necessary for longitudinal trend analysis. Furthermore, time-series databases handle the continuous influx of daily rankings by partitioning data points into discrete chronological shards, ensuring that queries spanning multiple years do not bottleneck the primary input-output operations. By employing distributed consensus algorithms and continuous asynchronous replication across multiple geographic server zones, these platforms guarantee both disaster recovery resilience and uncompromised availability for global marketing teams hunting for historical anomalies.
Data retention limits and export constraints
Navigating the boundaries of archival longevity requires a clear understanding of platform thresholds, as enterprise portfolios generate immense volumes of metrics that challenge even the most advanced cloud storage architectures. The table below Artikels the operational boundaries governing data preservation and extraction capabilities across professional rank tracking environments.
| Platform Tier | Historical Data Retention | Maximum Export Row Limit | Data Granularity Preservation |
|---|---|---|---|
| Standard Professional | Up to 24 Months | 50,000 Rows per CSV | Daily Aggregates After 90 Days |
| Enterprise Dedicated | Unlimited / Custom Archive | 1,000,000+ Rows via API | Uncompressed Daily Metrics |
| Agency Multi-Account | 36 Months Rolling Window | 250,000 Rows per Export | Weekly Summaries Past One Year |
Database query performance during massive portfolio filtering
Executing complex queries across millions of permutations within hyper-competitive regional markets tests the absolute limits of relational database indexing and parallel processing frameworks. When an enterprise user applies multiple simultaneous filters—such as filtering for top-three ranking movements, specific landing page URLs, and localized zip codes across a portfolio exceeding one hundred thousand s—the underlying database management system must instantly evaluate millions of discrete rows.
Achieving sub-second response times in these scenarios is impossible through traditional row-oriented database structures, necessitating the implementation of advanced indexing techniques like bitmap indexes and inverted search trees.
Optimized database architectures utilize distributed query engines that dynamically break down sweeping search visibility requests into parallel execution threads, distributing the computational load across dozens of worker nodes simultaneously.
This parallelized approach ensures that heavy analytical workloads initiated by one user do not degrade the overall responsiveness of the platform for concurrent global users. Consequently, professional digital marketers can seamlessly slice and dice colossal datasets without experiencing frustrating processing latency, maintaining an uninterrupted state of strategic workflow immersion.
Hyper-targeted local search performance archiving
Capturing and storing hyper-localized search performance introduces an exponential layer of complexity, as search engine results pages vary wildly down to specific street coordinates and postal codes. To accurately archive these hyper-targeted metrics, tracking infrastructures deploy specialized query agents that simulate user queries from exact geographic nodes using proxy networks distributed across hundreds of distinct municipalities. Each captured snapshot includes not only the standard ranking position, but also localized map pack listings, featured snippet ownership, and hyper-local knowledge graph integrations.
Navigating accuranker vs ahrefs reveals distinct SEO tracking insights, much like mapping corporate landscapes to discover that assetworks inc headquarters city and state resides in vibrant Twinsburg, Ohio. This surprising geographical anchor inspires fresh strategic momentum, empowering digital marketers to conquer competitive search rankings with precision clarity and unstoppable optimism.
Storing this multi-dimensional spatial data requires spatial indexing extensions—such as PostGIS-enabled database schemas—which map ranking fluctuations onto geographic coordinate grids with pinpoint accuracy. For example, a national retail chain tracking ranking variances across five thousand distinct store locations generates millions of localized data points weekly, all of which must be indexed against specific latitude and longitude boundaries to yield meaningful local visibility scores over extended multi-year campaigns.
Uncovering hidden competitors through automated discovery algorithms transforms how digital strategists map out market share dominance.

Source: buttercms.com
Modern search environments no longer limit market rivalry to traditional brick-and-mortar boundaries or self-proclaimed industry leaders. Advanced digital intelligence platforms constantly scan millions of vectors to unearth unexpected challengers quietly capturing valuable traffic. Grasping this dynamic requires looking beneath the surface of standard search engine results pages to observe how machine learning models connect dots invisible to the human eye.
Strategists now rely on sophisticated discovery engines that parse semantic relationships and query overlaps in real time, shifting the entire paradigm of competitive intelligence from reactive observation to proactive dominance.
The underlying mechanical routines deployed by these platforms rely on multi-layered vector space modeling and probabilistic graph theory. When a software crawler ingests thousands of rankings daily, it does not merely log positions; it maps semantic clusters based on shared audience intent. Algorithmic engines calculate matrix factorizations to identify domains that consistently appear within the top twenty organic results for identical groups, even if those domains operate in entirely different vertical markets.
For instance, a lifestyle blog might suddenly surface as a primary revenue threat to a specialized e-commerce retailer because both converge on long-tail informational queries that drive high-intent buyers. By continuously feeding historical clickstream data and localized search variations into neural clustering models, the discovery suite isolates structural correlations. These calculations measure the exact frequency with which two distinct web properties share screen real estate across volatile algorithm updates.
Consequently, digital strategists gain a crystal-clear lens into non-obvious market contenders, revealing digital entities that siphon off prospective customers long before traditional market research reports ever identify them as legitimate threats.
Algorithmic parameter metrics for competitive overlap scoring
Evaluating the true extent of market intrusion demands a standardized framework of quantitative indicators. The table below Artikels the core metric parameters utilized by modern algorithms to calculate exact domain overlap and visibility collision rates.
| Metric Parameter | Mathematical Basis | Strategic Interpretation | Industry Benchmark |
|---|---|---|---|
| Confluence Score | Jaccard similarity coefficient of ranked terms | Measures the exact percentage of shared vocabulary between two distinct domains. | Greater than fifteen percent indicates direct market rivalry. |
| Visibility Entropy Index | Shannon entropy formula applied to rank volatility | Quantifies how unpredictable a competitor’s ranking fluctuations are over time. | Low entropy signifies entrenched market authority. |
| Traffic Value Density | Estimated monthly click volume multiplied by CPC | Calculates the monetary worth of organic traffic captured by the rival domain. | Varies heavily by niche monetization models. |
| Intent Vector Alignment | Cosine similarity of user intent classifications | Determines if the rival targets informational, navigational, or transactional queries. | Alignment above eighty percent signals direct audience theft. |
Methodologies for eliminating low-value domain noise
Raw algorithmic data frequently introduces massive amounts of irrelevant noise, ranging from massive content aggregators to sudden viral flash-in-the-pan forums that distort true market analysis. Successfully isolating genuine industry adversaries requires implementing strict, multi-tiered filtration protocols that purge statistical anomalies from daily reports. Professional search marketers apply rigorous threshold parameters to ensure that only economically significant entities command strategic attention.
- Excluding massive user-generated content platforms and generic dictionary sites that rank for millions of unrelated terms without driving targeted conversions.
- Setting minimum thresholds for estimated commercial traffic value, ensuring that rival domains possess actual purchasing power influence rather than vanity rankings.
- Filtering out short-lived algorithmic anomalies by requiring a minimum persistence window of thirty consecutive days within the shared top twenty search results.
- Segmenting domain categories based on strict vertical taxonomy to separate direct product competitors from broad informational publishers.
Tracking protocols for emerging algorithmic disruptors
Market stability is an illusion in contemporary search landscapes, where new algorithmic disruptors can capture top-tier visibility overnight through aggressive topical authority scaling or programmatic content execution. Detecting these rapid shifts before they erode market share requires deploying continuous monitoring frameworks that alert strategists the moment an unknown domain breaks ranking thresholds. Real-life cases from recent retail algorithm rollouts demonstrate how nimble direct-to-consumer brands bypassed legacy giants within weeks by exploiting structural gaps in product schema implementation.
To replicate this level of vigilance, tracking systems utilize automated trigger alerts based on sudden velocity spikes in acquisition. When an unmapped domain exhibits a compounding growth rate in shared target s exceeding a pre-set percentage within a seven-day cycle, the intelligence platform flags the entity for immediate manual audit. This rapid-response workflow ensures that digital marketing teams can swiftly counter emerging threats, adapt their content optimization strategies, and defend their hard-earned search real estate against agile new market entrants.
While mastering AccuRanker versus Ahrefs sharpens digital visibility, modern commerce also demands seamless checkout experiences, making a retail ipad pos essential for empowering sleek transactions on glowing storefront counters. Elevating your brand requires precision marketing tools alongside efficient sales gear, ensuring every data driven insight gained from comparing AccuRanker versus Ahrefs transforms straight into undeniable retail growth and lasting customer loyalty.
Integrating external data sources via application programming interfaces expands the operational boundaries of both platforms.: Accuranker Vs Ahrefs

Source: samblogs.com
Modern digital marketing ecosystems thrive on connectivity, pushing analytics engines far beyond their native browser interfaces into the realms of custom software pipelines and automated enterprise intelligence. True operational mastery emerges when search metrics stop living in isolated silos and begin flowing freely through the digital veins of a corporate infrastructure. AccuRanker and Ahrefs provide robust application programming interfaces that invite developers to bridge the gap between raw rank tracking data and comprehensive business intelligence dashboards.
Unlocking this potential requires a deep dive into the architectural capabilities of both systems, examining how webhooks, developer documentation, authentication standards, and rate limits dictate the rhythm of enterprise data synchronization.
Webhook integrations and developer documentation endpoints, Accuranker vs ahrefs
Building responsive data architectures relies heavily on real-time event notifications and clear technical blueprints. AccuRanker approaches this through a streamlined webhook system designed to instantly broadcast ranking updates, additions, and deletion events directly to external endpoints as soon as daily background checks conclude. This event-driven philosophy allows engineering teams to trigger downstream processes, such as localized alerts or immediate database refreshes, without resorting to resource-heavy polling scripts.
Developer documentation for AccuRanker Artikels clean, resource-oriented REST endpoints using standard HTTP response codes and JSON payloads, making it remarkably straightforward for modern web developers to parse ranking fluctuations on the fly. Ahrefs approaches external extensibility through its robust API V3, which supplies programmatic access to massive historical index metrics, backlink profiles, and organic traffic estimates. While Ahrefs relies less on real-time webhooks due to the colossal scale of its web crawler databases, its developer portal provides exhaustive documentation featuring interactive code snippets in Python, cURL, and JavaScript.
The API endpoints are meticulously structured to support granular filtering, sorting, and pagination, allowing data engineers to extract precise subsets of petabyte-scale link datasets. Comprehensive endpoint documentation ensures that development teams spend less time deciphering ambiguous parameters and more time architecting seamless data pipelines that feed executive dashboards with laser-accurate search visibility metrics.
Automated reporting pipelines linked to cloud storage providers
Establishing continuous data flows between cloud repositories and platforms eliminates manual CSV downloads and human error. Modern automated reporting pipelines rely on scheduled orchestration tools like Apache Airflow or serverless functions to periodically query API endpoints and safely deposit raw JSON or CSV payloads directly into scalable cloud storage layers.
- Executing daily cron jobs to fetch fresh AccuRanker ranking arrays and staging the compressed outputs inside Amazon S3 buckets for downstream transformation.
- Triggering Google Cloud Functions via Cloud Scheduler to ingest massive Ahrefs backlink export reports and automatically load them into BigQuery tables for ad-hoc SQL analysis.
- Leveraging Azure Blob Storage alongside custom Python microservices to archive historical performance snapshots, ensuring long-term auditability and regulatory compliance.
- Configuring automated error-handling loops that dispatch Slack notifications whenever an API data ingestion job encounters rate-limiting throttles or payload parsing anomalies.
Rate limits and authentication protocols for enterprise data warehousing
Enterprise data warehousing demands strict adherence to security standards and predictable throughput to prevent pipeline failures during critical executive reporting cycles. AccuRanker enforces authentication primarily through secure API tokens generated within user account settings, which must be passed cleanly in the request headers for every transaction. Their rate-limiting framework is designed to protect server stability while accommodating high-volume users, typically measured in requests per minute, requiring client-side queuing mechanisms during massive bulk data pulls.
Navigating accuranker vs ahrefs reveals crucial ranking insights, much like reviewing the verified sharpcloud ltd company status 2022-2026 to chart steady corporate resilience and growth. By harnessing these sharp analytics, digital pioneers confidently decode market trends, empowering every strategic SEO leap forward.
Securing enterprise synchronization pipelines requires robust token rotation policies and exponential backoff algorithms to gracefully manage API rate limits during peak analytics processing hours.
Ahrefs utilizes robust OAuth 2.0 protocols and project-specific API keys depending on the tier of service, ensuring that enterprise applications authenticate securely with granular permission scopes. Because Ahrefs indexes trillions of links and s, its rate-limiting architecture is tied directly to API credit consumption models. Enterprise data architects must carefully calculate credit expenditure rates, implementing intelligent caching layers and incremental data fetching strategies to avoid exhausting daily or monthly allocations prematurely during heavy data warehouse synchronization tasks.
Custom visualization scripts built on top of raw metric exports
Raw numbers stored in a database rarely tell a compelling story to stakeholders without the aid of tailored visual interfaces designed to highlight actionable insights. Transforming extracted metric arrays into intuitive, executive-ready charts requires custom visualization scripts written in modern languages like Python using Streamlit or R using Shiny. Visual storytelling elements can be meticulously crafted to display a glowing, deep-blue heatmap representing organic distribution across the top three search engine result page positions, shifting dynamically as seasonality alters consumer search intent.
Alongside the heatmap, interactive line graphs trace historical visibility index trajectories over a rolling twenty-four-month period, utilizing high-contrast vector lines to clearly delineate algorithmic core updates from standard market fluctuations. Custom scripts also empower growth marketers to overlay proprietary internal conversion revenue data directly on top of Ahrefs traffic estimation curves, rendering a vivid dual-axis scatter plot that proves the exact monetary ROI of targeted content optimization efforts.
By bypassing standard dashboard limitations, these bespoke visualizations turn complex arrays of algorithmic data into clear, persuasive narratives that drive high-level strategic alignment.
Assessing financial investments against organizational scale requires careful calculation of feature utility versus monthly overhead.

Source: shoutmeloud.com
Navigating the complex financial landscape of modern enterprise software requires a meticulous balancing act between feature richness and fiscal sustainability. When digital marketing agencies and enterprise teams weigh their software expenditures, every dollar spent must directly correlate with operational efficiency and measurable client ROI. Financial forecasting in the digital marketing sector is no longer just about keeping operational costs low; it is about strategically deploying capital into tools that accelerate market dominance and secure a competitive advantage in an increasingly crowded digital ecosystem.
Understanding the true cost of ownership demands a comprehensive look beyond the baseline sticker price, delving deep into the operational limitations, user seat models, and hidden scaling fees associated with industry-leading intelligence platforms. As organizations expand their client rosters and data processing requirements, the architecture of their chosen tracking ecosystem dictates the financial trajectory of their growth.
Subscription tier structures and user seat limitations
The financial commitment required for professional infrastructure is dictated by rigid tiered models that govern feature access, data refresh frequencies, and team collaboration capabilities. AccuRanker positions its pricing model tightly around the volume of s tracked, offering granular scalability where users pay strictly for the exact number of tracking slots they consume. This token-based or -tiered flexibility allows boutique agencies to scale their inventory up or down dynamically without being forced into exorbitant enterprise leaps, though it implements strict caps on user seats depending on the chosen tier, often requiring supplemental licensing fees for larger collaborative teams.
Conversely, Ahrefs operates on a more traditional, rigid plateau model anchored by fixed monthly subscription tiers such as Lite, Standard, Advanced, and Enterprise. Each step up the Ahrefs pricing ladder unlocks broader historical data depths, higher daily query limits, and expanded access to advanced modules like the Content Explorer and Site Audit crawlers. However, Ahrefs historically enforces strict limits on included user seats and concurrent project setups, compelling growing agencies to purchase additional user licenses or face operational bottlenecks when multiple strategists attempt to analyze backlink profiles simultaneously.
Visualizing this operational environment reveals a bustling, high-stakes corporate command center where financial controllers meticulously map out software expenditure against client deliverables. Imagine a sleek, minimalist financial dashboard glowing softly in a dimly lit corner office, displaying real-time graphs of monthly software overhead juxtaposed against incoming retainer revenues, highlighting the exact tipping point where a tier upgrade becomes financially justifiable.
To navigate these subscription structures effectively, agencies must evaluate their internal workflows and data consumption habits thoroughly before committing to long-term billing cycles. The following guidelines Artikel critical considerations for selecting the optimal organizational tier:
- Audit historical tracking volume to prevent over-provisioning and eliminate wasted expenditure on dormant data slots.
- Analyze team collaboration frequency to determine whether baseline user seats suffice or if budgeting for supplementary licenses is mathematically mandatory.
- Calculate the frequency of deep analytical crawls required by high-value enterprise accounts to justify stepping into higher-tier data limits.
- Review contract terms and billing cycles to capitalize on annual prepayment discounts offered by software vendors for predictable cash flow management.
Comparative analysis of platform pricing and administrative structures
Evaluating the financial efficiency of tracking and backlink intelligence tools requires a standardized metric system that breaks down raw subscription costs into actionable cost-per-domain ratios. Administrative overhead often lurks beneath the surface of baseline invoices, encompassing everything from user seat management to specialized data processing add-ons that accumulate over time.
| Platform Tier Focus | Approximate Monthly Investment | Cost Efficiency per Tracked Domain | Administrative & User Seat Impact |
|---|---|---|---|
| AccuRanker Entry Tier | Moderate (Volume-Based) | High for dense sets per domain | Low base seats; extra user fees apply at scale |
| AccuRanker Enterprise Tier | High (Custom Volume) | Maximum scalability for large portfolios | Scalable seat allocation with enterprise support |
| Ahrefs Standard Tier | Fixed Mid-Range | Optimal for moderate backlink analysis needs | Strict single-user or limited seat caps |
| Ahrefs Advanced/Enterprise | High Fixed Overhead | Superior value for heavy data crawling needs | Additional user licenses incur recurring monthly costs |
The structural disparity between a -centric volume pricing model and a feature-gated plateau model fundamentally changes how digital marketing agencies forecast their quarterly software budgets. While volume-based scaling rewards precision management, fixed-tier models reward heavy exploratory research and expansive link-building campaigns, making the choice heavily dependent on an agency’s core service offerings.
Hidden financial liabilities in API overages and team licensing
Operational friction frequently materializes in the form of unexpected budgetary bleed caused by platform limitations and consumption-based overages. When digital agencies scale their operations, internal data pipelines often rely on automated application programming interfaces to feed custom client reporting dashboards and proprietary intelligence systems. Both platforms enforce strict daily and monthly limits on API calls, and exceeding these thresholds triggers immediate financial penalties or throttled data delivery, which can cripple client-facing reporting schedules during critical campaign reviews.
Furthermore, the cost of scaling human capital within the software ecosystem presents a subtle yet persistent financial drain. As agencies onboard new specialists, content strategists, and account managers, the need for concurrent user access expands rapidly. When baseline subscription tiers cap user seats at restrictive levels, organizations are forced into purchasing expensive block licenses for additional team members. Over a fiscal year, these seemingly minor per-user surcharges compound significantly, eroding profit margins on fixed-fee client retainers if not properly accounted for during initial budget formulation.
“Sustainable software profitability is achieved not by purchasing the most expensive ecosystem available, but by aggressively aligning API consumption thresholds and user seat allocations with actual, billable client output.”
Consider the real-world case of a mid-sized digital marketing agency managing over fifty enterprise e-commerce clients that suffered a twenty percent drop in quarterly software ROI due to unmonitored API call overages during a massive site migration audit. By implementing automated usage alerts and restricting raw data pulls to scheduled off-peak hours, the agency successfully reclaimed thousands of dollars in wasted overhead, proving that technical governance is just as vital as financial planning.
Strategic budget allocation models for expanding digital agencies
Maximizing the return on investment for enterprise software demands a disciplined, proactive approach to capital deployment that mirrors the rigorous financial strategies of top-tier venture capital firms. Growing agencies cannot afford to treat software subscriptions as static, set-it-and-forget-it line items; instead, they must implement dynamic budget allocation models that adapt to shifting client demands and seasonal campaign fluctuations. By continuously auditing software utilization rates and pruning redundant toolsets, marketing leaders can redirect capital toward high-impact data modules that directly drive revenue growth.
Building a resilient financial strategy involves diversifying software dependencies while ensuring that mission-critical tracking infrastructure remains fully funded even during economic downturns or client churn events. The following structured approach Artikels how progressive agencies optimize their technology stack investments:
- Establish a centralized software procurement committee tasked with reviewing tool utilization metrics and API consumption reports on a strict quarterly basis.
- Negotiate custom enterprise agreements that bundle high-demand features and additional user seats into predictable, locked-in annual billing structures.
- Implement strict internal chargeback or client-pass-through billing models for specialized data processing tasks and heavy API usage tied to specific enterprise accounts.
- Maintain a dedicated technological innovation fund reserved for testing emerging intelligence platforms, ensuring the agency remains at the bleeding edge of search marketing efficiency.
Gauging the accuracy and precision of rank fluctuations uncovers the reliability of automated search engine result page scrapers.

Source: buttercms.com
Beneath the surface of every clean analytics graph lies a relentless digital warfare zone. Automated engines constantly clash with sophisticated security gatekeepers, striving to capture an authentic snapshot of search engine result pages before algorithms shift again.
Modern search visibility platforms operate on complex engineering frameworks designed to harvest data at scale without triggering security alarms. When monitoring millions of s daily, platforms must execute requests that mimic genuine human interaction while maintaining blindingly fast processing speeds. Behind every reported position shift rests a sophisticated machinery of engineering maneuvers built to outsmart modern web defenses.
Technical mechanics of proxy rotation and headless browser deployment
Enterprise tracking platforms deploy massive, distributed architectures to harvest search engine results continuously. At the core of this operation lies the integration of advanced proxy rotation networks. These networks route automated requests through millions of residential, datacenter, and mobile IP addresses across specific geographic coordinates. By constantly shifting the source of each network packet, tracking tools prevent target search engines from identifying patterns and slapping the scrapers with permanent IP bans.
Complementing these IP pools are headless browser technologies—instances of Chrome or Firefox running without a graphical user interface. These browsers execute complex JavaScript, load CSS stylesheets, and render document object models just like a physical device sitting on a desk. To slip past aggressive bot detection systems like Cloudflare or proprietary search engine firewalls, these headless instances spoof user-agents, inject randomized mouse-movement telemetry, manage complex cookie lifecycles, and solve invisible cryptographic challenges in milliseconds.
Precision in rank tracking is not merely about pulling raw HTML; it is an ongoing technological arms race to emulate human behavior at machine scale.
Edge cases of search engine localization distorting positional data
Global visibility reports frequently run aground on the jagged rocks of hyper-local search intent and personalization variables. Even when coordinates are locked to a specific zip code, subtle variations in data parsing can completely skew the final metrics delivered to a marketer’s dashboard.
- Hyper-local radius shifts cause rankings to swing wildly between neighboring city blocks due to hyper-targeted local pack algorithm triggers.
- Personalized search history injection skews automated scrapers that lack pristine, untainted browsing cookies, reflecting a ghost user rather than a neutral baseline.
- Real-time query intent re-ranking dynamically alters difficulty metrics based on breaking news cycles or sudden spikes in regional search volume.
- Multi-language regional variations and automatic country-code top-level domain redirection force scrapers into unintended localization loops.
Verification methodologies for sudden ranking drops
When a primary dashboard flashes a catastrophic drop in positions, professional search marketers never take the automated alert at face value. A sudden plunge might indicate a genuine algorithmic penalty, a technical site failure, or simply a temporary glitch in the data harvesting pipeline.
To separate reality from digital phantom noise, analysts execute structured verification protocols. First, they bypass the automated crawler by initiating manual browser checks through virtual private networks configured to the exact geographic coordinates of the target market. They clear local caches and utilize incognito modes to establish a clean slate. Next, they cross-reference the anomalous data point against secondary and tertiary rank-tracking tools to see if the drop is universally observed across competing scraping infrastructures.
Finally, they inspect server log files to confirm whether search engine bots successfully crawled the affected landing pages during the exact window of the reported drop, ensuring the issue stems from ranking algorithms rather than server downtime or accidental robotic exclusion tags.
Device emulation variances impacting metric authenticity
The digital world fractures the moment a user moves from a desktop monitor to a smartphone screen, and automated rank trackers must mirror this structural divide. Desktop versus mobile device emulation goes far beyond simply shrinking a viewport width; it dictates an entirely different layout of the search engine results page. Mobile layouts introduce heavy ad saturation, collapsible knowledge graphs, inline image carousels, and accordion features that push organic search listings deep below the fold.
When tracking software emulates a mobile device, it must accurately simulate mobile user-agents, touch-event APIs, and constrained hardware processing limitations. If a platform relies on lightweight mobile user-agent strings while fetching desktop HTML layouts, the reported pixel-depth and ranking positions become fundamentally corrupted. True mobile emulation ensures that the invisible distance between the top of the screen and the first organic blue link reflects what a mobile consumer actually experiences in the wild.
Last Point
Mastering the intricacies of digital visibility is an ongoing journey of discovery, where choosing the right ally can elevate a brand from obscurity to market dominance. Whether leaning into the lightning-fast, dedicated rank precision of one or the sprawling, interconnected domain intelligence of the other, the ultimate victory belongs to those who interpret the data with vision and purpose. Embrace these powerful insights, refine your strategy, and watch as your digital presence rises to meet the boundless possibilities of tomorrow.
