exportable data for analysis serves as the vital bridge connecting raw digital inputs to profound operational breakthroughs across global industries. Deep within humming, temperature-controlled server sanctuaries, technicians meticulously liberate rigid ledgers from proprietary systems, breathing new life into historical weather models, volatile financial markets, and sprawling biomedical matrices.
When enterprise networks pulse with unchained metrics, researchers and analysts gain the unprecedented power to decode complex trends. By stripping away software silos and standardizing formats like comma-separated values and extensible markup language, modern organizations transform static numbers into dynamic catalysts for discovery, collaboration, and sustainable growth.
Digital information portability transforms how researchers study historical meteorological trends and global supply chain fluctuations.

Source: r2.dev
In an era where every degree shift in global temperature and every microsecond delay in maritime shipping alters economic realities, the ability to effortlessly move massive datasets has become the lifeblood of modern scientific inquiry and logistical strategy. Researchers unlocking centuries of atmospheric pressure records and multinational corporations mapping the labyrinthine paths of container vessels no longer remain tethered to the proprietary silos of yesterday.
Instead, they harness the fluid movement of exportable data to illuminate unseen patterns, turning static numbers into dynamic narratives that shape our understanding of a changing planet and interconnected markets.
Raw exportable data for analysis illuminates hidden financial truths beneath daily administrative operations. Modern institutions are now implementing accounting software for schools to effortlessly organize complex ledgers into crystal clear records. Harnessing these breakthroughs empowers leaders to transform scattered digital numbers into strategic insights that successfully guide future educational growth.
The journey of transforming locked digital archives into actionable intelligence begins at the very foundation of software architecture. Traditional database management systems often trap records behind proprietary walls, utilizing specialized query languages and encrypted binary structures designed to discourage external access. Liberating spreadsheets from these walled gardens requires a deliberate dismantling of vendor lock-in through abstraction layers and standardized parsing engines.
Technicians deploy intermediary translation scripts that strip away proprietary headers and binary wrappers, exposing the raw numerical matrices underneath. By converting these closed structures into open, standardized text streams, systems can finally read, transport, and analyze information without needing the original software ecosystem that birthed it.
Comparative Analysis of Exportable Data Formats
Choosing the correct medium for data transportation is a critical architectural decision that dictates how efficiently algorithms parse historical climate telemetry or maritime manifests. The landscape of exportable formats offers distinct structural philosophies, each balancing human readability, parsing speed, and hierarchical depth in unique ways.
| Format Name | Primary Structural Characteristic | Ideal Analytical Use Case | Human Readability |
|---|---|---|---|
| Comma-Separated Values (CSV) | Flat tabular text with delimiter-separated fields and row breaks. | Massive meteorological spreadsheets and simple transactional logs. | High |
| Extensible Markup Language (XML) | Strictly validated tree structures utilizing custom tags and attributes. | Complex supply chain manifests requiring rigorous schema enforcement. | Moderate |
| JavaScript Object Notation (JSON) | Lightweight key-value pairs and ordered lists natively aligned with web APIs. | Real-time global freight tracking and dynamic weather sensor feeds. | High |
| Binary Serialization Formats | Compressed, machine-optimized byte streams bypassing text translation. | Petabyte-scale historical climate simulations and deep learning pipelines. | None |
Preservation of Metadata Integrity During Legacy Extraction
Extracting numerical records from aging mainframe servers risks stripping away the contextual DNA that gives those numbers scientific and economic validity. Metadata—encompassing timestamps, coordinate projections, instrument calibration logs, and provenance histories—serves as the critical anchor preventing raw data from becoming meaningless noise. During the extraction phase, engineers must wrap numerical payloads in standardized semantic envelopes, ensuring that a temperature reading recorded in 1895 London retains its exact spatial coordinates, time zone offset, and sensor accuracy metrics.
Failing to preserve this intricate web of contextual data turns valuable historical baselines into ambiguous points of failure.
Metadata is the silent witness of data provenance; without it, numerical records are merely ghosts haunting a digital void.
Modern data pipelines combat degradation by employing sidecar files and embedded schema definitions that travel directly alongside the numerical payloads. When algorithms harvest records from legacy SQL databases or flat-file archives, automated validation routines cross-reference every data point against predefined JSON schemas. This rigorous verification process guarantees that missing fields, truncated decimals, or altered date formats are caught immediately, safeguarding the historical fidelity required for long-term climate modeling and predictive supply chain analytics.
Technical Methodologies for Preventing Data Corruption Across Operating Systems, Exportable data for analysis
Shifting petabyte-scale database archives across disparate operating systems—such as migrating historical meteorological logs from legacy UNIX mainframes to modern Linux cloud clusters—exposes information streams to silent corruption caused by endianness mismatches, character encoding discrepancies, and network packet loss. To counteract these systemic vulnerabilities, systems architects implement end-to-end cryptographic hashing protocols, predominantly utilizing SHA-256 algorithms. Before a massive archive departs its origin environment, a unique cryptographic checksum is generated.
Raw exportable data for analysis fuels modern business breakthroughs, transforming chaotic digital streams into crystal clear strategic insights. Organizations can unlock ultimate scalability by evaluating test.com pricing enterprise plans to discover advanced analytical tools. Embracing these powerful resources empowers teams to turn complex metrics into extraordinary success stories and drive future growth.
Upon arrival at the destination operating system, the archive undergoes an identical hashing calculation. If the resulting strings match perfectly, the data transfer is verified as pristine, ensuring that not a single bit of a century-old temperature log or global shipping manifest has been altered by operating system translation anomalies.
Furthermore, engineers utilize network-level error-correcting transmission protocols combined with containerized virtualization environments to neutralize environmental discrepancies between source and target systems. By encapsulating database archives within standardized Docker containers running isolated file systems, the underlying operating system kernel differences—such as how Windows handles carriage return line feeds compared to POSIX-compliant systems—are effectively neutralized. During massive migrations involving global supply chain telemetry, automated staging servers chunk continuous data streams into manageable multi-gigabyte segments.
Each segment undergoes immediate verification and parallel insertion into distributed databases like Apache Cassandra or PostgreSQL. This modular transfer strategy ensures that if a localized hardware failure or network interruption occurs mid-migration, only the specific corrupted segment is re-transmitted, preserving the integrity of the broader archival migration without requiring a resource-intensive restart of the entire multi-terabyte operation.
Transportable numerical ledgers empower financial institutions to conduct rigorous statistical evaluations of volatile market behaviors.
Modern banking ecosystems rely heavily on the seamless flow of portable financial data to decode unpredictable economic shifts and forecast future market trajectories. When institutions harness clean, exportable ledgers, risk management teams gain the empirical foundation needed to survive turbulent trading cycles. This capability transforms raw, chaotic market signals into actionable intelligence, ensuring capital reserves remain stable during unexpected fiscal downturns.
Security protocols required when transmitting sensitive fiscal documents through encrypted transmission channels
Safeguarding proprietary monetary files during transit demands an uncompromising approach to cryptographic defense and network architecture. Financial institutions must implement robust end-to-end encryption frameworks, utilizing advanced cryptographic algorithms such as Advanced Encryption Standard 256-bit keys to shield data packets from malicious interception. Furthermore, strict access controls and multi-factor authentication mechanisms ensure that only authorized personnel can decrypt and ingest the incoming numerical ledgers.
Network administrators routinely deploy virtual private networks paired with secure shell protocols to establish impenetrable tunnels across public and private infrastructure, thereby neutralizing the threat of man-in-the-middle attacks during high-speed data transfers.
Step-by-step procedure for scrubbing personally identifiable information prior to external distribution
Before releasing datasets to external research partners or regulatory bodies, data governance teams must execute a meticulous sanitization process to eliminate all traces of sensitive client identities. This preemptive cleansing protects individual privacy rights while complying with stringent global regulatory standards like the General Data Protection Regulation. The following sequential workflow Artikels the precise actions required to neutralize exposure risks before files leave the secure corporate perimeter.
- Audit the entire incoming database to map every column containing client names, social security numbers, residential addresses, and direct communication channels.
- Execute automated masking scripts to substitute real user identifiers with randomized alphanumeric cryptographic hashes that preserve relational integrity without revealing true identities.
- Apply differential privacy algorithms to numerical ledgers, introducing controlled statistical noise to aggregate metrics so that individual financial behaviors cannot be reverse-engineered.
- Conduct a comprehensive manual sampling inspection of the sanitized dataset to verify that zero plaintext personal identifiers remain in the exportable files.
- Generate an immutable compliance log detailing the exact timestamp, scrubbing methodology, and technician credentials before authorizing the final file release.
Visual representation of a secure subterranean server facility processing liberated economic metrics
Deep beneath the bedrock, nestled behind reinforced titanium blast doors, a subterranean data bunker hums with relentless energy as it ingests vast oceans of global market telemetry. Rows upon rows of high-density blade servers stretch into the gloom, their matte black chassis punctuated by rhythmic, cascading arrays of amber warning lights that pulse like the nervous system of an awakened digital titan.
Harnessing exportable data for analysis empowers creators to decode intricate digital metrics with absolute clarity. As teams evaluate production expenses, understanding the cost of starlight mini cloud processing in topaz video illuminates brilliant pathways toward optimized visual enhancement. Ultimately, leveraging these precise exportable data for analysis insights fuels smarter decisions and drives groundbreaking project success forward.
Cooling systems roar softly, venting freezing mist across polished concrete floors while terabytes of liberated economic metrics cascade through fiber-optic backplanes at the speed of light. In this high-security sanctum, automated processors continuously parse through millions of volatile fiscal data points, converting raw trade fluctuations into pristine statistical ledgers that will soon dictate the financial strategies of major international banks.
Psychological hurdles analysts face when adapting to freshly imported spreadsheet structures from rival corporate departments
Stepping into a foreign analytical environment often triggers profound cognitive friction among quantitative specialists accustomed to legacy workflows and proprietary corporate taxonomies. When a financial analyst receives a newly imported spreadsheet originating from a rival department or recently acquired subsidiary, the immediate reaction is rarely one of seamless integration; instead, a palpable wave of institutional anxiety permeates the workspace. Analysts spend precious hours deciphering undocumented macro scripts, unconventional cell naming conventions, and foreign database schemas that defy their deeply ingrained cognitive habits.
This sudden disruption in workflow induces mental fatigue, as professionals must mentally reconstruct the underlying logic of a financial model built by minds operating under entirely different operational philosophies.
The invisible barrier of unfamiliar formatting breeds skepticism regarding the integrity of the incoming data, leading analysts to second-guess statistical outputs that might otherwise reveal critical market insights. For instance, when Wall Street investment firms merge or absorb regional banking branches, quantitative teams frequently clash over conflicting spreadsheet architectures, resulting in delayed risk assessments and missed hedging opportunities during critical trading windows.
Overcoming this psychological inertia requires intentional cross-departmental training programs and standardized data dictionaries that bridge the conceptual gap between disparate corporate cultures. By transforming chaotic external data formats into universally understood enterprise standards, institutions can alleviate the cognitive burden on their analytical staff, allowing them to focus on high-level market forecasting rather than frustrating administrative troubleshooting.
Raw exportable data for analysis illuminates hidden patterns within every thriving enterprise today. Industry leaders now deploy modern dance studio software to effortlessly capture vital rhythmic metrics and attendance flows. Transforming these vibrant operational insights into precise exportable data for analysis empowers ambitious visionaries to sculpt a brilliant future.
Portable records repositories facilitate cross-departmental collaboration within decentralized biomedical research laboratories studying cellular mutations.

Source: tendata.com
Modern breakthroughs in cellular biology depend heavily on the seamless flow of massive datasets across isolated research nodes, transforming how global teams decode complex genetic mutations. As brilliant minds unite across borders, the physical and digital movement of deep genomic archives empowers scientists to accelerate the discovery of life-saving therapeutics without missing a single beat.
Decentralized laboratories often operate in diverse geographic regions, meaning that unifying disparate information streams requires robust synchronization strategies. When molecular geneticists share terabytes of sequencing data regarding cancerous cell line alterations, every single byte must transition securely between repositories to maintain absolute scientific integrity and collaborative synergy.
Hardware limitations encountered when attempting to migrate multi-gigabyte biological matrices onto portable solid-state drives
Moving multi-gigabyte biological matrices onto portable solid-state drives exposes immediate hardware bottlenecks, particularly thermal throttling and sustained write-speed degradation during massive file transfers. High-density genomic archives generate intense heat dissipation challenges inside compact enclosure designs, frequently forcing controllers to throttle transfer speeds to prevent silicon degradation. Furthermore, high-capacity NAND flash memory relies on limited-write endurance cycles, meaning that continuous mirroring of complex molecular matrices can saturate the internal cache and abruptly halt deep-sea data expeditions across laboratory networks.
The physical realities of high-capacity data shuttling demand a deep understanding of interface bandwidths and thermal management properties to prevent data corruption during transit. The following overview Artikels the primary hardware boundaries encountered by computational biologists in the field:
- Thermal throttling restricts continuous data throughput during prolonged multi-terabyte writes.
- Nand flash cache exhaustion causes sudden drops in sustained writing velocities.
- Controller overheating risks temporary drive unresponsiveness in field environments.
- Connector pin degradation limits the longevity of frequently swapped physical storage units.
Hardware interfaces utilized for biological data migration
Selecting the optimal transmission channel is critical when moving colossal genomic matrices between laboratory servers and mobile hardware repositories. The table below categorizes the prominent interface architectures leveraged by modern research institutions to maximize transfer velocity and structural reliability.
| Interface Category | Peak Transfer Rate | Typical Use Case | Reliability Factor |
|---|---|---|---|
| Universal Serial Bus 3.2 Gen 2×2 | 20 Gigabits per second | Field-level drive backups and mobile node synchronization | Moderate thermal sensitivity |
| Thunderbolt 4 Protocol | 40 Gigabits per second | Direct workstation-to-array genomic mapping | High cable shielding integrity |
| Optical Fiber Transport (SFP+) | 10 to 100 Gigabits per second | Inter-facility backbone data migration | Immune to electromagnetic interference |
| Network-Attached Storage Nodes | 1 to 10 Gigabits per second (Aggregate) | Decentralized multi-user laboratory access | Redundant array protection |
Historical anecdotes concerning the physical transport of magnetic tape reels by courier service during the early days of computational biology
Long before fiber-optic cables spanned continents, the foundational epochs of computational biology relied on human endurance and physical logistics to bridge computational gaps. In the formative decades of genomic sequencing, laboratories often generated datasets too voluminous for early telecommunication networks, necessitating the physical deployment of magnetic tape reels packed securely in padded flight cases. Couriers navigated international transit corridors carrying sequenced genetic codes for early protein folding simulations, treating fragile reels of magnetic media like priceless artifacts.
These analog logistical maneuvers introduced fascinating challenges, ranging from customs inspections accidentally wiping magnetic headers with X-ray scanners to courier delays threatening time-sensitive cellular culture experiments. A vivid mental picture emerges of researchers anxiously tracking commercial flights carrying suitcases filled with open-reel magnetic tapes, where a single lost luggage claim could set back critical oncology research by months. This analog hustle laid the cultural bedrock for modern data management, proving that scientific collaboration has always transcended simple digital boundaries through sheer determination.
Comprehensive workflow required to validate the arithmetic precision of transferred health records before publishing peer-reviewed findings
Ensuring the absolute fidelity of transported biomedical archives requires an uncompromising, multi-tiered validation workflow designed to catch even the most microscopic bit-flip errors. Before any cellular mutation dataset contributes to a peer-reviewed publication, bioinformatics teams must execute rigorous cryptographic checksum verifications, cross-referencing source hashes with destination hashes using advanced algorithms like SHA-256. This mathematical defense mechanism guarantees that every nucleotide sequence analyzed in the final manuscript matches the exact biological reality captured at the sequencer level.
Following primary cryptographic verification, researchers initiate secondary structural validation protocols by running automated parsing scripts that check for schema conformity, missing telemetry vectors, and metadata corruption. These diagnostic scripts interrogate the incoming health records against standardized biomedical ontologies, ensuring that clinical variables and genomic coordinates align without mathematical drift. Any discrepancies detected during this phase trigger an immediate quarantine of the affected matrix segments, requiring a complete re-migration from the master repository to preserve the sanctity of the downstream statistical models.
Once structural integrity is confirmed, biostatisticians perform deep-dive exploratory data analyses, running descriptive statistical benchmarks and distribution tests against historically established baseline models. This step involves generating frequency histograms and variance metrics to verify that the transport process did not introduce systematic bias or truncation errors within high-dimensional phenotypic arrays. If the exploratory metrics deviate beyond acceptable tolerance thresholds, the pipeline halts instantly, initiating a forensic audit of the hardware interfaces and transfer logs utilized during the migration phase.
In the realm of biomedical research, a single undetected bit-flip in a genomic matrix can misdirect years of cellular mutation analysis and invalidate transformative clinical hypotheses.
The final stage of the validation architecture demands independent replication across an isolated computational environment, ensuring that different operating systems and parsing libraries interpret the transferred files identically. Researchers deploy containerized environments—such as Docker instances configured with exact software dependencies—to re-run core analytical pipelines on the newly arrived data repositories. Only after achieving unanimous convergence across both primary and secondary computational nodes do principal investigators authorize the integration of the datasets into manuscripts destined for high-impact scientific journals.
Unbound digital metrics serve as the primary fuel for modern logistical optimization engines operating within multinational shipping conglomerates.: Exportable Data For Analysis

Source: revisit.dev
Global commerce moves at a breathtaking pace, relying heavily on the seamless flow of data across vast oceans and complex continental distribution networks. When supply chain operators harness free-flowing digital metrics, they unlock unprecedented visibility into cargo movements, inventory turns, and predictive maintenance schedules. This constant stream of operational intelligence acts as the vital heartbeat of modern maritime logistics, breathing life and agility into fleets that span the globe.
Behind the scenes, colossal container ships and sprawling port facilities generate petabytes of telemetry every single second, tracking everything from ambient container temperatures to fuel injector pressures. By feeding these uninhibited data streams directly into advanced machine learning algorithms, shipping conglomerates can dynamically reroute vessels in real time to avoid severe weather anomalies and unexpected port congestion. The resulting efficiency gains translate directly into millions of dollars in operational savings and significantly reduced carbon footprints across international shipping lanes.
Structural parameters necessary for converting fragmented warehouse inventories into harmonized transferrable files
Transforming chaotic, siloed warehouse data into a universally readable format requires adherence to strict architectural rules and standardized data schemas. Without a unified structural blueprint, disparate inventory management systems will inevitably fail to communicate, leading to costly stock discrepancies and fulfillment delays.
- Establishing rigid data type definitions for every inventory attribute, ensuring numerical counts, monetary values, and timestamps are universally recognized across all participating database architectures.
- Implementing automated schema validation protocols that actively intercept and reject corrupted or improperly formatted data packets before they enter the primary export pipeline.
- Deploying standardized metadata tagging frameworks that categorize inventory by SKU, volumetric dimensions, and hazardous material classifications without ambiguity.
- Enforcing strict character encoding standards, predominantly UTF-8, to prevent data corruption when warehouse records are transferred between legacy mainframe systems and modern cloud environments.
Bridging the digital divide between legacy warehouse systems and modern analytics engines requires meticulous attention to these foundational parameters. When data fields align perfectly, inventory managers gain a panoramic view of stock levels spanning multiple continents, turning historical friction into a streamlined, automated competitive advantage.
Data integration friction is the silent tax paid by enterprises attempting to bridge legacy software silos with modern analytical frameworks.
Moving unstandardized records across incompatible software ecosystems often results in data loss, schema corruption, and catastrophic synchronization failures. Industry veterans recognize that proprietary file formats act as artificial moats, trapping vital logistical data within closed systems and forcing engineers to build fragile, custom middleware bridges just to maintain basic operational visibility.
Freight dispatchers utilizing portable freight ledgers to forecast fuel consumption anomalies across transatlantic cargo routes
Navigating the unpredictable swells of the Atlantic Ocean demands precision engineering and meticulous resource allocation from every maritime dispatcher on duty. Modern shipping operations rely on self-contained, portable freight ledgers that travel securely with the vessel manifests, allowing shore-based analytics teams to cross-reference historical weather patterns against real-time fuel burn rates. These portable ledgers encapsulate every variable from hull drag coefficients to engine load profiles, presenting a complete operational narrative that travels effortlessly between satellite uplinks and onshore servers.
Consider the transatlantic voyage of a 20,000-TEU container vessel departing from the Port of Rotterdam bound for New York Harbor. By analyzing the portable ledger containing telemetry from dozens of identical sister ships traversing the same corridor during previous winter seasons, dispatchers can accurately predict fuel consumption spikes caused by the Gulf Stream’s aggressive counter-currents. The onboard optimization software immediately adjusts cruising speeds and recommends optimal ballast distributions, saving hundreds of metric tons of heavy fuel oil on a single crossing.
This predictive capability transforms raw historical data into an actionable roadmap for sustainable, cost-effective maritime transit.
Long-term sustainability impacts of storing redundant digital archives across multiple cloud hosting providers
The relentless accumulation of digital information within the global supply chain has triggered a massive expansion of enterprise data centers, sparking critical conversations regarding long-term environmental sustainability. While multinational corporations routinely replicate vital logistical archives across multiple geographically diverse cloud hosting providers to guarantee disaster recovery readiness, this practice carries a substantial ecological toll. Each redundant copy of a massive inventory database or historical shipping manifest requires continuous power for processing units, active memory retention, and aggressive server cooling systems.
As enterprises scale their digital footprints, the cumulative energy consumption of these mirrored repositories contributes significantly to global greenhouse gas emissions.
Examining the real-world operational footprint of major cloud infrastructure providers reveals the sheer scale of this environmental challenge. Hyperscale data centers operated by industry giants consume as much electricity as small municipalities, drawing heavily on local power grids that frequently rely on fossil fuels during peak demand cycles. When a logistics conglomerate maintains triple-redundant backups of ten petabytes of supply chain analytics across North American and European cloud zones, the continuous hardware humming and thermal management systems draw megawatts of power uninterruptedly.
Analysts point to case studies from major shipping hubs where enterprise data retention policies mandate keeping historical shipment records for up to seven compliance years, inadvertently locking corporations into decades of compounding energy expenditures.
Mitigating the environmental degradation associated with sprawling digital archives requires a fundamental shift toward intelligent data lifecycle management and carbon-aware computing strategies. Forward-thinking maritime organizations are increasingly adopting tiered storage models, automatically migrating infrequently accessed historical ledgers from high-performance, energy-intensive solid-state drives down to cold storage archiving solutions powered by renewable energy sources. Furthermore, advancements in data deduplication algorithms allow enterprises to compress redundant file structures by up to sixty percent without sacrificing regulatory compliance or analytical fidelity.
By deliberately balancing the absolute necessity of robust data redundancy against the ecological realities of modern cloud infrastructure, the shipping industry can successfully chart a course toward a genuinely sustainable digital future.
Summary
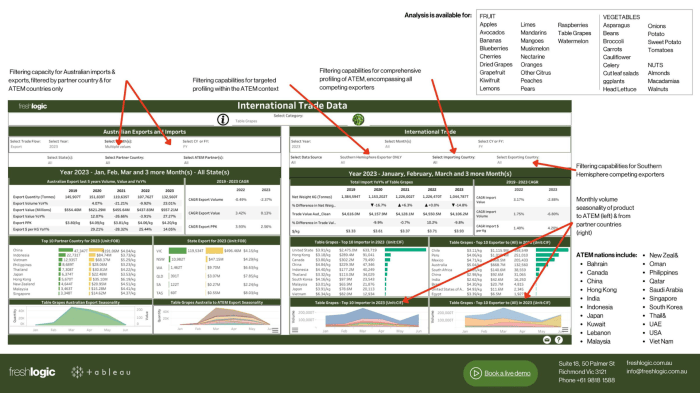
Source: com.au
Ultimately, the seamless migration and preservation of digital intelligence redefine how humanity solves its most intricate logistical and scientific puzzles. As we harness these transportable records to forecast global shifts and streamline operations, we step boldly into an era where absolute precision and shared knowledge light the path forward to enduring success.
