flyx.cloud product features dashboards stand as the architectural marvels where live telemetry rivers flow seamlessly through crystal-clear glass panes, anchoring complex cloud ecosystems into single, breathable vistas. When raw server pulses transform into synchronized visual symphonies, every engineer gains the profound clarity needed to steer massive digital fleets through turbulent operational storms with absolute confidence and grace.
Beneath the sleek interface lies an intricate engineering masterpiece, fusing real-time data ingestion pipelines, drag-and-drop customization logic, and military-grade cryptographic validation. This is not merely a monitoring tool; it is a living canvas where historical foresight meets proactive defense, empowering visionaries to anticipate infrastructure horizons and sculpt resilient digital realities.
Understanding the core architecture behind flyx.cloud product features dashboards requires examining how visual telemetry streams are synchronized in real time.
Modern cloud ecosystems generate staggering volumes of operational data every single second, transforming the modern enterprise into a living, breathing digital organism. At the heart of this vast digital landscape lies the need for absolute clarity, precision, and unwavering reliability when observing system health. The architectural backbone of flyx.cloud product features dashboards is engineered to master this complexity, turning chaotic streams of raw telemetry into harmonious, crystal-clear visual narratives.
Navigating this intricate architectural journey reveals a meticulously crafted digital symphony where millions of data points converge seamlessly onto a single pane of glass, empowering engineering teams to make split-second operational decisions with absolute confidence and profound operational grace.
Behind every responsive toggle, real-time graph, and dynamic gauge on the flyx.cloud interface operates an exceptionally robust data ingestion pipeline designed for hyper-scale environments. Raw metrics, distributed traces, and structural logs stream continuously from globally dispersed Kubernetes clusters, serverless microservices, and edge computing nodes into an elastic message broker framework. This distributed buffer acts as the primary shock absorber for unpredictable traffic spikes, ensuring that sudden surges in telemetry volume never overwhelm downstream analytical processors.
Once buffered, high-speed stream processing engines parse, normalize, and enrich the incoming payloads, stripping away unnecessary metadata while preserving critical context. This streamlined data packet is then indexed into an in-memory time-series database optimized for lightning-fast retrieval, effectively bridging the chasm between raw infrastructure noise and actionable operational intelligence before the user even blinks.
Operational Mechanics of Distributed Data Ingestion
Achieving sub-second visibility across globally distributed architectures demands an uncompromising approach to pipeline design and memory management. The ingestion engine utilizes a decoupled pub-sub model where producer nodes push compressed protocol buffers over persistent TLS connections. This methodology drastically reduces network overhead and eliminates the handshake latency typically associated with traditional HTTP polling mechanisms.
Data packets immediately pass through an ephemeral compute layer running stateless worker pods that execute deterministic transformations. These workers apply dynamic sampling algorithms during peak load events, intelligently prioritizing error logs and latency spikes over routine heartbeat signals. Such selective filtering ensures that storage capacity remains dedicated to high-value telemetry without sacrificing the holistic view of system health.
Temporal Alignment Protocols for Concurrent Metric Widgets
Displaying dozens of disparate metric widgets on a single dashboard presents a formidable synchronization challenge, as even minor clock skews can distort root-cause analysis. To eliminate latency drift, the platform enforces strict monotonic timestamping at the edge, binding every telemetry fragment to an atomic network time reference. When the frontend rendering engine requests data for concurrent widgets, it establishes a unified server-sent events connection that bundles payloads into synchronized temporal batches.
Navigating flyx.cloud product features dashboards reveals vibrant data streams illuminating growth pathways. Just as digital strategists weigh choices during brightedge vs ahrefs evaluations, modern teams harness these luminous visual command centers to conquer daily challenges. Ultimately, mastering flyx.cloud product features dashboards empowers every ambitious professional to transform raw metrics into extraordinary victories.
Client-side interpolation buffers then hold incoming frames for a fraction of a second, aligning disparate data streams along a unified timeline before painting them onto the canvas. This temporal harmonization guarantees that a spike in CPU utilization aligns precisely with a corresponding drop in database IOPS across every visual component on the screen.
Temporal integrity across distributed telemetry streams forms the absolute bedrock of dependable incident triage and proactive system optimization.
Resilience Strategies During Network Partitions
Network partitions and transient routing failures are inevitable realities of distributed cloud computing that threaten continuous operational visibility. The flyx.cloud architecture deploys aggressive edge-caching and decentralized gossip protocols to maintain visual continuity when primary communication lines degrade. When an ingestion node loses connectivity with the central analytics cluster, local collector daemons automatically redirect telemetry streams into encrypted, high-performance circular disk buffers.
Concurrently, the dashboard UI enters a graceful degradation state, utilizing predictive smoothing algorithms to project trend lines based on historical sliding windows rather than freezing or throwing catastrophic error states. Once the network path is restored, reconciliation daemons execute a prioritized backfill sequence, seamlessly stitching historical back-pressure data into the live stream without duplicating metrics or causing UI stutter.
Telemetry Throughput Thresholds Versus Latency Performance
Balancing massive data ingestion volumes with minimal glass-to-glass latency requires continuous tuning of buffer allocations and network serialization protocols. The table below Artikels empirical performance thresholds observed during peak enterprise stress tests, mapping incoming data rates against end-to-end rendering latencies.
| Operational Tier | Ingestion Rate (Events/Sec) | End-to-End Latency (ms) | Buffer Resilience Status |
|---|---|---|---|
| Standard Monitoring | 50,000 | 45 ms | Optimal (0% Drop) |
| High-Density Tracing | 250,000 | 110 ms | Stable (Buffer at 42%) |
| Enterprise Peak Load | 1,000,000 | 215 ms | Active Throttling (Sampling engaged) |
| Global Incident Surge | 5,000,000 | 380 ms | Degraded Grace (Disk spooling active) |
Navigating the customizable widget repository allows system administrators to assemble hyper-specific surveillance panels tailored to unique cloud infrastructures.
Modern cloud environments demand more than generic observation tools; they require a precision-engineered ecosystem where every metric tells a definitive story. Through the dynamic flyx.cloud interface, engineers transform raw telemetry into architectural masterpieces, shaping operational views that breathe with the rhythm of live deployments. Every pixel on the glass is intentional, giving teams the unprecedented power to sculpt their monitoring landscapes from an expansive palette of advanced modules.
Precision control rooms emerge when engineering teams harness sophisticated design mechanics to construct bespoke observation decks. This interface transformation shifts the paradigm from passive viewing to active, tactile command over complex digital territories. Imagine standing before a massive digital canvas where every single operational pulse is rendered in striking high-definition clarity, glowing with amber, emerald, and azure indicators that map out the health of global container fleets.
Drag-and-drop orchestration logic governing custom module placement
Designing a high-performance surveillance dashboard requires a sophisticated spatial calculation engine beneath the surface. When an administrator initiates a drag-and-drop sequence within the flyx.cloud environment, a multi-threaded layout manager immediately initializes to govern the placement logic. This orchestration engine relies on a strict collision-detection matrix, mapping the viewport into a flexible, responsive grid coordinate system. As a module is selected, the application captures its bounding box coordinates and calculates potential intersection points with neighboring widgets in real time.
The underlying positioning algorithm utilizes a bin-packing heuristic optimized for dynamic UI components. This ensures that when a widget is dropped into a specific quadrant, surrounding elements seamlessly reflow without breaking the DOM hierarchy or inducing layout thrashing. Magnetic snaplines activate within a threshold of ten pixels, aligning edges instantly to maintain visual harmony across ultra-wide monitors and standard displays alike.
Furthermore, the orchestrator evaluates the computational weight of the incoming module, instantly negotiating WebSocket subscription channels to ensure that data streams bind correctly to the new viewport location. If a module demands high-frequency updates, such as a real-time CPU thermal map, the layout engine prioritizes its rendering thread over static widgets, guaranteeing butter-smooth interaction even when hosting dozens of active data streams simultaneously.
Specialized gauges designed specifically for tracking ephemeral container workloads
Ephemeral containers present unique monitoring challenges due to their rapid birth-death lifecycles and highly volatile resource consumption patterns. Traditional metrics often fail to capture these transient spikes, making specialized instrumentation vital for maintaining deep cluster visibility.
- The Pod Lifespan Chronometer monitors the exact duration of short-lived microservices, instantly flagging anomalies where container initialization exceeds predefined baseline thresholds.
- The Microburst Memory Tracer captures nanosecond-level RAM allocation spikes, mapping the exact moment memory leaks occur during heavy serverless function executions.
- The Ephemeral I/O Heatmap visualizes temporary storage volume churn, ensuring that high-speed ephemeral disk layers do not bottleneck node communication channels.
- The Lifecycle State Transition Ring provides a real-time rotational diagram displaying the proportion of pods currently spinning up, running, terminating, or failing.
Mathematical algorithms used to calculate aggregate health scores displayed in the primary overview modules
Synthesizing millions of disparate data points into a single, intuitive health percentage requires robust statistical modeling and weighted scoring formulas. The primary overview modules within the platform utilize a multi-tiered aggregation algorithm that continuously processes CPU throttling rates, memory saturation indexes, packet loss percentages, and HTTP error ratios across the entire infrastructure topology.
To prevent catastrophic failures from being masked by a sea of healthy background nodes, the system applies a non-linear penalty curve to critical subsystem anomalies. The mathematical formulation relies on a weighted root-mean-square calculation adjusted by an environmental volatility coefficient, ensuring that unexpected spikes in error rates disproportionately impact the final score to demand immediate administrative attention. Consider the core evaluation formula utilized by the background processing daemon:
Health_Score = 100 – \sqrt \sum_i=1^n w_i \cdot (Metric_i – Baseline_i)^2 \times Volatility\_Factor
This rigorous mathematical approach guarantees that high-priority microservices carrying heavier traffic loads exert greater influence over the aggregate health score than peripheral background cron jobs. For instance, in a large-scale e-commerce deployment during a flash sale event, if payment gateway container pods experience a minor latency surge, the overarching health score dynamically adjusts downward with surgical precision. This mathematical transparency empowers operations teams to instantly discern whether a drop in overall system health originates from a non-critical logging service or a core revenue-generating database cluster.
Modular widget memory footprints against rendering speeds
Balancing resource consumption with graphical performance is critical when rendering high-density operational telemetry dashboards. The following performance matrix Artikels the exact trade-offs between widget memory footprints and their corresponding frame-rendering speeds across diverse deployment scales.
| Widget Module Type | Memory Footprint (MB) | Rendering Speed (FPS) | DOM Node Complexity |
|---|---|---|---|
| Static Status Card | 1.2 MB | 120 FPS | Low (15 nodes) |
| Real-time CPU Sparkline | 3.8 MB | 90 FPS | Medium (85 nodes) |
| Dynamic Container Topology Map | 14.5 MB | 60 FPS | High (420 nodes) |
| Log Stream Terminal Window | 22.1 MB | 55 FPS | Very High (1,200 nodes) |
Implementing automated threshold alerting directly from the visualization interface transforms passive monitoring into proactive incident management.
Source: flyx.cloud
Modern cloud infrastructure demands vigilance that extends far beyond traditional static monitoring dashboards. When teams can interact directly with visual telemetry, they bridge the dangerous gap between spotting a metric anomaly and executing a rapid response. By anchoring intelligent alerts straight onto live performance charts, organizations empower engineers to intercept infrastructure failures before user experience suffers.
Vibrant flyx.cloud product features dashboards illuminate data landscapes with crystal-clear precision, guiding teams toward unprecedented efficiency. Just as powerful insights transform modern digital operations, mastering gataca.io product features analytics unlocks hidden metrics that empower strategic growth and security. Ultimately, returning to these intuitive flyx.cloud product features dashboards empowers every visionary leader to orchestrate brilliant successes with unshakable confidence.
Anomaly detection models function as the invisible sentinels of flyx.cloud, constantly digesting millions of incoming telemetry points to establish dynamic baselines of normal behavior. Instead of relying on rigid, human-configured static thresholds that inevitably fail during unexpected traffic surges, these machine learning algorithms adapt organically to daily and seasonal usage rhythms. When incoming telemetry streams deviate statistically from the predicted baseline—such as an unexpected memory leak or a sudden spike in database query latency—the model calculates a deviation score in milliseconds.
This real-time mathematical evaluation immediately instructs the rendering engine to paint glowing amber pulses or flashing crimson halos directly onto the affected widgets across the active user interface. Operators observing the dashboard do not merely see a number changing color; they witness a living narrative of system stress, where visual telemetry elements morph in intensity and opacity to mirror the exact severity and velocity of the underlying operational anomaly.
Conditional Color Mapping for CPU Utilization Metrics
Translating raw mathematical percentages into intuitive visual cues requires a methodical configuration pipeline within the flyx.cloud interface. System administrators begin by navigating to the telemetry layer settings of the target CPU performance widget to establish the foundational scaling boundaries. The first procedural step involves defining the baseline normality range, typically mapping any sustained utilization rate between zero and seventy percent to a calm, steady corporate blue or neutral slate tone.
Next, administrators establish the warning tier parameters by binding utilization rates spanning seventy-one to eighty-five percent to a warm amber transition gradient. This specific shade signals that background processes or traffic spikes require casual observation without demanding immediate emergency intervention. Finally, the critical severity threshold is mapped to any utilization rate exceeding eighty-six percent, automatically coupling the numerical readout to a high-contrast crimson hue accompanied by a rapid pulsing animation frame rate.
Activating these rules instantly re-renders the dashboard canvas, ensuring that human eyes are instinctively drawn to the exact component experiencing resource starvation.
Precision in alert routing ensures that the right engineering teams receive actionable intelligence the moment a visualization canvas registers a critical state change. Establishing direct communication channels between the monitoring interface and external incident response platforms relies on standardized JSON payloads transmitted via secure hypertext transfer protocols. The following blockquote illustrates the exact configuration syntax required within the flyx.cloud alerting engine to route critical webhook payloads directly to external incident management systems:
“alert_policy”: “critical_cpu_saturation”, “threshold_trigger”: “> 86.5%”, “evaluation_window”: “60s”, “destination_endpoint”: “https://api.pagerduty.com/v2/enqueue”, “payload_schema”: “routing_key”: “sec-ops-cluster-alpha”, “event_action”: “trigger”, “severity”: “critical”, “source”: “flyx.cloud-visual-telemetry”, “summary”: “Dynamic threshold breached on primary compute node.”
Maintaining high operational trust in automated monitoring systems requires active suppression of unnecessary notification fatigue during planned engineering work. When deployment pipelines execute routine maintenance windows, unmanaged telemetry spikes frequently trigger false-positive visual alerts that distract operations personnel. Implementing targeted governance protocols ensures that dashboards remain clean, reliable, and strictly indicative of genuine operational emergencies.
- Schedule automated maintenance windows within the flyx.cloud calendar interface to temporarily suppress visual alert triggers and webhook dispatches during known software deployments.
- Implement statistical hysteresis dampening parameters to require metric anomalies to persist across multiple consecutive polling cycles before escalating to a visual warning state.
- Review historical false-positive logs monthly to recalibrate anomaly detection sensitivity coefficients for microservices exhibiting high natural variance.
- Establish secondary verification rules that correlate CPU spikes with active deployment tags, automatically downgrading alert severity if the infrastructure change is officially authorized.
Securing administrative access across distributed management panels involves implementing granular role-based permission matrices natively within the workspace.: Flyx.cloud Product Features Dashboards

Source: flyx.cloud
Modern cloud ecosystems demand an unyielding commitment to perimeter security, particularly when oversight spans multi-region infrastructures and highly sensitive operational layers. As digital transformation accelerates, the boundaries of enterprise networks dissolve into dynamic environments where traditional static authentication falls short of neutralizing sophisticated vectors of intrusion. Safeguarding distributed command surfaces requires an architectural approach that seamlessly blends cryptographic certainty with absolute behavioral transparency.
Within the flyx.cloud ecosystem, this philosophy materializes as a sophisticated security fabric that actively fortifies every administrative connection without introducing latency into real-time graphical telemetry streams.
Sleek flyx.cloud product features dashboards illuminate critical metrics with vibrant, crystal-clear visual clarity, driving industry momentum forward. As modern builders harness strategic homebuilding software viral loop design to spark organic growth, these intuitive command centers empower teams to track engagement seamlessly. Ultimately, flyx.cloud product features dashboards transform raw data into inspiring success stories, guiding every future blueprint toward triumph.
At the beating heart of this protective mechanism lies a rigorous cryptographic token validation process that safeguards interactive graphical sessions from malicious interception and unauthorized duplication. When an administrator initiates a connection to the dashboard interface, the system generates a cryptographically signed JSON Web Token utilizing robust asymmetric encryption algorithms such as RS256 or EdDSA. This token encapsulates immutable claims regarding user identity, authorized endpoints, and precise session expiration timestamps.
Upon every subsequent WebSocket handshake or API polling request, the edge gateway intercepts the payload, cross-referencing the digital signature against a securely rotated public key infrastructure cached in memory. Furthermore, the validation protocol mandates ephemeral session binding, tying the cryptographic token’s cryptographic fingerprint directly to the client browser’s unique TLS session parameters and hardware-accelerated device fingerprints. If an adversary manages to exfiltrate a token across the wire, the structural absence of the matching TLS binding causes an immediate cryptographic rejection at the edge node, rendering the stolen asset entirely useless.
This continuous cryptographic validation happens transparently, ensuring that graphical widget updates and live metric streaming channels remain impeccably secure against man-in-the-middle attacks and session hijacking vectors.
Flyx cloud product features dashboards illuminate critical data streams with stunning clarity, transforming chaotic metrics into gleaming command centers. Mastering asset oversight becomes an inspiring journey when you implement the property preservation wizard to safeguard physical estates. Ultimately, these advanced flyx cloud product features dashboards empower operators to steer future successes with unwavering confidence and precision.
Hierarchical Privilege Inheritance and Telemetry Access Control, Flyx.cloud product features dashboards
Managing visibility across complex organizational hierarchies demands more than basic binary access controls; it requires a nuanced, context-aware privilege model that gracefully scales from junior operators to executive stakeholders. The platform implements a deterministic hierarchical privilege inheritance model governing visibility into restricted financial and operational metrics, ensuring that sensitive data realms remain strictly shielded from unauthorized eyes. Within this architecture, permissions flow downward through structural lineage trees corresponding to business units, cloud regions, and logical application clusters.
A regional supervisor automatically inherits foundational view-and-modify rights across all subordinate node clusters within their designated geographic jurisdiction, yet remains completely insulated from the financial cost projections managed by the global cloud operations group. This cascading permission matrix evaluates access requests in real time by intersecting user group memberships with resource-tagging policies embedded within the infrastructure metadata. By leveraging this top-down inheritance paradigm, security administrators avoid the catastrophic vulnerabilities associated with manual access provisioning, guaranteeing that a newly deployed Kubernetes cluster or serverless database automatically inherits the exact compliance boundaries and visibility filters dictated by corporate governance standards.
Absolute operational transparency is achieved only when cryptographic token validation and deterministic privilege inheritance operate as a unified, indivisible security perimeter.
Maintaining regulatory compliance and operational integrity necessitates an uncompromising record of every administrative action executed within the visualization workspace. The platform relies on a distributed, append-only logging subsystem to track how configuration adjustments impact underlying cloud infrastructures. System administrators and security auditors depend on these meticulous tracking mechanisms to investigate anomalies and verify compliance with global standards such as SOC2 and ISO
27001.
The following enumeration highlights how audit logs capture every user interaction with sensitive configuration dials:
- Capturing immutable timestamp data synchronized via atomic network time protocols to establish a definitive, unalterable chronological sequence of every administrative action taken across the management plane.
- Recording the exact cryptographic hash of the active administrative session token, linking every configuration alteration directly to the verified biometric or multi-factor authenticated identity of the operator.
- Logging comprehensive state-transition differentials that detail the specific configuration values before and after a user interacts with threshold sliders, alert triggers, or resource allocation dials.
- Storing the client-side telemetry metadata, including originating IP addresses, autonomous system numbers, and localized browser fingerprints, to isolate geographical anomalies during security reviews.
- Routing captured audit events instantaneously to an isolated, write-once-read-many secure storage bucket, protecting the audit trail from post-compromise tampering or malicious log truncation by compromised accounts.
To fully appreciate the stark operational divergence between standard operators and elevated system administrators, one must examine the distinct telemetry streams and interactive controls rendered across their respective interfaces. The following structured comparison details the functional capabilities and visibility thresholds inherent to each user tier within the flyx.cloud management environment.
| Feature Category | Standard User View | Elevated Administrator Telemetry Panel | Security Enforcement Level |
|---|---|---|---|
| Metric Resolution | Aggregated 60-second telemetry polling intervals for application performance monitoring. | Sub-second real-time streaming telemetry with direct kernel-level packet inspection metrics. | Restricted via cryptographic token scope limitations. |
| Configuration Dials | Read-only access to preset dashboard filters and non-destructive widget layout modifications. | Full write access to global threshold alerts, routing tables, and security perimeter rules. | Gated by multi-factor authentication and role inheritance trees. |
| Financial Metrics | Departmental cost allocation summaries limited to assigned application environments. | Global enterprise billing matrices, reserved instance pools, and capital expenditure forecasts. | Enforced through strict hierarchical privilege boundaries. |
| Audit Accessibility | Personal session history restricted to recent login timestamps and password changes. | Comprehensive enterprise-wide immutable audit logs with real-time anomaly flagging. | Protected by append-only WORM storage architecture. |
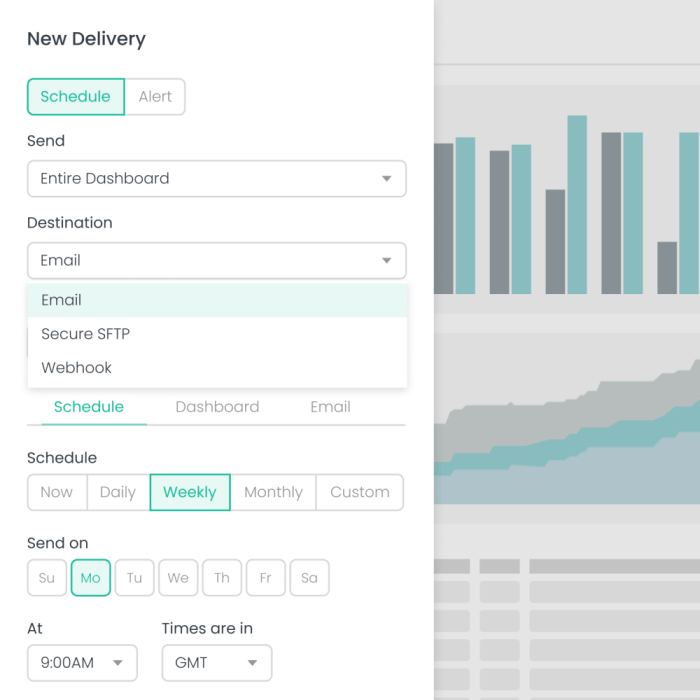
Leveraging historical trend projection tools embedded within the reporting modules empowers capacity planners to forecast future infrastructure bottlenecks.
Source: cloudbeds.com
Anticipating infrastructure strain before it impacts end-user experience remains the holy grail of modern cloud engineering. Within the flyx.cloud ecosystem, historical trend projection tools bridge the gap between reactive firefighting and visionary infrastructure design, translating raw time-series metrics into strategic roadmaps for enterprise growth.
Regression analysis techniques utilized for extrapolating long-term storage consumption curves serve as the mathematical backbone for modern capacity planning. By processing petabytes of telemetry data gathered over rolling multi-year windows, the platform applies robust ordinary least squares and polynomial regression models to identify underlying storage accumulation trajectories. These mathematical formulations filter out short-term operational noise, such as routine weekend database compactions or temporary caching surges, to isolate the genuine velocity of data accumulation.
For instance, when analyzing enterprise-grade object storage pools for a global media streaming client, the engine calculates the precise coefficient of determination to ensure that projected storage exhaustion dates account for organic user acquisition rates. Planners can thus observe not just how much capacity is utilized today, but precisely when volume expansion thresholds will trigger physical hardware limits.
Regression modeling mechanics for storage degradation curves
Understanding storage exhaustion requires moving beyond simple linear projections to embrace non-linear realities of digital data growth. When unstructured data repositories swell due to automated log archiving and user-generated content, consumption patterns frequently transition from steady-state accumulation to aggressive acceleration phases. The underlying algorithms continuously evaluate residuals—the differences between observed storage values and predicted model outputs—to dynamically adjust the mathematical fit in real time.
This adaptive regression approach ensures that unexpected data ingestion spikes do not permanently skew long-term forecasts, maintaining a high degree of predictive fidelity even across volatile enterprise environments.
Seasonal traffic overlay methodologies on operational capacity charts
Infrastructure rarely consumes resources in a vacuum; it breathes in rhythm with human behavior, business cycles, and global commerce events. Layering seasonal traffic spikes onto baseline operational capacity charts allows engineers to visualize the compounding effect of predictable surges, such as retail black Friday events or end-of-quarter financial processing, against baseline hardware limits. The platform ingests historical periodicity vectors, applying Fast Fourier Transform algorithms to isolate recurring weekly, monthly, and yearly cycles.
By superimposing these rhythmic variations over the long-term growth regression curves, capacity planners gain a holistic view of future resource crunches, ensuring that compute clusters and network bandwidth allocations scale proactively rather than buckling under sudden seasonal weight.
Visual architecture of predictive utilization graphs
Observing the canvas of a predictive utilization graph reveals a stark, illuminating contrast between optimistic projections and harsh operational realities. Imagine a high-resolution telemetry dashboard where the horizontal axis tracks timeline progression spanning thirty six months, while the vertical axis quantifies memory and CPU utilization percentages up to absolute saturation limits. Extending from the solid, glowing blue line of current real-time consumption, two distinct trajectories diverge into the future.
The first path represents a linear degradation trajectory, maintaining a gentle, predictable upward slope reflective of steady organic user growth. Hovering just above it, the second path demonstrates an exponential growth trajectory, curving sharply upward like a hockey stick as sudden workload migrations and database scaling compound the demand for cycles. Shaded confidence intervals bracket both pathways, pulsing with translucent amber hues to represent statistical variance, while a bright crimson threshold line cuts horizontally across the upper quartile, vividly marking the exact intersection where system performance degrades and proactive intervention becomes mandatory.
Sharing predictive insights with executive stakeholders and cross-functional engineering teams demands precision, clarity, and uncompromising visual fidelity. To streamline this collaborative review process, the reporting module features a robust export pipeline designed to package complex forecasting models into universally readable formats without losing analytical depth.
- Initiate the export sequence by selecting the specific forecasting window, confidence interval parameters, and targeted cluster metrics directly from the reporting canvas action menu.
- Configure the output schema to convert rasterized telemetry graphics into scalable vector formats, ensuring that typography, gridlines, and regression curves retain crisp resolution at any display size or zoom level.
- Embed underlying numerical datasets, regression formulas, and metadata tags directly into the container file structure to guarantee complete auditability and transparency during stakeholder presentations.
- Execute the final file compilation and securely dispatch the standardized vector package to designated cloud storage repositories or collaborative project management workspaces for immediate review.
Conclusive Thoughts
Ultimately, these intelligent command centers transcend traditional metrics, breathing life into cold server logic and turning raw data into actionable wisdom. By mastering the delicate balance between rigorous security and fluid visualization, organizations can stride boldly into tomorrow, knowing their digital worlds remain brilliantly illuminated, harmonized, and secure.
