hook.co capabilities dashboards stand at the very epicenter of modern digital architecture, transforming raw, chaotic data streams into breathtaking vistas of absolute clarity and precision. In an era where every single millisecond dictates the difference between triumph and operational turbulence, understanding these advanced interfaces is no longer optional; it is the ultimate catalyst for extraordinary achievement.
Behind every sleek glass panel and vibrant telemetry pulse lies a sophisticated engineering marvel designed to empower visionaries and operators alike. By weaving together lightning-fast server protocols, intuitive visual hierarchies, and seamless collaborative workflows, this platform redefines how growing enterprises monitor, interpret, and conquer complex technological challenges on a daily basis.
Exploring the underlying architecture behind hook.co capabilities dashboards

Source: v-cdn.net
Beneath the sleek, responsive glass of the hook.co capabilities dashboards lies an uncompromising digital engine designed to translate massive telemetry into immediate operational clarity. Modern engineering demands more than mere data visualization; it requires a living, breathing pipeline that bridges raw telemetry and human decision-making without hesitation. Every pixel rendered on the screen is the final destination of a meticulously engineered journey that begins deep within distributed cloud environments and terminates at the browser viewport.
Data streams flow directly into the interface through a continuous, unyielding torrent of event-driven architecture, transforming raw telemetry into actionable intelligence the moment it occurs. Imagine a global nerve system where billions of discrete metric points—ranging from API response times to memory utilization spikes—are captured at the edge by lightweight daemon collectors deployed across worldwide availability zones. These collectors serialize the incoming payloads into compact Apache Avro schemas, drastically reducing the payload size before it ever hits the transport layer.
Once formatted, the data enters a distributed message broker cluster powered by Apache Kafka partitions, ensuring that ingestion scales horizontally without a single point of failure. Consumer microservices, written in Go for maximum memory safety and execution speed, consume these topics in real-time, executing preliminary aggregations and anomaly detection algorithms on the fly. The processed data is then pushed directly to edge worker nodes via persistent persistent WebSocket connections and Server-Sent Events (SSE), bypassing the traditional HTTP request-response bottleneck entirely.
This establishes a direct, full-duplex communication highway between the backend processing core and the client-side application. Inside the browser, a custom virtual DOM diffing engine receives these binary-encoded chunks, translating them into fluid UI updates at a crisp sixty frames per second. Users do not wait for the dashboard to refresh; instead, the interface simply breathes in the incoming stream, dynamically shifting charts, counters, and status indicators as the digital universe evolves around them.
Hook.co capabilities dashboards illuminate brilliant paths toward operational clarity, transforming raw metrics into vivid stories of growth. By integrating robust 3pl warehouse management software , teams unlock unprecedented momentum, navigating complex logistics with absolute precision. Ultimately, these dynamic hook.co capabilities dashboards empower leaders to witness their grand vision materialize into daily triumphs.
Server-Side Communication Protocols for Ultra-Low Latency
Maintaining microsecond-level responsiveness requires discarding legacy request-response paradigms in favor of stateful, high-throughput transmission layers. The platform relies on a hybrid protocol stack tailored for deterministic packet delivery and minimal serialization overhead across distributed networks.
- HTTP/3 over QUIC is utilized for all initial client handshakes and heavy static asset delivery, eliminating TCP head-of-line blocking and ensuring resilient connections even across unstable last-mile networks.
- gRPC powered by Protocol Buffers manages internal microservice communication, replacing bulky JSON payloads with compressed binary serialization that accelerates inter-node data transfer by up to eight times.
- Custom binary WebSocket sub-protocols are deployed exclusively for the final telemetry delivery mile, stripping away HTTP header bloat and sustaining continuous, bi-directional data flow with zero handshake repetition.
Backend Hardware Specifications
The raw computational muscle driving the real-time aggregation and streaming pipelines requires enterprise-grade hardware engineered for extreme throughput, massive parallel processing, and absolute fault tolerance.
| Component Tier | Hardware Specification | Operational Role | Throughput Capacity |
|---|---|---|---|
| Edge Ingestion Nodes | Dual AMD EPYC 9654 96-Core Processors, 768GB ECC DDR5 RAM | Terminating incoming telemetry streams and initial protocol translation | 1.2 million events per second per node |
| Stream Processing Cluster | NVIDIA Grace Hopper Superchip, 96 ARM Neoverse V2 Cores | Executing real-time stream analytics and machine learning anomaly detection | 850 GB/s aggregate memory bandwidth |
| In-Memory Cache Layer | Intel Xeon Platinum 8480+, 4TB NVMe-backed RAM | Maintaining hot state tables and reducing database read pressure | Sub-millisecond read/write latency |
Multi-Tier Caching Strategies for Peak Operational Hours
Traffic spikes during critical business hours can easily cripple traditional databases, but the hook.co architecture neutralizes interface lag through an aggressive, multi-layered caching hierarchy designed to absorb sudden surges without dropping a single frame. When millions of concurrent operators flood the platform simultaneously, the system prevents database exhaustion by intercepting queries at the absolute edge of the network before they can propagate inward.
Static assets and semi-static configuration metadata are aggressively cached within globally distributed Content Delivery Network nodes, ensuring that the initial dashboard shell renders instantly regardless of geographic origin. For dynamic dashboard state, a distributed in-memory data grid coordinates synchronized read-through and write-behind policies across regional clusters. This guarantees that aggregated historical trends and pre-calculated metric rollups are served directly from RAM within sub-millisecond windows.
Furthermore, client-side IndexedDB acts as a localized buffer, intelligently storing recent state snapshots so that if a temporary network partition occurs, the interface seamlessly interpolates missing data points without freezing or throwing fatal exceptions. Predictive cache warming algorithms analyze historical usage patterns prior to known high-traffic events, proactively populating memory nodes with the exact datasets users are most likely to query.
Just as global financial markets manage millions of concurrent transactions during opening bells by leveraging distributed memory grids, this architecture ensures that peak utilization feels just as fluid as quiet operational hours.
Real-time visibility is not merely about displaying data as it happens; it is about engineering an unbroken chain of custody for every single byte from the server core to the human eye.
Navigating the intricate visual hierarchy of hook.co capabilities dashboards
Stepping into the command center of modern data ecosystems feels much like standing at the helm of a sophisticated spacecraft, where every glowing indicator demands swift interpretation. Within the hook.co capabilities dashboards, clarity is not merely an aesthetic preference; it is the vital bridge between raw telemetry and decisive action. Operators must translate cascading streams of information into meaningful strategies without falling victim to cognitive overload.
Every pixel on the screen serves a deliberate purpose, constructing a carefully measured landscape designed to anchor human attention precisely where it matters most during critical operational moments.
Mastering this digital terrain requires an appreciation of spatial geometry and chromatic intelligence working in seamless harmony. When critical metrics pulse softly against darkened glass panels, the interface communicates urgency and stability simultaneously. Designers have meticulously mapped human visual psychology, ensuring that peripheral vision catches subtle shifts in performance indicators while focused gaze dissects deep analytical trends. This architecture turns complex analytics into an intuitive extension of the operator’s daily routine, transforming intimidating data tables into clear narratives of system health.
Typography dynamics within high-density data environments
Typography serves as the invisible scaffolding that supports massive influxes of operational intelligence, guiding the human eye across dense clusters of metrics with effortless precision. When thousands of rapid data points populate a single screen, traditional text layouts inevitably collapse into chaotic noise. The hook.co interface leverages a sophisticated typographic hierarchy, pairing proportional sans-serif typefaces with strict weight variations to establish immediate order.
Header elements command primary attention through bold geometric presence, while mid-level indicators utilize medium weights to signify stable operational status. Monospaced numerals are systematically deployed within numeric arrays, aligning decimal points vertically to accelerate scanning speeds across fast-moving financial and telemetry feeds. This deliberate alignment prevents visual fatigue during extended monitoring sessions, allowing analysts to parse fluctuating values without second-guessing their baseline orientation.
Descending scale steps—ranging from prominent twenty-four-point primary metrics down to eleven-point metadata tags—create natural visual resting places, preventing cognitive exhaustion. The interplay between character tracking and line height ensures that dense alphanumeric blocks remain completely legible even when scaled down for multi-monitor command rooms. By treating every character as a directional signpost, the typography actively curates the operator’s visual journey, silencing unimportant background chatter and amplifying critical insights the exact moment they materialize on the display.
Beyond basic legibility, font weight adjustments act as real-time indicators of systemic volatility, shifting dynamically when thresholds are breached. Operators learn to read these subtle shifts unconsciously, freeing up mental bandwidth for complex problem-solving rather than struggling to decipher distorted text. The underlying design philosophy respects the limitations of human perception, acknowledging that clarity under pressure relies heavily on disciplined typographic restraint.
Workflow customization methodologies for modular widgets
Customizing the spatial arrangement of dashboard components empowers professionals to tailor their digital workspace directly to individual operational rhythms and habitual workflows. Recognizing that a DevOps engineer requires a radically different visual footprint than a financial controller, the platform supports highly responsive, drag-and-drop module configurations. Operators can establish personalized priority zones, anchoring high-frequency monitoring widgets within their primary field of view while relegating peripheral logs to collapsible side drawers.
Effective personalization follows specific strategic guidelines to maintain overall system performance and reduce visual friction during high-stress scenarios.
- Pin mission-critical throughput graphs to the upper-left quadrant, aligning with natural Western reading patterns to ensure immediate visual capture upon session initialization.
- Group functionally related telemetry feeds, such as memory utilization and latency spikes, into adjacent container blocks to facilitate rapid cross-referencing during incident triage.
- Minimize non-essential decorative elements and secondary tickers within primary workspaces, relocating them to secondary tabs to preserve maximum screen real estate for core operational data.
- Save customized layout profiles based on specific operational scenarios, enabling seamless transitions between routine monitoring modes and emergency incident response views with a single keystroke.
Adapting the interface layout to match personal cognitive habits significantly slashes the time required to locate vital information during rapidly evolving situations. As professionals interact with their customized environments, the workspace evolves into a natural extension of their analytical process, minimizing physical mouse movement and maximizing mental focus.
Hook.co capabilities dashboards illuminate complex data landscapes with brilliant clarity, transforming raw metrics into compelling operational narratives. Modern facilities are elevating their safety protocols by deploying intuitive jail management software , ensuring every critical inmate detail is tracked seamlessly. Ultimately, these advanced hook.co capabilities dashboards empower visionary leaders to drive unprecedented institutional excellence and inspire enduring community trust.
Visual contrast modes and accessibility comparisons
Visual accessibility remains a foundational pillar of modern interface design, ensuring that every operator, regardless of visual acuity, can interpret dense data streams accurately under varying ambient lighting conditions. The transition between standard themes and high-contrast modes involves meticulous calibration of luminescence ratios and chromatic harmonies. The following structural breakdown contrasts the default operational theme with specialized high-contrast accessibility modes to highlight how visual parameters adapt to diverse user needs.
| Interface Attribute | Default Operational Theme | High-Contrast Accessibility Mode | Monochrome Precision Mode |
|---|---|---|---|
| Background Luminance | Deep Slate Charcoal (#121619) | Absolute Pitch Black (#000000) | Neutral Industrial Gray (#2A2A2A) |
| Primary Text Contrast Ratio | 10.5:1 (WCAG AAA Compliant) | 18.2:1 (Maximum Legibility) | 14.1:1 (Optimized Grayscale) |
| Critical Alert Indication | Dynamic Amber/Red Gradient Glow | Solid High-Visibility Yellow-Orange | Pulsing High-Contrast Border Artikel |
| Target Audience Environment | Standard Control Room Lighting | Low-Light or Vision-Impaired Operators | Bright Sunlight or Monochrome Displays |
Optimizing these contrast profiles guarantees that critical warnings never blend into the background, regardless of whether an operator is monitoring systems in a darkened control bunker or a brightly lit corporate office. Every color choice undergoes rigorous testing against international accessibility standards to eliminate ambiguity during high-pressure decision-making cycles.
Layout architecture for secondary metric tickers
Deploying secondary metric tickers without overwhelming the primary display area requires a disciplined approach to spatial partitioning and motion design. Secondary metrics—such as historical baseline averages, minor error counts, and auxiliary system status updates—provide essential context without demanding constant focal attention. To prevent these supplementary data streams from creating visual clutter, designers implement compartmentalized ticker channels that utilize controlled, non-distracting animation speeds.
The truest test of dashboard architecture is its ability to remain profoundly quiet until absolute relevance demands a voice.
This philosophy governs how secondary metrics inhabit the periphery of the screen, resting quietly until a predefined threshold triggers a subtle, elegant highlight. By embedding tickers within sleek, low-profile status bars situated at the absolute bottom or rightmost edge of the viewport, the interface respects the central workspace’s dominance. Operators absorb background system health through gentle ambient motion, relying on peripheral awareness rather than active visual tracking.
This methodical separation ensures that auxiliary information remains readily available for periodic audits while leaving the central stage entirely unobstructed for primary analytical tasks.
Harnessing telemetry streams within hook.co capabilities dashboards
The relentless pulse of modern digital infrastructure generates rivers of raw data that require immediate, intelligent decoding. Within hook.co capabilities dashboards, harnessing these expansive telemetry streams transforms chaotic metric noise into crystalline operational clarity, empowering engineering teams to command complex cloud environments with absolute precision and profound situational awareness.
Navigating vibrant hook.co capabilities dashboards reveals brilliant data constellations illuminating modern enterprise pathways. Observers frequently investigate inquiries such as does pulsifi.me have a blog while researching digital growth strategies across diverse corporate landscapes. Ultimately, mastering these advanced hook.co capabilities dashboards empowers visionary leaders to transform raw analytics into extraordinary achievements.
Every millisecond, millions of data points flow seamlessly into the core analytics engine, painting a living portrait of system health and performance dynamics. By converting raw numbers into vibrant, contextualized visual feeds, the dashboard empowers operators to intercept micro-failures before they cascade into catastrophic outages, bridging the gap between raw data collection and proactive digital governance.
Automated anomaly detection algorithms triggering visual alerts
Modern architectures operate at a velocity that completely surpasses human cognitive capacity for manual log monitoring, necessitating advanced computational sentinels. Hook.co capabilities dashboards deploy sophisticated, self-learning anomaly detection algorithms that ingest continuous streams of system metrics, establishing dynamic baselines that adapt organically to fluctuating traffic patterns and workload cycles. These machine learning models constantly evaluate incoming telemetry against historical norms, identifying subtle deviations in CPU spikes, memory leakage, and network latency that standard static thresholds consistently fail to catch.
When a statistical variance breaches calculated confidence intervals, the system bypasses traditional delayed notification queues to instantly flash high-priority visual alerts across the glass, drawing the operator’s immediate focus to the exact epicenter of degradation.
To visualize this mechanism, imagine a primary monitoring screen bathed in a calming, ambient turquoise glow that represents nominal, healthy operations across a global microservices mesh. Suddenly, a localized cluster of nodes begins exhibiting erratic memory consumption, causing the algorithmic sentinel to instantly recalculate local entropy values. Within milliseconds, the serene turquoise interface dynamically shifts to an urgent amber pulse directly over the failing zone, while expanding concentric red rings ripple outward from the specific service node in the topology map.
This deliberate visual choreography ensures that engineers do not have to hunt for trouble; rather, the trouble illuminates itself, commanding attention through a sophisticated interplay of chromatic intensity, motion design, and precise geospatial dashboard placement that communicates severity without requiring a single line of text to be read.
Historical telemetry logging assisting in predictive infrastructure scaling
Looking backward into archived operational data serves as the ultimate compass for navigating future capacity demands with absolute confidence and financial prudence. Hook.co capabilities dashboards archive massive volumes of historical telemetry, feeding structured time-series data into forecasting models that accurately predict upcoming traffic surges based on seasonal trends, marketing campaigns, and historical user behavior. For instance, global e-commerce platforms leveraging these dashboards successfully anticipate Black Friday traffic spikes by analyzing the precise resource consumption curves from the previous year, allowing the automated orchestration layer to provision thousands of secondary container instances hours before the actual surge hits.
This eliminates reactive scrambling, reduces over-provisioning waste, and ensures that user experience remains buttery smooth under unprecedented load.
Predictive scaling transforms reactive firefighting into strategic infrastructure choreography, ensuring compute capacity meets demand precisely when the world begins to knock.
When analyzing these predictive workflows, system architects rely on structured comparative datasets to evaluate algorithmic efficiency against manual capacity planning methods. The following matrix illustrates the performance metrics governing resource allocation strategies across high-traffic enterprise deployments.
| Scaling Approach | Response Latency | Resource Waste Margin | Predictive Accuracy |
|---|---|---|---|
| Manual Threshold Adjustment | 15 to 45 minutes | 38 percent | Low (Reactive) |
| Standard Metric Autoscaling | 3 to 5 minutes | 19 percent | Moderate |
| Hook.co Telemetry Predictive Engine | Sub-second (Pre-allocated) | 4 percent | High (Proactive) |
Threshold configuration procedures for server load metrics
Establishing accurate boundaries for server performance metrics requires a meticulous balance between aggressive alerting and alert fatigue mitigation. Operators must configure these parameters carefully to ensure the platform remains sensitive to genuine threats while ignoring benign, temporary fluctuations in resource consumption.
The configuration workflow involves several vital technical phases to optimize dashboard responsiveness and maintain high signal-to-noise ratios:
- Establish baseline performance metrics over a mandatory fourteen-day observation window to capture normal weekly operational cycles and background cron job executions.
- Define tiered warning thresholds at seventy-five percent utilization for CPU and memory, triggering gentle yellow visual indicators without waking on-call personnel.
- Set critical failure thresholds at ninety percent utilization sustained over three consecutive polling intervals, immediately initiating high-severity dashboard pulsing and automated pager integrations.
- Incorporate hysteresis parameters to prevent alert flapping, ensuring that metrics must drop significantly below the trigger boundary before the visual alert state clears itself.
Descriptive narrative illustrating a midnight system recovery tracked via real-time graphical pulses, Hook.co capabilities dashboards
The digital clock on the operations center wall glows a silent 03:42 AM when the ambient tranquility of the monitoring floor is abruptly shattered by a synchronized cascade of visual shifts on the hook.co capabilities dashboards. Across the massive curved command displays, a cluster of core database nodes suddenly bleeds from a calm, steady green into a frantic, pulsating crimson, signaling an unexpected thread pool exhaustion that threatens to lock the entire payment gateway.
In the center of the dark room, the real-time graphical pulse chart transforms into a jagged, erratic heartbeat, tracing the rapid ascent of memory consumption toward the absolute brink of total system failure. The automated anomaly detection engine instantly highlights the failing microservice with an oscillating golden halo, drawing the bleary-eyed engineer’s gaze directly to the problematic process ID without forcing them to manually parse endless scrolling log files in the dark.
With practiced precision, the engineer initiates an automated rolling restart sequence directly through the dashboard interface, watching as the telemetry streams respond almost instantaneously to the intervention. On the glass surface, the violent red pulses begin to soften, transitioning back through a cautious amber hue as thread counts stabilize and incoming requests find newly provisioned compute corridors. The graphical load waves, which moments ago resembled a violent mountain range of distress, gently flatten into smooth, predictable sine curves, mirroring the restored equilibrium of the underlying server architecture.
As the final node reports a healthy status, the entire interface settles back into its familiar, soothing turquoise cadence, leaving behind only a comprehensive telemetry audit trail that captures every microsecond of the midnight skirmish for post-incident review.
Integrating third-party developer tools into hook.co capabilities dashboards
Modern engineering workflows thrive on synergy, demanding seamless bridges between isolated software ecosystems and centralized monitoring centers. As teams scale their operational footprints, bringing external developer tools directly into the hook.co capabilities dashboards transforms static observation posts into dynamic command centers where every metric tells a cohesive story.
Hook.co capabilities dashboards illuminate strategic paths with sharp analytical clarity, empowering teams to conquer complex operational landscapes. Behind this dynamic digital command center, implementing robust protocols like complyflow iso27001 certified establishes an unbreakable foundation of absolute security and trust. Ultimately, these advanced hook.co capabilities dashboards transform raw metrics into vibrant opportunities for unprecedented organizational growth and resilience.
Unlocking this next evolution of operational clarity relies on robust data ingestion, careful DOM manipulation, and stringent security barriers that keep malicious payloads at bay without slowing down real-time telemetry processing. Every external widget added and every script executed acts as a vital thread in a broader tapestry of system awareness.
Authentication Handshake Mechanics for External API Ingestion
Establishing a secure and resilient connection between external APIs and the hook.co environment begins with a sophisticated cryptographic handshake designed to verify identity and establish trust channels before a single byte of telemetry is exchanged. When an external developer tool attempts to feed data into the dashboard, it initiates a mutual TLS (mTLS) negotiation alongside an OAuth 2.0 authorization code grant flow enriched with Proof Key for Code Exchange (PKKE).
This multi-layered verification ensures that intercepted tokens remain useless to malicious actors while confirming the cryptographic fingerprint of the originating server. The external client transmits a signed JSON Web Token (JWT) containing ephemeral claims, including timestamp boundaries, tenant identifiers, and scoped permission arrays. Upon receipt, the hook.co ingress gateway validates the token against a distributed public key infrastructure, cross-referencing the issuer signature and expiration window with sub-millisecond latency.
Once validated, the gateway mints a short-lived session token bound exclusively to the client’s socket connection, effectively isolating the session from broader network movements. This rigorous cryptographic barrier prevents unauthorized data injection and safeguards the telemetry pipeline against man-in-the-middle exploits. Furthermore, rate-limiting policies are dynamically applied during the handshake phase based on historical behavioral analysis, ensuring that legitimate traffic flows unimpeded while anomaly-driven connection floods are throttled at the perimeter.
The entire sequence operates transparently in the background, maintaining an unbreakable chain of custody for every data point that eventually populates the visual widgets on the glass.
Endpoint Mapping Architecture for Real-Time Widgets
Connecting incoming event streams to specific visual components requires a structured translation layer that maps popular webhook payloads directly to UI elements. The following responsive table Artikels how external developer services interface with native dashboard containers.
| Service Provider | Webhook Endpoint Pattern | Target Visual Widget | Payload Processing Rule |
|---|---|---|---|
| GitHub Actions | /api/v2/hook/github/workflow | Pipeline Status Matrix | Extract build status and commit hash to update matrix node colors. |
| Datadog | /api/v2/hook/datadog/alert | Incident Heatmap | Parse severity scores to dynamically re-render heatmap intensity nodes. |
| PagerDuty | /api/v2/hook/pagerduty/incident | Escalation Timeline | Map incident lifecycle timestamps onto a chronological event stream. |
| Jira Software | /api/v2/hook/jira/issue | Velocity Burn-Down Gauge | Calculate story point deltas to adjust real-time velocity curves. |
DOM Injection Methods for Custom Telemetry Scripts
Integrating custom JavaScript telemetry scripts directly into the dashboard interface requires surgical precision to ensure that the underlying Document Object Model remains stable, responsive, and completely free of layout thrashing. Developers must avoid naive script loading techniques that block the main rendering thread or corrupt existing component hierarchies within the hook.co architecture. The following methods Artikel the precise steps required for safe, asynchronous telemetry embedding:
- Initialize a localized Shadow DOM encapsulation boundary using native Web Component standards to isolate the custom telemetry script’s styles and execution context from the main dashboard document.
- Construct a dynamic asynchronous script element in memory, assigning the external telemetry source URI while explicitly setting the attribute to async and crossorigin attributes for optimal resource fetching.
- Append the newly minted script node exclusively to a designated, isolated container element located deep within the secondary frame buffer rather than modifying the primary application root.
- Establish a secure MessageChannel interface to facilitate bi-directional communication between the isolated shadow root and the master dashboard state, preventing direct memory access leaks.
Secure DOM manipulation is not merely a performance optimization; it is the fundamental architectural firewall that guarantees zero downtime when third-party code executes in production.
Security Sandboxing Protocols for Cross-Origin Data Polling
Polling telemetry data across disparate domains introduces inherent vulnerabilities that require uncompromising isolation mechanisms to protect master administrative credentials. The hook.co platform deploys strict Content Security Policy (CSP) headers combined with isolated Web Workers to process untrusted JSON payloads entirely off the main execution thread. These background workers operate within a restricted zero-trust realm where access to cookies, local storage, and parent DOM nodes is cryptographically denied by the browser kernel.
When cross-origin polling occurs, incoming network packets are sanitized through a strict schema validation parser that strips out executable strings, SQL injection vectors, and malformed script tags before they ever reach state management stores. Authentication secrets, such as master API keys and bearer tokens, reside strictly within secure memory spaces inaccessible to external modules, utilizing proxy objects that intercept and sign requests without exposing raw credentials to the global scope.
This architectural defense-in-depth approach ensures that even if a compromised external tool attempts to exfiltrate session data, the sandboxed environment starves the exploit of actionable targets. Real-world implementations across enterprise monitoring systems consistently demonstrate that isolating polling logic within dedicated worker threads eliminates cross-site scripting propagation vectors while maintaining high-frequency data refresh rates.
Optimizing team collaboration features embedded inside hook.co capabilities dashboards
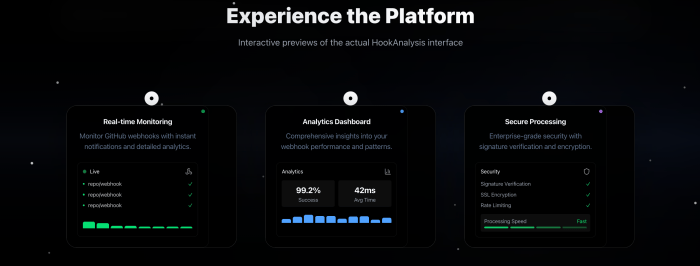
Source: githubusercontent.com
Modern engineering organizations thrive when operational data bridges the chasm between isolated silos and collective intelligence. Within the hook.co ecosystem, capabilities dashboards have evolved far beyond static monitoring panes into vibrant, shared command centers where cross-functional teams diagnose anomalies, debate architectural trade-offs, and execute rapid remediation strategies together in real time.
Harnessing this collective momentum requires meticulous orchestration of interactive workflows, ensuring that every participant—from front-end developers to executive stakeholders—can contribute meaningfully without compromising system integrity or data security.
Role-based permission matrices governing interactive annotation layers
Precision collaboration relies fundamentally on rigorous access boundaries that dictate who can modify, comment upon, or authorize changes within shared analytical workspace layers. The architectural backbone of hook.co capabilities dashboards utilizes a granular role-based permission matrix, dynamically evaluating user credentials against specific telemetry streams and canvas regions before rendering interactive annotation tools active. Imagine a bustling mission control center during a critical rocket launch, where flight controllers possess absolute authority over propulsion telemetry adjustments, while external observers maintain read-only visibility into trajectory projections; similarly, senior architects hold administrative dominion over system-wide threshold markers, empowering them to lock baseline configurations against accidental overrides by junior analysts, thereby preserving historical data fidelity across multi-departmental post-mortems.
This tiered access governance operates seamlessly behind the scenes, enforcing security protocols via cryptographically signed JSON Web Tokens that accompany every cursor movement, text note, and visual markup dropped onto the dashboard canvas. When an engineer with deployment-level clearance highlights an erratic latency spike on a microservices throughput graph, the system instantly validates their clearance level through the permission matrix, appending their organizational identity and security badge metadata to the sticky note container.
Conversely, team members restricted to viewer roles see the annotation rendered in a neutral, non-editable slate, complete with an informational tooltip displaying the authoring credentials and timestamp. By meticulously parsing user roles down to the individual component level, hook.co ensures that collaborative brainstorming remains structured, accountable, and entirely shielded from unauthorized alterations during high-pressure incident response intervals.
Procedure for pinning live metric snapshots into shared contextual discussion threads
Transforming fleeting visual observations into permanent organizational knowledge requires capturing exact temporal states of streaming telemetry and anchoring them directly inside ongoing asynchronous communication streams. The hook.co interface streamlines this critical handoff through a robust snapshot-pinning protocol designed to eliminate ambiguity during distributed troubleshooting sessions. Users initiate this workflow by activating the capture overlay on any active widget, which freezes the DOM rendering pipeline, packages the underlying time-series dataset into a lightweight vector payload, and generates a persistent deep-link identifier tied securely to the exact epoch timestamp.
Following capture, the engineer selects the target discussion thread from an integrated sidebar populated by connected enterprise messaging channels or internal project boards. The pinned snapshot does not merely transmit a flat PNG image; rather, it embeds an interactive, rendered WebGL widget preview alongside the commentary, allowing remote colleagues to hover over data points, inspect raw payload headers, and toggle underlying log layers without leaving their collaborative communication workspace.
When a distributed site reliability engineering team investigates an unexpected memory leak across production clusters in Frankfurt and Seattle, embedding these live metric snapshots directly into the shared incident channel drastically reduces mean-time-to-resolution by presenting every participant with the exact same interactive analytical viewport, eradicating discrepancies caused by delayed page refreshes or misaligned time zones.
Methods for exporting filtered view states into collaborative whiteboarding environments
Complex analytical discoveries frequently outgrow the rigid boundaries of standard dashboard widgets, necessitating a seamless transition into infinite-canvas whiteboarding tools where teams can map out root-cause hypotheses, sketch architectural rewrites, and correlate disparate system metrics against broader business OKRs. The hook.co platform bridges this analytical divide through a specialized export utility that translates active filter states, custom query parameters, and visual node hierarchies into standardized interchange formats compatible with leading enterprise visual collaboration spaces such as Miro and Lucidchart.
- The process begins when an analyst isolates a specific anomalous cluster using the multi-dimensional filtering toolbar, applying regex parameters and temporal boundaries to narrow millions of log events down to a precise failure signature.
- Upon clicking the collaborative export icon located in the primary navigation header, a modal dialogue prompts the user to select their preferred whiteboarding target and configure the fidelity level of the exported visual elements.
- The dashboard engine compiles the active state into a structured JSON payload containing vectorized chart graphics, embedded metadata tags, and direct hyperlinks back to the live hook.co telemetry source.
- Within seconds, the external whiteboard instantiates a fully interactive cluster map where product managers and software engineers can draw conceptual connection lines between the failing database node and downstream user-facing API gateways, turning raw diagnostic data into a tangible canvas for strategic problem-solving.
True organizational transparency is not achieved merely by broadcasting raw data to every corner of the enterprise, but by forging intuitive, secure, and interactive bridges that transform disparate observations into a unified, collective understanding of operational reality.
Scaling telemetry oversight across distributed enterprise clusters using hook.co capabilities dashboards

Source: facilityconnex.com
Modern enterprises operate within vast, geographically dispersed ecosystems where monitoring infrastructure demands surgical precision and unyielding reliability. As organizations expand their footprint across multiple continents, maintaining real-time visibility into mission-critical applications becomes a formidable test of engineering fortitude. The hook.co capabilities dashboards transform chaotic oceans of raw metrics into harmonious symphonies of actionable intelligence, empowering system administrators to master sprawling infrastructures.
Every byte of operational data finds its rightful place within a unified pane of glass, dissolving the friction that traditionally hindered enterprise-scale observability.
The journey toward absolute infrastructural transparency relies on sophisticated data ingestion pipelines that synthesize telemetry from thousands of isolated edge nodes. Operators no longer need to piece together fragmented puzzle pieces from disparate monitoring silos; instead, they experience a fluid, uninterrupted stream of health indicators. This seamless unification paves the way for unprecedented operational resilience, allowing engineering teams to anticipate anomalies long before they impact the end-user experience.
Multi-tenant hierarchy views aggregate regional server performance
Enterprise environments require structured governance models that reflect organizational boundaries while simultaneously providing a holistic macro-level perspective. Within the dashboard interface, multi-tenant hierarchy views serve as the architectural backbone for organizing complex clusters by region, business unit, and criticality. This structural clarity allows stakeholders from regional site reliability engineers to global chief technology officers to visualize performance metrics tailored precisely to their operational scope without cognitive overload.
Aggregating regional server performance across disparate time zones and network topologies requires robust data normalization algorithms running continuously in the background. The dashboard dynamically rolls up CPU utilization, memory pressure, and request latency from localized edge clusters into overarching regional summaries. When a localized performance dip occurs in a European data node, the hierarchical tree automatically flags the anomaly, visually pulsing with color-coded severity indicators that draw immediate operator attention.
Behind this visual elegance lies a sophisticated data aggregation framework capable of handling millions of time-series data points per second without breaking a sweat. By utilizing intelligent down-sampling techniques and distributed caching mechanisms, the interface ensures that historical trends and real-time spikes render instantaneously. Operators can effortlessly drill down from a global health map straight into the specific container logs of a single faltering micro-service residing in a specific rack within a Tokyo data center.
The visual depiction of this architectural marvel unfolds as an interactive, multi-layered cartographic interface bathed in sleek dark-mode aesthetics. Glowing geopolitical nodes pulse with vibrant cyan and emerald lights to represent healthy data flows, while constrained zones softly transition into amber caution states. Connecting these nodes are luminous data vectors whose thickness fluctuates dynamically to mirror real-time throughput volumes, painting a living portrait of global digital commerce in motion.
Effective enterprise telemetry is not merely about collecting massive volumes of data, but about establishing an intuitive visual hierarchy that transforms raw signals into immediate operational readiness.
Global data node bandwidth consumption analysis
Monitoring the flow of information across worldwide data centers requires granular tracking of network bandwidth to prevent bottlenecks and optimize payload distribution. The following responsive data structure Artikels bandwidth consumption patterns, peak processing loads, and latency thresholds across major global operational hubs.
| Global Data Node | Average Bandwidth Consumption | Peak Load Threshold | Average Latency |
|---|---|---|---|
| North America East (Virginia) | 4.2 TB/s | 6.8 TB/s | 12 ms |
| Europe Central (Frankfurt) | 3.8 TB/s | 5.9 TB/s | 18 ms |
| Asia Pacific (Tokyo) | 5.1 TB/s | 7.5 TB/s | 24 ms |
| South America (São Paulo) | 1.4 TB/s | 2.3 TB/s | 45 ms |
Automated failover visualization indicators notifying operators of localized network blackouts
When unexpected infrastructural disruptions occur, every second counts in mitigating downtime and preserving service level agreements across enterprise systems. Automated failover visualization indicators act as an early warning system, instantly transforming passive dashboard screens into high-alert operational command centers during critical incidents. These indicators do not merely report failures; they actively trace the automated rerouting of traffic away from compromised zones toward healthy redundant infrastructure.
The moment a localized network blackout is detected—such as a sudden fiber-optic severance or a regional cloud provider outage—the dashboard interface adapts its visual narrative dramatically. A pulsing crimson containment boundary immediately isolates the affected geographic sector on the global map view, accompanied by audible telemetry alerts and priority event logging. Simultaneously, secondary traffic vectors illuminate in bright electric blue, mapping out the precise alternative pathways that incoming requests are taking to bypass the blackout zone.
This real-time visualization removes the paralyzing uncertainty that typically accompanies major outage events, granting incident commanders clear visibility into automated recovery workflows. Operators can monitor the self-healing sequence step-by-step, observing as Kubernetes pods automatically spin up in failover regions to absorb the sudden surge in migrated workload demand. The interface also displays real-time convergence metrics, showing precisely when system stability is restored and data replication lag drops back to nominal operational tolerances.
Visualizing these complex failover sequences involves rendering dynamic flow-chart overlays directly on top of infrastructural topology maps, utilizing vector animations to denote active data redirection. Glowing pulse waves sweep across geographical boundaries to indicate the successful rerouting of client sessions, providing undeniable visual confirmation of system resilience. This transparent display of automated failover mechanics builds immense confidence among engineering teams, proving the absolute reliability of their distributed architecture.
Custom macro creation for instantly toggling between micro-service topologies and macro-level health scores
Navigating the vast chasm between individual container behaviors and global enterprise health can often overwhelm even the most seasoned system administrators. Custom macro creation bridges this analytical gap by allowing engineering teams to program bespoke viewing shortcuts tailored to their specific operational workflows and troubleshooting habits. With a single keystroke or a dedicated interface button, operators can instantly shift their perspective from a granular code-level trace to a sweeping macro-level enterprise health score.
Building these macros involves defining complex combinations of filters, time-range parameters, and layout configurations that can be deployed across any dashboard view within the enterprise ecosystem. For instance, a site reliability engineer can configure a macro that instantly collapses thousands of individual micro-service dependencies into a clean, high-level health index whenever error rates exceed a predefined threshold. Conversely, another macro can instantly unpack that same health index to reveal the exact failing API gateway and its associated memory leak footprint.
The flexibility of macro design empowers different organizational roles to customize their monitoring environments without altering the underlying telemetry ingestion pipelines or disrupting other team members. Development teams can focus intensely on call-stack topologies and inter-service communication latency, while executive leadership can pin persistent macro widgets displaying overarching business availability metrics. This democratization of data ensures that every stakeholder interacts with the telemetry platform in the manner most conducive to their specific responsibilities.
The visual transition executed by these macros unfolds with cinematic smoothness, employing fluid zooming animations that mimic plunging deep into a digital metropolis or soaring high above the clouds. As the view shifts from macro health scores to micro-service topologies, the interface gracefully cross-fades background telemetry grids into detailed dependency graphs complete with real-time payload heatmaps. This seamless morphological transformation keeps the operator anchored in context, ensuring that shifting perspectives never results in a loss of situational awareness.
Final Wrap-Up

Source: supabase.co
Ultimately, mastering these advanced interface ecosystems unlocks a boundless horizon of operational excellence and team synergy. As global networks expand and data grows ever more intricate, embracing these robust monitoring tools ensures that every organization remains resilient, focused, and perpetually prepared to turn tomorrow’s challenges into today’s greatest victories.
