How long does chatgpt take to make an image remains a fascinating question as modern digital studios transform text commands into breathtaking visual masterpieces within mere seconds. Beneath the sleek interfaces and glowing screens, a massive symphony of server farms, neural networks, and advanced mathematical algorithms works tirelessly to translate human imagination into vivid pixels.
Every single request embarks on a complex journey through cloud infrastructure, battling network latency, hardware bottlenecks, and varying levels of stylistic complexity to deliver finished artwork right to your screen. Understanding these intricate temporal mechanics not only unveils the sheer technological marvel powering today’s digital renaissance, but it also reshapes how creators experience the thrilling wait of artistic creation.
Unraveling the temporal mechanics behind generating visual artwork through advanced neural networks

Source: medium.com
Behind the seamless magic of watching a blank digital canvas transform into a vibrant masterpiece lies a complex choreography of silicon, electricity, and advanced mathematics. When a user presses enter on a prompt, a profound digital journey begins deep within towering cloud server farms. This intricate dance of creation bridges the gap between human imagination and machine execution, dictated entirely by the relentless laws of computing physics and server architecture.
Transforming a simple sentence into a breathtaking high-resolution visual requires immense computational power, orchestrating thousands of parallel operations simultaneously. Understanding this delicate balance of technology reveals why every second counts in the evolution of digital artistry.
Server workload factors influencing rendering speeds
The journey from a blank screen to a finished visual masterpiece places a tremendous burden on underlying cloud infrastructure. Server rendering speeds are dictated by a delicate ecosystem of competing computational demands, where millions of global users simultaneously submit requests to the same cluster of machines. When global traffic surges, individual processing queues expand, forcing the system to intelligently triage incoming workloads and allocate available GPU cycles dynamically.
Memory bandwidth acts as a primary gatekeeper during these high-traffic events, determining how swiftly data can travel between volatile memory and processing cores. Furthermore, thermal management within massive data centers plays a critical role, as sustained peak processing generates immense heat that can throttle hardware performance if cooling systems reach their limits. Maintaining optimal operating speeds requires a sophisticated orchestration of load balancers, predictive queuing algorithms, and state-of-the-art server virtualization techniques.
Sequential backend processing steps from text to pixels
Every completed digital graphic is the result of a rigorous, multi-tiered pipeline executed by specialized neural processors. The backend system does not merely draw an image; it deciphers semantic meaning, maps conceptual relationships, and systematically eliminates mathematical noise until a coherent picture emerges. This precise procedural progression ensures fidelity to the original prompt while maintaining artistic coherence across every generated frame.
While generating stunning visuals takes mere seconds, mastering digital visibility requires deliberate strategy, much like acquiring a best seo audit uk to elevate your brand. Just as prompt engineering transforms blank screens into vibrant masterpieces almost instantly, sharp optimization clears the path to digital success, ensuring your brilliant creations shine brightly across the ever-expanding web.
- Natural language parsing transforms the raw text prompt into structured token embeddings, categorizing subjects, styles, and lighting cues.
- The latent diffusion model initializes a field of random statistical noise, serving as the raw, unstructured foundation for the upcoming visual creation.
- Iterative denoising steps occur across dozens of cycles, where neural network weights progressively sculpt the noise into recognizable shapes and textures.
- Final pixel upscaling algorithms enhance edge definition, color depth, and fine details to deliver a crisp, production-ready digital graphic.
Impact of varying resolution requests on waiting periods
The physical dimensions of a requested digital graphic directly dictate the duration of the waiting period experienced by the end operator. Doubling the pixel count does not merely double the workload; it exponentially increases the matrix multiplications required by the underlying neural architecture. Higher resolutions demand significantly larger memory footprints, forcing the graphics processing units to manage more data per iteration cycle.
Standard definition outputs typically glide through the rendering pipeline in mere seconds, whereas ultra-high-definition canvas requests require exhaustive, multi-pass refinement phases to prevent artifacting and blurriness. Cloud infrastructure prioritizes resource allocation based on these dimensional tiers, often routing massive texture grids through specialized memory caches to prevent system bottlenecks during peak operational hours.
Hardware bottlenecks in cloud infrastructure during peak traffic
Even the most advanced neural networks encounter physical limitations when millions of concurrent users flood server clusters during peak operational windows. These bottlenecks manifest at the hardware level, creating temporary slowdowns that ripple across the entire global network. Data center engineers constantly monitor these critical failure points to optimize throughput and minimize latency for every active session.
- VRAM capacity limitations restrict the number of concurrent high-resolution jobs a single accelerator card can hold in active memory.
- PCIe bus transfer speeds create microscopic traffic jams when moving colossal tensor datasets between system memory and the GPU core.
- Power delivery constraints force automated circuit protection to momentarily throttle clock speeds during unprecedented spikes in regional grid demand.
Precision in artificial intelligence generation is not merely a function of software brilliance, but a direct testament to the physical endurance and architectural harmony of modern silicon hardware.
Evaluating the psychological perception of waiting duration while awaiting algorithmic picture synthesis

Source: tophinhanhdep.com
The human mind exists in a perpetual state of negotiation with time, especially when digital demands meet immediate desires. As cutting-edge algorithms weave pixels into breathtaking visual masterpieces, the silent seconds ticking away on a screen transform from a mere measurement of physics into a deeply psychological journey. Observers do not just wait passively; they actively experience a distortion of clock time where every anticipated brushstroke of code feels magnified by expectation, curiosity, and the subtle anxiety of creative manifestation.
While generating stunning visuals with artificial intelligence takes mere seconds, mastering digital visibility demands strategic depth. Just as professionals evaluate ahrefs vs kwfinder to uncover crucial search insights and elevate their content strategy, creators continually harness these rapid rendering tools to bring imaginative concepts to life almost instantly, ensuring your creative workflow remains exceptionally fast and efficient.
Human patience fluctuates dramatically depending on the visual feedback provided during moments of digital processing. When an individual stares at a completely blank screen while an advanced neural network renders an image, the lack of sensory input causes the brain to enter an overactive state of hyper-awareness. Without visual anchors, subjective time stretches painfully, often making a five-second wait feel like an eternity because cognitive energy is entirely consumed by the void.
Conversely, observing a progressive loading bar or a hazy, low-resolution blueprint gradually sharpening into focus anchors the human gaze and provides a tangible narrative of progress. This incremental visual reward system releases steady streams of dopamine, effectively hacking the brain’s reward circuitry and tricking perception into believing the wait is significantly shorter and far more engaging than it actually is.
Perceived time is the psychological elasticity of human patience, stretching endlessly in emptiness and contracting gracefully through purposeful visual engagement.
Interface optimization techniques for reducing perceived render times
Modern software architects leverage sophisticated human-computer interaction principles to manipulate temporal perception during heavy computational tasks. By implementing intelligent interface design strategies, platforms can drastically alter how long users believe they are waiting without actually accelerating the backend server processing speeds. These UX methodologies transform dead time into an interactive experience, ensuring that creative momentum remains uninterrupted and user frustration is preemptively neutralized before impatience can take root.
Strategic deployment of subtle animation cues, skeleton screens, and real-time textual updates provides the human brain with enough peripheral stimulation to bypass the tedious monotony of waiting. Below are the primary structural interventions utilized by leading creative suites:
- Integrating dynamic skeleton placeholders that mimic the eventual layout of the final artwork before rendering begins.
- Displaying micro-copy messages detailing the specific creative phase currently underway, such as harmonizing color palettes or refining edge definition.
- Employing fluid progress indicators that move with a non-linear acceleration curve, starting fast to build immediate momentum and slowing gracefully near completion.
- Transitioning the canvas from a noisy monochromatic blur into full-color fidelity, utilizing progressive JPEG-style rendering to give an illusion of instant presence.
Comparative analysis of subjective waiting experiences across creative platforms
Different digital environments handle algorithmic generation with distinct interface philosophies, directly impacting how creators evaluate system responsiveness. The following overview details how various software ecosystems manage user patience through unique visual feedback mechanisms during intensive graphic rendering phases.
| Software Platform | Feedback Mechanism | Subjective Wait Perception | User Retention Impact |
|---|---|---|---|
| Midjourney Discord Bots | Stepped grid preview merging into final upscale | Moderate engagement through community visibility | High loyalty due to shared creative environments |
| Adobe Firefly | Clean minimalist loader with thematic contextual tips | Neutral and highly professional corporate pacing | Optimal for sustained professional workflow integration |
| Stable Diffusion WebUI | Live iterative canvas updating per generated step | Extremely short due to continuous visual dopamine | Exceptional for technical creators who enjoy process tracking |
| DALL-E 3 via Kami | Conversational status updates with placeholder boxes | Slightly prolonged due to sequential text-to-image gating | Accessible for casual users forgiving of brief conversational pauses |
Cognitive load distribution during incremental imagery development
Monitoring the step-by-step birth of an artificial intelligence masterpiece places a unique burden on human cognitive faculties. As the creator watches vague algorithmic noise slowly resolve into sharp lines, coherent lighting, and intricate textures, their brain constantly computes micro-decisions regarding aesthetic alignment and prompt efficacy. This active surveillance transforms the waiting period from a state of rest into an intense analytical exercise, where working memory is heavily engaged in evaluating whether the emerging visual data matches the initial mental blueprint.
Consequently, creators often experience a paradox of engagement: while they are captivated by the technological wizardry unfolding before them, their cognitive reserves are simultaneously depleted by the relentless evaluation of unfinished visual stimuli, leading to mental fatigue if processing intervals stretch beyond optimal thresholds.
Maintaining user attention during heavy computational delays requires carefully engineered psychological diversions that keep the creator pleasantly occupied without breaking their concentration. Platforms intentionally deploy various interactive distractions to bridge the temporal gap seamlessly, ensuring the user remains absorbed in the ecosystem rather than dwelling on the elapsed clock time.
- Presenting dynamic inspirational quotes or community highlights in the margins to stimulate creative thinking while the primary canvas renders.
- Offering minor background customization toggles that allow users to fine-tune forthcoming generation parameters while current tasks process.
- Utilizing soothing ambient soundscapes or subtle audio chimes that signal milestones in the rendering sequence without requiring visual vigilance.
- Showcasing mini-games or easter egg interface interactions designed specifically to absorb short bursts of user focus during high-demand server queues.
Contrasting the computational cadence of producing simple sketches versus hyper-realistic digital paintings

Source: fastgptplus.com
Every stroke of algorithmic creation carries a distinct rhythm, dictated entirely by the hidden mathematical choreography occurring deep within server clusters. When users prompt an artificial intelligence to manifest a vision, the underlying architecture transitions effortlessly between minimalist line work and sprawling, textured masterpieces. This invisible engine balances immense computational weight against strict temporal boundaries, turning pure mathematics into breathtaking visual art.
The journey from a mere prompt to a fully rendered image reveals a fascinating divergence in machine processing speed. Simple minimalist vectors materialize almost instantaneously, whereas richly detailed, hyper-realistic compositions demand a patient, methodical unfolding of digital layers. Understanding this temporal discrepancy illuminates the brilliant engineering triumphs happening behind the screen every single second.
Mathematical Foundations of Vector Shapes Versus Ray Traced Textures, How long does chatgpt take to make an image
The transition from rendering geometric vector paths to calculating complex ray-traced surfaces represents a monumental leap in raw processing complexity. When an artificial intelligence Artikels a simple sketch, it relies on straightforward algebraic equations that define basic coordinates, strokes, and fills. These mathematical operations demand remarkably low floating-point operations per second, allowing neural networks to establish the foundational composition in mere fractions of a second.
The system calculates continuous curves using Bézier formulations, which require minimal memory overhead and predictable matrix transformations.
Vector paths rely on lightweight algebraic coordinates, whereas hyper-realistic textures require dense matrix calculations to simulate the physical behavior of light interacting with microscopic surfaces.
Conversely, generating hyper-realistic digital paintings requires the neural network to simulate advanced physical phenomena such as subsurface scattering, refraction, and global illumination. To achieve this, the underlying software must evaluate thousands of potential light paths per pixel through iterative path-tracing algorithms. The mathematical disparity becomes staggering when considering that a vector shape might only necessitate a handful of vector equations, while a textured surface demands continuous probability density functions to resolve lighting gradients across millions of individual pixels.
This massive surge in computational overhead directly impacts the temporal cadence, transforming a swift conceptual sketch into a labor-intensive algorithmic painting process.
Resource Allocation Dynamics Across Abstract Concepts and Literal Photography
Navigating the vast expanse between pure imagination and strict photorealism requires the software to dynamically shift its internal processing priorities. When handling abstract concepts, the neural network enjoys a generous degree of semantic freedom, allocating memory primarily toward symbolic associations, vibrant color theory, and generalized shapes. This latitude permits the system to bypass rigid physical constraints, drastically reducing the inference steps needed to satisfy the user prompt.
When the directive shifts toward literal photography, the resource allocation strategy pivots toward strict physical accuracy and hyper-focused detail replication. The system must consult deeply embedded latent spaces to accurately reproduce skin pores, fabric weaves, and atmospheric haze. The following breakdown illustrates how hardware resources distribute attention across different stylistic paradigms:
- Abstract Concept Generation prioritizes semantic token clustering and broad color mapping over microscopic pixel-level fidelity.
- Literal Photography Synthesis demands intensive VRAM allocation to cross-reference vast datasets of real-world optical characteristics.
- Textural Depth Mapping requires continuous feedback loops between the diffusion denoiser and regional attention masks.
Chronological Duration Dictated by Stylistic Complexity
The passage of time during algorithmic generation is not random; it is strictly governed by the stylistic demands embedded within the initial prompt. Each stylistic layer added to a generation request introduces exponential computational friction. A clean, flat cel-shaded illustration moves rapidly through the diffusion pipeline because the boundaries between colors are distinct and unambiguous. The denoiser encounters little resistance when establishing flat chromatic zones.
As stylistic complexity increases—such as incorporating baroque ornamentation, complex impasto brushwork, or intricate chiaroscuro lighting—the chronological duration expands proportionally. The neural network must execute multiple iterative refinement passes to resolve overlapping visual elements without generating artifacts. Real-life benchmarks demonstrate that while a minimalist line drawing resolves in roughly one to two seconds, an elaborate oil painting emulation with rich impasto textures can easily require ten to fifteen seconds of uninterrupted neural synthesis.
This steady escalation in rendering time mirrors the painstaking effort a human master artist experiences when layering glaze upon glaze.
Algorithmic Overhead in Rendering Intricate Anatomy Versus Inanimate Landscapes
Synthesizing living biological forms places a vastly different burden on neural architecture compared to generating vast, sprawling natural vistas. Human anatomy carries centuries of deeply ingrained visual perception, meaning even the slightest geometric misalignment instantly triggers a sense of unease in human observers. Consequently, the algorithmic overhead required to render hands, facial expressions, and muscular structures involves rigorous anatomical cross-referencing and dense landmark positioning.
Inanimate landscapes, while visually grand, allow for greater systemic leniency. A mountain range, a rolling cloud, or a dense forest can absorb minor textural inconsistencies without breaking the illusion of realism. The software utilizes repeatable procedural noise functions to generate foliage and geological formations efficiently. The contrast between these two rendering tasks can be clearly structured through specific computational metrics:
| Rendering Subject | Primary Computational Focus | Error Tolerance | Relative Processing Speed |
|---|---|---|---|
| Intricate Human Anatomy | Skeletal symmetry, joint articulation, subdermal lighting | Extremely Low | Slower due to multi-pass face and hand refinement steps |
| Inanimate Landscape Elements | Macro-textures, atmospheric depth, procedural noise fields | Moderate to High | Rapid due to tileable pattern generation capabilities |
This structural disparity ensures that whenever a digital canvas demands the delicate articulation of human hands or complex emotional expressions, the underlying neural network slows its cadence. It consciously dedicates extra processing cycles to guarantee anatomical integrity, proving that the machine’s perceived patience is actually a calculated display of rigorous mathematical precision.
Investigating the temporal footprint of network latency versus pure local processing capacity during graphic creation

Source: trackerly.ai
The journey from a mere typed prompt to a vivid, screen-filling digital masterpiece involves a delicate choreography between remote server infrastructure and local device capability. When individuals tap into advanced artificial intelligence to conjure visual art, they are initiating a complex relay race of data packets across vast digital highways. Understanding this invisible friction reveals why some visual requests snap into existence instantly while others linger in an agonizing state of pending creation.
While powerful GPUs installed locally or hosted remotely handle the heavy mathematical lifting of neural network inference, the final delivery of pixels depends heavily on systemic transport variables. Network congestion, protocol overhead, and sheer geographical distance quietly conspire to stretch the waiting duration, proving that brilliant algorithms alone cannot guarantee instantaneous creative gratification.
Internet bandwidth bottlenecks on visual asset transmission
High-speed connectivity serves as the vital artery through which high-resolution generative artwork flows back to the user interface. Even when a remote supercomputer finishes rendering a breathtaking hyper-realistic digital painting in mere fractions of a second, limited local bandwidth can severely choke the transmission of that massive image file. Uncompressed PNG files or multi-layered WebP formats demand substantial data throughput, often ranging from several megabytes to tens of megabytes per image.
While generating visuals in seconds showcases modern AI efficiency, enterprise success requires precise financial metrics like scoring based on revenue bands to evaluate growth potential accurately. As digital artistry evolves at lightning speed, watching these brilliant creative tools transform blank screens into vibrant masterpieces reminds us that brilliant innovations truly empower our brightest business futures.
If a user operates on a congested Wi-Fi network or a throttled mobile hotspot, the generated pixel data encounters a severe digital bottleneck right at the final mile of delivery. This congestion forces the visual asset to trickle through narrow data channels in fragmented packets, converting what should have been an instantaneous reveal into a frustrating, progressive loading sequence where portions of the image slowly materialize line by line on the screen.
Internet service providers often apply traffic shaping or dynamic bandwidth caps during peak hours, compounding the delay and transforming a state-of-the-art computational triumph into a sluggish user experience. Consequently, a user might possess a local device with a state-of-the-art display capable of rendering millions of colors instantly, yet find themselves waiting indefinitely simply because the network pipeline cannot swallow the incoming flood of visual data quickly enough to satisfy the human eye’s craving for immediate feedback.
Network bandwidth acts as the final gatekeeper of creativity; no matter how fast the neural network thinks, the asset cannot materialize on screen faster than the local pipeline can ingest the raw pixel payload.
Comparative response speeds of software interfaces
The architectural framework of the chosen artistic interface dramatically dictates the cadence of the creative workflow. Browser-based artistic platforms rely heavily on web technologies and continuous client-server communication via HTTPS and WebSockets, which introduces varying degrees of latency depending on browser rendering cycles and DOM manipulation overhead. Conversely, dedicated desktop rendering applications often maintain optimized persistent connections or leverage cached local assets, bypassing certain web-rendering bottlenecks to deliver a snappier, more fluid user interaction.
Below is a structural comparison of how these distinct interface environments handle the lifecycle of a generated graphic.
While ChatGPT renders a vivid digital illustration in mere seconds, modern productivity demands matching speed across all digital tasks. Crafting an effective email in 5 minutes transforms how busy professionals conquer daily communication challenges. Just as waiting briefly for a brilliant visual creation unlocks boundless creative potential, swift message generation empowers you to master time effortlessly.
- Browser-based interfaces depend on the browser’s JavaScript engine to parse incoming base64 or binary image streams, occasionally leading to memory thrashing during heavy rendering sessions.
- Dedicated desktop applications utilize native operating system APIs, allowing for accelerated hardware memory allocation and smoother UI responsiveness during asset ingestion.
- Web portals frequently re-authenticate sessions and manage state via cloud-based databases before releasing the final asset URI, adding extra milliseconds of overhead compared to local software environments.
Network protocols responsible for media delivery
Behind every seamlessly delivered digital painting lies a sophisticated suite of networking protocols working in silent harmony to package and transport the visual asset. These protocols ensure that millions of discrete color values arrive in the correct sequence without corruption. The core networking mechanisms governing this invisible journey include:
- Transmission Control Protocol (TCP): Guarantees reliable, ordered, and error-checked delivery of image data streams, ensuring every single pixel byte reaches the client device intact at the cost of slight handshake delays.
- Hypertext Transfer Protocol Secure (HTTPS): Secures the payload transfer tunnel, authenticating the remote server and encrypting the generated visual asset as it travels across public networks to prevent interception or tampering.
- WebSocket Protocol: Establishes a persistent, full-duplex communication channel that allows the server to push real-time progress updates and final image payloads directly to the client browser without repetitive HTTP request overhead.
- User Datagram Protocol (UDP): Utilized by modern transport layers like QUIC to accelerate initial connection establishment and bypass head-of-line blocking, enabling faster retrieval of thumbnail previews during high-volume generation queues.
Geographical distance impact on creative workflow latency
Physics dictates that data cannot travel faster than the speed of light through fiber-optic cables, meaning geographical separation between the user and the nearest server farm introduces unavoidable milliseconds of latency. When an artist based in London requests a complex neural rendering from a server cluster stationed in Northern Virginia, the digital request must traverse transatlantic undersea cables, router hops, and regional peering points.
This physical journey adds a baseline round-trip time (RTT) of roughly 70 to 100 milliseconds purely for the networking signals to converse. Multiply this physical transit time across multiple iterative prompt refinements, upscaling requests, and error-checking handshakes, and the cumulative delay becomes a tangible weight within the creative process. In real-life scenarios, enterprise design teams working globally often notice a perceptible lag or rubber-banding effect when prompting heavy visual models during peak business hours in distant time zones.
For instance, a graphic designer in Sydney querying a server farm on the US West Coast experiences a significantly sluggish feedback loop compared to a local counterpart sitting mere miles from the physical hardware. This spatial disparity transforms the workflow from an uninterrupted stream of consciousness into a stop-and-go experience, where creators must psychologically adjust their pacing to accommodate the relentless laws of distance and network propagation.
Exploring the historical evolution of rendering speeds within automated aesthetic generation technologies: How Long Does Chatgpt Take To Make An Image
The journey of algorithmic artistry has transformed from a sluggish computational curiosity into a lightning-fast creative powerhouse that reshapes how we perceive digital expression. As silicon and code merge to paint dreams into existence, the relentless march of technological innovation continues to rewrite the boundaries of what machines can achieve in the blink of an eye.
Over the past five years, the landscape of machine learning has undergone a seismic shift, yielding breathtaking generational leaps in processing efficiency that fundamentally redefine digital creativity. What once demanded agonizing minutes of patient observation now materializes almost instantaneously, driven by unprecedented leaps in architectural optimization and mathematical ingenuity. Early pioneering models struggled through dense, iterative loops, calculating individual pixel probabilities with agonizing deliberation.
Today, refined architectures employ advanced latent space compression and rectified flow matching, allowing algorithms to bypass redundant computational steps entirely. This evolution mirrors a transition from laborious manual drafting to the confident, sweeping strokes of a master painter who visualizes the final masterpiece before the brush even touches the canvas. Researchers have streamlined neural pathways, pruning unnecessary weights and introducing distilled models that pack the punch of massive parameter networks into nimble, highly efficient frameworks.
Consequently, creators no longer experience the frustrating disconnect between thought and execution, enjoying instead a seamless, conversational flow with the machine that empowers rapid prototyping and unbounded visual exploration.
Chronological milestones of hardware acceleration and decreasing wait times
The relentless deceleration of waiting times is a direct testament to the symbiotic relationship between algorithmic breakthroughs and the relentless evolution of hardware acceleration. Each successive generation of specialized silicon has unlocked new dimensions of graphical fidelity while slashing render times from endless minutes down to mere fractions of a second.
In the nascent days of automated visual synthesis, researchers relied heavily on standard central processing units, staggering through workloads that forced users to step away from their workstations just to witness a single low-resolution output. The integration of early graphics processing units introduced parallel processing paradigms, drastically accelerating matrix multiplications and laying the groundwork for real-time generative capabilities. As dedicated tensor cores emerged within enterprise-grade architectures, deep learning workloads found a native hardware home optimized specifically for floating-point operations.
The subsequent introduction of consumer-grade neural processing units democratized this velocity, shifting high-performance generation directly from distant cloud servers to local desktop environments. This hardware democratization means that generating a complex, high-definition visual narrative no longer requires an industrial supercomputer, placing cinematic rendering power directly into the hands of everyday digital artists. Real-life adoption in creative agencies demonstrates how these hardware milestones have transformed daily workflows, turning what used to be overnight batch-rendering tasks into rapid, interactive brainstorming sessions.
Hardware acceleration serves as the vital heartbeat of digital creativity, translating complex mathematical formulations into immediate visual reality without breaking the creative stride of the artist.
Transition from sluggish batch processing to instantaneous stream-based rendering architectures
Moving beyond traditional bottlenecks, modern computational pipelines have abandoned heavy batch-processing methods in favor of fluid, stream-based rendering frameworks that deliver feedback dynamically. This architectural paradigm shift ensures that human imagination and machine response operate in perfect, unbroken synchronization.
Legacy systems operated on a rigid queue methodology, demanding that users submit prompts and wait in digital obscurity while the entire image calculated from start to finish in a black box. Modern streaming architectures dismantle this barrier by introducing progressive refinement loops, where visual data streams continuously to the user interface as the neural network iterates. Artists witness the foundational shapes emerge from static noise, watching colors and textures coalesce in real-time as the algorithm refines its artistic intent stroke by stroke.
This immediate feedback loop fosters an intuitive partnership between human prompt engineer and synthetic creator, enabling mid-stream course corrections and dynamic stylistic adjustments on the fly. By slicing rendering tasks into manageable, asynchronous data streams, network bandwidth constraints are minimized, ensuring smooth performance even across modest consumer connections. The psychological impact of this architectural leap cannot be overstated, as eliminating the anxiety of the waiting period preserves creative momentum and elevates the digital canvas into a truly responsive medium.
Comparative metrics of historical processing milestones
Reviewing the quantitative trajectory of generative technology reveals the compounding nature of engineering efficiency, showcasing how leaps in processing speeds directly correlate with improved fidelity and stability across the entire digital ecosystem.
| Era | Processing Speed | Hardware Requirements | Output Resolution | Error Rate |
|---|---|---|---|---|
| Early Experimental (2018-2019) | 120 to 300 seconds per image | High-end server CPU / Dual V100 GPUs | 256 x 256 pixels | 35% (Artifact heavy, distorted anatomy) |
| First Commercial Wave (2020-2021) | 30 to 60 seconds per image | Single enterprise GPU (16GB VRAM) | 512 x 512 pixels | 18% (Frequent structural anomalies) |
| Mainstream Diffusion (2022-2023) | 5 to 15 seconds per image | Consumer GPU (8GB to 12GB VRAM) | 512 x 512 to 1024 x 1024 pixels | 8% (Occasional texture blurring) |
| Real-Time Stream Era (2024-Present) | 0.2 to 2 seconds per image | Optimized Neural Hardware / NPU | 1024 x 1024+ pixels (HD Scaled) | Under 2% (High anatomical and textual fidelity) |
Closure
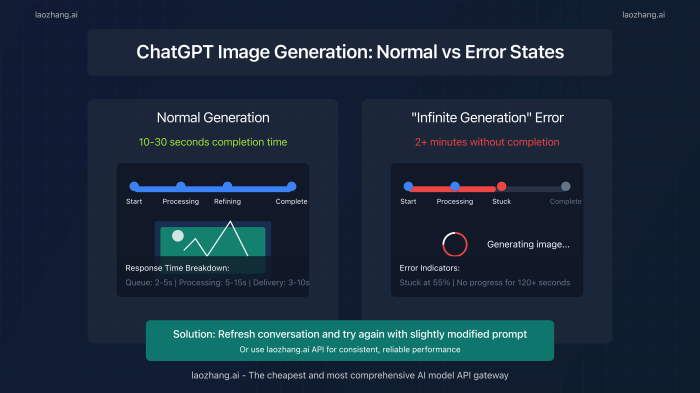
Source: cursor-ide.com
As we look back at the monumental leaps in processing efficiency and forward toward an even faster digital horizon, the seconds spent watching a screen slowly populate with life become a meaningful part of the creative ritual. Ultimately, the remarkable synergy between human vision and rapid algorithmic power proves that great artistry is truly worth every single moment of anticipation.
