how to build pivot table unlocks a transformative journey where chaotic seas of raw data suddenly part to reveal crystal-clear horizons of actionable business intelligence. We stand at the intersection of confusion and clarity, where every disorganized row of numbers holds the potential to rewrite the trajectory of an enterprise. By embracing disciplined data hygiene and intentional structural shifts, analysts cross the threshold from passive observation into active digital storytelling, turning fragmented records into living blueprints of operational success.
Mastering this dynamic calculation matrix empowers decision-makers to distill millions of data points into focused, executive-ready insights with remarkable precision. As we explore the mechanics of spatial quadrant arrangement, chronological grouping, and real-time data synchronization, you will discover how a simple interface can completely revolutionize your analytical workflow. Prepare to elevate your reporting standards and watch your raw spreadsheets breathe with purpose, clarity, and undeniable momentum.
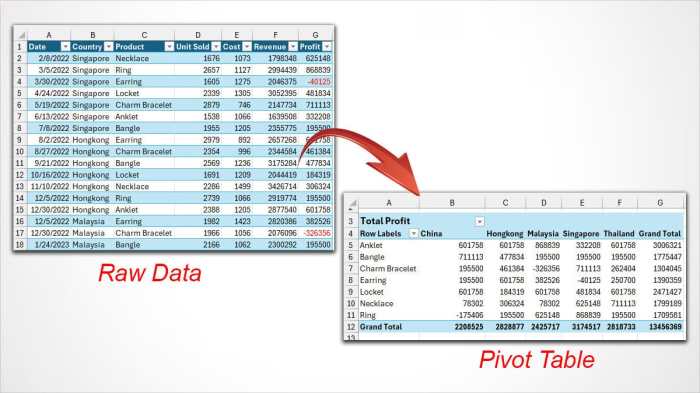
Unlocking the hidden narrative within raw spreadsheets requires mastering the foundational mechanics of dynamic data summaries.
Source: insidetheweb.com
Stepping into the realm of multidimensional reporting demands a fundamental rewiring of how we perceive a grid of numbers. For years, the traditional spreadsheet has conditioned us to read information linearly, scanning horizontally across rows or vertically down columns like lines in a ledger. This flat-file mentality treats data as an endless wall of text where every entry holds equal visual weight, masking the vital relationships hidden beneath the surface.
Transitioning to dynamic summaries requires a cognitive leap from passive record-keeping to active data sculpting. Instead of asking what a single row represents, the analytical mind must instantly visualize information as fluid blocks of dimensions and metrics, ready to be rotated, filtered, and compressed on demand.
This psychological evolution transforms the spreadsheet from a static digital filing cabinet into a responsive lens that focuses clarity onto chaotic markets, operational bottlenecks, or shifting consumer behaviors. When analysts break free from rigid, static rows, they stop manually calculating totals and start interrogating the underlying architecture of their information. Imagine looking at a sprawling global sales sheet for a multinational retailer; the flat-file view presents a blinding snowstorm of individual transaction IDs, shipping dates, and SKU numbers.
The mental shift occurs the moment an analyst stops seeing individual sales receipts and begins perceiving clustered constellations of regional performance, seasonal demand spikes, and category dominance. Embracing this multidimensional perspective allows professionals to construct frameworks where answers emerge dynamically, turning overwhelming volumes of enterprise data into immediate, actionable intelligence that drives strategic business decisions.
Prerequisite Data Hygiene Habits for Accurate Aggregation
Before a single dynamic summary can be conjured, the underlying data must undergo a rigorous cleansing ritual to ensure absolute mathematical integrity. Machine aggregation engines rely on rigid consistency; even minor architectural flaws in a source dataset can cascade into catastrophic calculation errors, instantly rendering executive dashboards misleading or entirely useless. Establishing disciplined preparation habits acts as the ultimate insurance policy against skewed metrics, false totals, and broken relationships during the grouping process.
The journey toward flawless data hygiene begins with the absolute enforcement of uniform column headers across the entire dataset. Every single column must possess a unique, descriptive title residing exclusively in the top row, completely free of merged cells, decorative line breaks, or empty spaces that confuse database indexing engines. Furthermore, data types within each column must remain strictly homogenous.
Mixing text strings into a designated currency column or inserting unexpected dates into a numerical quantity field will cause aggregation tools to silently drop records or return frustrating value errors.
Consistency in data entry is equally critical for successful grouping and filtering operations. Minor typographical variations, such as recording a region as ‘North’ in one row and ‘north ‘ with a trailing space in another, will fracture a pivot engine into treating them as entirely distinct entities. Implementing strict validation rules or master drop-down lists prevents these silent discrepancies from infiltrating the source material.
Additionally, removing trailing spaces, standardizing date formats to an international ISO standard, and eliminating unformatted text characters ensure that the calculation engine computes sums and averages with absolute precision.
Visual representation of data hygiene principles reveals the stark contrast between functional chaos and structural readiness. The following structural comparison Artikels the transformation required to prepare raw inputs for reliable multidimensional analysis.
| Dimension Evaluated | Messy Data Layout | Submission Ready Table Format | Operational Impact |
|---|---|---|---|
| Column Headers | Merged cells spanning multiple columns with blank spaces. | Single-row unique headers with descriptive text. | Prevents indexing failures and ensures correct field mapping. |
| Data Consistency | Mixed data types, text in numeric fields, trailing spaces. | Homogenous data types, standardized text casing, trimmed spaces. | Eliminates calculation errors and prevents fragmented groupings. |
| Row Integrity | Blank separator rows and embedded subtotal summaries. | Continuous contiguous rows without internal gaps or totals. | Allows automated boundary detection and accurate grand totals. |
| Date Formats | Inconsistent regional date entries and textual representations. | Standardized numerical date format across all records. | Enables seamless chronological grouping and time-series analysis. |
Precision Range Selection Techniques for Dynamic Data Architecture
Accurate data architecture relies heavily on defining the precise geographical boundaries of your source information before activating any summarization tool. Selecting a data range incorrectly introduces severe structural vulnerabilities into your reporting pipeline. Capturing extraneous blank rows forces the calculation engine to process empty sets, artificially inflating record counts and introducing phantom categories into your final reports. Conversely, failing to encompass the entire dataset results in truncated summaries that silently omit critical performance metrics from executive visibility.
Mastering range selection requires understanding the mechanics of contiguous data blocks within modern spreadsheet grids. Analysts must bypass the dangerous habit of manually dragging selection cursors across thousands of rows, a method prone to human fatigue and accidental boundary slippage. Utilizing native programmatic shortcuts instantly locks onto the exact outer perimeter of the active dataset, recognizing natural barriers formed by completely empty border rows and columns.
When preparing to generate a dynamic summary, visual verification of the active selection zone is essential. A properly bounded data range exhibits a glowing marquee border that wraps snugly around the exact matrix of headers and records, stopping precisely before any aggregated summary footers or external calculation notes sitting at the bottom of the sheet. Including summary footers inside a source range is a cardinal sin in data architecture, because the pivot engine will aggregate those pre-calculated totals alongside raw transactional data, effectively doubling the metrics and destroying the validity of the final report.
To visualize the ideal selection environment, picture a pristine digital excavation site where the soil has been cleared away to expose only the pure, load-bearing architecture of the business. The top boundary is marked by clean, unmerged headers glowing with clear categorical definitions. The left and right flanks are defined by steady, predictable data streams flowing downward without interruption. The bottom boundary halts decisively at the final transaction record, leaving external notes, commentary blocks, and manual grand totals safely outside the perimeter.
To guarantee mathematical accuracy, always isolate raw transactional inputs from manual summary calculations, ensuring that the selected source matrix contains exclusively primary records and uncompromised categorical dimensions.
Executing this disciplined approach to boundary definition guarantees that every subsequent calculation, filter, and drill-down operation pulls from a pristine, trustworthy foundation. By respecting the structural integrity of the source range, analysts protect their final outputs from computational distortion, establishing a reliable baseline for enterprise-grade intelligence reporting.
Activating the data summation engine involves navigating interface menus to summon the blank canvas of a fresh calculation matrix.
Stepping beyond the raw boundaries of endless data rows requires a decisive mechanical shift, transforming passive numerical records into a dynamic playground of business intelligence. This vital operational transition begins the moment you command the software to synthesize millions of data points into a singular, responsive calculation matrix. Every modern spreadsheet environment relies on a distinct architectural pathway to summon this analytical core, requiring deliberate user input to establish the boundaries of the forthcoming data summary.
Launching the foundational matrix generation dialog box demands a precise mechanical sequence, tailored to the specific software architecture currently occupying your workstation display. Mastering these precise clicks removes friction from your analytical workflow, allowing you to bridge the gap between unstructured records and executive-level insight with absolute mechanical precision.
Precise sequence of mouse clicks required to launch the matrix generation dialog box from various spreadsheet applications
Initiating the matrix generation sequence across different software environments requires navigating specialized ribbons, menus, and contextual toolbars designed to handle heavy computational lifting. Understanding these precise pathways ensures you never waste precious seconds hunting for hidden tools while deadlines loom large over your desk.
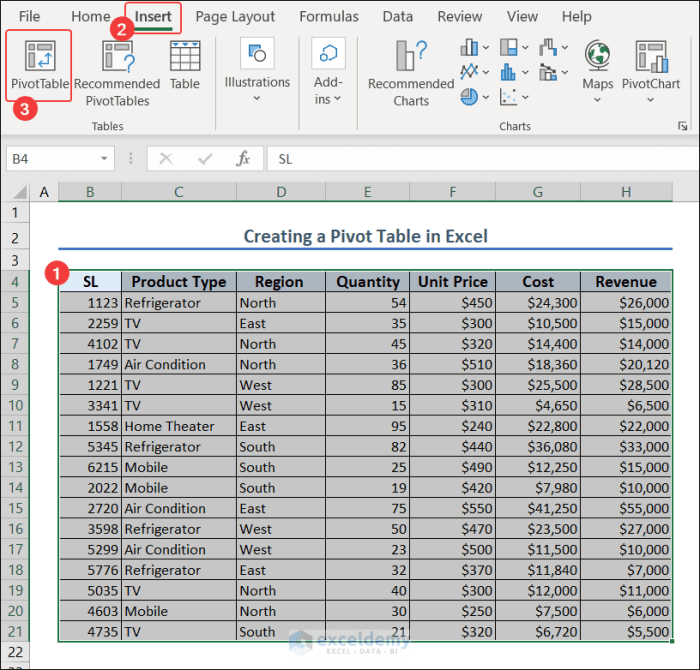
- Locate the primary menu ribbon at the uppermost boundary of your desktop application window and execute a deliberate left-click upon the Insert tab to expose the primary object creation tools.
- Scan the newly revealed toolbar icons from left to right until your cursor isolates the PivotTable command button, which often features a stylized grid icon symbolizing dynamic data restructuring.
- Click directly on the PivotTable icon to instantaneously trigger a prominent modal dialogue box over your active workspace, featuring pre-selected cell boundaries that envelop your continuous block of source data.
- Review the flashing marquee border visually marching around the perimeter of your source dataset, confirming that the software has successfully trapped every essential row and column inside the calculation perimeter.
- Finalize the preliminary launch sequence by pressing the Enter key or clicking the prominent OK button situated at the base of the dialog box, immediately deploying the pristine blank canvas onto your screen.
Menu pathways across desktop software cloud variants legacy versions and mobile applications
Navigating the vast ecosystem of spreadsheet tools requires adapting your tactical approach depending on whether you are running a heavy local installation, accessing a browser-based cloud environment, or operating a touch-screen mobile device on the go.
| Software Category | Primary Ribbon Tab | Secondary Menu Selection | Execution Trigger |
|---|---|---|---|
| Desktop Software | Insert | Tables > PivotTable | Dialog Box Confirmation |
| Cloud Variants | Data | Pivot table | Create button in side panel |
| Legacy Versions | Data | PivotTable and PivotChart Report | Step 3 Wizard Completion |
| Mobile Applications | Overflow (…) | Insert > Pivot Table | Selection range confirmation |
Decision making process for placing the resulting summary onto an existing sheet versus spawning a dedicated tab
Choosing where your newly spawned calculation matrix will live is a strategic architectural decision that directly influences the long-term readability, scalability, and maintenance of your workbook. Placing a summary matrix onto an existing sheet alongside raw data can conserve workspace tabs in smaller reports, but it drastically increases the risk of horizontal or vertical collision as the summary dynamically expands and contracts.
Spawning a dedicated tab for your dynamic summary isolates the analysis from the unpredictable fluctuations of underlying source data feed updates, creating a clean executive dashboard experience. When working with enterprise-grade datasets containing hundreds of thousands of entries, housing the pivot table on its own designated worksheet prevents visual clutter and protects downstream formulas from accidental overwrites. Seasoned data architects consistently recommend deploying dedicated tabs for mission-critical reports, ensuring stakeholders can interpret metrics without scrolling past thousands of raw input rows.
Visual indicators confirming the system has successfully anchored your source range to the new summary interface
Recognizing the visual cues of a successfully anchored data connection provides immediate psychological reassurance that your analytical workspace is primed and ready for action. Without these subtle interface cues, users risk building complex summaries on top of corrupted or unlinked data ranges, leading to catastrophic reporting errors.
A properly anchored data engine immediately surrounds your source cells with an animated, marching border of alternating light and dark dashes, visually sealing the dataset within the computational memory of the application.
Simultaneously, a floating or docked panel appears on the right side of your interface, populating its top section with the exact field headers pulled directly from the top row of your anchored range. The appearance of these distinct field names serves as undeniable visual confirmation that the software has successfully ingested your structural metadata, transforming static text cells into active variables ready to be dragged and dropped into your newly summoned calculation matrix.
Arranging fields into specific spatial quadrants transforms an empty grid into a coherent tapestry of metric insights.
Source: exceldemy.com
Stepping beyond the initial setup reveals the true architectural core of data summarization, where raw numbers find their purposeful place in the world. Constructing an informative report relies heavily on intentional placement, turning chaotic rows of digital ledger entries into a structured landscape of business intelligence. Every corner of the workspace holds a distinct purpose, acting as a gravitational pull for specific types of information that dictate how the final story unfolds.
Mastering how to build pivot table transforms chaotic spreadsheets into vibrant, crystal-clear financial landscapes where every data point tells a compelling story. As modern analysts uncover hidden market dynamics, utilizing advanced site search operators find affiliate listicles best recruiting software reviews becomes crucial for gathering competitive intelligence. Armed with these brilliant insights, you can expertly refine how to build pivot table frameworks and drive phenomenal business growth.
Observing a blank pivot grid for the first time might feel akin to standing before an empty architectural blueprint, waiting for walls and pillars to define the space. By deliberately positioning distinct dimensions into their designated zones, analysts breathe life into dormant figures, transforming isolated data points into a synchronized chorus of actionable knowledge. This spatial choreography bridges the gap between raw metrics and executive decision-making, ensuring that every financial indicator or operational metric speaks with absolute clarity.
Mastering how to build pivot table transforms chaotic spreadsheets into vibrant stories of triumph and clarity. As professionals everywhere streamline their daily workflows by completing a quick neos log in to access vital data archives, your analytical journey begins to shine. Embrace this powerful technique today, watch complex numbers arrange themselves into brilliant insights, and unlock your true potential for data-driven success.
Functional responsibilities of spatial drop zones
Mastering the four primary quadrants requires a deep understanding of the unique role each zone plays in data processing. The filter zone acts as the ultimate gatekeeper, sitting proudly at the summit of the interface to isolate specific subsets of information without cluttering the primary viewing area. Beneath it, the column and row zones establish the fundamental axes of the report, dictating the horizontal flow and vertical hierarchy of categorical descriptors.
Finally, the value zone serves as the mathematical engine room, aggregating numbers through automated functions to deliver the core financial and operational totals.
Each quadrant demands precise inputs to prevent analytical distortion, operating much like specialized departments in a corporate hierarchy. Misplacing a numeric field into a descriptor zone halts proper calculation, while relegating a primary category to the value zone triggers unwanted data truncation. Respecting the boundaries of these functional zones guarantees that the underlying database engine computes summaries with mathematical integrity and unyielding precision.
Psychological impact of categorical orientation on executive consumption
Human cognition responds profoundly to the horizontal versus vertical presentation of business metrics, making the choice of row or column placement a subtle psychological art form. Placing primary categorical descriptors along the vertical row axis invites natural, top-to-bottom reading habits, which align perfectly with how stakeholders digest detailed financial statements and itemized performance logs. This linear descent allows reviewers to scan extensive lists of product categories, regional offices, or sales representatives without cognitive fatigue, building a comfortable baseline of familiarity.
Conversely, arraying major categories across the horizontal column axis shifts the executive mindset toward comparative analysis and temporal progression. Stakeholders scanning columns naturally evaluate performance side-by-side, such as comparing quarterly revenues or departmental expenditures in a single panoramic sweep. Strategic placement influences whether leadership focuses on deep granular investigation through vertical scrolling or broad comparative evaluation across horizontal spreads, tailoring the narrative impact of the data.
When presenting financial summaries to a board of directors, the structural layout dictates the immediate emotional and intellectual reception of the metrics. A vertically dominant layout instills confidence through exhaustive detail, while a horizontally balanced display encourages rapid cross-sectional evaluation and strategic decision-making.
Strategic deployment of spatial orientation follows specific cognitive patterns during executive reviews:
- Vertical row arrangements foster deep sequential analysis and meticulous auditing of individual operational units.
- Horizontal column layouts accelerate multi-variable comparisons, ideal for quarterly tracking and budget allocations.
- Balanced matrix placements reduce cognitive friction by preventing excessive horizontal scrolling while maintaining comparative breadth.
Procedural methodology for multi-dimensional layout stability
Executing complex data manipulations without triggering disruptive interface flickering requires a controlled, step-by-step approach to field dragging. Sudden layout shifts often occur when analysts attempt to reposition multiple large-scale dimensions simultaneously without locking the calculation canvas first. Adhering to a disciplined procedural sequence ensures that the rendering engine processes structural adjustments smoothly, maintaining visual stability throughout the transition.
Applying structured techniques minimizes computational lag and prevents the accidental misplacement of vital data fields during high-speed reporting tasks. The following sequential framework Artikels the exact protocol for shifting multiple dimensions:
- Temporarily disable the automatic update checkbox within the pivot table options menu to freeze background rendering computations.
- Click and hold the primary dimension header within the field list, dragging it securely into the target row quadrant before releasing.
- Select the secondary and tertiary descriptive fields in descending order of hierarchy, dropping them directly beneath the primary field without intermediate refreshing.
- Navigate back to the pivot table options menu and re-enable the automatic update feature to render the fully synchronized multi-dimensional layout in a single pass.
Strategic spatial arrangement transforms static spreadsheets into dynamic command centers, where every dropped field breathes intention into raw corporate data.
Automated calculation engine decision pathways
The underlying calculation engine operates on a sophisticated set of heuristic rules that evaluate the inherent data type of any field dropped into the workspace. When a text-based string or categorical descriptor enters the row or column zones, the system recognizes the non-numeric nature of the data and defaults to counting the frequency of occurrences. This automated classification ensures that textual attributes like customer names, product codes, or geographic regions are instantly quantified by volume or distinct instances.
On the other hand, dragging a numerical field into the value zone triggers a completely different computational pathway, shifting from mere counting to mathematical summation. The engine scans the data type, detects integer or decimal values, and automatically applies the SUM function to aggregate the total financial impact or operational output. This intelligent discernment removes the burden of manual formula writing, allowing analysts to trust that numbers sum while text categories count, all based entirely on spatial placement within the matrix.
Recognizing how the software interprets spatial inputs empowers analysts to bypass tedious manual overrides, trusting the automated architecture to handle baseline computations accurately. Whether processing millions of retail transactions or auditing global supply chain logistics, the engine consistently applies the correct mathematical operation driven solely by quadrant destination.
Translating raw tallies into meaningful business intelligence demands choosing the correct mathematical aggregation routine.
Transforming endless rows of transactional data into executive-ready intelligence requires moving beyond basic arithmetic. When analysts rely solely on default summation, critical business trends remain buried beneath inflated totals, masking underlying vulnerabilities and opportunities within the enterprise ecosystem.
Shifting the analytical lens from a standard sum operation to an average calculation fundamentally alters the perspective on operational performance, often exposing hidden anomalies that cumulative figures completely conceal. Consider a regional retail enterprise evaluating two distinct store locations over a busy fiscal quarter. Store Alpha generates a massive aggregate sales sum of one million dollars supported by fifty thousand individual transactions, while Store Beta records a modest aggregate sum of two hundred thousand dollars across just one thousand transactions.
A surface-level review favoring total sum metrics erroneously designates Store Alpha as the uncontested powerhouse of the organization. However, switching the mathematical aggregation routine to calculate the average order value reveals a starkly different narrative. Store Alpha operates with a meager average transaction value of twenty dollars, driven by high-volume, low-margin inventory that strains supply chain logistics and customer service bandwidth.
Mastering how to build pivot table transforms chaotic spreadsheets into vibrant landscapes of crystal-clear data insights. Just as businesses track vital personnel metrics via complyflow current employees to streamline workforce operations, you too can conquer information overload. Harness these dynamic organizational tools today to elevate your analytical journey and unlock brilliant new professional heights effortlessly.
Conversely, Store Beta boasts a robust average order value of two hundred dollars, signaling a highly lucrative boutique model with exceptional customer yield per interaction. This computational pivot exposes operational inefficiencies, resource misallocation, and margin leakage that would otherwise remain invisible. Operational leaders must recognize that raw volume frequently flatters poor efficiency, whereas averages illuminate the true operational heartbeat and unit economics of individual business units.
Comparative Analysis of Aggregation Methodologies
Selecting the appropriate mathematical function dictates how raw data translates into actionable corporate strategy, requiring a comprehensive understanding of diverse calculation mechanics.
| Methodology | Primary Mathematical Function | Operational Use Case | Analytical Risk or Blind Spot |
|---|---|---|---|
| Sum | Aggregates cumulative totals across filtered datasets. | Tracking total revenue, inventory volume, or absolute cost expenditures. | Masks performance disparities between high-volume and low-volume entities. |
| Average | Calculates the arithmetic mean by dividing sum by count. | Evaluating average order value, employee productivity, or mean time to resolution. | Highly susceptible to skewing from extreme outliers or skewed distributions. |
| Variance | Measures the dispersion of data points around the mean value. | Assessing financial risk, process quality control, and demand volatility. | Abstract statistical output requires careful interpretation by non-technical stakeholders. |
| Distinct Count | Tallies unique occurrences while ignoring duplicate entries. | Counting distinct purchasing customers, unique IP addresses, or active SKUs. | Fails to capture transaction frequency or total volume generated by specific keys. |
Procedures for Proportional Value Display
Contextualizing absolute figures within a broader financial framework requires shifting display settings from raw integers to relative proportions, illuminating the exact weight of each category. Executing this transformation demands precise navigation through the calculation interface to reconfigure the underlying presentation layer of the pivot table.
The step-by-step configuration sequence unfolds directly within the interface to recalibrate output metrics without altering source data:
- Locate the target value field currently positioned within the data quadrant of the pivot layout interface.
- Right-click the specific value header or click the designated field settings icon to open the configuration dialog box.
- Navigate to the tab labeled to show values as, which exposes a secondary dropdown menu containing advanced calculation options.
- Select the percentage of grand total parameter from the available options to automatically reindex every numerical entry.
- Apply the changes to instantly transform absolute tallies into proportional shares, revealing the precise fractional contribution of each row and column item to the overarching corporate metric.
To mathematically reconcile the distortion caused by uneven sample sizes, the analytical engine computes weighted averages by multiplying each data point by its corresponding weight, dividing the sum of those products by the sum of the weights, thereby ensuring that high-volume segments appropriately dictate the baseline trend while low-frequency anomalies are statistically neutralized.
Taming chaotic temporal variables requires grouping chronological records into manageable seasonal and fiscal blocks
Raw datasets often arrive as a chaotic flood of daily timestamps, concealing critical business trajectories beneath an overwhelming avalanche of granular details. Transforming this relentless daily noise into clear, actionable intelligence requires a deliberate structural shift, turning scattered calendar entries into clean, predictable blocks of time.
When analytical vision is clouded by thousands of individual transaction dates, strategic decision-making stalls. Establishing order within temporal data is not merely an organizational preference; it is an absolute operational necessity for uncovering the true rhythmic heartbeat of commercial performance.
Procedural Workflow For Chronological Summarization, How to build pivot table
Executing a seamless transition from granular daily transaction logs to polished monthly and quarterly reports involves a precise, multi-step navigational sequence within the data architecture. The mechanics of this workflow demand careful attention to the temporal boundaries governing the source grid.
Mastering this transformation requires a systematic execution of interface commands that anchor disorganized daily events into structured administrative periods.
- Verify that the primary date column within the source data table is formatted uniformly as a recognized date serial number rather than standard text strings.
- Right-click any individual date cell within the populated row field of the calculation canvas to summon the primary context menu.
- Select the grouping command to open the temporal categorization parameters dialogue window.
- Highlight both months and quarters simultaneously within the timeframe selection box while explicitly deselecting days and years to force an intermediate aggregation layer.
- Confirm the configuration parameters to instantly collapse thousands of individual daily entries into clean, high-level fiscal summaries.
Data integrity relies entirely on the underlying source timestamps remaining untouched while the viewing lens adapts dynamically to macro-level business cycles.
Fiscal Year Isolation Methods
Modern enterprises frequently operate on financial calendars that completely diverge from standard January-to-December Gregorian cycles, running instead on customized 12-month fiscal frameworks. Isolating specific financial periods without permanently altering or destructive editing of the underlying source database timestamps is a core competency for advanced analysts.
Creating custom fiscal windows requires leveraging calculated helper columns or advanced filtering matrices that map standard calendar dates directly to proprietary corporate accounting periods. By introducing a secondary calculated attribute driven by logical formulas, analysts can segregate corporate performance metrics cleanly.
For instance, a retail enterprise whose fiscal year commences in February can implement a conditional offset formula to reassign January sales to the tail end of the preceding fiscal cycle. This ensures that annual performance reports accurately reflect operational realities without corrupting the raw transaction ledger, maintaining absolute historical fidelity while delivering tailored executive reporting views.
Temporal Grouping Parameters Reference
The following structural matrix Artikels the multi-tiered architecture used to categorize raw transactional events across ascending chronological increments.
| Day Level | Week Level | Month Level | Year Level |
|---|---|---|---|
| YYYY-MM-DD | ISO Week Serial | Full Month Name | YYYY Fiscal |
| Granular Event | Operational Sprint | Financial Reporting | Strategic Planning |
| Maximum Noise | Tactical Review | Seasonal Trend | Macro Trajectory |
Visualizing Seasonal Spikes Through Chronological Field Arrangements
Unveiling the hidden rhythms of consumer demand requires arranging temporal fields across distinct spatial quadrants within the analysis grid to create a vivid visual tapestry of performance. Positioning the newly formed month and quarter fields into the column headers while placing product categories down the row axis transforms a static grid into an expressive thermal landscape.
Picture a dynamic matrix where the intersection of fourth-quarter columns and holiday merchandise rows lights up with intense numerical concentrations, immediately illustrating historical inventory surges. This spatial choreography allows stakeholders to instantly visualize seasonal velocity, turning abstract numerical tallies into a compelling narrative of peak commercial activity and operational triumph.
Filtering infinite data permutations down to actionable slices empowers stakeholders to isolate specific operational anomalies.: How To Build Pivot Table
Modern enterprise ecosystems generate tidal waves of transactional metrics, often obscuring critical performance indicators beneath layers of digital noise. When executive decision-makers face sprawling matrices that span millions of cells, the ability to isolate specific operational anomalies becomes the ultimate competitive differentiator. Harnessing targeted data reduction strategies shifts the organizational paradigm from passive observation to aggressive, precision-guided intervention.
Deploying page-level report filters acts as the ultimate governance mechanism for multi-departmental datasets, allowing analysts to partition enterprise-wide metrics into distinct, digestible viewing panes. At its core, the operational mechanic relies on establishing a global exclusion and inclusion boundary situated at the very top of the reporting hierarchy. When an analyst designates a specific departmental dimension—such as Global Supply Chain or Regional Retail Operations—as a page-level filter, the underlying calculation engine immediately recalculates the entire pivot cache.
It intercepts the data stream before it hits the visual canvas, effectively muting irrelevant records from memory allocation. This creates a secure sandbox where cross-functional stakeholders can examine localized performance without interference from external business units, ensuring that departmental KPIs remain untainted by broader corporate anomalies.
Execution procedures for multi-item constraint selection
Precision filtering frequently requires combining multiple variables within a single constraint category to capture complex operational realities without overwhelming the viewer. Maintaining clarity while selecting multiple disparate items demands a disciplined approach to user interface configuration and logical grouping.
- Navigate to the designated filter zone within the field mapping panel and activate the primary criteria dropdown menu.
- Locate and check the master control box designated to allow the selection of multiple items, ensuring the interface registers additive parameters rather than exclusive single-value toggles.
- Select the desired operational subdivisions sequentially, utilizing the search utility to rapidly pinpoint non-contiguous entries across massive categorical lists.
- Validate the collective selection by observing the dynamic update of the summary headers, confirming that all chosen parameters are visibly acknowledged within the filter status display.
Precision in data isolation transforms overwhelming organizational complexity into crystal-clear strategic visibility.
When underlying database schemas undergo restructuring, legacy filter criteria frequently become orphaned, leaving behind phantom constraints that skew analytical reporting. Systematically purging these disconnected remnants is essential for maintaining analytical integrity across enterprise dashboards.
- Audit the current pivot cache against the updated relational database schema to identify fields that return null values or missing reference errors.
- Execute a comprehensive refresh of the data connection string to flush out deprecated dimensional keys and synchronization lag.
- Manually detach orphaned fields from the report filter drop zones by dragging them completely outside the active calculation matrix boundaries.
- Re-map the newly updated database dimensions to the corresponding filter slots, verifying that incoming data streams align seamlessly with current operational taxonomies.
Picture a sprawling, high-definition executive dashboard glowing softly against the dark glass of a corner office monitor, initially teeming with over two million chaotic rows of global transactional data spanning every continent and operational vertical. With a single, deliberate click on the regional page filter, the chaotic sea of figures instantly collapses inward, shedding extraneous noise with the fluid grace of a digital accordion.
The massive, intimidating grid shrinks smoothly down to a hyper-targeted European subset, instantly isolating a minor logistical anomaly in a remote distribution hub. Vibrant conditional formatting highlights the localized variance in stark crimson against a clean white canvas, turning what was once an impenetrable wall of numbers into an immediate, unmistakable call to action for the regional director.
Polishing the visual presentation elevates an intimidating block of aggregated numbers into an executive ready briefing document.
Transforming raw analytical outputs into compelling executive briefings requires a delicate blend of deliberate design discipline and precise architectural refinement. When stakeholders glance at a financial dashboard or an operational summary, their initial psychological reaction dictates their entire engagement level with the data. A messy, unformatted matrix breeds confusion, whereas a meticulously styled canvas commands instant respect and drives swift, confident decision-making.
Mastering this final stage of data craftsmanship means stripping away visual noise and highlighting the core narrative hidden within the cells. By treating the layout as an editorial canvas, analysts can bridge the gap between complex algorithmic computations and human comprehension, ensuring that vital business intelligence shines through without obstruction or ambiguity.
Aesthetic Theory and Structural Clarity in Data Design
Applying professional color themes and removing distracting grid lines involves deep artistic principles rooted in cognitive psychology and visual hierarchy. When an analyst overlays a cohesive corporate color palette—such as muted navy blues paired with subtle gray accents—the human brain processes the information much faster than it would when facing a harsh, default spreadsheet grid. Grid lines often create cognitive fatigue by forcing the eyes to track countless unnecessary intersecting lines, effectively trapping the viewer’s attention in a microscopic cage rather than allowing them to see the macro-level business trends.
Eliminating those default structural borders opens up the whitespace, letting the data breathe and allowing strategic highlights, such as top-performing regional sales or critical cost overruns, to naturally step into the foreground. Color must never be applied merely for decoration; it serves as a semantic anchor that guides the executive eye along predetermined pathways of importance. Warm accent tones should be reserved exclusively for outliers or urgent performance metrics, while neutral tones maintain the structural integrity of the background matrix.
This intentional restraint turns an otherwise sterile database query into an engaging, executive-friendly narrative that respects the viewer’s time and cognitive bandwidth.
Design is not just what it looks like and feels like. Design is how it works to communicate truth clearly.
Nomenclature Customization and Header Optimization Strategies
Translating machine-generated default headers into human-readable display names is a critical step in bridging the gap between raw backend database architecture and boardroom vernacular. Automated systems typically output rigid, clinical field names such as Sum of Q1_Actuals_2023 or Row Labels, which immediately alienate non-technical stakeholders and disrupt the professional flow of a presentation. Analysts must actively override these automated labels by directly typing intuitive, industry-standard terminology into the field settings, transforming cryptic database jargon into clear executive language like Regional Revenue Q1 or Product Categories.
Beyond simply renaming fields for aesthetic appeal, maintaining data integrity requires avoiding duplicate header names that confuse the calculation engine. If two columns require the same visual title, inserting a subtle non-breaking space or appending a specific contextual modifier ensures the spreadsheet software functions smoothly while preserving the illusion of a clean, bespoke report. This careful attention to nomenclature elevates the document from a generic export into a polished corporate asset.
Structural Layout and Presentation Configuration Matrix
Configuring the structural layout requires precise alignment across multiple dimensional parameters to ensure optimal readability across both digital screens and physical printouts. The following comprehensive reference details the essential settings required to balance aesthetic appeal with functional data density in enterprise reporting environments.
| Layout Views | Banded Rows | Subtotals Positioning | Grand Total Alignments |
|---|---|---|---|
| Compact Form optimizes vertical screen real estate by nesting row fields hierarchically within a single column boundary. | Enabling alternating row shading introduces subtle contrast tints, guiding the eye smoothly across wide data horizons. | Placing subtotals at the top of each respective group keeps summary metrics immediately visible above detailed line items. | Displaying grand totals exclusively for both rows and columns at the outer edges anchors the entire analytical summary. |
| Artikel Form separates distinct field categories into individual vertical columns, providing a structured columnar architecture. | Disabling banded rows creates a clean, minimalist canvas ideal for minimalist PDF exports and formal printed executive briefs. | Positioning subtotals at the bottom of groups delivers a traditional accounting format favored by auditing departments. | Hiding grand totals entirely prevents analytical confusion when presenting intermediary departmental roll-ups or rolling forecasts. |
| Tabular Form mimics a traditional database table layout, allowing seamless integration with downstream reporting templates. | Customizing band colors with ultra-light corporate tints reinforces brand identity without overwhelming the numeric values. | Suppressing subtotals altogether streamlines complex multi-tiered hierarchies to emphasize strictly high-level regional totals. | Aligning grand totals with specific filtered data subsets ensures dynamic accuracy during interactive stakeholder presentations. |
Preparing extensive reports for physical distribution or formal PDF archiving demands rigorous page-setup configurations to maintain context across multi-page documents. When a summarized data table spans three or four physical pages, readers quickly lose track of what each column and row represents unless explicit structural anchors are enforced. Configuring the output engine to repeat specific row headers at the top of every single printed page ensures continuous comprehension, eliminating the frustrating need for executives to flip back and forth between pages to decipher metric labels.
Mastering how to build pivot table transforms chaotic spreadsheets into vibrant stories of clarity. As data illuminates every hidden path forward, professionals increasingly rely on advanced energy accounting software to illuminate consumption trends and drive sustainable growth. Harnessing these precise insights empowers your analytical journey, ensuring you can always build pivot table solutions that successfully decode complex numbers.
To achieve this seamless pagination, navigate to the page setup and sheet properties within the software interface, locate the row to repeat at top command, and designate the exact row coordinates containing the primary table headers. Coupled with setting the print scaling to fit precisely one page wide, this technique guarantees that whether the report is viewed on a high-resolution boardroom monitor or printed out on heavy cardstock for a physical meeting, the visual presentation remains impeccably consistent, authoritative, and ready for immediate executive action.
Synchronizing dynamic summaries with external data streams ensures your analytical models self heal as new transactions occur.

Source: easyclickacademy.com
In the fast-paced theatre of modern enterprise, static reports are rapidly becoming obsolete relics of a bygone era. When incoming data streams continuously feed your operational databases, your analytical models must possess the resilience to adapt without constant manual intervention. Imagine walking into a high-stakes quarterly review where every metric, trend line, and aggregate sum updates fluidly in real-time, reflecting the exact state of the business down to the second.
This operational nirvana is achieved by forging an unbreakable link between your dynamic summaries and the living, breathing data sources that power your organization. By establishing this live synchronization, you eliminate the friction of manual updates and build an analytical ecosystem that thrives on momentum rather than maintenance.
Behind every resilient reporting dashboard lies a robust technical architecture designed to handle the relentless influx of new information. To truly understand how these models self-heal, we must examine the foundational mechanics of expanding source ranges through named table references. When you convert a standard range of cells into a formalized data table, you fundamentally alter how the spreadsheet engine calculates memory allocation and boundary parameters.
Instead of referencing static coordinate anchors like A1 through Z500, a named table utilizes a flexible semantic structure that automatically stretches its boundaries downward and outward as rows and columns are appended. This architectural elasticity relies on an underlying XML-based table definition schema that registers every new record injected via external feeds, macros, or database queries. As new transactions stream into the bottom of the table, the calculation engine instantly registers the expanded row index, recalculating the pivot cache on-the-fly without requiring the analyst to redefine the source data range manually.
This seamless integration prevents broken links and ensures that downstream calculations remain mathematically sound, even during high-volume data ingestion cycles.
Troubleshooting protocol for handling sudden error codes
Even the most meticulously engineered models can occasionally stumble when unexpected structural changes occur upstream in the data pipeline. When a source column is abruptly deleted or renamed by another user, the reporting engine panics, casting ominous error codes like a cascading wave of red ink across your executive dashboard. To combat this vulnerability, analysts must deploy a systematic troubleshooting protocol that rapidly diagnoses the root cause of the structural fracture and restores data integrity before stakeholders notice the discrepancy.
The first line of defense involves isolating the exact field mapping failure within the pivot cache configuration interface. When a reference name vanishes from the underlying source table, the calculation engine flags the missing identifier as a null value, resulting in value errors throughout the aggregated matrix. You must immediately open the data source manager and inspect the table properties to verify that all column headers match the exact string criteria expected by your analytical model.
If a column was renamed, updating the field alias within the data source definition restores the broken handshake instantly. In scenarios where a critical data column was permanently deleted, the protocol requires you to temporarily substitute the missing vector with a placeholder array of zero values or historical averages to prevent complete model collapse. Following this remediation, you must re-map the dynamic range boundaries and execute a full memory purge of the pivot cache.
This rigorous troubleshooting sequence transforms a potential operational crisis into a minor maintenance event, ensuring uninterrupted analytical continuity.
When cached metric calculations stubbornly refuse to update following a massive influx of external data transactions, forcing a manual recalculation of the workbook memory becomes imperative. Utilizing specific keyboard commands allows power users to bypass the graphical user interface and command the processing core to re-evaluate the entire dependency tree instantly.
- Pressing Control, Alt, and F9 simultaneously forces a complete recalculation of all formulas across all open workbooks, thoroughly rebuilding the dependency tree from scratch.
- Utilizing Shift alongside F9 recalculates only the active worksheet, proving immensely useful when you need to refresh a single dashboard tab without consuming processing power on unrelated sheets.
- Executing the Control and F11 sequence inserts a brand-new macro sheet, which can sometimes jog a stuck background data connection back into an active synchronization state.
- Tapping the application-specific refresh command sequence clears the local pivot cache and pulls the absolute latest dataset directly from the external connection string.
Presenting stale aggregated figures to decision makers is not merely a technical oversight; it is an operational hazard that introduces catastrophic blind spots into strategic planning, potentially steering multi-million-dollar capital investments toward obsolete market assumptions.
Ultimate Conclusion

Source: excelinsider.com
Transforming complex, chaotic data repositories into polished, dynamic summaries is not merely a technical task, but an artistic triumph of modern analysis. By diligently cleaning your source tables, structuring your matrix quadrants thoughtfully, and maintaining synchronized external data streams, you build a resilient foundation for long-term strategic growth. Armed with these robust analytical frameworks, you are now fully equipped to conquer endless rows of information and turn every calculated metric into a stepping stone for future excellence.
