Mastering how to check duplicates in google sheets is an essential journey toward transforming chaotic spreadsheets into pristine landscapes of clarity and precision. In the fast-paced ecosystem of modern collaboration, data streams constantly converge, bringing along the inevitable clutter of redundant entries and accidental copy-paste errors that cloud our vision.
Every professional striving for absolute accuracy knows that unmanaged data eventually leads to miscalculations, flawed financial projections, and lost productivity. By taking deliberate control of your digital workspace today, you empower your team to unlock true operational efficiency, ensuring every single row tells an authentic and reliable story.
Uncovering hidden database clutter requires understanding why identical rows manifest during collaborative spreadsheet editing

Source: ctfassets.net
Hunting down repetitive spreadsheet entries manually can feel like searching for a needle in a digital haystack, yet clarity ultimately emerges. Transforming raw spreadsheets requires powerful tools, which is why exploring the demoboost.com insights data visualization product illuminates brilliant pathways toward crystal-clear analysis. Master this essential verification process today to ensure every single row shines with absolute accuracy.
Modern data ecosystems often resemble crowded digital hallways where multiple hands shape a shared canvas, inevitably leaving behind tangled layers of redundant information. When teams converge on cloud-hosted ledgers, the pursuit of organizational efficiency sometimes births the very chaos it aims to prevent, transforming pristine records into labyrinths of repeating entries. Navigating this landscape demands a profound look into the mechanics of collective data entry, tracing the trajectory from ancient ledger books to the seamless yet volatile world of cloud-based grids.
Every keystroke and paste action within a shared workspace contributes to a vast, invisible tapestry of interactions that reveal the habits of the collective workforce. Understanding the genesis of these overlapping data points requires examining the intersection of human behavior, technological evolution, and the subtle footprints left by concurrent collaborators navigating the same digital workspace.
Evolutionary Trajectory of Financial Record Management
The journey of maintaining financial and logistical records has undergone a monumental transformation over the centuries, transitioning from ink-stained physical pages to instantaneous cloud infrastructures. In the era of traditional manual bookkeeping, accountants relied on physical ledgers where every entry required deliberate physical effort, naturally curbing the temptation to duplicate records due to the sheer cost of time and physical space.
The introduction of early desktop software in the late twentieth century revolutionized this space, allowing rows to be copied and pasted across files with minimal friction, albeit still restricted by local file ownership barriers.
Today, cloud-hosted spreadsheet ecosystems empower global teams to edit the exact same document at the exact same second, multiplying productivity while exponentially increasing the risk of redundant information entries. This shift from isolated physical books to hyper-connected matrices means that database clutter is no longer just a clerical oversight, but a systemic byproduct of frictionless, multi-user collaboration.
Psychological Drivers Behind Shared Ledger Redundancy
Human psychology heavily influences how users interact with shared financial ledgers, often driving them to commit data duplication under the guise of security or urgency. When team members operate under high-stress deadlines, cognitive fatigue sets in, diminishing their ability to cross-reference existing rows and compelling them to paste raw data directly into the sheet just to ensure it is recorded somewhere.
This behavior is frequently rooted in a lack of trust in collaborative systems; individuals fear that their contributions might be accidentally overwritten by a peer, prompting them to create redundant local backups directly inside the master document.
Furthermore, the diffusion of responsibility in large teams creates a psychological safety net where contributors assume someone else will clean up messy inputs, ultimately leading to a proliferation of identical records. Recognizing these underlying behavioral patterns is essential for organizations seeking to implement effective data governance, moving beyond technical fixes to address the root causes of user-driven clutter.
Comparative Dynamics of Accidental Versus Intentional Data Redundancy
Inventory management sheets frequently bear the brunt of both careless errors and strategic redundancies, each leaving distinct signatures within the database architecture. Analyzing these contrasting phenomena helps administrators deploy targeted clean-up strategies tailored to the specific origin of the duplicated rows.
| Feature | Accidental Duplication | Intentional Data Redundancy |
|---|---|---|
| Primary Cause | User fatigue, overlapping sync events, and hasty paste shortcuts. | Deliberate offline backups, cross-departmental record-keeping, and audit trails. |
| Visual Pattern | Scattered identical rows with minor timestamp discrepancies across different sections. | Structured, grouped blocks of repeating entries mapped to specific regional categories. |
| Mitigation Strategy | Automated conditional formatting rules and script-based removal protocols. | Establishing centralized master databases with restricted write permissions. |
Digital Footprint Manifestations in Cloud Spreadsheets
When multiple contributors operate simultaneously within a cloud-hosted workspace, they generate a complex trail of metadata, version histories, and conflicting cell states that define the digital footprint of the document. Every synchronization event captures the exact nanosecond of a save action, yet concurrent edits often trigger synchronization bottlenecks where local caches merge awkwardly, spawning ghost rows that mirror existing entries.
Visual descriptors of this digital activity paint a picture of a bustling metropolis where traffic signals occasionally fail, causing vehicles to park in overlapping lanes.
The visual representation of this phenomenon manifests as a rapid cascade of revision history highlights, where user color-codes overlap on adjacent cells, indicating a flurry of competing inputs. To maintain structural integrity amidst this digital turbulence, administrators often rely on robust validation formulas to keep the data ecosystem clean and accountable.
=COUNTIF(A:A, A2)>1
Implementing strict verification formulas ensures that the invisible footprints left by simultaneous editors do not permanently degrade the analytical reliability of the foundational database.
Spotting repetitive data entries in your spreadsheet prevents costly errors with sharp clarity. As accurate records build the foundation of every successful venture, entrepreneurs frequently utilize free business plan software to streamline their operational strategies. Mastering conditional formatting rules illuminates identical values instantly, ensuring your database remains flawlessly organized and ready for strategic growth.
Utilizing native conditional formatting rules transforms repetitive visual data scanning into an immediate color-coded revelation.
Source: excelmojo.com
Picture a sprawling digital ledger where thousands of inventory items blur together into an exhausting sea of alphanumeric noise. Human eyes grow weary when forced to manually scan endless rows for accidental duplicates, missing the subtle human errors that inevitably creep into collaborative spreadsheets. Shifting from passive observation to active technological illumination changes everything, turning a tedious auditing chore into a striking visual experience.
Colors emerge dynamically from the grid, immediately drawing attention to overlapping entries before minor inventory discrepancies cascade into major operational failures.
Harnessing the built-in intelligence of modern spreadsheet architecture allows users to automate the detection of redundant data entries seamlessly. Instead of relying on manual oversight, specific mathematical conditions evaluate every single cell against the broader dataset in real time. This automated oversight acts as an ever-vigilant guardian for your data ecosystem, ensuring that unique records maintain their integrity while accidental clones are instantly flagged for review.
The underlying logic operates quietly in the background, translating complex data relationships into an intuitive, vibrant spectrum of hues that guide decision-makers straight to the heart of the problem.
Menu navigation sequences for custom formula implementation
Activating this visual transformation requires a precise series of navigation steps within the spreadsheet interface to bridge raw data with intelligent formatting logic. Executing these mechanical adjustments properly ensures that the calculation engine evaluates the correct ranges without throwing syntax errors or missing boundary conditions.
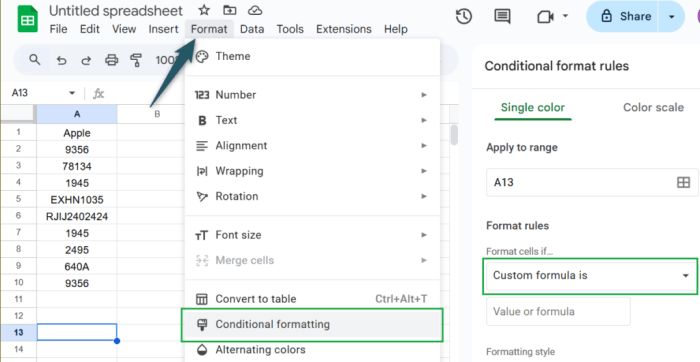
- Highlight the target data range by clicking the top-left cell of your inventory table, such as cell A2, and dragging downward to the final row of active data like A10001.
- Navigate to the top application menu bar and click on the Format tab to open the primary styling dropdown options.
- Select the Conditional formatting option located near the bottom of the dropdown menu to summon the configuration panel on the right side of the workspace.
- Locate the Format rules section within the side panel, click the drop-down menu currently displaying Single color, and scroll down to select Custom formula is.
- Enter the exact matching formula into the provided input box to begin evaluating duplicate values across the designated column range.
Executing these precise interface steps establishes the structural foundation for advanced data auditing. The custom formula acts as a logical filter, reading the dataset dynamically as team members update inventory counts across the globe.
=COUNTIF($A$2:$A$10001, A2) > 1
This specific formula evaluates the entire range, locking the absolute boundaries with dollar signs while letting the target reference adapt flexibly. Whenever the occurrence count of a specific cell value surpasses one, the formatting engine triggers the assigned visual style instantly.
Color palette hierarchy for frequency tier mapping
Structuring a multi-tiered color scheme brings profound clarity to chaotic datasets by categorizing duplicates based on how frequently they appear. Visualizing data density through a carefully curated palette helps inventory managers quickly distinguish between a harmless double entry and a systemic data duplication error.
| Visual Color Palette | Frequency Tier Description | Occurrence Range | Operational Risk Level |
|---|---|---|---|
| Soft Emerald Green | Unique Baseline Data | Exactly 1 occurrence | Zero Risk (Optimal) |
| Warm Amber Yellow | Standard Duplicate Match | 2 to 3 occurrences | Low to Moderate Risk |
| Vibrant Crimson Red | High-Density Overlap | 4 to 10 occurrences | Elevated System Risk |
| Deep Charcoal Grey | Critical System Clutter | 11+ occurrences | Critical Data Corruption |
Implementing this structured mapping approach turns raw numerical frequencies into an immediate, actionable dashboard. Stakeholders can assess the overall health of a massive inventory log in mere seconds without needing to write complex pivot tables or run external scripts.
Mastering how to check duplicates in google sheets transforms messy data into pristine clarity, much like organizing your finances while discovering unexpected cart voucher deals that elevate your shopping experience. Embracing this vital spreadsheet skill empowers you to conquer daily administrative hurdles with renewed professional confidence and absolute precision.
Performance optimization metrics across large scale inventory sheets
Scaling conditional formatting rules across ten thousand rows of active inventory metrics places a noticeable computational burden on browser-based spreadsheet engines. Every time a user modifies a cell, the calculation thread must re-evaluate the custom formulas across the entire specified range, which can introduce frustrating latency. Real-world retail operations managing massive stock logs often experience sluggish scrolling and delayed input responses if formatting rules are applied carelessly to entire columns rather than bounded ranges.
Limiting the evaluation scope strictly to active data boundaries prevents memory leaks and keeps the workspace operating at peak efficiency.
System administrators must also remain mindful of rule overlapping, as stacking multiple complex conditional formats on the same range multiplies the processing overhead exponentially. For instance, testing a multi-warehouse inventory file containing 10,000 SKUs with five overlapping custom formulas forces the calculation engine to perform 50,000 independent evaluations on every single edit. Balancing visual feedback needs with raw computational performance requires deliberate optimization, ensuring that sheets remain nimble enough to support rapid, collaborative data entry during peak operational hours.
Troubleshooting protocol for formatting rules failing on trailing spaces
Invisible characters like trailing spaces frequently sabotage conditional formatting rules, causing identical product codes to bypass detection entirely because one entry contains an unnoticeable blank space at the end. When automated matching logic compares SKU-100 to SKU-100 with a trailing whitespace, the strict evaluation engine registers them as completely different strings. Resolving this persistent data hygiene challenge requires integrating text-cleaning functions directly into the validation syntax to ensure absolute accuracy during comparisons.
Quickly spot repeated spreadsheet entries by highlighting data rows, then pivot toward securing global data privacy compliance via the robust syrenis cassie platform enterprise consent management solutions to protect vital customer trust. Once privacy standards are successfully locked down, return to your clean digital workspace to efficiently verify remaining records and ensure absolute accuracy across every column.
- Inspect suspect cells by enabling a strict character length check using the formula =LEN(A2) in an adjacent helper column to spot hidden padding.
- Modify the existing custom formatting rule by wrapping the cell reference inside the TRIM function to automatically strip away leading and trailing whitespace before evaluation.
- Update the core rule formula to incorporate the cleansing function directly within the conditional logic parameters.
=COUNTIF($A$2:$A$10001, TRIM(A2)) > 1
Applying this upgraded formula forces the spreadsheet engine to sanitize every data point on the fly before checking for duplicates. This proactive troubleshooting measure neutralizes human input errors, ensuring that invisible whitespace never compromises the integrity of your inventory audits.
Executing advanced filter criteria allows meticulous data stewards to isolate and extract redundant rows without altering original datasets.
Data integrity serves as the invisible backbone of successful modern enterprises, quietly dictating whether strategic decisions thrive or falter amidst digital noise. When collaborative teams simultaneously populate extensive spreadsheets, chaotic redundancies inevitably infiltrate the architecture, threatening the reliability of critical performance metrics. Moving beyond basic visual scans empowers administrative professionals to interact with large matrices of information surgically, ensuring that every duplicate record stands exposed without disturbing the pristine chronological history of the primary document.
Mastering precision data filtering requires a shift from destructive editing to non-invasive analytical observation, granting custodians the power to peel back layers of redundant information seamlessly. Imagine a bustling corporate financial department closing out a tumultuous fiscal quarter, where hundreds of parallel invoice submissions have accidentally bled into a master ledger. Instead of blindly deleting rows and risking the accidental eradication of vital transactional records, advanced filtering mechanics create a temporary digital lens that brings only the duplicated anomalies into sharp, isolated focus.
This sophisticated approach guarantees that the underlying database remains structurally intact while administrators surgically extract, review, or purge the exact friction points clogging up daily operational workflows.
Establishing custom filter views for non-destructive data isolation
Implementing targeted filter views acts as a protective shield for shared collaborative workspaces, allowing individual editors to slice through data chaos without disrupting the real-time viewing experience of colleagues. To deploy this methodology effectively, navigators must access the Data menu interface, select Filter views, and establish a brand-new customized parameter specifically mapped to the columns housing potential duplicate identifiers, such as transactional ID numbers or client email addresses.
By configuring these specific conditions to evaluate custom formulas based on COUNTIF logic, the spreadsheet instantly conceals all singular, non-repeating entries, presenting a streamlined, minimalist workspace populated exclusively by the offending duplicate clusters. This calculated isolation permits deep analytical inspection, allowing data stewards to verify whether matching rows represent legitimate dual-entry transactions or frustrating system-generated glitches, all while preserving the ambient operational ecosystem for everyone else sharing the file.
Understanding the operational boundaries between temporary analytical lenses and permanent structural modifications prevents catastrophic data loss during intense administrative audits. The following distinctions highlight why utilizing non-destructive methods safeguards organizational productivity across multi-user environments.
- Temporary filter views operate as an isolated user-specific overlay that hides unique or unselected rows without rearranging the underlying row indices, ensuring that active collaborative partners experience zero visual disruption or cell displacement.
- Permanent data sorting aggressively reorganizes the absolute physical sequence of the entire dataset based on ascending or descending parameters, frequently scrambling dependent formulas and disrupting parallel workflows across active team sheets.
- Filter views automatically save parameters to the cloud infrastructure without requiring manual reversion steps, whereas sorting actions demand immediate ‘Undo’ execution to prevent accidental saving of corrupted database states.
- Custom filter layouts can be named and assigned to specific recurring operational tasks, contrasting with standard sorting which overwrites the default view of the master document instantly upon application.
Organizations managing massive weekly administrative audits rely heavily on repeatable automation and pre-configured parameters to streamline repetitive oversight routines. Preserving a customized filter view involves locking in specific range boundaries and formula criteria within the view configuration panel, which automatically timestamps and stores the preference under the designated filter dropdown menu for instant future retrieval. Data custodians can instantly invoke this saved audit profile every Monday morning across monumental workbooks containing tens of thousands of rows, drastically cutting down the manual setup time traditionally required to hunt down overlapping data entries.
When dealing with sprawling multi-tab workbooks where mouse navigation across dozens of sheets drains valuable processing time, speed becomes an absolute operational necessity.
=IF(COUNTIF(A:A, A2)>1, “Duplicate Found”, “Unique”)
Expediting filter activation across colossal multi-tab spreadsheets demands absolute fluency in specialized keyboard architecture, turning sluggish manual point-and-click routines into instantaneous computational execution. For Windows operating systems, highlighting the active data matrix and triggering the shortcut sequence Ctrl + Alt + Shift + 2 instantly summons the filter creation engine, while Mac users achieve identical high-speed deployment via Cmd + Option + Shift + 2.
Once the framework is active, pressing Ctrl + Shift + V rapidly toggles between standard master displays and saved custom filter views, enabling data supervisors to cross-examine redundant data points across complex financial portfolios in mere fractions of a second without ever lifting their hands from the primary typing keys.
Deploying the unique function constructs a pristine secondary matrix populated exclusively by singular, non-repeating records.
Data clutter often creeps into collaborative spreadsheets like an invisible tide, turning organized sheets into chaotic landscapes of duplicated entries and fragmented information. When multiple team members simultaneously update inventories, financial ledgers, or customer relationship management lists, identical rows inevitably multiply across the digital workspace. This structural disarray demands an equally sophisticated remedy that goes beyond basic visual highlighting or manual deletions.
Enter the mathematical elegance of dynamic array formulas, specifically designed to sift through overwhelming volumes of repetitive text and numbers with surgical precision. Transforming a messy ledger into a streamlined, reliable source of truth no longer requires tedious manual sorting or destructive removal operations that risk permanent data loss.
At the heart of modern spreadsheet architecture lies a powerful mechanism capable of distilling raw, redundant inputs into an immaculate secondary matrix. By abandoning outdated destructive practices that permanently erase entries, data stewards now embrace a generative philosophy. This approach constructs entirely fresh, isolated views of pristine data while preserving the chaotic historical record untouched in its original location. Imagine watching a turbid stream of consciousness filter through a series of crystalline layers, eventually pooling into a serene, crystal-clear reservoir where every single droplet represents a singular, unique identity.
This transformation empowers analysts, project managers, and financial controllers to build dynamic dashboards that update in real time as fresh inputs arrive from the field, ensuring absolute integrity across every downstream calculation.
Syntax Mechanics Required for Nesting the Unique Function inside a Sorting Algorithm
Achieving peak efficiency in data management requires more than merely isolating singular entries; it demands structural order. Nesting formulas allows power users to combine multiple operations into a single, cohesive execution string, transforming raw information instantly into a polished, alphabetical or numerical hierarchy. The mechanics rely on wrapping the primary extraction tool within an ascending or descending ordering framework.
To construct this advanced sequence, the extraction logic must reside as the internal argument of the arrangement command. Visualizing this process involves picturing a funnel that first strains out all repetitive echoes before passing the purified stream through a mechanical grader that aligns every element by size or alphabetic weight. This nesting technique eliminates intermediary helper columns, keeping the spreadsheet lightweight and responsive even when processing thousands of enterprise-grade rows.
When executing this nested syntax, precision in referencing coordinate ranges dictates overall success. A minor syntax omission can trigger cascading calculation stalls across the entire sheet, making exact parameter placement vital for seamless automation.
=SORT(UNIQUE(A2:C100), 1, TRUE)
The formulation begins by harvesting distinct entries from the specified data array, ensuring zero redundancy in the intermediate virtual output. Immediately following this extraction, the sorting wrapper takes over, referencing the first column index and enforcing an ascending sequence configuration denoted by the boolean true parameter. For instance, a chaotic inventory log containing scattered product names automatically reorganizes into a neat, alphabetized catalog the exact millisecond a new item enters the primary intake table.
Contrasting Dynamic Extraction against Standard Data Removal Tools, How to check duplicates in google sheets
Choosing the right methodology for data sanitization defines the operational resilience of any analytical workflow. The following matrix illustrates the profound differences between modern generative extraction formulas and legacy destructive removal utilities.
| Operational Attribute | Legacy Removal Utilities | Dynamic Extraction Functions |
|---|---|---|
| Data Permanence | Destructive; permanently deletes original duplicate rows from the dataset. | Non-destructive; preserves raw input while generating a pristine secondary matrix. |
| Automation Level | Static; requires manual re-execution whenever source data updates. | Dynamic; automatically recalculates and updates instantly upon source modification. |
| Audit Trail Integrity | Poor; historical redundancy data is completely lost upon deletion. | Superior; maintains complete traceability between raw inputs and finalized outputs. |
Troubleshooting Scenarios for Handling Reference Errors Generated by Dynamic Array Spills
Dynamic arrays introduce a revolutionary capability where a single formula populates multiple adjacent cells automatically, but this power comes with strict spatial requirements. When the designated spill path encounters a physical obstruction, the calculation engine halts and displays an error notification. Understanding the root causes of these spatial collisions ensures rapid resolution without disrupting ongoing collaborative projects.
Before implementing corrective measures, reviewing the common spatial friction points helps maintain uninterrupted data pipelines across complex workbook architectures:
- Encountering structural blockages where pre-existing text, numbers, or formatting occupy cells directly below or beside the primary formula origin point.
- Attempting to spill results into merged cell configurations that disrupt the natural coordinate grid required by the calculation engine.
- Referencing external data ranges that fluctuate in dimension, causing intermittent boundary overruns during automated data imports.
- Failing to clear residual formatting remnants from previously deleted rows that trick the calculation engine into registering false obstructions.
Resolving these spatial calculation faults requires clearing all obstructed coordinates surrounding the formula origin cell. For example, if a financial dashboard throws a spill error because a stray total label sits three rows down, simply deleting that isolated text string allows the extraction formula to cascade downward freely. Establishing dedicated, unformatted output zones specifically designated for dynamic arrays prevents these spatial conflicts from occurring in collaborative multi-user environments.
Combining Extraction Logic with Transpose Parameters to Reorganize Horizontal Data Blocks
Data structures frequently arrive in unconventional orientations, requiring analysts to rotate vertical lists into horizontal layouts or vice versa to meet specific reporting templates. Merging extraction logic with spatial rotation tools creates a versatile pipeline capable of flipping matrix axes on demand. This capability proves indispensable when integrating spreadsheet outputs into presentation slides or external reporting systems that demand horizontal data distribution.
The structural integration involves enclosing the singular data harvester inside a rotational modifier. Picture a mechanical assembly line where vertical stacks of unique identification codes pass through a pivoting gate that lays them out horizontally across a row-based summary table. This automated pivot responds instantly to upstream additions, ensuring that rotating layouts never fall out of sync with raw data inputs.
=TRANSPOSE(UNIQUE(B2:B50))
Deploying this dual-action command forces the calculation engine to first isolate unique items from a vertical column and immediately pivot the resulting array ninety degrees across horizontal coordinates. Consider a regional sales tracking sheet where district managers submit vertical lists of participating retail outlets filled with repetitive entries. By applying this rotational extraction formula, corporate headquarters generates a clean, horizontal header row for executive summaries that updates automatically as new stores open their doors.
Leveraging custom Apps Script automation empowers power users to engineer bespoke notification routines for recurring data entry flaws.

Source: officewheel.com
Modern collaborative environments demand sophisticated approaches to data integrity beyond basic manual reviews or standard spreadsheet formulas. When multiple team members simultaneously update shared ledgers, identical entries inevitably creep into the system, threatening the reliability of underlying business metrics. Transforming reactive error correction into a proactive, automated surveillance system requires deploying tailored code solutions that monitor spreadsheet behavior continuously. Elevating data governance standards ensures that operational teams maintain pristine databases without sacrificing precious hours to tedious administrative maintenance routines.
Deploying programmatic oversight directly addresses the root causes of spreadsheet pollution by intercepting problematic inputs the exact moment a document opens. Establishing this level of background surveillance shifts organizational culture from chaotic cleanup efforts toward an environment of absolute data confidence and structural precision.
Architectural Design of Spreadsheet Automation Scripts
The structural foundation of a lightweight monitoring script relies upon event-driven programming hooks natively supported within cloud-based spreadsheet ecosystems. Specifically, the initialization sequence leverages a reserved trigger function that executes automatically whenever a user opens the workbook document. This architecture ensures that computational overhead remains negligible, activating only during the initial document handshake rather than constantly lagging active user edits.
The underlying logic targets designated column ranges, systematically reading data arrays into memory to evaluate row uniqueness efficiently.
Translating raw spreadsheet cells into manageable JavaScript arrays allows the script to compare strings rapidly, isolating repeated values without impacting the user interface experience. Once the evaluation logic identifies redundant entries, it compiles a structured record containing the exact timestamp and cell coordinates of the violation. This automated sweep acts as a vigilant sentinel, quietly preserving the structural integrity of collaborative assets while team members focus on core operational tasks.
Implementation of Automated Redundancy Logging Routines
Deploying specialized code requires precise syntax to ensure seamless interaction between the script execution environment and the underlying spreadsheet infrastructure. The following programmatic implementation demonstrates how to scan a designated column range, evaluate duplicate entries, and append audit data directly into a dedicated compliance ledger.
/
 * Scans a specific column upon opening and logs duplicate timestamps.
 */
function auditSheetDuplicates()
  var spreadsheet = SpreadsheetApp.getActiveSpreadsheet();
  var sourceSheet = spreadsheet.getSheetByName("Data");
  var auditSheet = spreadsheet.getSheetByName("AuditLog") || spreadsheet.insertSheet("AuditLog");

  // Define the target range for column A, starting from row 2
  var lastRow = sourceSheet.getLastRow();
  if (lastRow < 2) return;
  var range = sourceSheet.getRange(2, 1, lastRow - 1, 1);
  var values = range.getValues();

  var seen = ;
  var duplicates = [];
  var timestamp = new Date();

  for (var i = 0; i < values.length; i++)
    var val = values[i][0];
    if (val === "") continue;

    if (seen[val])
      duplicates.push([timestamp, "Row " + (i + 2), val]);
     else
      seen[val] = true;


  if (duplicates.length > 0)
    auditSheet.getRange(auditSheet.getLastRow() + 1, 1, duplicates.length, 3).setValues(duplicates);
Cloud Environment Authorization Protocols and Permissions
Executing custom macro routines within enterprise cloud environments necessitates navigating rigorous security frameworks designed to protect sensitive organizational assets. Before any automated script can access, read, or modify spreadsheet contents, the system enforces a strict OAuth consent workflow. Users executing the script for the first time must explicitly grant permissions, acknowledging the specific scopes requested by the application, such as viewing and managing spreadsheets.
Organizations often implement domain-wide administrative controls to regulate which scripts can interact with corporate data repositories. Understanding these authorization layers is vital for maintaining compliance and ensuring that background automation tools operate within authorized security boundaries without triggering false positives from cloud monitoring systems.
Enterprise Security Implications of Shared Macros
Sharing custom automation scripts across expansive corporate networks introduces complex security vectors that demand meticulous governance and oversight. Unrestricted macro sharing can inadvertently expose proprietary business logic or grant unauthorized personnel access to confidential audit logs if permission parameters are improperly configured. Establishing standardized deployment procedures ensures that only verified scripts with minimal necessary privileges circulate within workspace domains.
IT administrators typically enforce strict code reviews and centralized script repositories to mitigate vulnerabilities associated with decentralized macro creation. Balancing operational agility with robust enterprise security safeguards the organization against malicious script injection and accidental data leakage, preserving the trust of clients and stakeholders alike.
Integrating third-party add-ons expands the native spreadsheet ecosystem through specialized heuristic matching algorithms.
Source: excelmojo.com
Modern data management often demands tools that go beyond standard spreadsheet functionalities, especially when dealing with massive, sprawling datasets where duplicate entries quietly corrupt analytical integrity. When native formulas and basic conditional formatting reach their operational limits, external extensions step in to bridge the gap by deploying advanced computational logic. These specialized tools utilize heuristic matching algorithms capable of recognizing semantic similarities, phonetic variances, and subtle typos that standard exact-match formulas completely overlook.
Picture a bustling corporate environment where thousands of customer entries flood a shared ledger daily, transforming a structured database into an unmanageable labyrinth of repetitive records. Deploying external utility extensions acts as a master key, instantly scanning millions of data points to restore absolute clarity and structural harmony to the digital workspace.
The architecture of these external utilities relies on sophisticated fuzzy logic engines that calculate the statistical probability of data duplication based on adjustable sensitivity thresholds. By analyzing character sequences, structural patterns, and contextual metadata, these algorithmic solutions successfully identify records that share identical traits despite minor formatting discrepancies. For instance, distinguishing between variations like “Acme Corporation,” “Acme Corp,” and “Acme Corp.” requires computational capabilities far exceeding traditional spreadsheet capabilities.
Implementing these robust extensions allows data administrators to bypass manual verification entirely, letting automated heuristic scans handle the heavy lifting while teams focus on strategic analysis and high-value decision-making processes.
Security compliance standards of marketplace extensions versus internal script development
Evaluating the security posture of external tools versus custom-coded solutions requires a careful examination of data governance frameworks, regulatory adherence, and infrastructural vulnerabilities. Organizations handling sensitive financial ledgers or personally identifiable information must navigate a complex landscape of compliance mandates, including GDPR, HIPAA, and SOC 2 Type II certifications. Marketplace extensions undergo rigorous vetting by platform security teams before publication, ensuring they adhere to established API access protocols and data encryption standards at rest and in transit.
Conversely, internal script development grants organizations absolute sovereignty over their codebase, eliminating third-party data handlers but placing the entire burden of vulnerability management and security auditing directly onto internal IT personnel.
Deploying marketplace extensions involves trusting an external vendor’s infrastructure, which necessitates a thorough review of privacy policies, data retention schedules, and OAuth permission scopes requested during initial authorization. Internal script development, while offering tailored customization and isolated execution environments, often suffers from undocumented security flaws introduced by developers working under tight deadlines without formal security reviews. Enterprise environments frequently encounter realistic compliance challenges when employees bypass procurement protocols to install unverified marketplace utilities, inadvertently exposing confidential corporate data to external servers.
Establishing a balanced data governance model requires weighing the audited accountability of commercial extensions against the transparent, bespoke control inherent in internally engineered automation scripts.
Installation and permission-granting workflow for cloud-connected utility extensions
Acquiring and deploying cloud-connected extensions involves a standardized, highly regulated sequence of cryptographic handshakes and user-consent prompts designed to protect account integrity. Users initiate this journey through the integrated application marketplace, where selecting a desired utility triggers a structured authorization wizard managed by secure identity providers. The following sequential phases Artikel the operational milestones required to successfully integrate external tools into a cloud-based spreadsheet environment:
- Browsing the certified marketplace directory and selecting a verified duplicate management extension based on peer reviews, developer credibility, and documented compliance certifications.
- Initiating the installation sequence, which prompts the cloud platform to present a detailed permission request modal outlining the exact scopes of data access required by the extension.
- Reviewing the requested OAuth scopes to ensure the utility only accesses active spreadsheets and avoids overreaching into unrelated Google Drive directories or user profile data.
- Granting explicit user authorization, allowing the extension to inject its user interface components, background processing routines, and heuristic matching engines directly into the active document session.
User interface navigation strategies for locating hidden utility panels within the main application window
Once an external extension successfully integrates with the spreadsheet environment, locating its functional interface can sometimes present a slight navigational hurdle for unfamiliar users. Modern cloud applications typically tuck these specialized control panels away within contextual drop-down menus or sidebar drawers to maintain a clean, distraction-free workspace. Mastering the layout requires a systematic approach to UI exploration, ensuring operators can rapidly access matching controls without disrupting their analytical workflow.
The following structural elements illustrate the primary access points where external utilities manifest within the application window:
- The dedicated extensions menu located in the top horizontal application toolbar, serving as the master launchpad for all installed third-party add-ons and macro management tools.
- Collapsible sidebar panels that slide out from the right margin of the viewport, housing advanced parameter sliders, search filters, and real-time duplicate resolution dashboards.
- Contextual floating dialog windows that appear over the primary grid upon execution, designed to guide users through multi-step data cleansing wizards and review stages.
- Integrated toolbar icons nestled discreetly alongside native formatting options, offering instant one-click access to frequently utilized heuristic scanning shortcuts.
Visualizing the interface layout reveals a carefully orchestrated hierarchy where native tools and external extensions coexist harmoniously without overwhelming the user’s field of vision. Imagine a sleek, minimalist cockpit dashboard where primary flight controls remain prominent, while specialized diagnostic displays wait quietly along the periphery until summoned by the pilot. When an operator triggers a duplicate scanning utility, a slender control panel glides smoothly into view along the right border of the monitor screen, bathing the workspace in a clean, intuitive layout of toggle switches, progress bars, and color-coded action buttons.
This thoughtful spatial design ensures that complex computational algorithms remain entirely accessible without cluttering the pristine spreadsheet grid where the actual data resides.
Comparative evaluation of third-party extension metrics
Selecting the optimal third-party extension requires a methodical assessment of operational performance metrics, financial investments, usability factors, and data export flexibility. The following comparative matrix Artikels key performance indicators across prominent architectural approaches in the current marketplace:
| Add-on Processing Speed | Cost Structure | Interface Complexity | Export Capabilities |
|---|---|---|---|
| High-velocity multi-threaded scanning capable of processing 100,000 rows in under ten seconds. | Freemium model with advanced heuristic features locked behind a recurring enterprise subscription tier. | Moderate learning curve due to advanced parameter configuration panels and sensitivity sliders. | Comprehensive export options supporting CSV, Excel, and direct database synchronization connectors. |
| Moderate processing speed utilizing standard cloud API request loops for dataset analysis. | One-time lifetime license fee with limited ongoing update support and community forums. | Minimalist design featuring straightforward single-click scanning and basic output lists. | Restricted output functionality limited to internal sheet highlighting and row deletion protocols. |
| Enterprise-grade parallel processing optimized for massive big-data cloud warehouse integrations. | Custom consumption-based pricing tied directly to volume of records scanned per billing cycle. | High complexity requiring specialized administrator training and deep understanding of fuzzy logic rules. | Advanced automated synchronization linking cleaned datasets directly to external business intelligence platforms. |
Navigating the vast array of available extensions ultimately boils down to aligning technical capabilities with organizational priorities, resource availability, and data security mandates. When evaluating these tools, organizations must remember that efficiency should never compromise data integrity or regulatory compliance. Leveraging well-chosen extensions transforms the tedious chore of manual auditing into a streamlined, automated operation that safeguards the analytical accuracy of every record.
As collaborative data environments continue to expand in scale and complexity, mastering these advanced integration strategies remains an indispensable skill for modern data stewards and spreadsheet power users alike.
Implementing rigorous data validation parameters at the point of entry stops redundant entries before they contaminate collaborative ledgers.
Collaborative spreadsheets often transform into chaotic digital archives when multiple contributors input overlapping records simultaneously. Establishing preventative defenses at the exact moment of data creation fundamentally shifts organizational workflows from reactive cleanup to proactive data hygiene. By erecting functional boundaries directly inside input cells, teams cultivate an environment of absolute accuracy where mistakes find themselves intercepted before taking root in the ledger.
Deploying programmatic gatekeepers directly transforms raw input fields into intelligent checkpoints that actively evaluate incoming strokes against existing datasets. This proactive intervention relies on native spreadsheet logic to scan historical ranges instantly, rejecting compromised entries while simultaneously guiding the user toward correct formatting protocols.
Custom formula validation setup for identification numbers
Configuring a foolproof shield against duplicate identification numbers requires navigating directly to the designated input range settings and selecting the advanced rule parameters. Administrators must replace standard drop-down restrictions with a custom formula that evaluates the entire column dynamically to ensure absolute uniqueness before submission is permitted.
The implementation requires highlighting the target data entry cells, opening the data validation menu from the primary toolbar, and choosing the custom formula option from the criteria dropdown list. Entering a precise logical evaluation string prevents the system from accepting any repeating string values across the specified tracking column.
=COUNTIF(A:A, A1)=1
This exact formula counts the occurrences of the newly typed identifier within the entire column and compares it against the numerical threshold of one. If an entry attempts to breach this threshold by matching a preexisting sequence, the spreadsheet engine immediately halts the submission process and displays a corrective warning.
User feedback messages for correcting input behavior
Constructing an effective error management framework requires pairing technical validation rules with empathetic, highly descriptive guidance messaging. When a contributor triggers a rejection protocol, clear instructional prompts prevent frustration and steer the workflow back toward compliance without requiring direct intervention from senior data administrators.
- Custom rejection banners articulate precisely why the submission failed, reminding the operator that identification numbers must remain strictly exclusive across the master ledger.
- Inline instructional tooltips appear immediately upon selecting the data field, outlining the expected alphanumeric constraints and formatting criteria before typing begins.
- Dynamic visual highlight cues instantly flush the offending cell with a soft amber hue, signaling an immediate need for revision without disrupting surrounding operations.
Data validation mechanics during offline synchronization queues
Modern cloud-based spreadsheet environments frequently handle edits executed while users remain completely disconnected from active internet connectivity, creating unique reconciliation challenges. When local changes accumulate inside an offline browser cache, the validation engine temporarily defers its strict filtering protocols until re-establishment of the server connection occurs.
Upon reconnection, the synchronization queue processes offline modifications sequentially against the live master sheet containing the most current validation rules. If a locally typed duplicate manages to bypass offline restrictions due to the temporary disconnect, the background reconciliation protocol flags the discrepancy immediately, isolating the conflicting row for manual administrative resolution before permanent ledger integration.
Retrospective auditing methodologies for legacy spreadsheet environments
Applying modern structural integrity boundaries to historical archives demands a systematic auditing approach that cleanses accumulated clutter before enforcing new rules. Administrators must execute comprehensive diagnostic scans across legacy sheets to identify historical redundancies that would otherwise immediately trigger validation errors upon activation.
- Execute a preliminary sorting pass across historical identification columns to cluster identical records visually and verify the exact scale of historical data corruption.
- Deploy temporary helper columns utilizing conditional formatting highlight rules to isolate legacy duplication clusters spanning multiple archived tabs.
- Extract and archive redundant historical entries into a secondary audit ledger, leaving only pristine, singular records inside the primary active workspace.
- Apply the comprehensive custom validation formula across the newly sanitized historical range to lock down the legacy ledger against future duplicate contamination.
Ultimate Conclusion: How To Check Duplicates In Google Sheets

Source: bpwebs.com
Refining your spreadsheets is not merely a technical chore; it is an art form that elevates raw numbers into beacons of trustworthy insight. As you integrate these powerful detection methods and automation strategies into your daily routine, you pave the way for seamless collaboration, absolute confidence, and enduring organizational success.
