how to insert pivot table in excel unlocks a profound transformation, shifting our perspective from the chaos of endless data rows to the serene clarity of structured insight. Recent corporate efficiency reports highlight this exact mechanism as the primary catalyst for modern analytical breakthroughs, proving that mastering foundational spreadsheet architecture is no longer optional for forward-thinking professionals.
Stepping into this digital realm reveals a meticulously organized canvas where raw numerical matrices dissolve into vibrant, actionable intelligence. By executing precise mouse maneuvers and understanding the underlying mechanics of data summarization, practitioners can permanently alter how financial portfolios and operational metrics are perceived and evaluated across competitive industries.
Unlocking the hidden potential of raw spreadsheet matrices requires mastering the foundational steps of data summarization.

Source: exceldemy.com
Mastering how to insert pivot table in excel transforms chaotic data into crystal clear insights with just a few clicks. As professionals streamline their analytical workflows, exploring the renovatlygrowth.com pricing page unlocks advanced digital tools designed to elevate everyday productivity. Embracing this seamless data organization method ultimately empowers you to uncover hidden business trends and drive confident decisions.
Navigating the labyrinth of modern business intelligence often begins in the humble grid of a spreadsheet, where endless rows of alphanumeric characters stretch endlessly across the screen. Transforming this chaotic expanse into a coherent narrative is not merely a technical chore; it is an act of digital alchemy that brings clarity to confusion. Every data professional eventually faces the daunting challenge of making sense of thousands of unorganized entries without losing their sanity in the process.
Mastering how to insert pivot table in excel transforms chaotic data into crystal clear insights, much like upgrading your chaotic audio setup by exploring anything better than voicemeter for pristine sound control. Once your workflow reaches this brilliant level of clarity, knowing how to insert pivot table in excel empowers you to conquer any analytical challenge.
By learning the precise mechanics of data summarization, individuals can bridge the gap between raw, overwhelming data points and strategic, actionable insights that drive real-world decision-making.
Embarking on the journey to structure unorganized information requires a deliberate and precise sequence of physical interactions with your digital workspace. The process begins by selecting the target dataset, a foundational action that anchors your analysis. To achieve this, position your mouse cursor firmly over the top-left cell of your data range, which typically houses the primary header such as Date or Region.
Depress the left mouse button and, maintaining steady pressure, drag the cursor diagonally downward and across until every single populated cell, including all subsidiary columns and rows of numerical values, is fully encompassed within a glowing, highlighted boundary. Alternatively, for massive datasets spanning hundreds of thousands of entries, shortcut navigation streamlines this effort instantly. Once the entire data matrix is active and selected, guide your cursor upward to the ribbon menu spanning the top of the interface and execute a precise left-click on the Insert tab.
This action morphs the ribbon options, revealing a streamlined command deck where the primary data summarization tool resides prominently on the far left. A final, deliberate click on the PivotTable icon commands the software to instantiate the creation wizard, officially bridging the gap between raw data selection and dynamic, multidimensional reporting.
Interface Architecture and Structural Layout
Upon successfully executing the creation command, a floating dialogue window manifests over your primary workspace, presenting a clean, slate-gray canvas bordered by crisp lines. This utility window acts as the primary command center for your upcoming analysis, automatically detecting the previously highlighted cell range and populating the table reference field with absolute precision. Below this verification zone, the interface offers a choice regarding spatial placement, allowing creators to deploy their upcoming summary either within an existing worksheet or onto a brand-new, unblemished tab.
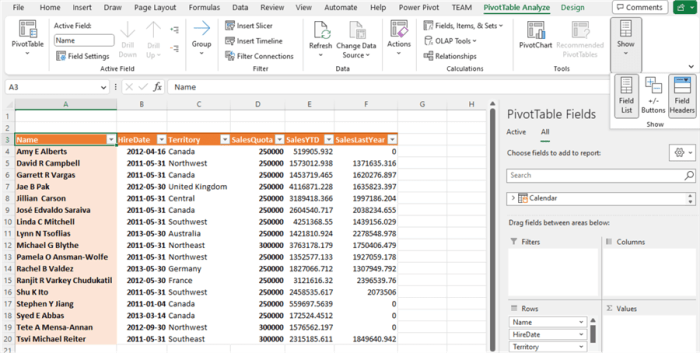
Dominating the right flank of this newly summoned environment is the field management dock, a vertically oriented panel divided cleanly into two distinct geographic zones. The upper tier displays a scrollable inventory of every column header pulled from your source data, rendered in clean, legible typography with tiny checkbox indicators beside each entry. Directly beneath this inventory lies the structural mapping territory, partitioned into four distinct quadrants labeled Filters, Columns, Rows, and Values.
This blank canvas functions as an interactive architectural blueprint, waiting for drag-and-drop maneuvers to dictate how raw numbers will be aggregated, categorized, and visually synthesized for executive review.
Mastering the spatial arrangement of data fields transforms chaotic spreadsheets into intuitive dashboards that communicate insights at a single glance.
Stepping away from endless rows of unstructured numbers provides a profound psychological release, alleviating the cognitive friction that routinely plagues analytical workflows. When confronted with unorganized ledgers containing millions of individual data points, the human brain experiences cognitive overload, struggling to parse trends or identify anomalies. Summarizing this data into structural matrix elements acts as a cognitive filter, shielding the mind from visual fatigue and replacing dread with a sense of absolute mastery.
As unstructured chaos gives way to clean, collapsible categories and neatly calculated sums, analysts experience a surge of confidence and creative momentum. This transition from passive observation to active structural design fundamentally alters how professionals perceive information, turning a once-dreaded audit into an empowering exercise in digital organization.
Mastering how to insert pivot table in excel transforms chaotic data into crystal-clear insights with just a few clicks. Much like deploying rater8 healthcare reputation management github open source to elevate patient trust and operational excellence, selecting your pristine dataset opens the door to powerful analytical breakthroughs. Embrace this seamless journey, click your way to success, and watch your reports truly shine.
Spreadsheet Version Selection Behavior Comparison
Different iterations of spreadsheet software handle the initial boundary detection and default range highlighting with varying degrees of algorithmic sophistication. Understanding these underlying variations prevents selection errors and ensures your summary engine captures every relevant data point without manual intervention.
| Spreadsheet Version | Contiguous Range Detection | Blank Row/Column Handling | Header Row Recognition |
|---|---|---|---|
| Legacy Desktop Suite 2010 | Stops at first completely blank row | Breaks selection continuity | Manual confirmation required |
| Modern Cloud Edition 365 | Dynamically spans entire data region | Bypasses minor internal gaps | Automatic intelligent detection |
| Open-Source Workspace 7.x | Auto-selects bordered data blocks | Halts execution upon obstruction | Prompted user verification |
| Enterprise Server Build 2021 | Expands using intelligent heuristics | Includes formatted tables natively | Strict top-row priority index |
Dragging fields into designated operational zones transforms blank grids into dynamic reporting dashboards.
Source: mssqltips.com
Stepping past the initial setup of an analytical workspace reveals the true engine of data manipulation. A blank matrix sits quietly on the screen, waiting for intent to shape its structure. As the cursor engages with the field list panel, every piece of raw information becomes a building block ready to be positioned.
Moving categories into specific operational zones dictates how information flows and aggregates across the sheet. The interface acts as a responsive canvas where structural decisions yield immediate visual results. Shifting a data point from obscurity to a primary analytical zone breathes life into stagnant rows and columns.
The Mechanics of Moving Categories into Filter Columns and Value Areas
The architecture of a pivot table relies on four distinct quadrants located within the field list pane: Filters, Columns, Rows, and Values. Mastering the flow of data requires deliberate placement of variables into these specific zones. When a categorical field, such as regional office locations, is dropped into the Filter area, the entire report gains a global perspective lens, allowing analysts to isolate specific subsets of data without altering the core layout.
Moving secondary categorical variables, like product lines, into the Column zone expands the horizontal narrative, spreading data points across a timeline or categorical spectrum to compare performance side by side. Meanwhile, the most critical phase involves routing numerical metrics, such as gross revenue or unit sales, straight into the Value area. The software automatically applies a mathematical aggregation—usually a sum or a count—turning individual transaction records into high-level summaries.
For instance, feeding a list of quarterly transactions into the value zone instantly calculates corporate-wide financial totals, shifting the analytical focus from granular detail to executive-ready intelligence.
Visual Feedback Provided by the Interface During Successful Docking
Interaction design within modern spreadsheet software relies heavily on immediate, intuitive feedback to guide user actions. As the mouse pointer drags a selected category across the workspace, the interface illuminates potential landing zones with subtle gray boundary Artikels. The moment a field successfully docks into a reporting quadrant, a crisp, darkened checkmark appears next to the field name in the master list, signaling that its data is actively contributing to the model.
Concurrently, the target quadrant highlights with a glowing border, and the grid itself experiences a microscopic flash of transformation. Cell dimensions adjust dynamically, and placeholder headers materialize instantly with bold typography. If a user attempts an illogical placement—such as dragging a text-heavy description field directly into the numerical calculation zone—the cursor shape modifies into a prohibition symbol, preventing structural corruption before it can occur.
This real-in-time visual dialogue ensures precision, transforming the mechanical act of clicking and dragging into a fluid, tactile experience of architectural design.
Navigating the initial learning curve often leads analysts to make predictable structural errors that distort analytical outcomes. Recognizing these common missteps prevents skewed reporting and ensures data integrity remains intact throughout the summarization process.
- Placing monetary figures or quantities into row headers instead of the value zone, which treats numbers as unaggregated text strings rather than calculable sums.
- Dropping unique identification numbers into the value area, causing the software to mistakenly sum up employee IDs or invoice numbers instead of counting occurrences.
- Overloading the filter zone with redundant categorical fields, creating an isolated reporting silo that hides critical trends from the primary matrix view.
- Failing to establish a clear hierarchy within the row zones, resulting in chaotic data nesting that obscures parent-child relationships between metrics.
Spatial Rearrangement of Operational Zones Altering Analytical Perspectives
A simple shift in geography across the operational quadrants alters the narrative told by the underlying metrics. Consider a retail dataset tracking annual sales across multiple store locations. When geographical regions occupy the row zone and product categories occupy the column zone, the report emphasizes regional dominance, highlighting which territories lead in overall volume. By dragging the region field out of the rows and dropping it into the filter zone, while elevating product categories to the primary row position, the entire analytical perspective pivots toward inventory performance.
The report now prioritizes merchandise analysis, revealing which specific items drive revenue across the enterprise as a whole. This spatial fluidity empowers decision-makers to interrogate the same underlying dataset from multiple angles within seconds, effectively rewriting the story of the business through simple drag-and-drop maneuvers.
Data is merely raw potential until spatial arrangement gives it a definitive voice and purpose.
Mathematical aggregations go far beyond basic addition when customized to answer complex business inquiries.: How To Insert Pivot Table In Excel
Stepping beyond the familiar boundaries of simple arithmetic changes how leaders interpret enterprise metrics. When raw data transforms into actionable intelligence, the underlying mathematics must accurately reflect the specific heartbeat of daily operations. Standard summation provides a helpful baseline, yet advanced analytics demand a deeper toolkit to decode market complexities.
Shifting the analytical perspective from cumulative totals to more nuanced statistical measures reveals hidden operational trends that would otherwise remain buried in massive data blocks. Modern enterprises rely on dynamic reporting matrices to navigate financial turbulence, making the mastery of custom calculations an essential competency for data-driven professionals.
Modifying foundational calculation parameters within reporting summaries
The default behavior of analytical matrices relies heavily on automated summation, which aggregates numerical entries by default. Recognizing when this standard approach obscures reality allows analysts to refine their reporting architecture. By navigating the primary configuration panel, users can seamlessly transition from cumulative totals to precise statistical evaluations such as arithmetic averages, distinct transaction counts, or population standard deviations.
Executing this transition requires interacting with the core summarizing interface, where a simple right-click opens the gateway to profound metric transformation. Selecting the summarization menu exposes a comprehensive array of alternative mathematical operations. For instance, shifting from total revenue to average order value immediately clarifies customer purchasing behavior without requiring manual data extraction or auxiliary formula columns.
Visualizing this adjustment involves observing a dense block of regional sales figures instantly recalibrate. Where a towering column of cumulative numbers once dominated the canvas, clean and balanced arithmetic averages emerge to highlight true performance benchmarks across different geographic territories. This immediate visual transformation signals to stakeholders that the reported figures account for varying transaction volumes rather than misleadingly rewarding larger sales teams simply due to higher activity frequency.
Unlocking advanced statistical calculations through value field settings
Beneath the surface of standard reporting menus lies a sophisticated control center that redefines the boundaries of spreadsheet analytics. Accessing the value field settings panel opens up specialized analytical tabs that transform standard data points into percentages of row totals, running totals, or comparative variance models. These built-in computational features eliminate the necessity for complex auxiliary formulas, streamlining the entire workflow.
Professional analysts frequently leverage the Show Values As tab to conduct horizontal and vertical benchmarking without altering the underlying database structure. By designating a specific baseline item—such as comparing each fiscal quarter against the preceding year—the reporting grid instantly populates with growth metrics and proportional distributions. This capability proves invaluable during executive briefings where leadership demands immediate context regarding market share shifts and operational expense variances.
Advanced analytical depth is achieved not by accumulating more data, but by applying precise mathematical frameworks to extract undeniable truths from existing figures.
The following structured matrix Artikels the primary mathematical functions available within the advanced configuration panel, detailing their operational mechanics and direct applications in corporate finance and operational management.
| Mathematical Function | Operational Calculation Method | Primary Business Use Case | Real-World Corporate Example |
|---|---|---|---|
| Average | Calculates the arithmetic mean by dividing the sum of values by the count. | Evaluating typical customer transaction sizes and baseline employee productivity. | Retail chains analyzing mean basket size per customer visit during holiday promotional campaigns. |
| Count | Tallies the total number of non-empty entries within a specified category. | Tracking operational activity volume, such as support tickets or order frequencies. | Logistics firms monitoring the daily volume of shipped packages across regional distribution hubs. |
| Standard Deviation | Measures the amount of variation or dispersion from the expected mean value. | Assessing financial volatility, risk exposure, and process manufacturing consistency. | Manufacturing plants evaluating defect rates across production batches to maintain quality control standards. |
| Index / % of Parent | Computes proportional contribution relative to specific row, column, or grand totals. | Executing detailed market basket analysis and departmental cost-center allocation. | Corporate finance teams breaking down regional office expenses as a percentage of total corporate overhead. |
Mathematical impact of incorporating custom formulas into summarized financial portfolios, How to insert pivot table in excel
Integrating tailored mathematical calculations directly into financial portfolios elevates spreadsheet modeling from static record-keeping to predictive business intelligence. When analysts introduce custom calculated fields—such as profit margin ratios derived from distinct revenue and cost streams—the resulting metrics maintain mathematical integrity even as underlying filters and pivot layouts shift dynamically.
The inclusion of weighted averages and variance models prevents skewed executive decisions caused by anomalous outliers in large datasets. For example, in corporate payroll analysis, relying solely on total departmental compensation can mask severe wage discrepancies, whereas incorporating median and standard deviation metrics provides governance committees with a realistic view of internal equity.
Strategic financial forecasting models utilized by multinational corporations depend heavily on these custom computational layers to simulate economic downturns and inflationary pressures. By embedding dynamic mathematical rules within the reporting framework, organizations establish a resilient analytical foundation capable of weathering complex market shifts and guiding executive strategy with absolute precision.
Filtering and slicing massive data assemblies enables rapid extraction of hyper-focused operational insights
Navigating through endless rows of corporate metrics often feels like searching for a solitary needle within a colossal digital haystack. Modern spreadsheet architecture provides sophisticated mechanisms to conquer this chaos, turning overwhelming ledgers into crystal-clear analytical landscapes. Professionals who harness these advanced filtering capabilities can dissect massive information networks instantaneously, separating peripheral noise from mission-critical business intelligence.
Deploying visual slicer buttons elevates static presentations into engaging, interactive experiences for stakeholders and leadership teams. When presenting complex financial forecasts or regional performance metrics during high-stakes board meetings, traditional dropdown menus often disrupt the natural flow of conversation. Slicers eliminate this friction by placing sleek, clickable graphic panels directly onto the worksheet canvas, allowing presenters to isolate specific departments, product lines, or geographic regions with a single click.
As the presenter selects a specific button, the underlying pivot table and associated charts instantly reconfigure in real time, painting a dynamic picture that adapts to the exact inquiries of the audience without forcing anyone to wade through irrelevant figures.
Establishing date hierarchies for temporal data grouping
Raw transactional entries often arrive in granular daily timestamps, creating an unwieldy continuum of information that obscures broader seasonal trends and yearly trajectories. Establishing chronological hierarchies bridges this gap by automatically clustering individual calendar days into cohesive monthly, quarterly, and yearly buckets within the pivot structure. This temporal consolidation empowers analysts to spot historical growth patterns, identify cyclical purchasing behaviors, and measure year-over-year performance with remarkable precision.
The process relies on grouping underlying date fields to synthesize thousands of isolated daily records into structured executive overviews, ensuring that strategic decisions are backed by comprehensive long-term perspectives rather than short-term anomalies.
Picture a chaotic regional sales ledger spanning three years, containing over one hundred thousand untamed rows of individual transactions, timestamped down to the exact second. The Chief Executive Officer walks into the boardroom requesting an immediate breakdown of fourth-quarter performance for the western territory, without any prior warning. Instead of embarking on a frantic, hours-long manual filtering and sorting expedition, the analyst selects the interactive dashboard.
By clicking the western region slicer button and expanding the newly established yearly date hierarchy to reveal the final quarter, the unruly spreadsheet transforms into a polished executive summary in mere seconds. The room shifts from anxious uncertainty to strategic clarity as the exact revenue figures materialize on the screen, proving the immense power of advanced data architecture.
Maintaining analytical integrity requires understanding the mechanical procedures involved in managing data connections, especially when transferring pivot structures between different workbooks or restructuring source databases. The following sequence Artikels the precise steps required for disconnecting and reconnecting filtering parameters within advanced reporting environments.
- Navigate to the pivot table analyze ribbon tab to locate the active data connections manager.
- Select the specific external data source linked to the workbook and initiate the unlinking protocol to sever the live connection.
- Verify that all dependent slicers and filters maintain their last cached state while operating independently of the primary database.
- Access the connection properties menu to re-establish the data pathway by pointing the system to the updated file path or server address.
- Refresh the entire pivot cache to synchronize the newly reconnected parameters with the latest incoming operational entries.
Precision in data filtration transforms overwhelming informational volume into immediate, actionable executive intelligence.
Maintaining synchronization between fluctuating source tables and final summary matrices prevents outdated reporting errors

Source: wikihow.com
In the fast-paced ecosystem of modern business intelligence, static data structures quickly decay into operational liabilities. When the foundational records of an enterprise ledger evolve, the corresponding analytical summaries must reflect those modifications instantly to preserve executive decision-making integrity. Neglecting this vital synchronization introduces critical vulnerabilities into financial forecasts, inventory tracking models, and resource allocation strategies, leading organizations to act on obsolete intelligence while believing they operate on current metrics.
Behind the scenes, Excel establishes a specialized memory architecture known as a data cache whenever a pivot table is initialized. This internal repository stores a compressed, flat-file duplicate of the original source range, separating the reporting interface from the active spreadsheet grid to accelerate computational performance. When modifications occur within the primary database—such as appended transaction logs or revised budgetary entries—the live grid updates independently while the isolated cache remains frozen in its historical state.
Re-establishing alignment requires flushing this memory buffer and forcing the application to re-read the primary ledger coordinates. During this procedural refresh, the calculation engine scans the designated data boundaries, rebuilds the internal index trees, and recalculates every aggregated sum, average, and count to mirror the current reality of the source array.
Automated Initialization Protocols and Structural Updates
Relying exclusively on human memory to execute manual updates leaves corporate reporting vulnerable to costly oversight and missed operational shifts. To eliminate this vulnerability, advanced workbook configurations allow analysts to program specific triggers that execute structural updates autonomously. Implementing these background operations ensures that analytical models remain perpetually current without demanding continuous manual intervention from the data steward.
Configuring the host document to synchronize upon launch involves altering the core properties embedded within the pivot table options menu. When a user enables the background refresh feature alongside the startup initialization command, the application immediately polls the designated data source the exact moment the file is unlocked. Imagine a multinational retail corporation opening its daily sales ledger across hundreds of regional terminals; as the primary file loads, background threads silently query the remote server, ingest the overnight transactions, and reconstruct the summary matrices before the executive team even views the opening dashboard.
Mastering how to insert pivot table in excel transforms messy data into crystal-clear insights. Picture this analytical precision applied to modern commerce, where setting up a dynamic web to print storefront streamlines creative operations seamlessly. Ultimately, unlocking these robust spreadsheet summaries empowers your workflow, turning complex numbers into powerful growth stories.
This seamless automation relies on specific operational parameters designed to optimize performance without freezing the user interface.
- Enabling the refresh-on-open property instructs the calculation engine to parse source updates during the document loading sequence.
- Activating background data retrieval allows the application to process heavy ledger re-indexing asynchronously while users interact with other worksheets.
- Disabling save-data-with-table-layout reduces overall file weight by stripping cached matrices, forcing a mandatory regeneration from live sources upon subsequent access.
- Setting timed background intervals compels the application to poll external SQL databases or connected cloud servers at predefined hourly markers.
Dynamic Named Ranges and Automated Row Expansion
Traditional data boundaries often restrict reporting flexibility because fixed cell references fail to capture newly appended records without manual intervention. Replacing static coordinates with dynamically expanding structures solves this limitation by establishing self-adjusting boundaries that scale automatically as operational ledgers grow. This mechanism relies on algorithmic formulas that calculate the precise dimensions of an active dataset, ensuring that every newly inserted row is captured seamlessly within the analytical matrix.
Envision a bustling logistics enterprise processing thousands of global shipping manifests daily, where supply chain analysts constantly append fresh delivery timestamps to the bottom of an ever-growing master ledger. By wrapping the primary data array in a smart table object or utilizing OFFSET and COUNTA formulas within the name manager, the designated source range automatically stretches downward to encompass every new entry.
When the reporting engine polls this elastic boundary, it effortlessly absorbs the freshly added rows into the existing memory cache, immediately populating regional performance boards and shipping duration summaries without requiring any manual adjustment of the underlying data source boundaries.
To construct an elastic data boundary using native formulas, define the range reference with the dynamic COUNTA function: =OFFSET(Sheet1!$A$1, 0, 0, COUNTA(Sheet1!$A:$A), COUNTA(Sheet1!$1:$1)).
The operational contrast between manual interventions and automated maintenance protocols dictates the overall resilience of corporate reporting infrastructure. Evaluating these distinct approaches helps organizations determine the ideal balance between system resource consumption and reporting accuracy.
| Operational Metric | Manual Refresh Triggers | Automated Background Updates | Impact on Reporting Integrity |
|---|---|---|---|
| Execution Timing | Dependent on user action and memory recall. | Executed continuously upon open or scheduled intervals. | Automation eliminates human delay and oversight. |
| System Resource Load | Zero background consumption until manually invoked. | Minor, managed overhead during active data polling. | Balanced efficiency with minimal disruption to workflow. |
| Error Vulnerability | High risk of distributing outdated or skewed metrics. | Low risk due to forced synchronization protocols. | Automatic updates safeguard executive decision-making. |
| Scalability | Becomes unsustainable as dataset volumes multiply. | Effortlessly handles high-frequency transactional inflows. | Essential for enterprise-grade business intelligence. |
Visualizing numerical summaries through integrated graphical representations bridges the gap between raw figures and stakeholder comprehension.

Source: medium.com
Transforming cold digits into vibrant visual narratives alters the entire trajectory of corporate decision-making. When rows and columns dissolve into dynamic graphical vistas, executive leadership stops translating spreadsheet jargon and starts absorbing immediate operational realities. This seamless transition from static calculations to living charts turns ordinary data reviews into compelling business milestones.
Pairing a dynamic summary grid with an interactive column chart begins right inside the core data architecture of the spreadsheet environment. Once the foundational summary engine is fully operational, select any active cell within that calculated grid to anchor the visualization process. Navigate directly to the primary menu ribbon, locate the dedicated graphical insertion tools, and choose the standard vertical column format.
Instantly, a floating canvas materializes across the screen, echoing every mathematical relationship currently active in the background. To establish the vital interactive bond, introduce dedicated slicing tools or categorical filter controls linked directly to the primary data source. As stakeholders click through specific regional segments or quarterly timelines, the companion column chart recalibrates its vertical pillars in real-time, instantly reflecting the filtered subset.
This active synchronization guarantees that the visual presentation remains structurally tethered to the underlying calculations, eliminating manual redraws and ensuring absolute fidelity during high-stakes presentations.
Aesthetic adjustments for executive briefings
Delivering impactful insights to the board requires a disciplined approach to graphical styling that prioritizes absolute clarity over ornamental distraction. Every visual element on the canvas must be meticulously calibrated so that high-level executives can extract critical trends within a three-second glance. Stripping away heavy background gridlines, standardizing font hierarchies, and employing a purposeful, high-contrast color palette ensures that crucial data series command immediate attention without visual fatigue.
Strategic formatting choices dictate whether an executive presentation inspires decisive action or causes frustrating confusion in the boardroom. The following design parameters must be enforced across all analytical displays:
- Eliminate default background shadows and three-dimensional bevel effects that distort true bar heights and obscure exact numerical values.
- Select a restrained, monochromatic color scheme for the primary data series, reserving a single, vibrant accent hue exclusively for highlighting top-performing metrics or outlier anomalies.
- Adjust the inner gap width between vertical columns to optimize visual density, ensuring bars appear neither too cramped nor excessively isolated across the plotting area.
- Position categorical axis labels horizontally to eliminate awkward neck-tilting and accelerate reading speeds for busy decision-makers.
Perceptual differences between tables and charts
Human cognition processes visual shapes and spatial lengths exponentially faster than rows of alphanumeric text. When stakeholders gaze upon structured tables, their brains engage in analytical decryption, systematically scanning numbers to calculate variance and identify peaks. Conversely, viewing a companion column chart triggers immediate pattern recognition, allowing the human mind to grasp proportionality, volume, and trajectory without conscious mathematical effort.
Tables excel at precision and exact record retrieval, whereas charts reign supreme in revealing the emotional and structural story hidden deep within the math.
Executive stakeholders routinely report that visual summaries reduce cognitive load during fast-paced strategic reviews. A classic corporate case study from a multinational retail enterprise demonstrated this psychological shift clearly during an annual earnings review. When executives viewed a massive cross-tabulated financial table detailing regional expenditures, consensus-building stalled for forty minutes as leaders debated individual cell figures. Upon replacing the table with an interactive, filtered column chart that highlighted regional variances, the executive board identified the primary cost overrun within ninety seconds and authorized corrective supply chain adjustments before the meeting concluded.
Checklist for dynamic label alignment with filtered parameters
Maintaining flawless synchronization between graphical text elements and actively filtered datasets prevents catastrophic miscommunication during live presentations. When data subsets shift dynamically, labels run the severe risk of displaying orphaned values or contradicting the visible graphical bars. Implementing a rigorous verification protocol guarantees total accuracy across every iterative view of the reporting dashboard.
A disciplined operational routine secures total reliability for all visible data callouts:
- Verify that all active chart data labels are permanently linked to the primary cell references rather than relying on static, manual text boxes.
- Test every connected slicer and filter category to ensure data labels dynamically update their numerical values without lagging or retaining cached historical figures.
- Confirm that chart axes automatically rescale their maximum boundary values immediately upon applying high-reduction filters, preventing compressed or visually misleading bar representations.
- Audit legend text strings to guarantee they accurately reflect current filtering criteria, ensuring zero ambiguity regarding which departmental subsets are currently displayed.
Visual accuracy is not merely an aesthetic preference; it is the ultimate foundation upon which executive trust and operational momentum are successfully built.
Concluding Remarks
Ultimately, bridging the gap between raw figures and stakeholder comprehension through advanced data structuring empowers every analyst to steer decision-making with absolute confidence. As dynamic matrices synchronize seamlessly with graphical representations, the journey from overwhelming spreadsheets to polished executive summaries proves that hidden potential is always waiting to be uncovered.
