how to sort alphabetically in excel is the definitive gateway to transforming chaotic digital ledgers into beautifully structured masterpieces of clarity. Behind every pristine grid lies a world of hidden potential, waiting for the simple touch of proper organization to reveal profound insights that drive business forward.
We live in a relentless sea of endless information, where missing a single misplaced record can trigger costly administrative errors and unravel meticulous planning. By mastering the fundamental mechanics of text arrangement within standard spreadsheets, professionals everywhere are reclaiming hours of lost productivity and steering their daily operations toward absolute precision.
Mastering alphabetical arrangement in electronic spreadsheets transforms chaotic data into structured masterpieces
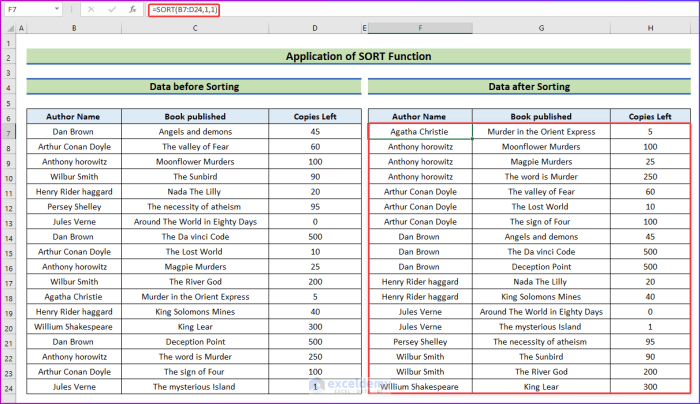
Source: exceldemy.com
Imagine staring at a sprawling digital canvas where thousands of unorganized names, product codes, and customer addresses bleed together into a dizzying wall of digital noise. In the fast-paced modern landscape of professional administration, raw data frequently arrives as an untamed wilderness, defying immediate comprehension and threatening operational efficiency. Elevating this disordered ledger into a harmonious, legible ecosystem requires more than mere housekeeping; it demands a strategic grasp of core organizational mechanics.
By implementing precise sorting methodologies within standard grid environments, professionals can instantly illuminate hidden patterns, turning frantic searching into seamless navigation.
At its core, rearranging text strings inside a spreadsheet grid relies on sophisticated underlying algorithms operating invisibly beneath the familiar rows and columns. When a user initiates an alphabetical sequence, the application evaluates the ASCII or Unicode values of individual characters from left to right, comparing the initial letters of each text string sequentially. If the first letters match, the system effortlessly cascades its evaluation down to the second, third, and subsequent characters until a definitive hierarchical position is established.
This deterministic process ensures absolute consistency, processing millions of data points in mere fractions of a second without altering the underlying data integrity.
Mastering how to sort alphabetically in Excel brings pristine order to chaotic data streams, much like how advanced recycling management software meticulously transforms scattered municipal waste into valuable renewable resources. Every single misplaced entry finds its proper designated place through this structured digital sorting journey, ultimately ensuring your ultimate spreadsheet transforms into a brilliant masterpiece of organizational clarity.
Foundational mechanics behind rearranging text strings within standard grid environments
The architecture of a modern spreadsheet grid is engineered to treat data arrays as cohesive relational blocks rather than isolated text entries. Understanding how these digital environments handle alphanumeric values prevents accidental data fragmentation, a common pitfall where names become disassociated from their corresponding financial figures. Visualizing the active workspace as a dynamic chessboard helps clarify this relationship, where moving a primary piece must inevitably carry its dependent attributes along the exact same trajectory to preserve context.
To safely execute this transformation without fracturing relational rows, specific operational parameters must be observed within the digital interface. The following structured sequence Artikels the precise technical actions required to align text strings accurately.
- Highlight the entire dataset range, ensuring all adjacent columns containing related numerical or categorical information are included within the selection boundary.
- Navigate to the primary data ribbon menu located at the top of the interface to locate the sorting and filtering command group.
- Designate the primary target column by selecting the specific header that holds the textual strings requiring alphabetical sequencing.
- Confirm the orientation settings to ensure the software processes the arrangement strictly from top to bottom along the vertical axis of the rows.
Executing these steps locks the relational integrity of the dataset, ensuring that every associated metric remains immutably anchored to its correct textual descriptor.
Data visibility enhancement through direct sorting mechanisms
Unlocking the full potential of a comprehensive dataset rarely necessitates the deployment of convoluted, nested algorithmic formulas that intimidate everyday users. Instead, simple structural adjustments radically amplify data visibility, casting a clear lens over otherwise obscure performance metrics and inventory logs. When information is arranged in predictable sequences, the human eye instantly detects anomalies, missing entries, or duplicate records that would otherwise remain hidden within a disordered mosaic of unstructured text.
Clear structural hierarchy directly reduces cognitive load, enabling decision-makers to extract vital insights at a single glance during high-pressure briefings. The accompanying breakdown highlights the distinct advantages of relying on native sorting tools over advanced computational workarounds.
- Native sorting operations execute instantaneously, requiring zero computational overhead compared to heavy array formulas that slow down workbook performance.
- Eliminating complex syntax dramatically reduces the learning curve for team members, fostering widespread digital literacy across departments.
- Built-in sorting features maintain strict data stability, preventing the volatile #VALUE! or #REF! errors frequently triggered by broken formula references.
Simplicity in data architecture is the ultimate sophistication, allowing reliable insights to emerge naturally from well-ordered rows and columns.
Practical administrative scenarios preventing costly operational errors
In high-stakes corporate environments, minor administrative oversights stemming from disorganized records routinely snowball into catastrophic financial losses and reputational damage. Consider a multinational logistics enterprise managing a massive inventory database of medical supplies destined for international distribution centers. If item descriptions and serial numbers remain jumbled alphabetically, a frantic warehouse dispatcher might misread a critical product code, leading to delayed shipments of life-saving therapeutics and incurring severe contractual penalties.
Real-world auditing cases frequently demonstrate that standardizing employee payroll directories through rigorous alphabetical sorting prevents duplicate disbursements and missed benefit allocations. For instance, a municipal human resources department overseeing thirty thousand civil servants once averted a six-figure clerical discrepancy simply by enforcing strict sorting protocols before cross-referencing tax withholding documents. Visualizing the spreadsheet as a finely tuned instrument of accountability highlights why meticulous text organization acts as an indispensable shield against costly administrative liabilities.
Mastering how to sort alphabetically in excel transforms chaotic data into a vibrant tapestry of pristine rows. Just as growing organizations demand clarity, exploring streamlinetechnology.io pricing enterprise plans unlocks powerful ways to elevate your operational efficiency. Embrace this seamless digital evolution, because knowing how to sort alphabetically in excel ultimately empowers your team to conquer everyday hurdles with renewed confidence and precision.
Selecting the appropriate data range prevents catastrophic misalignments during the sorting sequence
Stepping deeper into the architecture of spreadsheet management reveals a critical juncture where meticulous precision separates professional data stewardship from absolute digital disaster. Every single record in a database relies on a delicate harmony of interconnected attributes, from financial metrics to personal identifiers, existing in a synchronized horizontal row. Failing to respect the boundaries of this interconnected web during a routine reordering operation invites severe structural corruption that can silently sabotage months of rigorous analytical work.
Mastering how to sort alphabetically in excel brings brilliant clarity to chaotic data landscapes, much like how modern safety measures utilize kogniz contact tracing to protect bustling workplaces. Every neatly arranged row tells a story of triumph over disorder, empowering you to organize information seamlessly and illuminate your path toward absolute professional excellence.
Understanding the spatial mechanics of a spreadsheet grid ensures that sorting operations enhance clarity rather than destroying the foundational integrity of the information.
Highlighting only a single column instead of the entire dataset introduces profound operational risks that can permanently compromise the validity of a database. When a user isolates just one vertical slice of a table—such as a column containing employee names—and executes a sort command, the spreadsheet application blindly reorders those specific cells while leaving the adjacent columns completely untouched. This catastrophic action instantly fractures the relational integrity of the data.
Sales figures, employee identification numbers, and contact details that previously aligned with a specific person now point to entirely random individuals. In high-stakes corporate environments or scientific research databases, this silent data corruption frequently goes unnoticed until erroneous reports are generated, leading to flawed executive decisions, severe financial discrepancies, and irreversible loss of trust in the reported metrics.
Visual indicators confirming locked row relationships
Recognizing the visual cues that confirm whether adjacent rows remain safely locked to their corresponding values is an essential skill for anyone managing complex data structures. Experienced data analysts rely on distinct graphical checkpoints within the grid interface to verify that their selection boundaries are functioning correctly. Before committing to any reordering command, the user interface provides subtle yet unmistakable spatial feedback to indicate which cells are currently captured within the active boundary.
Observing the shaded perimeter of the active cell range reveals a continuous, unbroken Artikel encompassing every relevant column and row, signaling that the entire dataset is treated as a unified, cohesive block. Furthermore, scanning horizontally across the grid should display uniform row height markers and consistent gridlines that move in unison during preview phases, assuring the observer that no individual cells have been accidentally orphaned or left behind.
Visual harmony across the horizontal axis confirms that the relational bonds between disparate data points remain unbroken and secure.
To clearly illustrate the structural differences between safe practices and hazardous shortcuts, the following comparative framework details the mechanics of data selection:
| Selection Method | Structural Impact on Data | Risk Level |
|---|---|---|
| Full Dataset Boundary Capture | All horizontal attributes remain perfectly synchronized with their respective primary keys and companion metrics. | Zero risk of relational misalignment; preserves total data integrity. |
| Isolated Single Column Highlighting | Vertical cells reorder independently, severing horizontal ties and corrupting associated records. | Critical risk of permanent data corruption and mismatched information. |
| Partial Multi-Column Selection | Selected columns sort while unselected side columns remain static, creating fragmented database records. | High risk of partial data loss and untraceable analytical errors. |
Executing a safe and expansive boundary selection requires adherence to precise navigation protocols designed to capture every related data point without manual dragging errors. Standard desktop navigation shortcuts streamline this process while eliminating the human inaccuracies often associated with mouse dragging across massive digital sheets.
Implementing these standard desktop navigation procedures guarantees that the entire expanse of information is accurately enclosed within the operational boundary before any sequence modification takes place:
- Position the active cell selector inside the primary data table by clicking on the upper-leftmost data cell to establish the initial anchor point.
- Depress the combination of the Control key alongside the Asterisk key on the numeric keypad, or utilize Control plus the Shift key combined with the End key, to instantly expand the boundary across all contiguous populated cells.
- Inspect the outer perimeter of the highlighted region to confirm that all peripheral columns containing dependent variables and supplementary metrics are fully encapsulated within the glowing selection marquee.
- Verify the integrity of the selected area by checking the Name Box in the upper-left corner of the formula bar to ensure the entire expected coordinate range is displayed.
Precision in selection boundaries acts as the ultimate digital safeguard, ensuring that relational harmony triumphs over accidental data fragmentation.
Navigating the contextual ribbon menus unlocks advanced ordering parameters beyond simple ascending sequences.

Source: wikihow.com
When raw information demands precision, relying on quick toolbar toggles often falls dangerously short of true data organization. True mastery over electronic spreadsheets lies just beneath the surface of the primary workspace, waiting to be summoned through intentional interface navigation.
Stepping beyond basic single-column arrangements opens the door to sophisticated data management where complex relationships dictate the final visual layout. This journey requires looking past the surface level shortcuts and diving straight into the architectural engine room of the application.
Software Interface Pathway for Advanced Data Arrangement
Reaching the command center for sophisticated data manipulation demands a precise sequence of clicks across the application’s top navigation interface. Missing a single step keeps the user trapped in basic formatting limitations, so following an exact physical pathway through the software environment remains essential.
Begin by scanning the upper horizontal toolbar and locating the Data tab, which serves as the primary gateway for all structural transformations. Clicking this tab immediately shifts the ribbon display, revealing a specialized collection of tools dedicated strictly to sorting and filtering. Within this expanded panel, direct your visual focus toward the middle section labeled Sort and Filter, where a prominently displayed icon featuring large letters alongside upward and downward arrows awaits your command.
Clicking this specific Sort button instantly bypasses automatic assumptions and launches the advanced custom sorting dialogue window right in the center of your screen.
Visual Contrast Between Standard Toolbar Shortcuts and Deep Menu Configurations
The visual landscape of the spreadsheet application changes dramatically depending on whether you choose rapid surface-level shortcuts or deep menu architecture. Recognizing these distinct aesthetic and functional environments helps bridge the gap between casual data entry and expert spreadsheet engineering.
Standard toolbar shortcuts present themselves as minimalist, single-purpose glyphs—often just a pair of stacked letters like A-Z with an accompanying directional arrow. These icons are designed for immediate, impulsive clicks, offering zero visual feedback regarding how the background data is being interpreted before the change occurs. Conversely, the deep menu configuration manifests as a robust, floating dialogue window layered with drop-down menus, checkboxes, and interactive buttons.
This modal window occupies the focal point of the user’s vision, effectively dimming the background data grid to demand undivided attention for structural parameters. While the toolbar shortcut operates like a blunt instrument meant for instant gratification, the custom sorting dialogue functions like an architectural blueprint, displaying every active rule, hierarchy level, and directional condition simultaneously in a clean, tabular interface.
Available Parameters Within the Primary Sorting Panel
Unlocking the custom dialogue box exposes a comprehensive suite of control parameters designed to handle even the most chaotic datasets with absolute surgical precision. Familiarizing yourself with every operational dropdown within this control center ensures zero errors when structuring critical professional records.
- The Sort By dropdown establishes the primary column target that will dictate the initial phase of the data reorganization process.
- The Sort On parameter determines whether the sorting mechanism evaluates cell values, conditional formatting color, font color, or custom cell icons.
- The Order selection dictates the directional trajectory, allowing a transition from alphabetical ascending to descending, or the application of a bespoke custom list.
- The Add Level command expands the structural hierarchy, introducing subsequent secondary and tertiary sorting criteria for overlapping data categories.
- The Delete Level tool immediately removes redundant or obsolete sorting layers to keep the organizational logic streamlined and efficient.
- The Copy Level function duplicates an established sorting rule instantly, saving valuable time when configuring similar multi-tiered parameters.
- The Options button opens a secondary sub-menu that governs case sensitivity and determines whether sorting occurs vertically by rows or horizontally by columns.
Configuration of a Multi Layered Sorting Hierarchy for Complex Datasets
Real-world datasets rarely rely on a single category of information, making multi-layered hierarchies an absolute necessity for accurate analysis. Imagine managing a massive inventory database for a global retail enterprise containing thousands of regional sales records that demand rigorous, multi-tiered structural sorting.
To establish this complex order, open the custom sorting dialogue window and select the primary column representing the sales region in the first dropdown menu. Next, click the Add Level button to introduce a secondary tier, then configure this new layer to sort by product category alphabetically. Finally, add a third level targeting numerical sales figures from largest to smallest to rank performance within those specific categories.
When this three-tier command is executed, the software systematically groups all identical regions together, alphabetizes the respective product lines within each region, and orders the individual sales figures flawlessly from top to bottom. This systematic structuring transforms an unmanageable wall of numbers into a clear, readable narrative that drives executive decision-making with absolute confidence.
Precision in spreadsheet architecture transforms raw, unstructured input into reliable intelligence through the strict execution of multi-tiered logical parameters.
Handling stubborn numbers formatted as text requires preemptive formatting adjustments before initiating the sequence.

Source: flap.tv
In the intricate landscape of digital data management, encountering anomalies during a sorting process can disrupt an otherwise seamless workflow. Electronic spreadsheets rely heavily on strict typecasting to organize rows and columns effectively, making the coexistence of text and numerical digits a notorious trigger for structural chaos. When a database refuses to yield to standard alphabetical arrangement, the root cause often traces back to hidden data type discrepancies that defy immediate visual inspection.
Addressing these rebellious entries is a vital operational step that elevates a rudimentary spreadsheet into a polished, professional asset.
Understanding the underlying mechanics of spreadsheet sorting engines clarifies why numbers disguised as text cause such unpredictable ordering outcomes. Computers evaluate data types based on internal binary representations rather than human perception. When a numerical digit is stored as a text string, the software prioritizes its alphabetical sorting value over its mathematical value. Consequently, a string beginning with the digit ‘1’ will always sort before a string beginning with ‘2’, but a multi-digit number evaluates character by character rather than by its aggregate magnitude.
This behavior forces values like ’10’ to position immediately after ‘1’, disrupting the expected numerical progression of ‘1, 2, 3… 10’. Recognizing this fundamental operational rule prevents endless frustration and ensures that database arrangements remain logically sound.
Visual indicators and error identification
Detecting hidden formatting errors quickly relies on specific visual cues embedded directly within the spreadsheet interface. A meticulous visual inspection of the grid reveals subtle markers designed to alert operators of potential data anomalies.
Observing the active workspace closely unveils a distinct graphical warning sign in the upper-left corner of affected cells. This particular visual cue serves as an immediate diagnostic tool for data analysts.
- The micro-sized green triangle anchors itself firmly in the top-left angle of the cell boundary.
- Hovering the mouse pointer over this emerald marker triggers a floating warning icon accompanied by a contextual tooltip.
- The alert explicitly states that the number inside the cell is stored as text, differentiating it from adjacent authentic numeric entries.
- Unmarked cells containing text-digits often blend seamlessly into the background, requiring active formula-based auditing to uncover.
Methodical conversion of stored text to numerical values
Transforming rebellious text-based digits into genuine numerical values requires a deliberate, step-by-step execution to restore order to the sorting algorithm. Neglecting this crucial preparation phase almost invariably results in corrupted datasets and misaligned reports. Applying precise conversion techniques permanently corrects the underlying data type, empowering the spreadsheet engine to execute flawless chronological or numerical sequences.
Executing these targeted remediation steps guarantees that the spreadsheet interprets every digit according to its true mathematical weight rather than its character sequence. Precision during this phase safeguards the integrity of subsequent data manipulations and reporting functions.
- Highlight the entire range of cells exhibiting sorting irregularities by clicking and dragging across the targeted columns.
- Locate the floating yellow error icon that appears adjacent to the selected range and click the drop-down arrow to open the contextual menu.
- Select the command that explicitly directs the software to convert the selected text entries into true numbers.
- Alternatively, utilize the paste special multiplication method by typing the number one into an empty cell, copying it, and multiplying the targeted text-number range via paste special operations.
Troubleshooting persistent entries, How to sort alphabetically in excel
Certain stubborn dataset entries defy standard conversion protocols due to invisible formatting corruptions, such as trailing spaces, non-printable ASCII characters, or imported web artifacts. Resolving these deeply entrenched anomalies demands an advanced troubleshooting protocol that strips away invisible data layers before attempting another arrangement sequence.
When routine menu commands fail to alter the rebellious nature of corrupted cells, deploying targeted formulas provides an absolute remedy for cleansing the dataset. Implementing systematic text-cleaning functions forces the electronic canvas to purge extraneous characters and rebuild the cell contents from the ground up.
Employing the value function combined with the trim function, formatted as =VALUE(TRIM(CLEAN(A2))), successfully strips out all non-printable characters and trailing spaces while forcefully casting the stubborn string into a true, sortable number.
Executing this specialized formula across an auxiliary column instantly normalizes unruly records, allowing the newly generated clean data to be copied and pasted as permanent values over the original corrupted entries. Once this purification cycle is complete, the entire dataset responds predictably to sorting commands, flowing smoothly from top to bottom without unexpected interruptions or misplaced rows.
Automating repetitive data organization routines saves countless hours for professionals managing daily ledger updates.

Source: kajabi-cdn.com
Every single morning across financial hubs and logistics centers, thousands of dedicated professionals face the exact same digital mountain: rows upon rows of unorganized ledger entries demanding meticulous attention before the morning briefing. Staring at an endless grid of chaotic figures drains vital creative energy that could otherwise drive business growth and strategic planning. Transforming this tedious ritual into a seamless background operation requires harnessing the power of automation through customized recording tools embedded right inside the spreadsheet environment.
Reclaiming lost hours is no longer an impossible dream reserved for software engineers, but a practical reality waiting to be unlocked by everyday spreadsheet users.
Implementing hands-free data organization changes the psychological landscape of the modern workplace, replacing mounting daily frustration with an empowering sense of technological mastery. When complex arrangement sequences execute automatically in milliseconds, data custodians experience a profound shift from manual laborers of information to high-level architects of business intelligence. This newfound efficiency eliminates human error entirely, ensuring that every financial statement, inventory sheet, and operational roster adheres strictly to organizational compliance standards without fatigue creeping into the workflow.
Embracing this level of digital empowerment establishes a resilient foundation for sustainable productivity growth across entire corporate departments.
Recording Macros for Sequential Data Sorting
Capturing keystrokes and mouse movements into a reusable script transforms multi-step sorting protocols into an instantaneous, one-touch operation that executes flawlessly every single time. Before initiating the recording process, planning the exact sequence of actions prevents recording unnecessary clicks or corrective maneuvers that could clutter the underlying code. Activating the developer tab opens the gateway to the recording interface, where assigning a memorable keyboard shortcut links the automated routine directly to the fingertips of the user.
Executing the manual sort while the recorder actively captures every step ensures the script mirrors the exact analytical requirements of the business. Once the sorting criteria are successfully applied across the designated data range, stopping the recorder seals the routine into a persistent program module. Visualizing this process is akin to having a tireless digital assistant standing by, observing your exact workflow once, and then replicating your precise movements at lightning speed forever after.
A conceptual blueprint maps out this macro workflow from start to finish, providing a clear structural roadmap for implementation:
| Workflow Stage | Primary Action | System Response | Verification Metric |
|---|---|---|---|
| Initialization | Enable Developer Tab and click Record Macro. | A dialog box prompts for a macro name and shortcut key. | Status bar indicates macro recording is currently active. |
| Execution | Select data range and apply multi-level sort criteria. | Rows rearrange instantly according to specified parameters. | Data headers align correctly with sorted rows below. |
| Finalization | Stop the recording process via the developer controls. | Visual Basic code compiles the recorded actions. | Macro appears in the macro manager directory ready for deployment. |
| Deployment | Press assigned shortcut keys during daily ledger updates. | Routine runs background sorting in milliseconds. | Ledger updates complete without manual intervention. |
Security Considerations and Trust Settings for Automated Scripts
Deploying automated scripts introduces critical security variables that every organization must carefully manage to prevent malicious code injection and data corruption within sensitive financial repositories. Spreadsheet applications treat unverified macros as potential security vulnerabilities, automatically locking down execution capabilities until explicit trust is established by the administrator or end user. Navigating the trust center requires a balanced approach that maintains robust defense mechanisms while allowing legitimate productivity tools to operate unhindered.
Configuring secure execution environments involves designating specific network directories as trusted locations, ensuring only authorized scripts originating from approved internal sources run automatically. Understanding how macro security levels impact daily operations helps organizations prevent catastrophic data breaches while empowering staff to utilize automation safely.
- Disabling all macros without notification provides maximum security but completely halts workflow efficiency.
- Enabling digitally signed macros ensures that only code verified from a known publisher executes safely.
- Setting up a designated trusted folder allows internal scripts to run freely while isolating external downloads.
- Requiring notification for all other macros keeps the user fully aware of unauthorized script attempts.
Digital safety is not merely about locking doors, but about building intelligent pathways where trusted automation can thrive without compromising structural integrity.
Maintaining Macro Integrity Across Evolving Column Structures
Business landscapes shift constantly, and spreadsheet architectures inevitably evolve as new metrics, departments, and compliance requirements demand additional columns within existing ledgers. Hardcoded script references to rigid cell coordinates often break when a new column is inserted, causing automation routines to fail or sort incorrect data sets entirely. Preserving script longevity requires adopting dynamic programming practices that identify data ranges by headers rather than static grid coordinates.
Integrating robust structural adaptability ensures that even when rows expand or columns shift positions, the automated sorting routine dynamically adjusts its parameters to match the current layout. Best practices for long-term script maintenance include utilizing named ranges and writing adaptive loops that scan for header names dynamically before executing the sort sequence. This proactive maintenance strategy guarantees that your automation investment remains resilient, reliable, and immune to the inevitable structural evolution of modern business ledgers.
Preserving header integrity guarantees that title rows never accidentally sink into the middle of sorted datasets.
Picture the digital workspace as a pristine library archive where every ledger and log rests in its designated place until a rogue sorting command unleashes chaos. When column titles like Product Name or Revenue collapse into the depths of a spreadsheet, the resulting confusion can derail entire quarterly reports. Maintaining the sanctity of the top row is not merely a cosmetic preference; it is an absolute operational necessity for safeguarding the structural integrity of complex analytical models.
Professional spreadsheet architecture relies heavily on distinct boundaries between metadata and raw metrics. Without proper administrative safeguards, automated sorting routines view every single row as an identical participant in the arrangement sequence. This mechanical blindness treats descriptive titles as regular data points, leading to alphabetical anomalies where words like ‘Category’ end up lodged securely between ‘Banana’ and ‘Cherry’. Understanding the underlying mechanics of spreadsheet organization prevents these structural collapses and ensures professional deliverables remain immaculate.
Operational Mechanics of Data Range Recognition
The software sorting engine evaluates a selected block of information by scanning its perimeter and assessing structural characteristics to determine boundaries. During this automated evaluation, the algorithm looks for distinct formatting clues that differentiate the top row from the subsequent rows. These clues frequently involve contrasting background fills, bold typography, or a complete absence of numerical figures within the cells.
When users activate the sorting configuration panel, a specific administrative toggle dictates whether the top row participates in the rearrangement. The functional mechanics of this interface feature operate through a deliberate exclusion protocol. Activating the designated setting signals the sorting algorithm to lock the uppermost row in place, effectively building a digital firewall that protects column labels from participating in the alphabetical rotation.
Behind the scenes, the parsing engine executes a strict logical evaluation of the selected range. If the configuration parameter is active, the system treats the primary row exclusively as field identifiers rather than sorting candidates. Consequently, the remaining rows below this barrier undergo the requested alphabetical or numerical sequencing while the header remains untouched at the summit of the grid.
To visualize this protective mechanism in a professional reporting environment, consider the following structural setup:
- The primary header row contains distinct text strings paired with unique background shading.
- Data rows situated directly beneath the header consist of uniform typography and mixed alphanumeric values.
- The configuration checkbox establishes a permanent boundary layer between the first row and the rest of the dataset.
Locking the topmost row during data arrangement operations prevents administrative errors and maintains the logical hierarchy of the entire spreadsheet.
Neglecting this crucial configuration step introduces severe vulnerabilities into financial ledgers and project management trackers. For instance, in a corporate inventory audit tracking thousands of global shipments, a misplaced header can cause tracking codes to disassociate from their corresponding descriptions. This clerical displacement disrupts automated lookup formulas such as VLOOKUP or XMATCH, resulting in corrupted outputs that require hours of tedious manual auditing to resolve.
Emergency Recovery Protocols for Displaced Headers
Accidental integration of title rows into an alphabetical sorting sequence creates immediate disarray that demands swift corrective action. Recognizing the symptoms of a compromised dataset involves scanning the middle rows for uppercase text strings or categorical labels that disrupt the natural flow of the records.
Implementing an effective recovery procedure requires immediate intervention before subsequent edits overwrite the temporary memory cache of the software application. The standard remediation workflow follows a precise sequence to restore order without losing subsequent data modifications.
- Execute an immediate command interruption using the standard undo shortcut to revert the spreadsheet to its pre-sorted state.
- Locate the displaced title row if the undo function is unavailable, carefully selecting and cutting the misplaced labels from their incorrect location.
- Insert a temporary blank row at the very top of the spreadsheet grid and paste the extracted header titles into their proper position.
- Sort the remaining dataset beneath the restored header while ensuring the protective configuration option remains active for all future operations.
Complex recovery scenarios frequently occur when users perform multiple sequential operations before noticing structural damage. In such cases, relying solely on history buffers becomes impossible, requiring a manual audit of the dataset against backup files or version-control logs. Maintaining disciplined habits regarding range selection and configuration verification ultimately eliminates the need for emergency recovery protocols altogether.
Case sensitivity settings dictate whether capital letters precede lowercase entries during strict alphabetical collation.: How To Sort Alphabetically In Excel
Precision in data management often hinges on the minutiae of character recognition, where digital grids differentiate between upper and lower case letters. When compiling extensive records, the software relies on strict computational logic to determine the exact vertical placement of every text string. Unlocking the full potential of electronic spreadsheets requires mastering these nuanced sorting behaviors to ensure absolute data integrity.
Without proper configuration, lists featuring mixed capitalization can quickly devolve into disorganized sequences, frustrating analysts and undermining professional presentations.
Beneath the graphical user interface lies the foundational American Standard Code for Information Interchange system, universally known as ASCII. This digital translation framework assigns specific numerical values to every letter, punctuation mark, and symbol recognized by the computer. Capital letters from A through Z occupy numeric positions ranging from 65 to 90, while lowercase letters from a through z reside higher up the scale, spanning values from 97 to 122.
When a standard collation sequence runs, the underlying engine evaluates these numeric values rather than the linguistic shape of the characters. Consequently, the software inherently perceives every uppercase glyph as lighter or distinct from its lowercase counterpart, driving the fundamental mechanics of how data arrays settle into their designated rows.
Ascii Code Mechanics In Spreadsheet Sorting Operations
The internal processing architecture processes text strings character by character from left to right, comparing the raw ASCII values of each glyph in sequence. If two words share the exact same spelling except for a capital letter at the beginning, the lower ASCII value of the uppercase character forces it to appear before the lowercase version. This mathematical certainty governs every text-based arrangement within the workbook, operating silently in the background of daily spreadsheet tasks.
Grasping this computational reality empowers creators to predict exact outcomes before executing any sorting commands, eliminating unexpected shifts in large datasets.
Visualizing this process requires looking closely at how the grid renders text during a routine column arrangement. Imagine peering into a high-resolution display where a magnifying glass highlights the microscopic binary code driving the visual layout. Every keystroke is translated into a strict hierarchy of numbers, ensuring that the software never guesses but instead calculates exact positions based on predefined system dictionaries.
Configuration Pathways For Case Sensitive Sorting Parameters
Activating strict case-sensitive collation requires venturing beyond the standard, surface-level sorting buttons found on the primary ribbon interface. Users must access the dedicated sort dialog box by selecting the target range and opening the comprehensive sorting options menu. Within this specialized configuration window, a discrete checkbox allows administrators to explicitly enable case sensitivity, shifting the application from a lenient text evaluation mode to a rigorous character-matching standard.
Navigating this hidden menu transforms a basic spreadsheet tool into a powerful database engine capable of maintaining strict corporate naming conventions.
Executing this adjustment changes the behavioral response of the entire dataset instantly upon confirmation. The application re-evaluates the selected cells through the lens of exact character matching, rearranging the rows to reflect the newly enforced parameters. This level of control is indispensable when managing technical inventories, cryptographic keys, or proprietary product codes where capitalization carries significant operational meaning.
Comparative Behavioral Analysis Of Mixed Capitalization Arrangements
Understanding the practical differences between default sorting and case-sensitive collation becomes clear when observing how identical words with varying capitalizations settle into the grid. The choice of parameter rules directly dictates the final visual hierarchy of the spreadsheet, altering the reading flow for anyone reviewing the document.
- Under default sorting rules, the application treats ‘apple’, ‘Apple’, and ‘APPLE’ as functionally equivalent, often grouping them together based purely on alphabetical letters while leaving their relative order to chance or original entry sequence.
- Under strict case-sensitive parameters, the uppercase entry ‘APPLE’ invariably claims the topmost position due to its lower ASCII numerical value.
- Following the primary uppercase entry, the title-case word ‘Apple’ occupies the middle tier because its initial capital letter still precedes true lowercase characters in the ASCII sequence.
- The fully lowercase entry ‘apple’ settles at the bottom of the group, pushed downward by its higher ASCII positional value, ensuring a predictable and mathematically rigid hierarchy.
Aesthetic And Functional Impacts On Professional Name Directories
Corporate directories, human resources databases, and client contact lists rely heavily on immaculate presentation to project professionalism and reliability. Implementing case-sensitive ordering prevents embarrassing alphabetical anomalies, such as a lowercase surname appearing near the top of a directory simply due to an automated data import quirk. Maintaining a uniform structure where proper nouns adhere strictly to conventional capitalization rules enhances readability and fosters immediate trust among stakeholders and executive leadership.
Strict adherence to case-sensitive collation transforms chaotic data inputs into polished, audit-ready masterpieces that reflect organizational excellence and meticulous attention to detail.
Beyond mere aesthetics, functional integrity is vastly improved when names and identifiers maintain their intended capitalization without random sorting disruptions. Auditors and compliance officers examining financial ledgers or personnel files benefit immensely from predictable data structures that eliminate cognitive friction during reviews. By mastering these advanced sorting controls, professionals elevate their daily reporting from simple record-keeping to a sophisticated craft of data architecture.
Working with horizontal layouts demands specialized transformation techniques since standard sorting operates strictly on vertical columns.
Electronic spreadsheets are fundamentally engineered around a vertical architecture, treating columns as the primary axis for data manipulation and relational analysis. When information flows horizontally across a row rather than cascading downward, users often encounter unexpected structural roadblocks during basic administrative tasks. Transforming layout orientation bridges the gap between unconventional data entry and rigorous analytical standards, unlocking seamless structural optimization.
Understanding the core engineering limitations of spreadsheet applications clarifies why horizontal arrangements resist standard sorting commands natively. Spreadsheet algorithms are explicitly programmed to evaluate data vertically, assessing each entry row by row within a designated column boundary. Attempting to apply a standard sort across a horizontal axis results in fragmented values, broken formulas, and completely scrambled datasets because the underlying logic cannot natively comprehend row-based sequential ordering.
Mechanical Architecture of Spreadsheet Sorting Limitations
The internal mechanics of electronic grid systems rely entirely on vertical vector calculations to maintain relational integrity among adjacent cells. When a command is issued to arrange data alphabetically, the software scans downward through specified column ranges while keeping corresponding row data securely locked together. Horizontal layouts invert this expected matrix, placing independent data points across columns rather than rows, which causes standard sorting tools to either gray out entirely or misinterpret the entire array as isolated header labels.
Bypassing this structural hurdle requires temporary geometric conversion to align the data with the software’s native vertical processing capabilities.
Users facing horizontal data must execute a calculated pivot, temporarily converting the rebellious row-based layout into a compliant vertical column before executing any sorting sequences. This strategic maneuver respects the application’s core computational design while ensuring that the underlying data values remain completely intact and mathematically sound.
Successful data organization relies on respecting the architectural parameters of the software while applying creative transposition methods to handle unconventional layouts.
The transformation lifecycle from a horizontal layout to a sorted horizontal output follows a precise three-stage procedural flow involving extraction, vertical alignment, and final restoration.
| Stage Phase | Original Horizontal Layout | Transposed Vertical Layout |
|---|---|---|
| Initial Extraction | [Smith, Adams, Miller, Baker] | Adams (Sorted after transposition) |
| Active Processing | [Data values aligned left to right] | Baker |
| Final Preparation | [Requires manual or automated pivot] | Miller / Smith |
Restoration Procedures for Horizontal Orientation
Once the vertical column has been successfully organized into a pristine alphabetical sequence, returning the data to its original horizontal orientation requires a deliberate paste-special maneuver. Simply copying and pasting the sorted vertical column back into a row will paste the values downward unless the transposition flag is explicitly checked during the insertion phase. Utilizing the paste transposition utility seamlessly flips the vertical column back into its original horizontal posture, preserving the newly established alphabetical order while satisfying visual layout requirements for executive reporting.
Proper execution of this restoration phase ensures that dashboard designs, financial ledgers, and comparative summary tables maintain their required visual aesthetics without sacrificing structural data integrity. Mastering this bidirectional workflow empowers professionals to conquer any layout anomaly encountered in modern data management environments.
Managing dependent lists ensures that corresponding metadata stays anchored to primary names throughout the rearrangement
Data integrity forms the bedrock of professional operations, demanding absolute precision whenever rows and columns undergo structural updates. When records span multiple interconnected data points, executing modifications requires an uncompromising adherence to relational synchronization protocols. Failing to maintain this critical cohesion introduces catastrophic vulnerabilities into daily operational spreadsheets.
The structural dangers of sorting individual columns independently within relational tables cannot be overstated. When a user highlights a single column of names and applies an alphabetical sort without including adjacent data, the horizontal bond linking those names to their corresponding metrics, identification numbers, and financial values is instantly shattered. This isolated column manipulation creates a cascading structural failure throughout the entire spreadsheet environment.
Primary identifiers become completely disconnected from their associated foreign keys, rendering historical records, transactional ledgers, and analytical reports entirely untrustworthy. The human eye often fails to catch these subtle misalignments immediately, allowing corrupted datasets to propagate deep into enterprise reporting systems before detection occurs.
Relational Integrity Principles in Spreadsheet Management
Maintaining structural harmony across complex datasets relies on fundamental database principles applied directly to electronic spreadsheet environments. Relational integrity dictates that dependent data must remain physically or logically bound to its parent record at every stage of sorting or filtering. In a properly managed grid, rows act as indivisible atomic units where every cell horizontal to a primary entry shares an immutable relationship with that specific record.
When algorithms reorder an array, they must evaluate the entire bounding box of information simultaneously rather than treating vertical columns as independent silos. Adhering to these structural safeguards prevents the silent corruption of foreign keys, ensuring that inventory counts, pricing tiers, and serial numbers permanently track alongside their designated item names.
Consider the vivid, high-stakes scenario of a bustling global warehouse supply chain operating on a master inventory ledger containing thousands of sensitive stock entries. An unseasoned inventory manager attempted to organize a massive quarterly stock sheet by highlighting only the primary product name column and applying an automated alphabetical sort. The disaster unfolded silently. SKU numbers, unit costs, bin locations, and reorder thresholds remained entirely static while the product names shifted drastically up and down the vertical axis.
Medical supplies suddenly aligned with industrial heavy machinery pricing, and perishable grocery items inherited the serial numbers of hazardous chemical components. When the morning fulfillment cycle began, automated pickers pulled entirely incorrect items from warehouse shelves, dispatching millions of dollars in mismatched inventory to bewildered clients. The financial fallout required weeks of exhaustive physical stock audits, forensic database reconstruction, and substantial operational losses simply because adjacent columns were not linked during a routine sorting sequence.
Preventative Measures Utilizing Dynamic Table Structures
Modern spreadsheet applications provide robust, built-in structural architectures designed specifically to eliminate the risk of accidental data fragmentation during sorting operations. Converting raw cell ranges into official table objects fundamentally changes how the software interprets data boundaries. When data is formatted as a dynamic table, the application automatically locks adjacent rows together as a unified relational block, making it virtually impossible to accidentally sort a single column in isolation.
Mastering how to sort alphabetically in excel brings brilliant order to chaotic data streams, illuminating paths to clarity much like discovering the ideal alternative zu klarna streamlines your financial journey. Every organized row tells a compelling story of progress, empowering you to conquer spreadsheets with confidence and renewed professional momentum.
Furthermore, utilizing comprehensive range selection shortcuts before initiating any sort guarantees that all dependent metadata travels securely alongside its primary identifier.
The following practices Artikel the essential steps required to secure relational integrity before executing any sorting operation:
- Transform standard rectangular cell ranges into official application tables using native formatting commands to enforce automatic row locking.
- Select the entire data matrix including all headers, metrics, and dependent columns before invoking the sort dialogue interface.
- Enable contextual sorting tools that explicitly warn users when a selection range does not encompass adjacent populated columns.
- Implement strict permission controls on master operational ledgers to restrict unguided manual column sorting by unauthorized personnel.
Relational integrity is preserved only when the entire data array moves as a unified matrix, binding every dependent metadata point securely to its primary record.
Implementing these foundational safeguards transforms vulnerable spreadsheets into resilient, professionally managed information systems capable of withstanding rigorous daily updates without risking data corruption.
Utilizing conditional formatting alongside alphabetical sorting creates dynamic visual hierarchies within extensive operational sheets.
Imagine standing before a sprawling digital ledger containing thousands of client names, inventory entries, and financial records, where raw data threatens to overwhelm human comprehension. When professionals apply intelligent visual enhancements alongside structured name-based sequences, rows of monotonous text instantly transform into a vibrant, living landscape of actionable intelligence. This synergy between orderly arrangement and dynamic color mapping breathes life into static grids, guiding the human eye effortlessly toward critical operational insights without requiring tedious manual scanning.
Behind the scenes of this visual transformation, the digital grid maintains a strict, rule-based vigilance over every individual cell. When an electronic table undergoes a thorough restructuring from A to Z, conditional formatting rules do not remain stubbornly fixed to static physical coordinates; instead, they dynamically adhere to the moving data points. As names shift positions to occupy new rows, the assigned background hues and text pigments travel faithfully with their corresponding records.
This intelligent tracking mechanism prevents visual corruption, ensuring that a designated highlight—such as a soft amber alert for pending accounts—instantly relocates alongside the newly sorted client name.
Visual audit enhancement strategies through color coding
Executing rapid visual audits across massive corporate databases requires a disciplined palette that complements alphabetical groupings rather than causing sensory overload for reviewers. Implementing a thoughtful chromatic strategy allows executive leadership to scan hundreds of entries in mere seconds, instantly identifying trends, anomalies, or compliance gaps tucked inside alphabetized directories. The following palette deployment methods optimize readability during high-speed reviews.
- Deploying soft pastel green backgrounds exclusively for alphabetized employee surnames beginning with letters A through H establishes an immediate geographical anchor for early-alphabet personnel audits.
- Applying muted amber tones to mid-range entries from letters I through R creates a balanced transition zone, preventing visual fatigue during exhaustive compliance checks.
- Reserving striking coral or crimson highlights strictly for trailing alphabetical segments from S through Z draws immediate executive focus to the end-of-chain records that historically require closer supervisory oversight.
- Utilizing neutral gray-scale gradients for inactive accounts intermixed within active alphabetical logs ensures that obsolete data recedes into the background while live records command primary visual attention.
Configuration process for automated alphabetical range highlighting
Establishing automated visual triggers within modern spreadsheet applications requires a precise sequence of menu navigation and logic formulation. Analysts begin by selecting the target column containing the alphabetized text strings, ensuring the absolute reference markers are correctly adjusted to accommodate future data expansions. Next, accessing the conditional formatting management console allows users to craft custom formula rules that evaluate string values dynamically.
Instead of relying on rigid exact-match criteria, professionals deploy logical operators combined with text evaluation functions to target specific alphabetical boundaries. For instance, setting a rule to evaluate whether a text string falls alphabetically prior to a specific threshold enables the system to paint entire data rows with a distinct background tone automatically.
“Dynamic formatting rules anchored to sorted columns eliminate manual tagging errors and enforce absolute visual consistency across enterprise-wide reporting.”
Once the mathematical parameters are validated and applied, any subsequent sorting operation immediately triggers the rendering engine, instantly re-painting the newly aligned rows according to their updated alphabetical hierarchy.
Impact of combined visual tools on executive decision-making velocity
When leadership teams gather in high-stakes boardrooms to review quarterly performance metrics, the speed at which information is processed dictates the agility of corporate strategy. By fusing strict alphabetical organization with responsive chromatic indicators, organizations slash the time required to interpret complex operational dashboards from precious minutes down to split seconds. Executives no longer need to trace individual rows manually across wide display screens to verify regional sales performance tied to client names.
Real-life deployments in multinational supply chain management vividly demonstrate this acceleration; logistics directors utilizing automated alphabetical sorting paired with dynamic threshold highlighting can isolate regional bottlenecks within seconds during live crisis management briefings. The human brain processes color wavelengths thousands of times faster than raw alphabetical text strings, meaning that a strategically colored cell acts as an instant cognitive shortcut.
This seamless synthesis of order and color empowers decision-makers to pivot resources, address operational discrepancies, and execute decisive maneuvers with absolute confidence.
Final Thoughts
Mastering this essential digital skill is not merely about organizing rows and columns; it is about empowering your workflow to reach unprecedented levels of clarity and reliability. As you implement these robust data strategies, you pave the way for smarter decisions, flawless records, and a truly streamlined professional journey.
