hyperglance.com product features reporting transforms the chaotic sprawl of multi-cloud environments into a crystal-clear masterclass of digital command. Imagine a single pane of glass where complex data streams converge, painting a brilliant picture of operational health right before your eyes. Today, we step into a world where technology meets absolute clarity, empowering teams to conquer digital frontiers with unprecedented confidence.
By harnessing the power of advanced telemetry translation, custom metric widgets, and dynamic topology maps, modern enterprises can finally bridge the gap between raw infrastructure data and strategic business value. This comprehensive journey through intelligent reporting and governance tools reveals how seamless visibility paves the path for continuous innovation, financial precision, and bulletproof security across every distributed layer of your organization.
Unlocking operational visibility through hyperglance.com product features reporting dashboards
Modern enterprises navigate a relentless sea of digital complexity, where fragmented cloud architectures often obscure critical operational insights. Transforming this chaotic expanse into a realm of absolute clarity requires more than simple monitoring tools; it demands an intelligent command center that converges disparate data streams into an intuitive environment. Through advanced reporting dashboards, organizations bridge the gap between raw infrastructure metrics and strategic executive decisions, turning endless streams of telemetry into actionable intelligence that drives business momentum forward.
Beneath the surface of this unified interface lies a sophisticated foundational architecture engineered to ingest, normalize, and synthesize multi-cloud data streams into a single pane of glass. By establishing secure, low-latency API integrations with leading cloud service providers, the system continuously harvests telemetry, configuration logs, and performance metrics without introducing latency into production environments. This incoming torrent of data flows through a distributed processing engine that standardizes heterogeneous formats into a cohesive data model.
Operators no longer need to swivel-chair between native console views of different vendors. Instead, they interact with a unified semantic layer that instantly correlates dependencies, identifies bottlenecks, and presents a synchronized, real-time narrative of the entire enterprise digital footprint.
Multi-cloud data ingestion and aggregation foundations
Enterprise workloads sprawl across diverse environments, making the centralization of telemetry an essential prerequisite for robust governance and security posture management. The underlying data pipeline operates with resilient fault tolerance, ensuring that even during regional cloud outages or severe network partitions, reporting mechanisms maintain data integrity. Real-time stream processors capture state changes at the millisecond level, while asynchronous batch workers index historical logs for deep analytical queries.
This dual-track ingestion methodology guarantees that dashboards reflect both the immediate operational pulse and long-term capacity trends. Security teams and DevOps engineers alike benefit from this unified architecture, as role-based access controls ensure each stakeholder views precisely the data relevant to their operational domain, filtered through rigorous compliance standards.
Operational clarity is not merely about seeing everything at once; it is about distilling infinite complexity into the exact insight required to make decisive, error-free choices in high-stakes environments.
Resource utilization trends over historical timeframes
Understanding current consumption patterns is only half the battle when managing cloud expenditures and performance bottlenecks. Custom metric widgets empower engineering teams to look backward to predict forward, leveraging extensive historical timeframes to visualize resource utilization trends across CPU, memory, storage, and network throughput. These adaptable visual components allow administrators to isolate specific temporal windows—ranging from the last twenty-four hours to multi-year capacity planning arcs—identifying cyclical surges and chronic under-provisioning.
For instance, retail platforms preparing for seasonal traffic spikes can analyze historical Black Friday telemetry to auto-scale provisioned instances proactively rather than reactively, preventing latency and runaway bills.
Organizations often struggle with sudden spikes in cloud expenditures because traditional monitoring tools fail to contextualize short-term anomalies within broader operational trends. Custom metric widgets resolve this challenge by incorporating advanced statistical smoothing and anomaly detection algorithms directly into the dashboard interface. Key capabilities delivered by these analytical components include:
- Granular data aggregation intervals spanning from one-minute resolutions for active incident triage to monthly summaries for executive financial forecasting.
- Comparative overlay capabilities that juxtapose current infrastructure performance against historical baselines to immediately flag anomalous behavior.
- Automated threshold markers that change color dynamically as resource consumption approaches critical capacity limits defined by internal SLAs.
Dynamic visual topology mapping during infrastructure changes
Infrastructure is rarely static; auto-scaling groups launch new instances, serverless functions execute and terminate, and network routing tables update dynamically in response to shifting traffic demands. Keeping pace with this constant state of flux is impossible with static diagrams or outdated spreadsheets, necessitating an interface that evolves in real-time alongside the environment it represents. The visual topology mapping engine within Hyperglance redefines spatial awareness by rendering complex multi-cloud architectures as interactive, living graphs that instantly reflect modifications across the entire digital ecosystem.
When a cloud architect provisions a new Kubernetes cluster or alters a security group rule, the topology map updates instantaneously without requiring manual refreshes or script re-executions. Nodes represent compute instances, databases, load balancers, and storage buckets, while glowing directional edges depict active data flows, API calls, and dependency linkages. If a database instance experiences a surge in latency, the corresponding node visually pulses with an amber or red warning indicator, and its dependent microservices concurrently shift color to highlight the cascading impact radius.
Operators can click on any node to drill down into underlying telemetry, configuration history, and associated compliance policies without ever leaving the spatial context of the map.
This dynamic visualization relies on continuous graph database synchronization, which maps relational dependencies as they occur in the cloud fabric. Imagine a global financial institution deploying a hasty hotfix during a high-volume trading session; as new container pods spin up across multi-region VPCs, the topology map autonomously redraws its layout to group related assets by application stack and security zone.
This eliminates the blind spots that traditionally plague root-cause analysis during high-pressure incidents. By transforming abstract JSON configurations and terminal logs into a vibrant, navigable visual cartography, teams reduce mean time to resolution by instantly identifying precisely where a failure originated and which downstream services remain vulnerable to collateral disruption.
Alert notification thresholds and escalation pathways
Effective incident management relies on precision timing and unambiguous communication protocols to ensure operational anomalies are addressed before they escalate into catastrophic outages. The structured overview below details the comprehensive alerting matrix utilized to govern system health and drive rapid remediation workflows.
| Severity Level | Trigger Conditions | Notification Channels | Escalation Paths |
|---|---|---|---|
| Critical | Complete service unavailability, security breach detected, or core database failure exceeding 99.9% error rate. | PagerDuty automated phone calls, SMS broadcasts, high-priority Slack/Teams channels, and emergency webhook integrations. | Immediate wake-up call to On-Call DevOps Lead; if unacknowledged within 5 minutes, automatically escalates to Engineering Director and VP of Technology. |
| High | Significant degradation in application response times (>500ms baseline increase) or CPU utilization sustaining above 90% for 15 minutes. | Primary Slack/Teams operational channels, designated DevOps email distribution lists, and dashboard pop-up banners. | Notification sent to secondary on-call engineer; escalates to Team Lead if left unacknowledged for 15 minutes. |
| Medium | Storage volume capacity reaching 80% threshold or sporadic non-critical API timeouts occurring intermittently. | Standard operational ticketing system (Jira/ServiceNow) and daily email digest summaries. | Assigned to relevant system administrator during standard business hours; ticket reviewed in weekly sprint planning if unresolved. |
| Low | Minor configuration drift detected, non-impacting patch availability, or historical resource optimization recommendations. | Consolidated weekly reporting dashboard widgets and low-priority notification center feeds. | Logged for review during routine infrastructure maintenance cycles without triggering direct paging protocols. |
Transforming raw telemetry into actionable executive summaries with hyperglance.com product features reporting tools
In the fast-paced theater of modern enterprise cloud architecture, leadership teams are frequently overwhelmed by a relentless deluge of raw, unrefined telemetry data. Amidst gigabytes of CPU utilization logs, memory allocation spikes, and ephemeral network packets, the core business narrative often gets completely lost in translation. Bridging this critical communication chasm requires an intelligent translation layer that converts sprawling, technical metrics into crystal-clear executive intelligence.
By distilling millions of disparate data points into cohesive, boardroom-ready insights, organizations can finally align their underlying technical infrastructure with overarching financial and strategic goals.
The journey from chaotic cloud metrics to refined business intelligence relies on sophisticated abstraction engines that contextualize raw telemetry. When a cloud environment generates millions of API calls and storage read-write cycles every second, standard monitoring tools merely echo the noise. In contrast, advanced reporting frameworks categorize these signals into meaningful Key Performance Indicators such as operational velocity, financial burn rate, and infrastructure resilience.
This seamless metamorphosis empowers Chief Technology Officers and Chief Financial Officers to converse in a unified language of efficiency, eliminating the traditional friction between engineering execution and executive oversight.
Visualizing financial distribution and infrastructural inefficiencies requires a structured approach to data presentation. The following matrix illustrates how organizational departments consume cloud resources, highlighting financial leakage and immediate areas for strategic intervention.
| Department-wise Cost Allocation | Resource Wastage Percentages | Optimization Potential | Projected Monthly Savings |
|---|---|---|---|
| Research and Development | 34% | High | $24,500 |
| Customer Experience Engineering | 18% | Moderate | $11,200 |
| Global Marketing Operations | 42% | Critical | $38,900 |
| Enterprise Data Analytics | 12% | Low | $6,400 |
Automated report delivery mechanisms for stakeholder alignment
Maintaining continuous alignment across diverse corporate stakeholders demands absolute consistency and punctuality in information dissemination. Manually compiling weekly or monthly slide decks often results in delayed decisions and stale data by the time it reaches executive desks. Modern operational workflows demand seamless automation that bypasses human bottlenecks altogether, ensuring the right insights land in the right inboxes precisely when strategic reviews occur.
Configuring automated reporting schedules within the platform allows administrators to define exact delivery cadences tailored to specific executive personas. Financial controllers receive precise cost-breakdown PDFs every Monday morning, while engineering leads obtain comprehensive performance digests at the close of every sprint. These automated pipelines leverage secure, encrypted transmission protocols to guarantee that sensitive organizational telemetry remains protected while traveling from the cloud environment directly to executive mobile devices and workstations.
Operational transparency is achieved not through the volume of data collected, but through the unwavering precision of its automated delivery to decision-makers.
Predictive capacity forecasting algorithms and bottleneck prevention
Anticipating infrastructure strain before it degrades user experience separates reactive firefighting from proactive architectural mastery. Traditional monitoring systems alert engineers only after CPU thresholds breach critical limits or latency spikes begin frustrating end users. Advanced analytical frameworks alter this paradigm entirely by deploying robust trend forecasting algorithms that scan historical telemetry patterns to foresee impending resource exhaustion weeks in advance.
These predictive engines harness sophisticated machine learning models, including recurrent neural networks and seasonal autoregressive integrated moving average techniques, to evaluate cyclical workload behaviors. Consider a prominent global e-commerce enterprise preparing for an unprecedented surge in traffic during annual retail shopping events like Black Friday. By analyzing historical traffic influxes, database query volumes, and storage scaling velocities from previous years, the forecasting algorithm accurately projects exact saturation points across microservices.
Instead of scrambling to provision servers mid-crisis, the platform issues automated recommendations to pre-scale Kubernetes clusters and adjust database IOPS limits well before the traffic wave hits.
Furthermore, these predictive mechanisms factor in external variables such as marketing campaign schedules and historical user growth trajectories to refine their accuracy continuously. When an unexpected anomaly deviates from established seasonal patterns, the system recalculates optimization pathways instantly, safeguarding the digital supply chain against costly downtime. This deep analytical foresight ensures that cloud expenditures remain strictly tied to actual predictive demand curves, effectively neutralizing capacity bottlenecks before they ever materialize into tangible service interruptions.
Enforcing compliance governance standards utilizing hyperglance.com product features reporting capabilities

Source: hyperglance.com
Navigating the labyrinth of modern regulatory mandates often feels like chasing a moving target under a relentless spotlight. Security leaders face the daunting challenge of proving adherence to rigorous standards across sprawling multi-cloud infrastructures without slowing down innovation. By leveraging advanced reporting capabilities, organizations can bridge the dangerous gap between rapid deployment and absolute regulatory accountability. This analytical journey explores how automated oversight transforms compliance from a chaotic scramble into a streamlined, bulletproof operational standard.
Hyperglance.com product features reporting illuminates complex cloud architectures with striking visual clarity. Much like implementing efficient delivery management software transforms chaotic supply chains into seamless journeys of success, these dynamic analytics empower teams to navigate operational hurdles with unwavering confidence and drive future innovations forward.
Modern cloud architectures demand a paradigm shift in how enterprises approach security governance and audit readiness. Instead of relying on manual checklists and periodic snapshots, security teams now deploy intelligent surveillance systems that continuously evaluate every resource against established industry baselines. This proactive posture ensures that vulnerabilities are identified and neutralized before they can manifest as catastrophic compliance failures.
Hyperglance.com product features reporting illuminates complex cloud architectures with sharp clarity, transforming raw data into striking visual dashboards. As teams navigate these vivid insights, streamlining operations through the efficient quail vendor portal unlocks unprecedented partnership growth. Ultimately, this dynamic synergy empowers modern enterprises to elevate their reporting standards and conquer new milestones with absolute confidence.
Automated auditing procedures for regulatory benchmarks, Hyperglance.com product features reporting
Continuous vigilance forms the bedrock of modern cloud security, requiring systems that never sleep and never overlook minor misconfigurations. Automated auditing engines execute deep-dive inspections across every virtual machine, storage bucket, and network gateway, comparing live configurations against recognized security frameworks. When evaluating environments against the Center for Internet Security benchmarks or Healthcare Insurance Portability and Accountability Act regulations, the platform scans thousands of individual parameters in real time.
For instance, a healthcare provider managing patient data across hybrid architectures relies on these automated routines to instantly flag unencrypted databases or overly permissive access control lists, ensuring protected health information remains shielded from unauthorized exposure.
Continuous automated auditing transforms compliance from a reactive burden into an intrinsic, living component of cloud architecture integrity.
The system compiles these diagnostic findings into high-resolution visual dashboards that map directly to specific regulatory articles. Stakeholders can visualize compliance posture through dynamic heatmaps, where a glowing amber indicator signifies a drifted encryption setting while a solid green badge confirms adherence. This vivid visual narrative allows security directors to brief executive boards with absolute clarity, replacing dense technical spreadsheets with compelling evidence of risk mitigation.
Immediate remediation script generation from failed audit check items
Identifying a compliance violation is merely the first step; the true measure of a platform lies in the velocity of its corrective response. When an audit check fails, security analysts no longer need to manually draft complex command-line fixes or open protracted engineering tickets. The platform instantly synthesizes the context of the violation and produces bespoke remediation scripts tailored precisely to the affected cloud resource.
Whether generating Terraform modules, AWS CLI commands, or Azure Resource Manager templates, these immediate remediation tools empower engineers to resolve complex misconfigurations with a single click.
Visual descriptive evidence within the incident console displays the exact JSON state of the non-compliant resource side-by-side with the proposed corrected code block. This transparent preview allows senior administrators to verify the impact of the script prior to execution, eliminating the fear of unintended downtime. Consider a financial institution facing an unexpected S3 bucket public access policy; the system immediately highlights the offending permission and generates a corrective script that seals the perimeter instantly, effectively neutralizing the compliance breach within seconds of its detection.
Procedural steps for customizing regulatory framework templates
Adapting built-in compliance frameworks to align with unique internal governance policies requires a methodical and structured approach within the platform interface. Security operations personnel must execute precise configurations to ensure that custom reporting accurately reflects internal risk tolerances.
Hyperglance.com product features reporting illuminates complex cloud architectures with brilliant visual clarity, guiding teams toward informed decisions. Assessing corporate journeys, particularly tracking the sharpcloud ltd company status 2022-2026 , reveals inspiring resilience and strategic adaptation in the modern tech landscape. Ultimately, dynamic reporting tools empower organizations to navigate future growth with absolute confidence.
- Navigate to the governance module within the primary dashboard and select the compliance framework manager to initiate the template customization workflow.
- Choose an existing baseline, such as a standard CIS benchmark or HIPAA profile, and duplicate it to serve as the foundational template for internal modifications.
- Access the rule-mapping interface to toggle specific evaluation parameters on or off, tailoring the assessment criteria to match proprietary corporate security policies.
- Define custom severity levels for individual check items, ensuring that critical business assets trigger higher-priority alerts during routine reporting cycles.
- Assign automated notification workflows to designated security teams, specifying the exact communication channels and escalation paths for newly discovered compliance deviations.
- Save and deploy the newly configured template across targeted cloud accounts, initiating an immediate baseline scan to verify the updated governance parameters.
Configuration drift remains the silent assassin of enterprise cloud security, gradually eroding defensive perimeters as development teams push continuous updates and ephemeral resources spin up and down. Distributed development environments are particularly vulnerable, as decentralized engineering squads inadvertently introduce misconfigurations that slip past initial deployment gates. Continuous compliance monitoring acts as a permanent digital guardian, systematically identifying unauthorized deviations from established baselines before they compound into systemic vulnerabilities.
For example, a global retail enterprise utilizing distributed microservices avoided a major data exposure when the continuous monitoring engine detected an unauthorized port opening in a staging environment and automatically reverted the firewall rule to comply with internal security benchmarks. By maintaining an unbroken chain of automated oversight, organizations eliminate the blind spots that foster drift, ensuring that production, staging, and development environments adhere uniformly to rigorous regulatory standards without hindering the speed of modern software delivery.
Sharp hyperglance.com product features reporting illuminates modern operational visibility, yet true workplace safety demands even deeper vigilance. Integrating kogniz contact tracing bridges vital health protocols with cutting-edge analytics, empowering teams to safeguard environments seamlessly. Ultimately, robust hyperglance.com product features reporting delivers the clarity leaders need to navigate complex challenges with unwavering confidence and precision.
Optimizing financial expenditures through hyperglance.com product features reporting insights
Navigating the labyrinth of modern cloud economics demands rigorous oversight, deep telemetry analysis, and an unyielding commitment to financial accountability across every engineering tier. Organizations routinely hemorrhage capital through unmonitored provisioned resources, idle assets, and unoptimized compute layers that silently drain corporate balance sheets long before month-end invoices arrive. Fortunately, cutting-edge visibility platforms dismantle these fiscal blind spots, turning chaotic infrastructure expenditures into a predictable, highly optimized engine for sustainable business growth.
Modern enterprises achieve unprecedented fiscal discipline by deploying advanced attribution methodologies and real-time behavioral telemetry that expose precisely where every single digital dollar flows across multi-cloud environments. By connecting technical deployment metrics directly to economic ledgers, stakeholders eliminate guesswork, cultivate a profound culture of fiscal ownership among engineering squads, and transform raw consumption data into bulletproof executive strategies.
Granular attribution models for cloud spending allocation
Unraveling the complexities of shared cloud bills requires sophisticated attribution frameworks that accurately map abstract infrastructure consumption directly to the microservices and development squads responsible for generating them. Precision tagging, dynamic contextual labeling, and algorithmic cost-sharing engines dissect monolithic vendor statements into transparent, bite-sized financial ledgers. Engineering teams can finally view their exact economic footprint without wading through opaque administrative overhead.
Precision financial tracking relies on a multi-layered approach to dissecting infrastructure consumption across complex, containerized, and serverless environments. The platform applies layered tagging frameworks and heuristic parsing to distribute costs equitably.
- Contextual tagging cascades automatically through Kubernetes namespaces, associating runtime pods directly with responsible engineering squads.
- Shared infrastructure expenses, such as centralized data transfer gateways and enterprise logging clusters, distribute proportionally based on active connection volumes.
- Serverless invocation meters trace asynchronous function executions down to the millisecond, calculating exact memory and CPU billing footprints.
- Development sandbox environments apply automated depreciation models, factoring in scheduled downtime to prevent weekend idle costs from inflating core project budgets.
Organizations leveraging these robust attribution frameworks routinely uncover hidden cost centers, shifting the burden of cloud optimization from stressed finance departments to empowered software architects who design the systems.
Comparative financial metrics across infrastructure acquisition vectors
Balancing compute acquisition strategies requires continuous evaluation of reserved commitments, spot market opportunities, on-demand flexibility, and waste eradication. Financial analysts rely on structured comparative data to restructure cloud portfolios for maximum operational efficiency.
The following financial landscape illustrates how diverse procurement vectors and waste metrics interact within a mature enterprise cloud architecture over a standard billing cycle.
| Acquisition Vector | Cost Efficiency | Workload Suitability | Associated Risk Factors |
|---|---|---|---|
| Reserved Instance Coverage | High savings (up to 72%) | Steady-state, predictable databases | Unused capacity risk during sudden traffic contractions |
| On-Demand Usage Costs | Standard retail pricing | Spiky, unpredictable, emergency workloads | Budget inflation if left running unattended |
| Spot Instance Savings | Maximum savings (up to 90%) | Fault-tolerant batch processing, CI/CD pipelines | Sudden instance termination notices requiring graceful failover |
| Wasted Idle Asset Expenses | Zero return, 100% loss | Orphaned disks, unattached elastic IPs, abandoned test clusters | Silent accumulation eating into operational margins |
Visual forensic scenario for anomalous API expenditure detection
Imagine a high-resolution financial command center interface bathed in the soft glow of real-time telemetry tickers, displaying a steady, flatline expenditure graph for a primary customer-facing API gateway throughout the early morning hours. Suddenly, at 03:14 UTC, a jagged neon-red spike pierces the baseline, shooting vertically upward by four hundred percent in under six minutes. The monitoring dashboard instantly triggers an ambient visual pulse, shifting the affected microservice module from calm emerald green to a stark, commanding amber warning state.
An interactive forensic overlay expands across the screen, deploying translucent data plumes that trace the exact origin of the financial anomaly back to a misconfigured third-party web crawler stuck in an infinite query loop. Detailed tooltips instantly calculate the projected financial damage in real-time, estimating an additional hourly burn rate of twelve hundred dollars if left unmitigated. Simultaneously, an automated mitigation recommendation card slides into view, suggesting an immediate rate-limiting threshold adjustment and IP-range throttling protocol, effectively bridging the gap between raw anomaly detection and instant financial preservation.
Proactive budget allocation alerts and financial safeguard mechanisms
Preventing catastrophic month-end billing surprises requires more than passive dashboard viewing; it demands an aggressive, automated nervous system that actively intercepts runaway cloud expenditures before they destabilize corporate ledgers. Traditional financial workflows often rely on retrospective reviews, where stakeholders discover budget overruns weeks after the billing cycle closes, rendering corrective action impossible. Advanced cloud governance platforms replace this outdated reactivity with real-time predictive analytics and dynamic programmatic alerts that notify financial controllers and engineering leads the exact moment spending velocities deviate from established historical baselines.
These intelligent notification systems analyze hourly consumption trends, factoring in seasonal traffic spikes, scheduled marketing campaigns, and ongoing deployment cycles to forecast month-end totals with remarkable accuracy. When consumption patterns threaten to breach predetermined threshold limits, automated escalation workflows activate across multiple communication channels, dispatching urgent telemetry summaries directly to Slack workspaces, email inboxes, and enterprise ticketing systems.
Proactive financial governance transforms cloud billing from an unpredictable corporate liability into a tightly controlled, highly transparent operational investment.
Finance departments gain profound administrative leverage through customizable spending guardrails that can trigger automated remediation actions, such as throttling non-essential staging clusters or scaling down aggressive auto-scaling groups when budgets reach critical ninety-percent capacities. By integrating granular cost telemetry directly into the daily operational routines of both financial analysts and software developers, organizations eliminate the traditional friction and finger-pointing that typically accompanies unexpected cloud invoice spikes.
Engineering teams receive immediate, actionable context regarding the financial impact of their code deployments, fostering an environment where cost-efficiency is treated as a core performance metric alongside latency and uptime. Ultimately, these sophisticated budget alert mechanisms empower modern enterprises to innovate rapidly in the cloud without harboring lingering anxieties about fiscal stewardship, ensuring that every dollar spent directly contributes to measurable business value.
Accelerating troubleshooting workflows via hyperglance.com product features reporting query engines.
Source: hyperglance.com
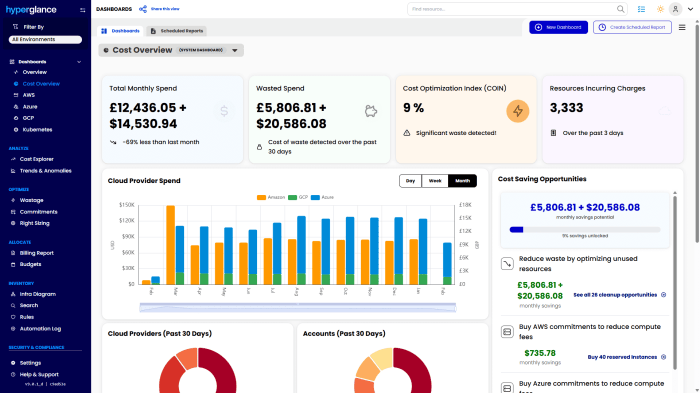
When critical infrastructure falters, every second counts in restoring normal operations and mitigating business impact. The pressure on engineering teams mounts rapidly as they sift through chaotic digital environments to isolate the exact origin of a failure. Modern enterprises require sophisticated mechanisms that cut through the noise of distributed architectures, transforming overwhelming diagnostic data into clear, immediate answers.
The platform introduces advanced querying capabilities designed to eradicate guesswork and drastically reduce mean time to resolution. By harnessing cutting-edge search architecture, technical operators can navigate complex cloud ecosystems with unprecedented speed and surgical precision, turning reactive firefighting into a streamlined, predictable resolution process.
Natural Language Asset Filtering
Navigating massive, multi-cloud inventories no longer requires memorizing complex command-line syntax or rigid database queries. Operators can interact with the system using conversational phrasing, dramatically lowering the barrier to entry for rapid asset discovery during high-pressure incidents. The underlying natural language processor instantly parses incoming text commands, translating everyday technical vocabulary into precise database filters.
Imagine typing a simple directive like “show me unencrypted production databases experiencing high memory usage in the eastern region.” The query engine immediately isolates the exact subset of assets from millions of infrastructure components across global cloud footprints. This capability eliminates manual sorting through endless asset trees, allowing responders to focus their cognitive energy on remediation rather than data gathering.
Metric Correlation and Latency Analysis
Isolating the root cause of degraded user experience often demands bridging the gap between application performance and underlying hardware behavior. The query engine excels at overlaying distinct telemetry streams, allowing engineers to juxtapose application response times directly against underlying infrastructure constraints. Pinpointing the exact moment an application slows down provides the necessary context to examine corresponding resource starvation indicators.
Correlating application latency metrics with underlying virtual machine CPU throttling events reveals hidden bottlenecks that standard monitoring tools frequently miss. When hypervisors restrict compute cycles due to noisy neighbors or exhausted credits, the resulting latency propagates straight up the software stack. The reporting engine constructs unified visual timelines, clearly demonstrating how hypervisor-level CPU stealing directly impacts transaction completion rates, thus empowering teams to right-size compute resources accurately.
Log Archive Export Procedure
Comprehensive incident post-mortems and rigorous security compliance demand seamless integration between cloud monitoring platforms and centralized auditing infrastructure. Exporting customized log archives ensures that historical telemetry remains accessible for deep forensic analysis and long-term compliance retention. The integration workflow allows organizations to stream targeted datasets directly into enterprise security information and event management systems without manual intervention.
The step-by-step procedure for exporting customized log archives into external security information and event management systems involves the following operational phases:
- Navigate to the reporting dashboard and access the advanced query builder to define the specific log parameters and time boundaries required for the export.
- Select the destination connector corresponding to the enterprise security information and event management system from the pre-configured integration directory.
- Configure the automated transformation schema to map hyperglance metadata attributes to the receiving system’s standard event taxonomy.
- Establish the transmission schedule, choosing between real-time streaming for active incidents or batch export for scheduled compliance archiving.
- Execute a dry-run test transmission to validate payload delivery, ensuring that encryption protocols and authentication tokens function correctly before finalizing the pipeline.
Historical State Playback Mechanics
Understanding an unexpected outage often requires traveling backward in time to inspect the exact configuration state of the infrastructure right before the failure occurred. Historical state playback acts as a digital flight data recorder for cloud environments, capturing continuous snapshots of every resource configuration, relationship mapping, and policy state. Forensic investigators utilize this time-travel capability to reconstruct the chronological sequence of events that led to a catastrophic system failure, moving beyond static post-incident assumptions.
Consider a scenario where an unexpected cascading failure brings down a major e-commerce checkout service on a global scale. Traditional logs might only show the final crash, leaving engineers baffled as to why the application servers suddenly lost connectivity. By leveraging historical state playback, an investigator can rewind the infrastructure timeline by precisely forty-five minutes to observe an unauthorized security group modification applied during an off-hours deployment.
The playback visualizes the exact moment an administrative port was closed inadvertently, cutting off internal microservice communication and triggering the outage. This definitive root cause analysis prevents recurrence through targeted procedural updates.
Operational resilience is achieved not by preventing every failure, but by reducing the time required to understand, isolate, and resolve anomalies through intelligent data interrogation.
By reviewing the chronological delta between normal operations and the degraded state, teams gain deep insights into architectural fragilities. The query engine indexes these historical snapshots efficiently, ensuring that searching through weeks of past infrastructure states takes mere seconds. This capability transforms forensic investigation from a tedious, speculative endeavor into an exact science grounded in verifiable chronological evidence.
Final Review: Hyperglance.com Product Features Reporting
Source: hyperglance.com
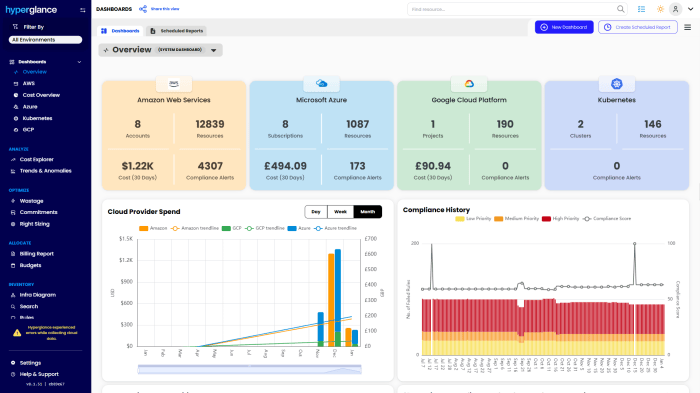
Ultimately, mastering these advanced analytical capabilities unlocks a future where uncertainty is replaced by absolute operational mastery. As teams leverage automated compliance, deep financial attribution, and lightning-fast troubleshooting engines, the horizon of digital possibility expands exponentially. Embrace this journey toward ultimate cloud intelligence and watch your organization soar to remarkable new heights of efficiency and growth.
