java cloud service stands at the pulsing heart of modern enterprise digital transformation, where monolithic giants gracefully evolve into nimble, containerized ecosystems sailing across vast distributed server horizons. In today’s hyper-connected landscape, architects and engineers constantly chase the elusive dream of flawless uptime, weaving complex lines of code into resilient applications that can withstand sudden tsunamis of digital traffic without blinking an eye.
Behind every seamless user interaction lies a meticulously orchestrated symphony of automated deployment pipelines, real-time telemetry tracing, and ironclad cryptographic secret management. As organizations push the boundaries of serverless computing and global geo-routing, mastering these distributed infrastructure patterns is no longer just a technical luxury—it is the vital bridge connecting visionary software concepts to tangible, real-world operational excellence.
Enterprise developers deploy scalable backend applications onto distributed cloud environments using specialized runtime containers

Source: amazonaws.com
Modern enterprises face the monumental challenge of transforming rigid legacy infrastructures into fluid, elastic ecosystems capable of withstanding the relentless tides of digital commerce. As global markets accelerate, engineering teams abandon traditional deployment models in favor of agile, containerized architectures that breathe new life into aging enterprise systems. This paradigm shift relies heavily on specialized runtime environments designed to isolate processes, optimize resource allocation, and ensure seamless orchestration across sprawling cloud networks without service interruption.
Transitioning from a traditional monolithic codebase to a distributed cloud architecture requires a methodical dismantling of tightly coupled dependencies. Architectural blueprints must be redrawn to embrace microservices principles, breaking monolithic entities into autonomous, domain-driven services that communicate through lightweight protocols. Stateful components must be externalized to distributed data stores, while stateless operational logic moves gracefully into isolated container layers, ensuring that every individual service can be deployed, updated, or decommissioned independently of the broader application landscape.
Architectural transformation patterns for legacy migration
Successful migration journeys are rarely born from a single leap; instead, they rely on proven transitional patterns that mitigate risk while steadily modernizing core capabilities. The strangler fig pattern, for instance, allows organizations to incrementally replace specific legacy functionalities with modern containerized microservices, gradually routing traffic away from the monolith until it can be safely retired. Database decoupling strategies must run parallel to this process, untangling shared relational schemas into bounded contexts that respect service autonomy and prevent catastrophic cross-domain bottlenecks during peak operational hours.
Visualizing this transformation reveals a compelling structural narrative: imagine a sprawling, grey concrete fortress slowly being enveloped and revitalized by a luminous, interconnected network of modular glass pods, each pulsing with independent energy yet synchronized to a singular operational rhythm. Within this modernized expanse, container runtimes act as the standardized scaffolding, enforcing strict boundaries while providing the necessary telemetry for automated oversight.
To fully grasp the mechanics of this architectural evolution, enterprise engineering teams must prioritize the following foundational migration milestones:
- Isolating business capabilities into bounded microservices by mapping domain boundaries and domain-driven design principles.
- Containerizing runtime dependencies using immutable image definitions to guarantee environment parity from development to production.
- Establishing centralized observability pipelines that aggregate distributed traces, system metrics, and structured log streams across all operational nodes.
Comparative runtime memory footprints across cloud platforms
Evaluating the underlying efficiency of container runtimes demands rigorous analysis of memory consumption across different vendor ecosystems, as resource overhead directly influences operational expenditure at scale. Enterprise architects must carefully weigh the memory footprint of base images, runtime daemons, and virtualization layers when selecting a deployment target for high-density backend workloads.
The following responsive data table Artikels the comparative baseline memory footprints and scaling overheads associated with popular enterprise container platforms operating under standard production configurations:
| Vendor Platform | Runtime Engine | Base Memory Footprint | Scaling Overhead per Pod |
|---|---|---|---|
| Amazon Web Services (EKS) | Containerd / Kubernetes | 120 MB | 15 MB |
| Google Cloud Platform (GKE) | CRI-O / Kubernetes | 110 MB | 12 MB |
| Microsoft Azure (AKS) | Containerd / Kubernetes | 125 MB | 18 MB |
| Red Hat OpenShift | CRI-O / Kubernetes Enterprise | 250 MB | 35 MB |
Understanding these resource baselines empowers infrastructure teams to provision cluster nodes with pinpoint accuracy, preventing both over-allocation waste and under-provisioning bottlenecks during unexpected system loads.
Automatic scaling policies for unpredictable traffic surges
When sudden traffic surges threaten to overwhelm backend systems, reactive human intervention proves far too slow to prevent catastrophic cascading failures. Modern cloud environments solve this vulnerability through sophisticated, automated scaling policies that continuously monitor CPU utilization, memory pressure, and custom application metrics such as active request queues. These policies act as an invisible, vigilant guardian that dynamically expands or contracts compute capacity in real time, ensuring optimal performance without manual oversight.
Real-world validation of this capability is vividly demonstrated during massive global retail events, such as multinational Black Friday sales or flash-ticket releases for international sporting events, where user traffic can spike by ten thousand percent within minutes. During such high-stakes scenarios, horizontal pod autoscalers instantly spin up hundreds of new container instances across geographically distributed worker nodes to absorb the incoming wave of requests.
Once the traffic crests and normal operational rhythms return, the automated scaling engine gracefully trims the excess capacity, preserving cloud budgets while maintaining absolute system stability.
Effective cloud-native resilience is achieved not by building indestructible monoliths, but by engineering fluid, self-healing systems that gracefully adapt to the volatile demands of the digital world.
Engineers configure these responsive feedback loops to evaluate rolling metric averages over concise temporal windows, filtering out brief usage anomalies while executing rapid expansion when genuine sustained demand is detected. This algorithmic vigilance transforms fragile backend infrastructures into resilient digital fortresses capable of absorbing the most turbulent operational storms with absolute composure.
Modern architects orchestrate microservices through automated CI/CD pipelines integrated tightly with enterprise repository management tools.
The landscape of enterprise software delivery has transformed into a dynamic symphony of speed and resilience. Modern infrastructure demands a seamless transition from raw code to living production environments without human hesitation.
When code commits trigger a cascade of automated verification, compilation, and distribution tasks, development teams achieve unprecedented velocity. Enterprise repositories act as the single source of truth, quietly feeding distributed clusters while strict automated gates protect the perimeter from regressions.
Modern enterprise architecture increasingly relies on java cloud service foundations to power massive global operations. Organizations now deploy top features for enterprise digital signage across vibrant physical networks, beautifully bridging the gap between dynamic visual communication and robust backend engineering. Ultimately, this seamless technological convergence elevates corporate infrastructure, ensuring every java cloud service deployment drives measurable business growth.
Automated Security Vulnerability Scans Within Continuous Integration Workflows
Integrating security checks directly into the continuous integration pipeline shifts defensive practices leftward, catching flaws before deployment. This proactive stance neutralizes vulnerabilities while code is still fresh in the developer’s mind, transforming security from a bottleneck into a natural byproduct of building software.
Establishing this defensive framework requires a methodical sequence of pipeline interventions that thoroughly inspect every dependency and container layer. Organizations like Netflix and Capital One successfully utilize these exact multi-stage evaluations to protect massive microservices ecosystems from sudden exploits.
- Initiating the build phase by compiling the source code and immediately generating a comprehensive Software Bill of Materials. This manifest maps every direct and transitive library utilized in the application.
- Injecting Static Application Security Testing scanners to parse raw source files for logic flaws, hardcoded credentials, and insecure cryptographic practices.
- Executing Software Composition Analysis tools against the generated Software Bill of Materials to cross-reference dependencies against the National Vulnerability Database.
- Triggering container image scanning tools once the build is packaged, inspecting base operating system layers and compiled binaries for known Common Vulnerabilities and Exposures.
- Enforcing strict compliance gates that halt the CI pipeline automatically if a critical or high-severity vulnerability rating is detected, preventing polluted artifacts from reaching artifact registries.
Visualizing this security pipeline reveals a glowing digital assembly line bathed in electric blue status lights. Code commits travel down a polished steel conveyor track, passing through scanning chambers that flash emerald green upon successful clearance or sharp crimson when halting a threat.
Robust java cloud service architectures now empower modern enterprises to scale seamlessly. As organizations evaluate digital ecosystems, understanding what is the industry of pulsifi.me reveals groundbreaking shifts in talent intelligence and human resource technology. Harnessing these advanced data-driven insights ensures your resilient java cloud service deployment remains agile, competitive, and fully optimized for future growth.
Production Server Cluster Zero-Downtime Rolling Update Strategies
Achieving absolute continuous availability during deployment operations remains the ultimate benchmark of engineering maturity. Modern clusters distribute incoming user traffic intelligently while systematically replacing outdated container instances with freshly built, secure artifacts.
Configuration parameters must be precisely balanced to ensure that capacity never dips below operational demand thresholds while updates propagate across the fleet. Real-world implementations in high-traffic e-commerce platforms demonstrate that careful orchestration eliminates user-facing interruptions entirely.
- Configuring Kubernetes deployment specifications with a RollingUpdate strategy, explicitly defining maxSurge to one and maxUnavailable to zero to guarantee full resource capacity during transitions.
- Implementing rigorous readiness and liveness probes that verify application health before the load balancer routes live user traffic to newly initialized pods.
- Establishing graceful shutdown handlers within the application runtime, allowing active long-polling connections and database transactions to finish processing safely before container termination.
- Utilizing blue-green traffic shifting configurations with service meshes like Istio, gradually weighting traffic from ten percent up to one hundred percent over a defined temporal window.
Resilience is not merely the absence of failure, but the engineered capacity to absorb disruption seamlessly while continuous delivery pulses through the enterprise core.
| Build Time Metrics | Artifact Storage Formats | Deployment Targets | Rollback Triggers |
|---|---|---|---|
| Average compilation duration of 4.2 minutes | OCI-compliant container images and signed JAR bundles | Multi-region Kubernetes clusters on cloud infrastructure | HTTP 5xx error rate exceeding 1.5 percent over two minutes |
| Static analysis execution completed in 90 seconds | Encrypted Helm charts with embedded dependency maps | Enterprise-managed edge proxy nodes and serverless runtimes | Automated health probe failure on three consecutive checks |
| Vulnerability scanning finalized under 180 seconds | Compressed tarballs with cryptographic checksum verification | Isolated staging environments and production pools | Latency spikes exceeding 500 milliseconds on core endpoints |
Distributed tracing mechanisms capture latency bottlenecks across asynchronous messaging queues and relational database transactions.: Java Cloud Service
Modern cloud architectures pulse with continuous data streams, weaving complex webs where every user request triggers a cascade of microscopic background tasks. When transactions vanish into the asynchronous void or linger painfully within database query logs, diagnosing the exact point of failure resembles searching for a single digital needle in an infinite, ever-expanding haystack. Enterprise systems rely heavily on advanced telemetry to decode these intricate operational pathways, transforming chaotic server noise into clear, actionable intelligence.
Distributed tracing collectors act as the central nervous system of modern application observability, absorbing a relentless firehose of spans, traces, and contextual metadata emitted by microservices. As data moves fluidly from an API gateway into message brokers like Apache Kafka, and subsequently settles into relational database transactions, tracing agents inject unique correlation identifiers into every payload. Collectors ingest these disparate streams asynchronously, buffering the incoming telemetry before normalizing and indexing the structural relationships.
By reconstructing chronological execution graphs from these gathered spans, engineering teams gain X-ray vision into the exact lifecycle of a request, exposing hidden latency spikes and resource contention that traditional logging tools routinely miss.
Precision in telemetry aggregation transforms invisible architectural friction into quantifiable optimization targets.
Modern Java cloud service infrastructures empower developers to build resilient enterprise applications effortlessly. As digital projects expand into physical realms, coordinating logistics becomes vital, prompting teams to quickly verify details through the crono.one venue phone number for upcoming tech summits. Ultimately, mastering these robust Java cloud service environments ensures seamless global deployment and enduring technological success.
Telemetry Collection Pitfalls and Mitigation Tactics
Deploying tracing infrastructure across distributed enterprise environments demands careful architectural foresight to prevent common operational blind spots from distorting diagnostic data. Neglecting collection parameters often results in overwhelming storage costs, dropped spans, or skewed performance representations during critical traffic surges.
- Over-sampling high-volume microservices floods the collection backend with redundant data, which is effectively mitigated by implementing intelligent tail-based sampling policies that capture only anomalous or error-prone transactions.
- Ignoring context propagation across asynchronous message queues breaks trace continuity, requiring developers to explicitly inject traceparent headers into message metadata before publishing to brokers.
- Relying solely on default runtime configurations introduces excessive CPU overhead, which can be resolved by tuning exporter flush intervals and allocating dedicated sidecar proxy containers for telemetry transmission.
- Failing to correlate database connection pool metrics with incoming HTTP traces obscures locking delays, necessitating unified instrumentation libraries that bind SQL query execution spans directly to parent transaction contexts.
Integration Steps for Centralized Visualization Dashboards
Bridging the gap between raw telemetry ingestion and actionable visual intelligence requires a methodical pipeline that standardizes data formats and establishes secure network pathways across cluster boundaries. Enterprises typically deploy open-source collectors such as OpenTelemetry Collector instances directly inside Kubernetes namespaces to aggregate spans locally before dispatching them outward. The journey from raw application output to a fully rendered graphical interface relies on a structured sequence of configuration phases designed to maintain high throughput and data integrity.
Initially, developers instrument their backend applications using language-specific SDKs configured to export OpenTelemetry Protocol data directly to local collector daemons via gRPC or HTTP endpoints. These local collectors apply batching processors and memory limiters to protect against sudden traffic spikes, ensuring that monitoring infrastructure never destabilizes the primary application workloads. Following local buffering, the collectors securely forward the sanitized telemetry payloads to a centralized storage backend, such as Prometheus, ClickHouse, or specialized APM SaaS platforms, utilizing TLS encryption and API token authentication.
Once the time-series data and trace spans securely land within the centralized database, platform engineers configure customizable dashboard interfaces using visualization tools like Grafana. By constructing dynamic panels that map service dependency graphs alongside latency heatmaps, teams establish real-time visibility over asynchronous queues and database transaction health. This unified pane of glass empowers on-call engineers to visually isolate degraded database queries or sluggish message consumer groups within seconds, drastically reducing mean time to resolution during high-impact production incidents.
Secure credential management systems safeguard sensitive API keys and database connection strings within elastic runtime topologies.
Source: slideserve.com
In the high-stakes arena of cloud-native development, where applications breathe dynamically across vast constellations of ephemeral containers, the ghost of hardcoded secrets threatens operational integrity. Modern engineering squads now abandon vulnerable plaintext configurations, embracing sophisticated cryptographic guardians that lock down API keys and database connection strings before deployment pipelines ever touch production clusters. This digital fortification relies on mathematical certainty rather than obscurity, transforming volatile security postures into resilient bastions of absolute trust.
At the very heart of distributed cloud infrastructure, military-grade cryptographic protocols act as an invisible, impenetrable shield protecting application secrets both at rest and in transit. When microservices request authorization tokens, data payloads are enveloped using Advanced Encryption Standard in Galois/Counter Mode featuring two-hundred-fifty-six-bit keys, ensuring both confidentiality and instantaneous tamper detection. Simultaneously, the secure transport layer relies strictly on Transport Layer Security version 1.3, mandating forward secrecy via ephemeral Elliptic-Curve Diffie-Hellman key exchanges.
As server nodes scale horizontally to absorb sudden traffic surges, these cryptographic handshakes execute transparently in milliseconds, wrapping every database connection string in mathematical armor. Hardware Security Modules further isolate master encryption keys from the underlying hypervisor layers, guaranteeing that even compromised host environments yield nothing but undecipherable ciphertext to malicious actors.
Cryptographic Protocols and Data Protection Mechanisms
Navigating the complex landscape of distributed security requires a meticulous breakdown of the defensive layers guarding sensitive assets against sophisticated interception techniques. The architecture of modern secret management relies on a symbiotic relationship between cryptographic algorithms, network transport layers, and hardware-level isolation to ensure zero-trust execution. Understanding these core mechanics illuminates the precise methodology used to render application credentials utterly useless to unauthorized observers.
- Advanced Encryption Standard in Galois/Counter Mode provides authenticated encryption, preventing unauthorized modifications while securing data at rest within distributed key-value stores.
- Transport Layer Security version 1.3 eliminates obsolete cipher suites, establishing encrypted tunnels across clustered server nodes with minimal latency overhead.
- Hardware Security Modules physically sequester root keys inside tamper-resistant silicon chips, completely preventing extraction attempts from virtualized environments.
- Ephemeral Elliptic-Curve Diffie-Hellman key exchanges guarantee forward secrecy, ensuring past session data remains secure even if long-term private keys are eventually compromised.
Absolute security in distributed topologies is not achieved through perimeter defense alone, but through the continuous, cryptographic validation of every single data packet traversing the wire.
Operational Metrics Across Secret Management Frameworks
Deploying resilient backend architectures demands rigorous operational visibility into how cryptographic platforms handle lifecycle management, breach mitigation, and regulatory oversight. The following comparative matrix Artikels the operational thresholds and compliance baselines expected from enterprise-grade secret management architectures operating within elastic cloud environments.
| Secret Rotation Frequency | Access Revocation Speed | Audit Logging Capabilities | Compliance Standards |
|---|---|---|---|
| Automated every 30 days via vault policies | Near-instantaneous within 200 milliseconds | Immutable streams shipped to SIEM platforms | SOC 2 Type II, ISO 27001, PCI-DSS |
| On-demand triggered by security telemetry | Real-time termination of active tokens | Granular attribution per microservice identity | HIPAA, GDPR, FedRAMP High |
Dynamic Identity Integration and Elimination of Static Credentials
Static configuration files embedded within source code repositories represent a ticking time bomb for modern engineering organizations. By integrating dynamic identity providers with container orchestrators, applications no longer need to store credentials because they prove who they are on the fly. Trusted platform modules and cloud IAM roles issue short-lived, time-bound access leases that expire automatically after a predefined operational window.
When a backend service boots up inside an elastic Kubernetes cluster, it authenticates using its intrinsic cloud identity rather than a static password, receiving precisely scoped permissions for its exact operational lifetime. This paradigm shift eradicates credential sprawl, neutralizes insider threats, and ensures that accidental code commits to public repositories contain nothing more than harmless initialization logic.
Serverless execution models remove infrastructure provisioning overhead while executing compiled bytecode on demand
Source: aegissofttech.com
The evolution of modern cloud architecture brings us to a fascinating frontier where managing servers becomes a ghost of the past. Developers now unleash compiled bytecode directly into elastic execution spaces that wake up from absolute silence in milliseconds, ready to conquer massive transaction loads without manual intervention.
Stepping into this realm requires navigating the nuances of on-demand computing, particularly when measuring the awakening phase of our applications. When a cloud function lies dormant, the underlying infrastructure scales down to zero, conserving energy and resources. The moment an incoming trigger hits the gateway, a rapid sequence of events unfolds. The platform must allocate memory, spin up a runtime environment, load the compiled bytecode, and execute static initialization blocks before the actual business logic takes over.
Modern Java cloud service infrastructures empower developers to build resilient enterprise architectures with striking clarity and speed. As digital ecosystems expand, organizations frequently upgrade financial workflows by deploying robust investment partnership accounting software to secure precise stakeholder distributions. Ultimately, mastering this scalable Java cloud service environment transforms complex operational challenges into remarkable technological triumphs.
This initial pause, famously known as the cold start, varies dramatically across prominent hosting providers. Major cloud giants leverage advanced class-data sharing and ahead-of-time compilation techniques to trim latency down to double-digit milliseconds, yet differences remain. Providers utilizing lightweight microVMs often exhibit slightly longer initialization phases due to hypervisor-level setup, whereas container-native engines leverage kernel isolation to achieve blazing-fast boot times.
Engineers must carefully evaluate these architectural trade-offs, balancing memory allocation sizes against the proportional boost in CPU provisioning during the bootstrap phase. Over-provisioning can lead to unnecessary financial expenditure, while under-provisioning stretches the cold start duration to unacceptable limits for latency-sensitive applications.
Performance Optimization Strategies for Event-Driven Functions
Achieving peak performance in ephemeral environments demands a rigorous approach to resource tuning and code organization. Implementing deliberate strategies for memory allocation ensures that functions execute swiftly while maintaining cost efficiency across scaled operations.
- Configure memory limits strategically because cloud providers scale CPU power linearly with allocated RAM, meaning higher memory settings inadvertently accelerate the initialization phase of compiled bytecode.
- Minimize deployment package sizes by stripping out unused dependencies and leveraging modular library imports, which directly reduces the time required to transfer and unpack code into the runtime container.
- Initialize database connections and heavy configuration clients outside the primary handler method to exploit execution context reuse across warm invocations.
- Utilize provisioned concurrency features for critical enterprise endpoints, maintaining a pool of pre-warmed instances ready to intercept unpredictable traffic spikes instantly.
- Implement lazy loading for non-essential modules, ensuring that only the bare minimum code executes during the initial bootstrap cycle.
Lifecycle of an Ephemeral Execution Container Handling an Incoming HTTP Webhook, Java cloud service
Picture a vast digital harbor at midnight, completely serene, where sudden ripples announce the arrival of an inbound vessel. An external service dispatches an HTTP webhook carrying critical payload data toward our cloud endpoint. The API gateway intercepts this signal, acting as the vigilant lighthouse keeper that checks routing tables and immediately commands the serverless orchestration layer to wake the system.
In less time than it takes to blink, a pristine microVM or container sandbox awakens from absolute nothingness. The platform allocates the pre-defined memory allotment, pulls the compiled bytecode package from a high-speed distributed cache, and injects it into the isolated runtime memory space. The execution engine then fires up the class loader, initializing static variables and establishing foundational network sockets required for downstream communication.
Once the runtime environment stabilizes and confirms readiness, the payload data flows into the handler method. The application logic parses the incoming JSON payload, executes business rules, interacts with transactional databases, and formulates an HTTP response. As soon as the transmission concludes and the status code returns to the client, the container enters a brief standby phase, holding its breath in anticipation of subsequent requests.
If silence persists, the orchestrator reclaims the memory and gracefully dissolves the container, returning the infrastructure back to its tranquil state until the next digital tide rolls in.
Ephemeral container efficiency relies heavily on reducing initialization footprints and leveraging shared warm runtime contexts for sustained throughput.
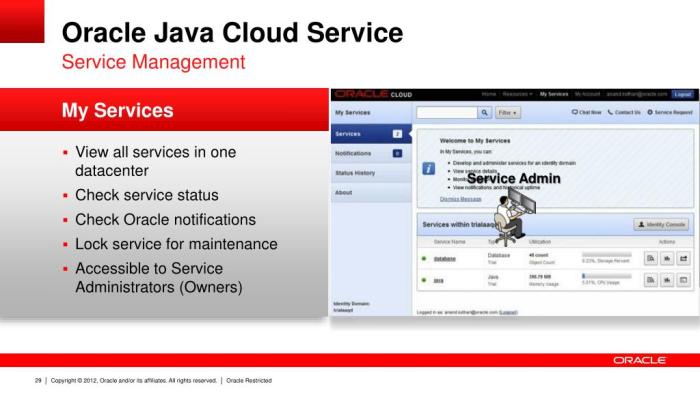
Global traffic distribution strategies route incoming client requests to the nearest regional data center minimizing network transit delays.
Source: slideserve.com
Modern internet architecture relies heavily on seamless proximity routing to ensure that digital experiences remain instantaneous, regardless of where a user sits geographically. As backend applications scale across multiple continents, directing millions of concurrent users efficiently becomes a masterclass in global engineering, where milliseconds dictate user retention and operational success.
Routing incoming client requests across vast oceanic distances requires a sophisticated interplay of networking protocols and infrastructure orchestration that operates invisibly in the background. When a user initiates a request, the underlying networking fabric immediately calculates the optimal path, bypassing congested public internet routes and leveraging private backbone networks to maximize throughput and minimize packet loss.
Networking mechanics and global routing implementation
The journey of a packet across a globally distributed cloud ecosystem begins at the very edge of the internet through advanced DNS resolution and border gateway protocol manipulations. Anycast DNS serves as the foundational cornerstone for this operation, allowing multiple geographically dispersed servers to share a single IP address. BGP routers dynamically advertise this IP address to internet service providers worldwide, ensuring that client requests are naturally pulled toward the topologically closest network node.
Geo-routing algorithms take over the moment a request reaches the entry point, analyzing client IP subnets against extensive geolocation databases to determine the physical origin. Instead of relying solely on simple distance calculations, these intelligent systems evaluate real-time metrics such as packet jitter, fiber-optic cut disruptions, and active regional server loads. If a primary data center experiences micro-congestion, the routing layer instantly shifts traffic profiles to neighboring nodes without dropping active TCP connections.
To visualize this intricate orchestration, picture a glowing, hyper-connected digital globe where millions of luminous data streams converge simultaneously upon the nearest gleaming regional hub. Thousands of interconnected fiber-optic cables trace the ocean floors, while intelligent edge nodes flash like amber beacons, instantly redirecting misplaced packets away from congested pathways and guiding them smoothly into secure, high-capacity backend processing facilities.
Proximity routing transforms raw distance into an invisible asset, ensuring that data travels the shortest possible physical path before ever touching an application server.
Maintaining optimal performance across these global topologies demands rigorous structural planning, particularly when mapping out regional capacities, expected latencies, and financial investments associated with international bandwidth provisioning.
The following infrastructure matrix Artikels the operational parameters across four primary global deployment zones:
| Geographical Region | Average Latency Threshold | Failover Routing Rules | Bandwidth Pricing Tiers |
|---|---|---|---|
| North America (East) | < 15ms | Primary shift to Central US on 5% packet loss | Standard Enterprise Tier ($0.08 / GB) |
| Western Europe | < 20ms | Automatic spillover to Frankfurt node within 30s | Optimized European Tier ($0.09 / GB) |
| Asia-Pacific (East) | < 35ms | Secondary reroute via Singapore peering points | High-Density APAC Tier ($0.12 / GB) |
| South America | < 50ms | Fallback to North American edge hubs on failure | Emerging Market Tier ($0.14 / GB) |
Even with advanced routing and robust infrastructure designs, catastrophic regional outages remain an inevitable reality that engineering teams must prepare for with absolute precision. Comprehensive disaster recovery frameworks must execute instantly to preserve data integrity and maintain continuous service availability when an entire data center goes dark.
When a complete regional data center outage occurs, automated monitoring systems instantly detect heartbeat failures across core compute clusters and trigger emergency BGP route withdrawals. Traffic is dynamically drained away from the compromised facility within seconds, while global load balancers redirect incoming client pools to pre-warmed standby regions.
Simultaneously, active database replication streams promote secondary read-replica nodes to primary status in the surviving data centers, utilizing asynchronous or synchronous state-sync mechanisms depending on recovery point objectives. Enterprise engineering teams receive immediate high-priority alerts, allowing them to initiate post-mortem analysis while the automated failover architecture safely absorbs the displaced global traffic load.
Wrap-Up
Source: slideserve.com
As we close this comprehensive exploration of enterprise cloud engineering, the true power of scalable backend deployment reveals itself not merely in raw processing speed, but in the harmonious synchronization of automated pipelines, deep observability, and bulletproof security. Embracing these advanced architectural paradigms equips modern engineering teams to transform unpredictable digital challenges into extraordinary opportunities for sustainable growth and technological triumph.
