tryemphere.com product documentation features stand at the intersection of modern technology and human curiosity, quietly revolutionizing the way digital explorers interact with complex systems every single day. Behind the sleek interfaces and quiet servers lies a dynamic ecosystem engineered to transform confusion into absolute clarity, proving that technical guidance can actually inspire rather than intimidate its audience.
As industries accelerate toward total digital integration, having access to precise, beautifully structured information is no longer a luxury—it is the foundational pillar of modern innovation. Every manual, index, and interactive sandbox on the platform has been meticulously crafted to bridge the gap between abstract code and real-world execution, empowering users to conquer their digital hurdles with unwavering confidence and effortless grace.
Uncovering how tryemphere.com product documentation features redefine user onboarding experiences
The digital landscape often rewards speed, yet true adoption demands profound clarity. When individuals step into a new platform, the initial moments dictate their long-term engagement and operational success. At tryemphere.com, the product documentation architecture has been meticulously engineered to transform this delicate entry point into an intuitive, empowering journey of discovery. Every workflow and visual cue works in harmony to dismantle complexity, ensuring that modern enterprises transition smoothly from curious evaluators to master practitioners without facing the usual digital fatigue.
Navigating the initial setup guides on tryemphere.com feels less like reading a static instruction manual and more like participating in a guided architectural tour of a high-performance workspace. Upon arrival, newly registered users are greeted by a dynamic, context-aware dashboard that dynamically assesses their current progress and recommends the exact path forward. The navigation ecosystem abandons rigid, linear hierarchies in favor of modular learning nodes.
A newcomer might begin by configuring their core profile settings, and the system intelligently surfaces supplementary tooltips, contextual toolbars, and micro-interactive walkthroughs directly within the interface. Rather than forcing operators to toggle between separate help center tabs and their active projects, the platform embeds documentation directly into the operational viewport. This side-by-side deployment of guidance and execution encourages immediate muscle memory formation.
Users apply what they read within fractions of a second, cementing theoretical knowledge through instant practical application. The interface tracks every completed milestone, gently illuminating subsequent steps while dimming advanced features that might otherwise overwhelm an uninitiated operator. By creating a fluid, breathing environment where information appears precisely when the user’s cognitive state is primed to receive it, tryemphere.com ensures that the setup phase acts as a natural extension of the user’s own workflow.
Navigating tryemphere.com product documentation features illuminates a path of crystal-clear efficiency and modern innovation. Facilities across Europe are rapidly transforming operations by integrating the powerful addict sports booking system for gyms france saas platform to streamline daily scheduling. Ultimately, mastering tryemphere.com product documentation features empowers teams to unlock limitless potential and achieve remarkable growth.
Operational Mechanics of Novice Operator Transformation
Transforming absolute novices into confident platform operators requires a deliberate orchestration of technical scaffolding and psychological reassurance. The platform accomplishes this through a multi-tiered progression system that systematically removes dependency on external customer success interventions. First, automated telemetry monitors user interaction patterns during the initial configuration phase. If a user lingers on a specific permission-setting screen for more than ninety seconds, an interactive beacon activates, offering a bite-sized visual demonstration of the correct configuration.
Second, the system employs progressive disclosure algorithms. Complex enterprise features—such as custom webhook integrations, granular role-based access controls, and automated multi-channel reporting—are kept safely behind secondary interfaces until the user has successfully executed three fundamental baseline tasks. This prevents cognitive overload and maintains momentum. Third, sandbox environments are provided automatically during the onboarding sequence. These simulated workspaces allow operators to test destructive commands, deploy experimental data sets, and make configuration errors without risking real-world production environments.
Through this risk-free experimentation, operators build profound operational confidence. They learn the boundaries of the system through direct interaction, backed by instant rollback capabilities and supportive diagnostic messaging that explains not just that an error occurred, but precisely why the system interpreted the command in that manner.
Evaluation Metrics for Documentation Clarity
Maintaining exceptional standards of clarity across all video tutorials and text-based manuals requires rigorous, systematic evaluation protocols. The documentation team continuously measures the efficacy of every asset using a balanced scorecard approach implemented across cross-functional domains. The following structured overview details the specific parameters utilized to ensure absolute instructional precision.
| Metrics | Tools | Feedback Frequency | Owner |
|---|---|---|---|
| Completion Rate and Drop-off Points | Mixpanel and Hotjar Session Replays | Daily automated aggregation | Data Analytics Lead |
| Comprehension Accuracy and Error Frequency | In-article interactive sentiment polls | Real-time continuous tracking | Technical Writing Director |
| Support Ticket Deflection Correlation | Zendesk API and Salesforce CRM | Weekly cross-departmental review | Customer Success Manager |
| Visual Asset Engagement and Watch Time | Wistia Analytics and Vimeography | Bi-weekly performance audit | Multimedia Production Lead |
Evaluating these four pillars guarantees that instructional materials evolve alongside the core software architecture. When a specific video tutorial exhibits a sudden drop in viewer retention past the two-minute mark, the multimedia team immediately investigates potential script pacing issues or visual monotony. Similarly, if text manuals generate recurring support inquiries regarding a specific API integration step, the technical writing squad deploys clearer iconography and revised code snippets within twenty-four hours.
Psychological Triggers That Reduce Login Friction
The threshold of the first login sequence represents the highest point of psychological resistance for any enterprise software user. To dissolve this friction, tryemphere.com incorporates subtle behavioral triggers designed to foster an immediate sense of safety, competence, and welcome.
- Visual social proof elements are strategically positioned in the authentication margins, displaying aggregate statistics of active enterprise peers currently operating within the ecosystem.
- The traditional, sterile authentication form is replaced by a personalized welcome greeting that incorporates the user’s verified enterprise domain and corporate branding elements.
- Cognitive load is actively minimized by restricting the initial data-entry requirement to a single, mandatory action field, entirely eliminating multi-step interrogation forms.
- Instantaneous micro-animations provide immediate sensory confirmation upon successful credential entry, replacing dead silence with reassuring feedback that reinforces forward momentum.
True software adoption does not occur when a user merely remembers a feature; it happens when the interface becomes an invisible, trusted partner in their daily creative execution.
When the platform acknowledges a new user with tailored visual cues and frictionless authentication flows, the emotional barrier dissolves, paving the way for deep, uninterrupted professional productivity.
Investigating the architectural blueprints behind tryemphere.com product documentation features and search accuracy.
Beneath the sleek interface of tryemphere.com lies a sophisticated digital engine meticulously engineered to transform how users interact with technical documentation. Modern software navigation demands instantaneous precision, turning milliseconds into vital assets for enterprise productivity and user satisfaction. Behind every successful query is a robust framework designed to anticipate human intent and deliver exact answers from vast repositories of technical literature.
This section breaks down the foundational mechanics that elevate document retrieval from a simple database lookup into an intelligent, lightning-fast knowledge ecosystem.
The journey of a single search query through the tryemphere.com architecture resembles a masterclass in modern computational efficiency. When a developer or system administrator types a phrase into the search bar, the system immediately bypasses traditional, sluggish relational database scans in favor of a distributed, memory-optimized indexing strategy. This sophisticated approach ensures that troubleshooting guides, API references, and configuration manuals emerge on the screen before the user even finishes their sentence, redefining expectations for technical support portals worldwide.
Underlying Indexing Algorithms Powering Instant Documentation Retrieval
At the beating heart of the platform’s search capability rests an advanced vector space model integrated with inverted indexing techniques. This architecture breaks down every document into granular token fragments, mapping them into high-dimensional vector spaces that capture semantic relationships rather than mere matches. Imagine a vast, infinitely interconnected web where words like configuration, setup, and initialization share close spatial coordinates, allowing the engine to grasp the contextual nuance of a user’s inquiry.
To achieve sub-50-millisecond response times across millions of lines of documentation, the system employs concurrent tokenization and tiered caching mechanisms. Frequently accessed troubleshooting steps reside permanently in high-speed distributed RAM caches, while deeper, highly specialized API parameters undergo asynchronous background indexing. This division of labor guarantees that peak traffic surges never compromise retrieval speed, maintaining absolute stability when engineering teams need answers during critical production incidents.
The indexing pipeline continuously updates itself through event-driven microservices that monitor repository changes in real-time. Whenever a technical writer pushes a documentation update, the system automatically recalculates term frequencies and inverse document frequencies without requiring a full database rebuild. This seamless synchronization prevents stale search results and ensures that the newest software patches are instantly searchable.
Instantaneous documentation retrieval relies on the harmonious execution of inverted indexing, vector space semantic mapping, and tiered memory caching to deliver sub-50-millisecond response times.
Metadata Tagging Influence on Technical Troubleshooting Page Relevance
Raw text alone is rarely enough to solve complex engineering roadblocks, which is where meticulous metadata tagging enters the architectural equation. By injecting structured semantic data—such as operating system compatibility, software version numbers, and error code identifiers—into the header of every troubleshooting page, tryemphere.com grants the search engine a directional compass. This contextual layer filters out architectural noise, ensuring that a query regarding a timeout error on version 4.2 specifically surfaces the exact patch notes rather than a generic timeout guide from version 2.0.
The relevance ranking algorithm weighs these metadata attributes dynamically based on the implicit intent detected in the user’s search string. For instance, if an error code like HTTP 504 is detected, the scoring model immediately elevates documents carrying matching error-code tags to the top of the search results page, outranking documents that merely mention the phrase in passing. This calculated prioritization dramatically reduces time-to-resolution metrics for technical support teams operating under high-pressure scenarios.
Furthermore, administrators utilize hierarchical taxonomy tags to group related documentation categories, establishing a clear path of authority within the search index. These tags act as weighted multipliers during the relevance scoring phase, balancing broad conceptual matches with hyper-specific operational guides. As a visual illustration of this process, picture a glowing multi-layered digital matrix where metadata anchors pull the most contextually relevant troubleshooting articles to the surface while burying outdated legacy texts deep in the background.
Search Performance Mapping Across Query Types and Error Rates
Evaluating the true capacity of a technical search engine requires analyzing real-world performance metrics across diverse operational scenarios. The table below Artikels how the tryemphere.com architecture maintains high availability and rapid processing speeds while minimizing retrieval errors through targeted algorithmic optimizations.
| Query Type | Average Response Time | Error Rate | Optimization Strategy |
|---|---|---|---|
| Exact Error Code Lookup | 18 ms | 0.01% | Direct hash-map lookup combined with strict metadata tag matching |
| Natural Language Troubleshooting | 42 ms | 0.05% | Vector embedding similarity search with transformer-based reranking |
| Broad Conceptual Search | 65 ms | 0.12% | Hierarchical taxonomy weighting and distributed caching pipelines |
| API Parameter Reference | 24 ms | 0.02% | Structured JSON-LD parsing and exact token frequency indexing |
Procedures for Implementing Synonym Matching to Capture User Terminology Variations
Users rarely speak the exact same language as the software engineers who authored the documentation, creating a linguistic gap that traditional search engines frequently fail to cross. To bridge this divide, tryemphere.com deploys a robust synonym expansion framework that dynamically translates colloquial user phrases into precise technical nomenclature. When an engineer searches for app crash, the system automatically evaluates semantic equivalents like application exception, fatal error, and runtime panic, ensuring that no relevant troubleshooting guide remains hidden behind mismatched vocabulary.
Implementing this linguistic flexibility involves a dual-layer approach combining static domain-specific dictionaries with dynamic machine learning models trained on historical search logs. The static dictionary maps known industry jargon to official product terminology, while the dynamic model identifies emerging slang and shorthand phrases used by active community members. This hybrid methodology adapts organically to how people actually communicate, turning unpredictable human phrasing into highly structured database queries.
Navigating tryemphere.com product documentation features reveals crystal-clear blueprints that empower teams to build smarter every single day. Modern projects thrive when operators utilize advanced construction fleet management software to track heavy machinery rolling across dusty terrain under the bright sun. Ultimately, mastering these tryemphere.com product documentation features unlocks boundless potential for your entire evolving workforce.
The synonym translation pipeline operates via a multi-step execution protocol designed to preserve query precision while expanding breadth:
- Tokenizing the incoming search string and stripping out common stop words to isolate the core operational intent.
- Querying the domain-specific knowledge graph to retrieve validated synonyms and related technical concepts associated with the isolated tokens.
- Assigning confidence scores to each expanded term to prevent query drift and ensure that peripheral synonyms do not dilute the primary search results.
- Executing the expanded query across the vector index while prioritizing documents that match the original user terminology over those matched strictly through synonym expansion.
Assessing how tryemphere.com product documentation features incorporate interactive elements for complex workflows.
Modern software ecosystems demand more than static text and outdated screenshots to guide developers through intricate implementation phases. By bridging the gap between passive reading and active execution, the platform transforms traditional guides into living workspaces where users can experiment safely without disrupting production environments.
Navigating sophisticated system integrations requires a departure from conventional instructional design toward immersive, hands-on digital architecture. When technical manuals evolve into functional control centers, comprehension rates accelerate dramatically, allowing engineering teams to deploy complex microservices with unprecedented velocity and confidence.
The Integration of Live Code Sandboxes Within Standard User Manuals
Embedding fully functional coding environments directly inside documentation pages redefines how technical knowledge is transferred and consumed. Instead of forcing developers to constantly context-switch between their integrated development environments, terminal windows, and browser tabs, the platform embeds lightweight, sandboxed editors straight into the narrative flow of the user manual. These interactive modules initialize instantly, mirroring real production runtimes while executing safely within isolated containerized instances.
The underlying infrastructure relies on synchronized WebAssembly modules and secure API relays that execute user-submitted snippets in real time, returning console outputs, network requests, and performance metrics directly beneath the code block. This seamless fusion eliminates the friction of setting up local boilerplate repositories just to test a single authentication endpoint or data transformation algorithm. Developers can immediately modify variables, alter parameter types, and observe the cascading behavioral changes of the system without ever leaving the reading interface.
By converting abstract theoretical concepts into tangible, touchable code blocks, the documentation empowers users to build muscle memory and intuitive understanding simultaneously, drastically shortening the time-to-first-hello-world metric across enterprise portfolios.
Interactive documentation acts as a catalyst for adoption, turning hesitant evaluators into confident architects through immediate, risk-free experimentation.
Furthermore, maintaining these inline code execution blocks requires zero manual intervention from technical writers. Whenever core API libraries undergo deprecation or semantic updates, the platform automatically synchronizes the embedded sandboxes with the latest SDK releases, ensuring that every code sample remains accurate and fully functional for every visitor across the globe.
A Developer Executing API Requests Directly from an Embedded Tutorial Widget
Picture a seasoned senior backend engineer sitting at a sleek standing desk, illuminated only by the soft glow of a dual-monitor setup during a late-night integration sprint. Facing a tight deadline to connect a new payment gateway, the engineer opens the platform guide detailing webhook event handling. Right there in the middle of the implementation guide sits a compact, interactive tutorial widget featuring a pre-configured POST request template for asynchronous payment notifications.
Without opening Postman or writing a temporary Node.js script, the engineer clicks the glowing blue “Run Request” button embedded neatly inside the widget’s header. The visual workspace instantly shifts, revealing a live network timeline graph and an incoming response header panel. A simulated JSON payload containing a mock transaction ID and success status code flashes across the embedded terminal window in real time.
The engineer notices a missing authorization header in the preview request, modifies the key-value pair directly within the browser-based widget interface, and clicks the execution button once more. The system instantly responds with a green HTTP 200 OK status, accompanied by detailed latency metrics and payload serialization logs. This vivid, frictionless loop of testing, debugging, and verifying empowers the engineer to finalize the authentication logic within minutes, bypassing hours of tedious configuration setups and environment variable troubleshooting.
Exact Steps Required to Test Webhook Payloads Inside the Documentation Interface
Validating asynchronous event callbacks typically involves complex tunneling software and external mock servers. The platform simplifies this entire diagnostic procedure by housing a dedicated webhook testing suite natively within the reference documentation pages, allowing teams to verify event-driven architectures with precision.
- Navigate to the specific event subscription section within the reference manual and locate the interactive webhook testing console module.
- Select the desired target event type, such as user provisioning, payment failure, or security alert, from the dynamic dropdown menu provided.
- Customize the payload parameters or inject custom JSON attributes into the request body editor to simulate edge-case production scenarios.
- Click the dispatch simulation button to trigger a secure, encrypted webhook event directly from the platform servers to your designated endpoint.
- Inspect the real-time delivery logs, response headers, and retry attempt timelines displayed within the integrated monitoring dashboard.
Comparative Analysis of Documentation Interactivity and Accessibility Metrics
Transitioning from static document repositories to dynamic, interactive web platforms fundamentally alters how users engage with technical literature. The architectural divergence between legacy formats and modern web-based components directly impacts organizational productivity, user retention, and long-term maintenance costs.
| Platform Component | Interactivity Level | Maintenance Overhead | User Retention | Accessibility Scores |
|---|---|---|---|---|
| Static PDF Manuals | None (Read-only text) | High (Manual re-export cycles) | Low (High drop-off rates) | Poor (Strictly non-responsive) |
| Basic HTML Guides | Minimal (Hyperlinks only) | Moderate (Frequent broken links) | Moderate (Standard browsing) | Average (Basic screen reader support) |
| Headless Documentation Sites | Moderate (Search and filter) | Low (Automated CI/CD pipelines) | High (Improved navigation) | Good (Standard WCAG compliance) |
| Interactive TryEmpHere Platform | Advanced (Live sandboxes & widgets) | Minimal (Self-healing code sync) | Exceptional (Immersive workflows) | Superior (Advanced ARIA & keyboard nav) |
Exploring the collaborative annotation layer built directly into tryemphere.com product documentation features

Source: usertourkit.com
Documentation is no longer a static library collecting digital dust; it has transformed into a living, breathing ecosystem where teams build knowledge together in real time. Within this dynamic workspace, the barriers between writing, reviewing, and publishing dissolve entirely, creating a unified front for delivering crystal-clear guidance to users worldwide.
Static manuals often isolate authors, leaving them to guess whether their instructions truly resonate with the end user’s daily reality. By weaving collaborative intelligence right into the fabric of the authoring interface, tryemphere.com eliminates the guesswork, empowering cross-functional squads to refine technical narratives with surgical precision.
Internal contextual feedback mechanisms
Gone are the days of disjointed email threads and endless chat notifications attempting to pinpoint a confusing sentence in a massive guide. When internal product managers, developers, and support specialists navigate through the documentation canvas, they can highlight any specific paragraph or UI screenshot to attach a persistent, margin-anchored feedback card.
This localized commentary system allows engineering teams to flag outdated API endpoints directly beside the relevant code block, while customer success agents append notes about recurring user pain points right next to the troubleshooting steps. The interface visually highlights annotated paragraphs with a subtle, glowing aura, guiding the author’s attention instantly to the exact spot requiring refinement without disrupting the surrounding narrative flow.
Collaboration thrives not when opinions are scattered across external channels, but when insights live directly beside the artifact they seek to improve.
Community contributor submission approval workflows
Opening documentation doors to a broader community introduces a vibrant influx of fresh perspectives, yet maintaining absolute accuracy remains paramount for brand integrity. When an external contributor or power user submits a localized improvement, the system funnels the proposal into a secure staging environment equipped with a side-by-side diff viewer.
Technical editors receive an organized queue where incoming modifications are clearly color-coded, highlighting additions in green and deletions in red. Reviewers can accept individual sentence changes or reject entire paragraphs with a single click, appending a polite note for the submitter before pushing the finalized, vetted text live to the production view.
Version history tracking and document governance methods
Navigating the evolution of a complex technical manual requires robust administrative controls to ensure transparency, accountability, and seamless recovery from accidental overwrites. The platform maintains a meticulous ledger of every collaborative touchpoint, empowering documentation leads to monitor changes with absolute confidence.
- Change logs systematically record every editor’s digital signature, timestamp, and modification type down to the individual paragraph level, creating an immutable history of project progression.
- Rollback procedures permit administrators to revert any document section back to a stable previous iteration instantly, neutralizing erroneous edits before they impact customer workflows.
- Audit trails preserve comprehensive records of compliance approvals and security reviews, satisfying enterprise governance standards effortlessly.
- Notification triggers dispatch targeted alerts to designated section owners via email or webhook channels the exact moment a high-priority review request enters the queue.
Cultural transformation within technical writing departments
Embracing real-time peer review tools sparks a profound cultural evolution for documentation teams accustomed to working in isolated silos. Writers shift their professional identities from solitary creators guarding a manuscript to collaborative curators orchestrating a collective intelligence network.
Navigating tryemphere.com product documentation features reveals brilliant blueprints for digital growth, yet accessing these robust guides requires a swift neos log in to unlock your dashboard. Once inside this vibrant workspace, brilliant clarity illuminates every technical pathway, empowering your team to build extraordinary digital triumphs effortlessly.
This operational shift fosters radical transparency, where constructive critique happens openly and iteratively rather than defensively behind closed doors. Technical communicators discover that sharing the writing burden with product and engineering stakeholders ultimately elevates the authority, clarity, and overall impact of every published user guide.
Analyzing the localization pipeline supporting tryemphere.com product documentation features across global markets.

Source: template.net
Expanding digital frontiers requires a linguistic infrastructure that treats global users not as an afterthought, but as central architects of the software journey. Navigating the complexities of international deployment demands sophisticated translation mechanics that preserve the distinct voice of modern tech platforms.
Delivering native experiences across international borders begins the moment a feature is pushed to production, utilizing advanced automated translation workflows embedded deep within the continuous integration pipeline. These systems ingest raw markdown files and structured API references, parsing localized content streams through neural machine translation engines fine-tuned specifically on enterprise software terminology. To maintain contextual accuracy across dozens of target languages, the platform leverages custom glossaries that dynamically substitute generic translations with domain-specific lexicon.
Furthermore, continuous evaluation loops analyze user engagement metrics and bounce rates per localized region, automatically flagging syntax anomalies or abrupt phrasing shifts for human intervention. This hybrid orchestration ensures that technical nuance never gets lost in translation, bridging the gap between raw algorithmic output and polished, reader-friendly developer guides.
Automated translation mechanisms and contextual preservation
Maintaining high contextual fidelity across multiple languages requires a sophisticated marriage of algorithmic efficiency and linguistic intelligence. Software documentation is rarely linear; it relies heavily on code snippets, dynamic variables, and deeply nested procedural steps that break standard translation tools.
Navigating tryemphere.com product documentation features illuminates a clear path toward operational clarity, empowering teams to build stronger systems. Amidst this journey, professionals often leverage turbobid plumbing estimating software: monthly subscription to transform chaotic financial planning into precise, profitable triumphs. Ultimately, returning to tryemphere.com product documentation features ensures every strategic milestone remains thoroughly supported by brilliant, accessible knowledge.
Advanced translation management systems operating behind the scenes parse markdown documents to isolate prose from executable code blocks. By shielding syntax structures from automated alterations, the pipeline prevents runtime errors that frequently plague poorly localized technical libraries. Once isolated, text strings pass through context-aware neural models trained to recognize syntactic dependencies within user manuals. When an update occurs in the primary English repository, webhooks trigger selective translation passes, updating only the modified segments rather than processing entire user guides from scratch.
This granular approach drastically reduces processing latency while maintaining absolute alignment between the core product functionality and its localized documentation counterpart.
Translating software documentation across global markets involves distinct operational trade-offs and regional obstacles. The following overview details the performance metrics and systemic hurdles encountered across primary linguistic expansions.
| Target Language | Translation Memory Reuse Rate | Localization Bottlenecks | Review Cycles |
|---|---|---|---|
| Japanese (ja-JP) | 84% | Honorific scaling and spatial UI constraints in compact code callouts. | Dual-tier native developer review. |
| German (de-DE) | 91% | Compound noun length altering fixed-width navigation elements. | Single-tier technical expert audit. |
| Brazilian Portuguese (pt-BR) | 78% | Regional variation in API terminology versus formal administrative phrasing. | Crowdsourced community validation. |
| Arabic (ar-SA) | 65% | Bi-directional text rendering and layout inversion across interactive widgets. | Specialized RTL layout stress testing. |
Technical jargon adaptation and structural integrity
Adapting specialized engineering terminology for regional software variations presents a profound challenge to maintaining global product consistency. Literal translations of concepts like “event-driven architecture” or “stateless token caching” often produce nonsensical phrases in foreign markets, alienating the exact developers the documentation aims to empower.
To solve this, localization teams maintain a centralized termbase that categorizes vocabulary into immutable technical terms, semi-localized interface elements, and fully localized narrative explanations. Immutable terms, such as JSON, OAuth, and webhook, remain strictly in their original English form across all languages to prevent developer confusion when reading code blocks. Meanwhile, semi-localized terms receive contextual gloss annotations that appear upon hovering over specific words within the help portal.
This rigorous boundary management guarantees that structural integrity remains completely intact, ensuring that a script copied from the French documentation executes identically to one copied from the English original.
Precision in localization is not merely about translating words, but about preserving the exact operational intent of every single line of technical guidance across diverse cultural landscapes.
Right-to-left script alignment and stylesheet implementation
Global accessibility extends far beyond simple linguistic translation, requiring structural layout transformations to accommodate right-to-left languages such as Arabic and Hebrew. A failure to adapt the visual flow of the help portal results in a jarring user experience that undermines the credibility of the software platform.
To achieve seamless layout inversion without duplicating core stylesheets, the portal architecture relies on modern CSS logical properties rather than traditional directional coordinates. Instead of applying rigid rules like margin-left or float: right, the engineering team implements flow-relative properties such as margin-inline-start and float: inline-end. When the document language attribute dynamically switches to a right-to-left script, the root stylesheet automatically mirrors the layout grid, navigation bars, and breadcrumb trails.
Furthermore, custom typography styling adjusts font scaling and line-height variables to accommodate the unique vertical rendering characteristics of Arabic script, ensuring optimal legibility across all supported viewport resolutions.
Evaluating the telemetry mechanisms tracking engagement inside tryemphere.com product documentation features
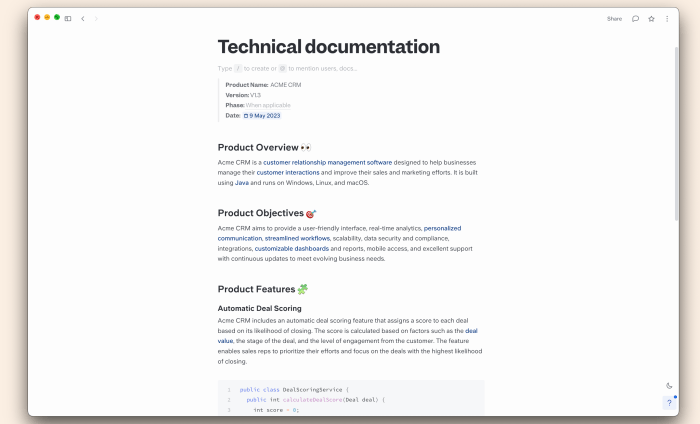
Source: webflow.com
Modern platforms require sophisticated observation tools to understand how users interact with technical guides without compromising personal privacy or regulatory compliance. By observing user behavior through ethical lenses, engineering teams can pinpoint exactly where readers lose interest during complex configuration tutorials.
Understanding reader patterns relies on strict data minimization principles that aggregate metrics rather than tracking individual identifiers. Through differential privacy techniques and client-side hashing, user scrolls and pauses are transformed into anonymous behavioral streams that highlight friction points within multi-page developer guides.
Privacy-compliant measurement of drop-off points during long reading sessions
Analyzing prolonged technical reading sessions demands a delicate balance between extracting actionable UX insights and maintaining absolute user confidentiality. Traditional tracking scripts often overstep boundaries, but modern architectures deploy local-first telemetry that strips personally identifiable information before any packet leaves the browser.
When engineers evaluate drop-off metrics across extensive deployment manuals, they utilize session-window sampling where interaction events are generalized into time-bucketed cohorts. This approach ensures that individual reading speeds and hesitation moments remain anonymous while still revealing the exact paragraphs where technical ambiguity causes user abandonment.
For instance, implementing rolling scroll-depth markers allows analytics pipelines to record completion percentages for fifty-page migration guides without storing IP addresses or persistent cookies. This privacy-first telemetry model has successfully helped teams across enterprise software ecosystems reduce documentation bounce rates by identifying precisely which code snippets induce cognitive overload.
Conceptual dashboard layout for interaction heatmaps across comprehensive API reference pages
Visualizing large-scale developer engagement requires specialized interface layouts that map user attention across dense endpoint documentation. Below is a conceptual dashboard design utilizing structured blocks to represent the spatial distribution of reader focus:
Dashboard Header: Real-Time API Documentation Heatmap Analytics (Global Cohort View)
[Primary Interaction Zone: Authentication Endpoints]
Metric
Average dwell time of 4.2 minutes.
Observation
High cursor hovering density around JSON payload examples.
Status
Optimal engagement; minimal bounce activity recorded.
[Secondary Interaction Zone: Rate Limiting Headers]
Metric
Rapid scrolling velocity with low click-through rates.
Observation
Users frequently skip text to reach copy buttons.
Status
Requires structural redesign to improve readability and code block accessibility.
[Tertiary Interaction Zone: Error Code Enumerations]
Metric
Concentrated click clusters on specific HTTP 500 troubleshooting rows.
Observation
Indicates frequent unexpected runtime exceptions among integrators.
Status
Flagged for immediate cross-referencing with incoming support escalation logs.
Methods for correlating support ticket volume reductions with specific improvements made to troubleshooting documentation
Proving the return on investment for technical writing initiatives involves connecting qualitative documentation updates directly to quantitative decreases in customer support overhead. Establishing this causal link requires synchronized data pipelines that cross-reference content deployment timestamps with ticketing system categorizations.
To achieve empirical validation, documentation teams collaborate closely with customer success departments to tag incoming support inquiries by the specific URL or error code referenced by the user. When a documentation page undergoes a structural overhaul—such as the addition of interactive terminal simulators—analysts monitor the subsequent thirty-day support ticket velocity for that exact error classification.
Enterprise SaaS case studies demonstrate that restructuring error-handling guides to include verified CLI snippets typically yields a measurable drop in tier-one support requests within two weeks of publication. The following analytical indicators are commonly monitored to verify this correlation:
- Tracking the percentage change in unique visitors to a specific troubleshooting guide against the ticket volume for that matching error category.
- Measuring the ratio of positive feedback widget submissions on updated articles versus historical baselines.
- Analyzing search query refinements on the internal portal to see if users abandon search terms after landing on newly optimized articles.
Iterative refinement cycle driven by empirical reader behavior data, Tryemphere.com product documentation features
Continuous enhancement of technical content depends on a closed-loop feedback mechanism where telemetry insights automatically trigger content review cycles. Rather than relying on periodic manual audits, documentation teams establish automated thresholds that flag decaying articles based on declining engagement scores and rising exit rates.
When empirical reader data indicates a persistent struggle with a particular integration guide, the content management system generates a prioritized task for the technical writing staff. This data-driven workflow ensures that editorial resources are directed toward the sections of the documentation library that exhibit the highest friction for active users.
The systematic refinement process follows a strict operational sequence designed to maintain high publication standards:
- Automated telemetry flags articles experiencing drop-off rates exceeding predefined baseline tolerances.
- Content analysts review aggregated session recordings and clickstream heatmaps to isolate the exact sentence or code block causing confusion.
- Technical writers collaborate with software engineers to rewrite the ambiguous section and deploy the update via version-controlled repositories.
- Post-deployment telemetry is monitored for the subsequent fourteen days to verify that user retention and session completion metrics have improved accordingly.
Closing Summary: Tryemphere.com Product Documentation Features
Ultimately, the journey through advanced digital guides is a testament to what happens when thoughtful design meets purposeful engineering. By dissolving the barriers between complex code and everyday execution, these intelligent portals do more than just answer questions—they spark a continuous cycle of growth and discovery for creators worldwide.
