laboratory data analysis software stands at the beating heart of modern scientific discovery, quietly rewriting how researchers unlock the universe’s most guarded secrets. Across dimly lit rooms and high-tech facilities alike, brilliant minds stare into cascading waterfalls of raw numerical charts, seeking meaning amidst overwhelming complexity. Today’s investigative engines act as master translators, reshaping chaotic electronic streams into luminous, coherent visual representations that inspire profound breakthroughs.
When experimental measurements threaten to overwhelm human endurance, these specialized digital platforms step forward to illuminate the path toward verified truth.
Behind every major breakthrough lies a sophisticated computational ecosystem carefully designed to balance raw processing speed against the nuanced demands of complex biological and chemical assays. As laboratories worldwide race to decode uncharted territories, the integration of advanced algorithms ensures that critical anomalies never slip past unnoticed. This relentless pursuit of clarity not only accelerates daily productivity but fundamentally redefines the boundaries of what dedicated research teams can achieve together.
Researchers frequently encounter hidden anomalies within massive experimental measurements before utilizing specialized computational toolsets designed for scientific interpretation.
Every breakthrough in modern science begins in the quiet tension between raw, unblemished observation and the messy reality of physical measurement. Long before pristine visualizations illuminate presentation screens, investigators navigate vast oceans of numerical records, where subtle distortions and phantom signals constantly threaten to obscure genuine discoveries.
The journey from physical sensors to actionable insight spans decades of rapid technological transformation, redefining how laboratories capture reality. In earlier eras, scientists relied on analog oscillographs, paper chart recorders, and manual ledger entries to document physical phenomena. This mechanical approach meant data was inherently limited in volume, trapped in physical media, and susceptible to human recording errors. The transition to early digital acquisition systems introduced magnetic storage and basic microprocessor logging, yet laboratories still faced severe bottlenecks in data throughput and fidelity.
Today, high-throughput instrumentation generates petabytes of streaming telemetry per second across fields ranging from genomics to particle physics. Modern laboratory data analysis software evolved precisely to bridge this widening chasm, replacing fragile manual processing with robust, automated pipelines capable of handling unprecedented dimensional complexity without losing sight of microscopic details.
Historical evolution of digital measurement processing workflows within advanced scientific environments
Navigating the labyrinth of raw numerical charts demands extraordinary cognitive endurance, forcing human analysts to process millions of individual data points through sheer visual and mental stamina. When scientists manually inspect endless rows of numerical logs or sprawling multi-axis graphs, they operate at the absolute limits of human attentiveness and pattern recognition. The human brain, while remarkably adaptive, is fundamentally ill-equipped to scan continuous multi-dimensional streams without succumbing to cognitive fatigue, confirmation bias, and the peril of perceptual blindness.
Staring at monotonous text tables or chaotic line charts for hours dulls the critical edge required to spot subtle, low-amplitude aberrations that might indicate a novel physical phenomenon or a catastrophic instrument failure. Furthermore, the sheer volume of contemporary datasets turns manual inspection into a Sisyphean endeavor, where researchers risk overlooking critical outliers buried deep within gigabytes of background noise.
This relentless cognitive strain often leads to subjective interpretations, inconsistent data cleaning standards across different team members, and severe delays in the research lifecycle. By forcing highly trained minds to perform mechanical tasks like anomaly hunting in raw text, laboratories waste invaluable intellectual capital that should instead be dedicated to theoretical formulation and experimental design. The psychological weight of knowing that a single missed anomaly could invalidate months of research amplifies stress, making the manual review phase a notorious bottleneck in high-stakes scientific discovery.
Instrumental noise patterns and mitigation parameters
Experimental apparatuses invariably introduce distinct artifacts into measurement streams due to environmental factors, hardware limitations, and electromagnetic interference. Understanding these disruptions requires systematic categorization of their origins, severity, and temporal signatures.
| Artifact Category | Severity Level | Mitigation Strategy | Detection Timeline |
|---|---|---|---|
| Thermal Johnson Noise | Moderate | Cryogenic cooling and digital bandpass filtering | Real-time streaming analysis |
| Power Line Interference (50/60 Hz) | High | Faraday cage shielding and notch filters | Post-acquisition phase |
| Sensor Drift and Calibration Decay | Critical | Automated baseline subtraction and reference checks | Periodic batch processing |
| Cosmic Ray Particle Impingement | Severe | Coincident sensor arrays and median clipping | Immediate anomaly flagging |
Advanced computational algorithms revolutionize how laboratories process chaotic numerical streams by translating sterile digits into intuitive, multidimensional visual landscapes. Instead of forcing researchers to decipher cold spreadsheets, modern investigative engines harness advanced rendering techniques to map complex variables into color, depth, and motion.
True scientific clarity emerges only when massive numerical arrays are sculpted into coherent visual narratives that allow human intuition to collaborate seamlessly with machine processing.
These sophisticated visualization environments empower investigators to rotate multi-variable point clouds in real-time, instantly isolating clusters, anomalies, and structural correlations that would otherwise remain invisible in linear data representations. By converting abstract mathematical matrices into dynamic visual topographies, these platforms bridge the gap between raw data and cognitive comprehension, transforming hours of tedious calculation into instantaneous, insightful realization.
Selecting appropriate algorithmic platforms requires balancing computational speed against the nuanced demands of complex biological and chemical assays.

Source: starlims.com
Modern laboratories operate at the thrilling intersection of high-throughput instrumentation and relentless data generation, where every single terabyte of experimental output holds the potential for a groundbreaking discovery. Navigating this vast ocean of multi-channel sensor readings demands an uncompromising approach to software acquisition, ensuring that raw figures transform seamlessly into actionable scientific insights without sacrificing analytical fidelity.
Laboratories evaluating fresh digital interpretation utilities must look far beyond superficial interface designs to scrutinize the underlying architecture that drives numerical processing. The journey from raw sensor capture to validated chemical confirmation relies on tools capable of handling immense dynamic ranges while maintaining rigorous statistical rigor across every single sample iteration.
Essential criteria laboratories use when acquiring fresh digital interpretation utilities
When procurement committees gather to modernize their computational suites, they evaluate several critical performance pillars to protect both scientific integrity and capital investment. These foundational parameters ensure that newly integrated applications integrate smoothly into existing workflows while adapting effortlessly to future experimental paradigms.
- Interoperability with existing laboratory information management systems to prevent data silos and streamline cross-platform data migration.
- Native support for open data formats to guarantee long-term accessibility of historical experimental records without proprietary lock-in.
- Algorithmic transparency and open-source documentation that allow lead researchers to audit complex calculation pathways thoroughly.
- Robust compliance frameworks adhering to stringent regulatory standards such as FDA 21 CFR Part 11 for electronic records and signatures.
Mathematical integration methods for multi-channel sensor inputs
Harmonizing diverse data streams from advanced spectrophotometers, chromatographs, and mass spectrometers requires sophisticated mathematical frameworks capable of resolving overlapping signals and suppressing background noise. Laboratories rely on specialized computational routines to fuse these multi-dimensional inputs into coherent, high-fidelity analytical models.
Modern laboratories constantly generate endless streams of raw figures requiring precise processing. Today, forward-thinking teams are upgrading their workflows by integrating gataca.io product features analytics to reveal hidden patterns with remarkable clarity. This breakthrough empowers scientists to transform complex metrics into actionable discoveries, ensuring that every piece of laboratory data analysis software delivers maximum reliability and drives future breakthroughs.
- Principal Component Analysis projects high-dimensional spectral matrices onto orthogonal latent variables to isolate primary variance while discarding instrumental noise.
- Wavelet transforms decompose non-stationary signals into localized scale-dependent coefficients, effectively separating sharp transient peaks from baseline drift.
- Partial Least Squares regression establishes robust linear relationships between multi-channel predictor variables and complex chemical concentration matrices.
- Kalman filtering applies recursive state estimation algorithms to dynamically update real-time sensor measurements against a theoretical physical model.
Precision in algorithmic data fusion dictates the boundary between verifiable scientific breakthroughs and costly experimental misinterpretation.
Financial impact of licensing models on computational infrastructure budgets
The financial architecture governing modern scientific software dictates much more than annual accounting expenditures; it fundamentally shapes the long-term operational capabilities of research institutions. When laboratories commit to a specific software vendor, the chosen licensing paradigm—whether perpetual, subscription-based, or consumption-driven—sets off a cascade of economic consequences that ripple through hardware upgrade cycles, staffing allocations, and grant sustainability. A perpetual license often front-loads capital expenditure, demanding a substantial initial investment that secures indefinite usage rights but risks rapid technological obsolescence as experimental demands outpace stagnant codebases.
Conversely, cloud-hosted subscription models shift expenses to operational budgets, providing predictable recurring costs and immediate access to algorithmic updates, yet they introduce vulnerabilities to long-term price inflation and continuous internet dependency during critical analytical runs. Furthermore, institutional budgeting must account for indirect costs such as internal technical support, specialized staff training, and the hardware upgrades required to run increasingly resource-intensive analysis suites.
For instance, a genomics facility transitioning from local server clusters to distributed cloud licensing might initially experience a twenty percent reduction in maintenance overhead, only to face unexpected cost surges during peak analytical seasons when high-concurrency data processing scales automatically. Consequently, financial planners must carefully forecast multi-year total cost of ownership models, weighing the flexibility of agile subscription frameworks against the financial predictability of locked-down enterprise agreements.
Neglecting these long-term fiscal dynamics often results in premature software abandonment, forcing institutions to prematurely discard customized analytical workflows and retrain personnel on entirely new platforms simply due to shifting vendor pricing structures.
Comparative evaluation matrix for software scalability and system performance
Visualizing system performance metrics helps technical directors assess whether a prospective software platform can sustain demanding enterprise workloads without buckling under pressure.
| Platform Tier | Processing Speed | Memory Footprint | User Concurrency Limit | Vendor Support Tier |
|---|---|---|---|---|
| Standard Local | Baseline execution for single-sample files | Moderate RAM consumption up to 32 GB | 1 to 5 simultaneous local operators | Email-based ticketing with 48-hour SLA |
| Enterprise Cluster | High-speed parallelized multi-node execution | Optimized caching utilizing up to 512 GB | Up to 50 active networked researchers | Dedicated account manager with 12-hour SLA |
| Cloud Scaled | Dynamic elasticity scaling across virtual cores | Virtually limitless distributed RAM allocation | Unlimited concurrent global access points | 24/7 priority live engineering intervention |
Translating disparate digital file formats into unified repositories remains a formidable hurdle for cross-disciplinary research teams.

Source: creliohealth.com
Modern laboratories generate a staggering velocity of digital metrics, yet these vital experimental outcomes often remain isolated inside incompatible digital silos. When brilliant minds across chemistry, biology, and data science attempt to merge their findings, they routinely collide with a labyrinth of vendor-specific constraints and locked file extensions that actively resist collaboration.
Bridging this vast technological divide demands a meticulous reimagining of how data flows from the benchtop into centralized analytical environments. Without deliberate architectural interventions, critical scientific momentum grinds to a halt beneath the weight of fragmented digital architectures.
Structural discrepancies between proprietary instrument outputs and open-source ingestion pipelines
The journey of a raw measurement begins inside specialized hardware, where manufacturers like Thermo Fisher, Agilent, or Waters write data into highly customized binary schemas. These proprietary formats frequently bundle instrument-specific calibration curves, hardware serial numbers, and proprietary checksums directly into the core file structure, creating an opaque digital artifact.
Conversely, open-source ingestion pipelines—built upon community-driven standards like mzML for mass spectrometry or AnIML for analytical chemistry—rely on transparent, extensible markup languages and standardized data arrays. When an open-source parser attempts to ingest a proprietary binary stream, the structural mismatch often results in missing headers, corrupted intensity matrices, or completely unreadable baseline calibrations. Researchers face an invisible tax on their time, manually writing bespoke parsing scripts just to extract baseline chromatograms that should flow effortlessly into downstream statistical models.
Detailed procedure for standardizing metadata across disparate experimental runs without losing fidelity
Achieving absolute data harmonization requires a rigorous, multi-step pipeline that preserves every nuance of the original experimental context while stripping away proprietary formatting anomalies. This methodical approach ensures that biological and chemical significance remains completely intact.
- Extraction Phase: Automated daemons poll instrument directories to harvest raw binary files immediately upon completion of an analytical run, capturing exact timestamps and hardware parameters without manual intervention.
- Ontological Mapping: Software routines parse the raw headers and map experimental variables—such as solvent gradients, ionisation voltages, and sample IDs—to controlled vocabularies defined by international scientific ontologies.
- Serialization and Normalization: The mapped parameters are translated into a neutral intermediate JSON-LD or HDF5 container, anchoring every quantitative metric to its precise contextual metadata.
- Fidelity Verification: Algorithmic checksums and automated unit-test assertions compare the normalized output against the original raw file to guarantee zero loss of decimal precision or spectral resolution.
Technical barriers preventing seamless interoperability among legacy laboratory systems
Unifying historical laboratory infrastructure with modern cloud-native analytics exposes deeply entrenched systemic vulnerabilities that have accumulated over decades of rapid hardware evolution. Legacy instruments running on outdated operating systems, such as unpatched iterations of Windows XP or embedded industrial controllers, represent critical security hazards and networking dead zones. These older workstations frequently lack modern application programming interfaces, relying instead on archaic file-transfer protocols or physical media like compact discs and USB drives to offload experimental runs.
The absence of standardized network protocols means that attempting to automate data ingestion from a twenty-year-old high-performance liquid chromatography unit requires brittle screen-scraping utilities or custom hardware adapters that routinely fail under production loads. Furthermore, database schema drift compounds the issue; early relational databases used by laboratory information management systems utilized rigid, flat-file table designs that cannot accommodate the dynamic, high-dimensional arrays generated by modern multi-omics platforms.
When institutions attempt to force these antiquated systems to converse with contemporary distributed computing clusters, they frequently encounter severe bandwidth bottlenecks, memory buffer overflows, and silent data truncation errors. Real-world implementations, such as multi-site pharmaceutical consolidation projects, routinely stall for months as engineers diagnose why floating-point numbers exported from legacy mass spectrometers lose crucial precision decimals during intermediary SQL database transits.
Overcoming these entrenched barriers requires organizations to deploy edge-computing gateways capable of sanitizing and translating legacy outputs right at the instrument bench before data ever touches the wider enterprise network.
Standardization is not merely a technical convenience; it is the fundamental bedrock upon which reproducible, transparent, and transformative scientific discovery relies.
Visual description illustrating a conceptual data harmonization pipeline showing data streams converging into a centralized clearinghouse
Imagine a vast, high-resolution architectural blueprint rendered in crisp vector lines against a deep navy digital workspace, depicting a sprawling data harmonization ecosystem in full motion. On the far left edge, multiple distinct data streams flow inward from diverse analytical instruments, represented as glowing, color-coded tributaries carrying raw binary files, XML schemas, and flat spreadsheets. These streams converge directly into a dynamic intermediary zone dominated by a series of glowing, interconnected transformation filters shaped like translucent hexagonal nodes.
Within these filters, data packets pulse with activity as automated scripts strip away proprietary wrappers, inject standardized ontologies, and normalize floating-point values into a cohesive structural format. Beyond the filtration grid, the streams flow through strict validation checkpoints marked by brilliant emerald-green laser lines that scan every data package for structural integrity and metadata completeness, instantly diverting any anomalous or corrupted files into a quarantined diagnostic channel.
The fully verified, pristine data streams finally empty into a massive, luminous central clearinghouse positioned at the exact center of the visualization—a vast, multi-layered repository radiating a steady, calming cyan glow. From this central hub, neatly organized data pipelines extend toward the right side of the canvas, distributing standardized, high-fidelity datasets directly to waiting machine learning models, collaborative research dashboards, and archival cloud storage arrays with flawless synchronization.
Automated anomaly detection algorithms revolutionize how technicians monitor continuous experimental trials for unexpected parameter deviations.: Laboratory Data Analysis Software
The relentless hum of the laboratory never truly sleeps, and neither do the digital sentinels watching over the data streams. As high-throughput pipelines pour millions of data points into analytical software every second, a single microsecond spike in pressure or temperature can spell the difference between groundbreaking discovery and catastrophic equipment failure. Traditional manual oversight simply cannot keep pace with this deluge of information, forcing modern laboratories to adopt algorithmic watchdogs that maintain absolute vigilance over complex scientific processes.
Precision laboratory data analysis software decodes complex experimental signals with crystalline clarity. Just as researchers optimize their vital findings, evaluating getresponse vs mailchimp reveals strategic pathways for vital audience communication. Ultimately, mastering these digital outreach platforms empowers scientists to broadcast breakthrough discoveries, ensuring advanced laboratory data analysis software drives both modern scientific progress and meaningful public engagement forward.
Behind the gleaming glass interfaces and real-time visualization dashboards lies a sophisticated orchestration of mathematical filters and computational logic. These systems continuously ingest live sensor feeds, comparing incoming experimental metrics against historical baselines and predetermined physical boundaries to catch deviations before they compromise the integrity of the entire trial.
Operational mechanics behind threshold-based alerting systems within high-throughput testing environments
At the beating heart of continuous experimental monitoring are threshold-based alerting systems designed to act as the first line of defense against unexpected deviations. These mechanisms rely on predefined upper and lower boundaries that encapsulate safe operational parameters for any given assay. When live telemetry streaming from a high-throughput sequencer or mass spectrometer crosses these invisible fences, the software immediately fires an alert to the technician on duty.
However, modern implementations go far beyond rigid static limits by integrating dynamic moving windows that adjust to the natural drift of prolonged experiments. This sophisticated operational workflow prevents nuisance alarms while ensuring that genuine anomalies trigger rapid interventions, safeguarding costly biological and chemical reagents from total destruction.
Decoding complex laboratory data analysis software reveals hidden scientific breakthroughs, much like how modern campuses streamline daily operations through efficient help desk software for schools to empower educators. Transforming raw digital metrics into inspiring clarity ultimately accelerates vital discoveries, bringing brilliant analytical visions vividly to life.
Statistical outlier identification techniques utilized by contemporary evaluation utilities
To navigate the vast seas of experimental data without getting overwhelmed by noise, contemporary evaluation utilities deploy a sophisticated arsenal of mathematical tools designed to isolate true anomalies from routine fluctuations. These quantitative methods provide the rigorous foundation necessary for objective data assessment before human experts step in to interpret the results.
- Z-score analysis measures how many standard deviations a given data point sits away from the mean, effectively flagging extreme measurements in normally distributed populations.
- Interquartile range filtering isolates anomalies by evaluating data spread within the middle fifty percent of observations, ignoring skewed extremes for robust non-parametric evaluation.
- Grubbs test computes the absolute difference between a suspicious data sample and the group average, dividing it by the standard deviation to statistically confirm single outliers.
- Moving median absolute deviation computes rolling deviations over time series data, providing exceptional resilience against sudden baseline shifts in continuous biological assays.
Psychological impact of automated oversight on human operator vigilance and decision fatigue
Integrating intelligent computational watchdogs into the daily workflow fundamentally transforms the cognitive landscape for laboratory technicians and principal investigators alike. Instead of manually scanning endless columns of raw numbers, human operators transition into supervisory roles where they monitor the monitors. This shift introduces a profound psychological paradox. On one hand, automated alerts dramatically reduce the sheer volume of mundane tasks, freeing up precious cognitive bandwidth for higher-level experimental design and creative problem-solving.
On the other hand, prolonged exposure to high-reliability automation can induce complacency, where operators implicitly trust the software and fail to notice rare, subtle systemic failures that the algorithm was never programmed to catch.
Furthermore, when complex anomalies do occur, technicians often grapple with severe decision fatigue, especially if the software generates frequent ambiguous warnings or false alarms during high-stakes overnight trials. In clinical diagnostic laboratories handling thousands of patient samples daily, an onslaught of alerts can lead to cognitive overload, where exhausted operators dismiss critical warnings simply because their mental reserves have been depleted.
To combat this phenomenon, modern software architects must design interfaces that not only flag anomalies accurately but also present contextual clarity and actionable remediation steps. By framing alerts in a narrative, human-readable format rather than cryptic error codes, the technology supports psychological well-being and sustains operator alertness during marathon experimental runs.
True scientific progress relies not on replacing human intuition with cold code, but on building intelligent systems that preserve our cognitive focus for the moments that truly matter.
Comparative breakdown of machine learning versus heuristic error flagging
Selecting the right analytical engine requires a careful evaluation of how different computational paradigms handle unexpected experimental deviations under pressure. The following breakdown contrasts rigid rule-based systems with adaptive machine learning models across critical operational vectors.
| Evaluation Metric | Heuristic Error Flagging | Machine Learning Algorithms |
|---|---|---|
| False Positive Rates | Typically higher in volatile environments due to fixed boundary limitations and inability to adapt to natural experimental drift. | Significantly lower over time as models learn normal baseline variance, though initial deployment phases may yield unexpected spikes. |
| Computational Overhead | Extremely low, requiring minimal CPU cycles and memory, making it ideal for edge devices and legacy laboratory hardware. | Moderate to high, often necessitating dedicated GPU acceleration and robust cloud infrastructure for real-time inference. |
| Training Requirements | Zero training needed; relies purely on domain-specific expert rules, threshold definitions, and hardcoded physical constants. | Extensive historical data required to train models effectively, demanding diverse training sets to prevent overfitting or bias. |
| Adaptability | Rigid and inflexible; requires manual code updates whenever experimental protocols or baseline parameters change. | Highly adaptive; continuously refines its internal weights and anomaly thresholds as new experimental data flows into the system. |
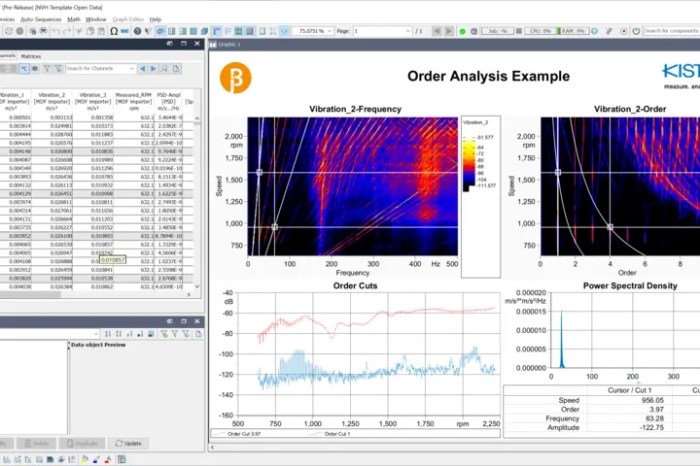
Collaborative digital workspaces enable distributed research consortiums to co-author findings and interrogate shared numerical archives simultaneously.
Source: celum.cloud
Modern scientific discovery rarely happens in isolation. Across continents, multidisciplinary teams are breaking down institutional silos by leveraging cloud-native analytical platforms that transform how massive computational datasets are examined and interpreted in real time. Imagine brilliant minds in Tokyo, Zurich, and Boston dynamically adjusting algorithmic parameters on a shared quantum chemistry matrix, watching live graphical renders shift as new telemetry streams into the central repository.
This seamless synergy relies on robust architectural frameworks designed to handle enormous throughput while maintaining absolute data integrity. As laboratories transition from localized hard drives to cloud-hosted computational dashboards, the velocity of scientific breakthroughs increases exponentially. Researchers no longer wait weeks for courier shipments of raw telemetry; instead, they co-create analytical narratives through synchronized interfaces that bridge geographical divides with remarkable precision.
Security protocols necessary for safeguarding sensitive intellectual property across cloud-hosted evaluation environments
Protecting proprietary biochemical assays and nascent algorithmic models requires a multi-layered defense strategy embedded directly into the cloud infrastructure. Encryption acts as the first line of defense, ensuring that all numerical matrices remain indecipherable both in transit across international networks and at rest within decentralized storage clusters. Advanced key management services restrict decryption capabilities solely to authenticated nodes operated by verified consortium members.
Beyond encryption, zero-trust network architectures continuously verify every user session and device posture before granting access to sensitive experimental logs. Role-based privilege matrices ensure that junior technicians, principal investigators, and external auditors interact only with the specific data tiers relevant to their authorized duties. Continuous behavioural monitoring tools watch for anomalous data exfiltration patterns, instantly isolating compromised endpoints before intellectual property can be compromised.
Mechanics of version control systems tailored specifically for scientific numerical records and metadata adjustments, Laboratory data analysis software
Traditional software development uses Git to track code changes, but scientific experimentation demands a specialized adaptation capable of handling massive binary datasets, floating-point precision variations, and complex metadata trees. Scientific version control systems treat every numerical adjustment as a distinct cryptographic state, recording not just the modified values but the exact computational environment, library dependencies, and hardware configurations used during the run.
When multiple researchers modify a shared spectral analysis file, the platform automatically generates divergent exploratory branches without overwriting the master baseline. Advanced diff-engine algorithms visually highlight microscopic shifts in chromatographic peaks or spectroscopic calibrations, allowing teams to merge successful experimental branches while maintaining an immutable audit trail. This meticulous tracking ensures absolute reproducibility, satisfying rigorous regulatory standards demanded by global patent offices and academic journals alike.
Accelerated validation of complex chemical trials through remote peer review sessions
Remote peer review sessions fundamentally alter the timeline of scientific validation, compressing months of traditional journal correspondence into days of dynamic, screen-shared interrogation. When a distributed consortium finalizes a complex synthesis trial, external reviewers are granted secure, temporary access to the live computational workspace, allowing them to independently re-run algorithms, tweak input parameters, and visualize resulting molecular interactions instantly.
This hands-on verification method eliminates the ambiguity of static PDF reports, enabling reviewers to stress-test mathematical models against raw experimental data streams in real time. For instance, during recent global vaccine development initiatives, distributed virology teams utilized synchronized digital workspaces to cross-examine binding affinity calculations concurrently. Reviewers could immediately identify edge-case variances in molecular modeling scripts and suggest corrective algorithmic adjustments on the spot.
The psychological impact of this transparent, collaborative environment fosters unprecedented trust and academic rigor. Disagreements regarding baseline normalizations or anomaly exclusions are resolved through live visual demonstrations rather than protracted written debates. Consequently, groundbreaking pharmaceutical compounds and material science breakthroughs move swiftly from computational sandbox environments to peer-reviewed publication, accelerating humanity’s capacity to address critical global challenges.
Access control paradigms regulating contributor permissions during active collaborative evaluation phases
Maintaining order within massive, decentralized research projects requires strict governance frameworks that define precisely who can view, edit, or execute specific computational models. The following paradigms dictate how permissions are enforced across active evaluation phases:
- Attribute-Based Access Control: Grants or denies entry based on dynamic environmental factors, such as a researcher’s physical location, institutional accreditation, and the specific security classification of the dataset.
- Mandatory Access Control: Implements rigid, system-enforced hierarchy levels where contributors cannot alter security labels, ensuring highly classified biochemical assay results remain strictly sequestered.
- Discretionary Access Control: Empowers primary data owners and lead principal investigators to delegate specific read or write privileges to visiting collaborators on a project-by-project basis.
- Role-Based Access Control: Assigns permissions according to predefined organizational titles, streamlining administrative oversight when large university departments onboard new graduate researchers into ongoing analytical pipelines.
Precision in collaborative analysis is not merely about sharing data; it is about establishing an unbroken chain of verifiable trust across every digital touchpoint.
Regulatory compliance mandates require strict traceability and cryptographic verification for every digital transformation applied to experimental numbers.

Source: thermofisher.com
Navigating the modern landscape of scientific research demands an unyielding commitment to data integrity, where every single computational adjustment leaves a permanent digital footprint. Global governing bodies have fundamentally reshaped how laboratories manage digital assets, transforming raw experimental figures into heavily guarded legal testimonies. When laboratories process vast streams of high-throughput data, the specter of falsification or accidental corruption looms large, threatening the credibility of entire institutions.
Consequently, adopting rigorous digital governance is no longer just an optional administrative best practice; it is the vital anchor holding modern scientific validation together.
Stringent auditing frameworks enforced by international regulatory authorities demand absolute transparency across the entire lifecycle of any digital record. Agencies such as the Food and Drug Administration and the European Medicines Agency enforce rules where every single keystroke, calculation, and algorithmic transformation must be accounted for without exception. These oversight protocols require systems to maintain an unbroken chain of custody, ensuring that no experimental metric remains anonymous or susceptible to clandestine alterations.
Failure to meet these demanding benchmarks invites severe operational shutdowns and tarnishes institutional reputation irreparably, highlighting the deep stakes involved in everyday laboratory informatics.
Implementation of immutable audit trails within proprietary digital suites
Modern analytical software must be meticulously engineered to embed cryptographic security directly into the core database architecture, transforming ordinary storage into an impenetrable fortress of verifiable truth. The journey toward total immutability begins by adopting append-only storage models, which fundamentally prohibit any administrative user from directly overwriting or deleting historical log entries. Whenever a researcher executes a data normalization algorithm or applies a baseline correction to a chromatogram, the software immediately captures the exact state of the dataset before and after the modification.
This dual-state capture forms the foundational building block of a robust investigative history.
To guarantee that these digital footprints cannot be tampered with by rogue actors or malicious insiders, advanced digital suites leverage cryptographic hash functions, such as SHA-256, to seal sequential transaction blocks. Each new event log is mathematically bound to the cryptographic signature of the preceding entry, creating a continuous, unbreakable chain of mathematical proof. If a single byte within an old experimental file is altered, the hash value instantly breaks, alerting security protocols and freezing affected analytical modules.
Furthermore, role-based access control policies dictate precisely who can initiate specific computational actions, ensuring that administrative privileges remain compartmentalized and fully accountable.
Visualizing this architectural marvel reveals a multi-tiered defense system operating quietly in the background of every laboratory terminal. Imagine a sleek, obsidian-tinted dashboard glowing softly in a dimly lit server room, where cascading streams of alphanumeric hashes continuously roll down the interface like a digital waterfall. Every time a scientist saves a modified dataset, a brilliant amber flash of cryptographic verification pulses across the screen, signifying that the new data block has been successfully chained to the historical ledger.
This visual feedback loop provides immediate psychological and technical reassurance, confirming that the digital architecture is actively guarding the sanctity of the research against unseen vulnerabilities.
Laboratories aiming for seamless compliance must also establish automated synchronization protocols that back up these immutable ledgers to geographically isolated, write-once-read-many storage arrays. This redundancy guarantees that even in the event of catastrophic local hardware failures or sophisticated cyberattacks, the historical record remains intact, pristine, and verifiable by external inspectors. Over time, these automated safeguards foster an internal culture of absolute scientific honesty, where researchers can focus entirely on groundbreaking discoveries without second-guessing the foundational reliability of their digital archives.
True scientific progress relies not only on the brilliance of the discovery, but on the unyielding integrity of the path traveled to reach it.
Step-by-step procedure for conducting internal compliance simulations prior to an official regulatory audit
Preparing an enterprise research facility for an external regulatory inspection requires a systematic, rehearsal-driven approach designed to stress-test every layer of data governance. Conducting proactive internal simulations helps identify hidden vulnerabilities in user permissions, data capture pipelines, and algorithmic tracking before federal inspectors arrive at the facility doors. To achieve maximum effectiveness, internal audit teams must methodically execute a structured sequence of operational evaluations that mirror real-world compliance challenges.
Precision laboratory data analysis software transforms raw numbers into shining beacons of discovery, illuminating pathways that reshape how we understand complex biological metrics. Just as vibrant broadcasts delivered through private media tv captivate audiences with crystal-clear clarity, these advanced computational platforms decode intricate scientific signals. Ultimately, mastering this sophisticated laboratory data analysis software empowers researchers to unlock brilliant breakthroughs for humanity.
- Assemble a multidisciplinary mock inspection committee comprising internal data security officers, lead bench scientists, and independent quality assurance specialists to oversee the simulation.
- Extract a randomized sampling of historical experimental datasets from the central laboratory data management system to evaluate their baseline cryptographic integrity and metadata completeness.
- Simulate unauthorized data tampering attempts by intentionally altering raw decimal values within a duplicated testing environment to verify whether anomaly detection alarms trigger appropriately.
- Review system access logs and user permission matrices to ensure that retired personnel accounts have been securely deactivated and active roles adhere strictly to the principle of least privilege.
- Interview key laboratory technicians regarding their day-to-day data entry protocols and their understanding of immediate incident reporting chains during unexpected software deviations.
- Compile all findings, detected compliance gaps, and remediation metrics into a comprehensive internal remediation report, setting strict deadlines for closing identified operational vulnerabilities.
Detection and remediation of an unverified metric modification
Proactive monitoring systems are engineered to spot irregularities instantly, transforming potential compliance disasters into routine administrative corrections. When an unauthorized adjustment bypasses standard protocol, automated diagnostics isolate the anomaly within milliseconds, notifying compliance officers with precise diagnostic telemetry. The following case study illustrates a recent incident within a pharmaceutical stability testing facility, where an unverified numerical alteration was successfully intercepted and remediated using standard enterprise protocol.
In this scenario, a junior technician attempted to manually smooth out an anomalous baseline spike in a high-performance liquid chromatography assay without documenting the justification in the electronic notebook. The proprietary software’s background integrity checker immediately flagged the broken cryptographic hash, locking the associated data file and dispatching a high-priority alert to the quality assurance dashboard. Swift intervention by the compliance team ensured that the erroneous modification was identified, investigated, and corrected before the dataset entered any official regulatory submission pipeline.
| Timestamp (UTC) | User Identification | Modified Parameter | Corrective Action Taken |
|---|---|---|---|
| 2023-10-14 14:22:05 | Tech_ID_409 (J. Doe) | Peak Area Integration Value (Col-3) | File locked automatically; cryptographic hash mismatch flagged by system daemon. |
| 2023-10-14 14:25:12 | QA_Officer_02 (M. Smith) | Incident Review & Session Termination | Forced session logout; unauthorized manual edit rolled back to original raw state. |
| 2023-10-14 15:00:40 | System_Admin_01 (A. Lee) | Role Permission Audit | Revoked manual override rights from temporary operational tier; issued compliance warning. |
Future technological integration points promise to merge augmented reality visualization with automated experimental evaluation frameworks
As modern scientific inquiry accelerates into uncharted territories, the convergence of spatial computing and automated data pipelines is fundamentally reshaping how discovery unfolds across global laboratories. Researchers are stepping beyond traditional flat-screen monitors, entering immersive digital realms where complex mathematical models and massive experimental datasets materialize directly within physical workspace environments. This evolution transcends mere convenience, marking a profound paradigm shift in how human intuition interacts with raw, high-throughput computational analytics.
Stepping inside this next-generation analytical ecosystem reveals an unprecedented level of interaction with multi-dimensional datasets. Spatial computing interfaces allow scientists to physically orbit around high-resolution holographic renderings of molecular structures, fluid dynamics, and genetic sequencing pathways. By replacing mouse-and-keyboard navigation with natural hand gestures and gaze tracking, investigators can slice through complex volumetric matrices, isolate anomaly clusters in real-time, and manipulate kinetic variables on the fly.
This tangible approach to data manipulation significantly reduces cognitive fatigue and accelerates the conceptualization of intricate chemical interactions, turning abstract algorithmic outputs into actionable, physical realities.
Emerging computational paradigms redefining high-throughput numerical scrutiny
The relentless scaling of experimental outputs demands a radical evolution in underlying algorithmic architecture to prevent computational bottlenecks. Several groundbreaking paradigms are rapidly maturing, promising to elevate analytical throughput and precision to unprecedented heights over the coming decade.
- Neuromorphic computing frameworks designed to mimic biological neural networks, drastically reducing the energy consumption required for processing massive streaming telemetry from particle colliders and genomic sequencers.
- Quantum-assisted annealing processors capable of resolving combinatorial optimization dilemmas in fractions of a second, effectively bypassing the limitations that currently stall traditional silicon-based architectures.
- Federated edge-learning nodes that allow secure, localized preprocessing of sensitive clinical data streams without ever exposing raw patient metrics to centralized servers.
- Autonomous self-optimizing code repositories that dynamically rewrite their own execution scripts in response to shifting experimental parameters and unexpected structural anomalies.
Decentralized peer-to-peer experimental verification networks
The scientific community stands on the brink of a major structural decentralization, moving away from vulnerable, centralized institutional silos toward resilient peer-to-peer verification networks. Historically, validating complex biochemical assays or materials science breakthroughs required lengthy, isolated peer-review cycles bound by geographical and organizational friction. The anticipated shift introduces cryptographic ledgers and distributed consensus mechanisms that automatically validate experimental datasets the moment they are generated by automated laboratory instruments.
When a high-throughput sequencing run concludes in a Tokyo facility, the resulting data matrices are instantly distributed across a global consortium of independent validator nodes. These nodes run automated validation scripts, checking for statistical anomalies, calibration drift, and methodological consistency against predefined compliance frameworks.
This decentralized approach effectively eliminates single points of failure, mitigates confirmation bias, and drastically curtails data tampering or selective reporting. Furthermore, smart contracts encoded within the network automatically trigger replication studies across partner laboratories using standardized robotic pipetting protocols, instantly generating cross-validated confidence scores. For instance, pharmaceutical conglomerates and academic consortia are already prototyping private distributed ledgers to verify clinical trial telemetry in real time, ensuring absolute data integrity before regulatory submission.
By distributing the burden of verification across a global, trustless digital fabric, the scientific enterprise gains an unprecedented layer of transparency and speed, transforming validation from a retroactive bottleneck into a continuous, automated property of the research lifecycle itself.
True scientific innovation accelerates when the friction between human cognition and computational infrastructure is entirely eliminated through spatial immersion and cryptographic trust.
Holographic laboratory control center spatial visualization blueprint
The architectural blueprint of an advanced holographic laboratory control center envisions a spacious, minimalist white chamber bathed in soft ambient lighting, devoid of traditional desk setups or physical monitors. Floating effortlessly in the center of the room is a multi-layered, three-dimensional holographic projection of an ongoing biochemical assay, rendered in translucent hues of cobalt blue, emerald green, and amber. The primary lead researcher stands at the edge of the interaction zone, wearing lightweight spatial computing spectacles that anchor the digital model precisely within the physical space.
With a gentle pinch of the fingers, the investigator expands a dense cluster of outlier data points, pulling a vibrant amber anomaly ring outward for closer visual inspection while holographic tooltips display real-time statistical significance vectors.
Tactile feedback simulations are seamlessly integrated through advanced ultrasonic phased arrays, generating localized air resistance and thermal cues that allow the researcher to physically feel the structural density of the numerical model as their fingertips pass through the floating particle streams. Across the virtual workspace, real-time collaborative avatars representing remote colleagues in Zurich and Boston appear as semi-transparent, life-sized figures, complete with spatial audio that tracks their exact positions around the holographic matrix.
These avatars point toward specific anomalies, co-authoring annotations in mid-air using voice-activated command macros that instantly sync with the institutional repository. The floor beneath the central projection features a subtle, dynamic grid pattern that shifts color intensity to indicate live computational load distribution across the facility’s quantum processing clusters, creating a harmonious union of physical presence, spatial depth, and blistering digital throughput.
Closure

Source: medium.com
The horizon of scientific exploration glows brighter than ever, anchored by robust digital ecosystems that turn unprecedented challenges into stepping stones for human progress. By embracing advanced technological frameworks and uncompromising regulatory standards, researchers around the globe now stand united on the edge of tomorrow. As these dynamic tools continue to evolve, they will undoubtedly empower visionary minds to decode the universe with absolute confidence, precision, and grace.
