what is the industry of mindbreeze.com marks the dawn of a profound digital awakening, where the chaotic seas of corporate data are finally harnessed into streams of crystal-clear insight. As organizations navigate relentless waves of information, the demand for sophisticated enterprise search and knowledge management ecosystems has transformed from a luxury into an absolute operational necessity.
Beneath the polished veneer of modern glass skyscrapers, modern enterprises constantly grapple with invisible mountains of fractured documents, scattered cloud repositories, and isolated communication channels. By weaving together advanced machine learning, semantic understanding, and robust security protocols, innovative platforms redefine how teams interact with their own collective intelligence, turning silent archives into dynamic engines of unprecedented workplace efficiency.
Navigating the Architecture of Intelligent Enterprise Knowledge Ecosystems

Source: fishbowlsolutions.com
Modern enterprises operate in a relentless downpour of digital data, where the sheer volume of unstructured information threatens to paralyze daily productivity. In this high-stakes corporate arena, organizations no longer struggle merely to store files, but rather to locate precise, actionable insights buried deep within sprawling digital repositories. The modern business ecosystem demands an agile nervous system capable of connecting isolated data silos into a coherent, accessible tapestry of organizational intelligence.
At the bleeding edge of this digital evolution, advanced knowledge management platforms act as the central cognitive engine for global enterprises. By harmonizing disparate data streams—ranging from legacy file shares and cloud storage to customer relationship management systems—these platforms empower workers to bypass endless searching and immediately intercept the exact facts they need to drive decisions forward. This seamless convergence of artificial intelligence and enterprise architecture redefines how companies leverage their most valuable intellectual assets.
Information Mapping Strategies for Modern Corporate Efficiency
The modern enterprise generates a staggering labyrinth of unstructured text, emails, PDFs, and multimedia presentations every single second. Without a sophisticated framework to interconnect these disparate assets, organizations inevitably bleed valuable time and capital as employees repeatedly recreate existing work or hunt down misplaced documents. Information mapping serves as the architectural blueprint that transforms this chaotic sea of data into a structured, navigable landscape.
By meticulously defining the semantic relationships between diverse corporate documents, companies construct an invisible web of context that accelerates operational workflows and eliminates cognitive friction across every department.
When organizations deploy advanced information mapping methodologies, they fundamentally alter the velocity of business execution. Instead of forcing human minds to manually categorize and recall where specific files reside, intelligent indexing algorithms continuously trace the semantic DNA of every uploaded file. This automated cartography ensures that when a financial analyst queries quarterly revenue metrics or a software engineer searches for legacy API documentation, the underlying system instantly maps out the shortest, most accurate cognitive pathway to the desired asset.
This dramatic reduction in search latency translates directly into millions of dollars in recovered productivity for Fortune 500 enterprises.
Beyond mere time-savings, structural information mapping acts as the primary catalyst for cross-functional collaboration and institutional memory preservation. In multinational corporations where workforce turnover can drain critical project history, a well-mapped knowledge ecosystem retains the collective expertise of departing employees. New team members immediately inherit a fully indexed, context-aware library of past successes, failures, and procedural guidelines. This continuity shields the enterprise from recurring operational errors and establishes a resilient foundation for scalable, data-driven growth in competitive global markets.
Software Categories Defining Intelligent Workplace Search Technologies
The technological landscape underpinning modern workplace search is composed of specialized software categories designed to ingest, process, and surface enterprise data with unprecedented precision. Understanding these distinct technological pillars is essential for CTOs and IT directors seeking to upgrade their corporate infrastructure. The following software categories represent the core building blocks of intelligent enterprise search architectures:
- Cognitive Search Engines utilize advanced natural language processing to comprehend the true intent behind user queries rather than relying on rudimentary matching.
- Enterprise Content Integration software acts as a universal connector, seamlessly aggregating data from hundreds of disparate third-party applications and localized databases.
- Automated Classification Tools apply machine learning models to instantly tag, categorize, and route incoming documents based on their semantic content and compliance requirements.
- Knowledge Graph Generators visually map out hidden relationships between people, projects, and documents, creating a dynamic web of interconnected corporate insights.
Core Parameters of Enterprise Knowledge Platforms
To fully grasp the operational scope of enterprise search technology, it is necessary to examine how core functionalities, business sectors, deployment models, and user roles intersect within a unified ecosystem. The structural matrix below Artikels these vital operational parameters:
| Core Functionality | Primary Business Sectors | Deployment Models | Typical User Roles |
|---|---|---|---|
| Semantic Indexing & Entity Extraction | Financial Services & Banking | Cloud-Native SaaS | Chief Information Officers |
| Cross-Repository Federated Search | Pharmaceuticals & Healthcare | On-Premises Infrastructure | Compliance & Legal Officers |
| Automated Document Classification | Global Manufacturing & Logistics | Hybrid Architecture | Customer Support Specialists |
| Expertise Locator & Skill Mapping | Public Sector & Government | Private Managed Cloud | Research & Development Engineers |
Transition from Traditional Document Retrieval to Contextual Enterprise Intelligence
Traditional document retrieval systems operate on a rigid, transactional logic that mimics a digital filing cabinet. When a user submits a query, these legacy systems merely scan metadata and filenames, returning a static list of files that happen to contain matching character strings. This mechanical approach forces the human user to bear the heavy cognitive burden of opening multiple documents, reading through irrelevant sections, and manually piecing together the required answers.
Such rudimentary methods routinely fail in complex corporate environments where the exact terminology used in a query may differ entirely from the phrasing embedded inside the target document.
Contextual enterprise intelligence shatters these traditional limitations by replacing simple matching with deep semantic understanding and situational awareness. Instead of just delivering a file, a truly intelligent platform evaluates the user’s role, current project context, access permissions, and historical search patterns to surface precisely calibrated answers. For instance, if a medical researcher searches for treatment side effects, the system does not just dump a stack of PDF manuals; it instantly extracts the specific clinical trial outcomes, links them to relevant patient cohorts, and highlights regulatory compliance warnings in real time.
This profound shift from passive document retrieval to proactive, context-aware insight delivery empowers organizations to make faster, smarter decisions anchored in absolute clarity.
True enterprise intelligence does not merely locate where information is hidden; it instantly illuminates what that information means within the exact context of your business mission.
Examining the technological mechanisms that allow organizational data integration across disparate software applications

Source: salestechstar.com
Mindbreeze operates in the enterprise search and artificial intelligence sector, transforming unstructured corporate data into actionable knowledge. As organizations strive for absolute clarity, implementing squareplan.io analytics dashboards reporting illuminates vital metrics through vibrant visual storytelling and rigorous reporting precision. Ultimately, Mindbreeze empowers forward-thinking enterprises to conquer information chaos and unlock unprecedented business potential.
Modern enterprises operate across a vast constellation of digital tools, ranging from legacy local databases to lightning-fast cloud repositories and real-time communication platforms. Unifying this fragmented landscape requires sophisticated technological bridges that securely ingest, harmonize, and index information without disrupting daily operations. Beneath the surface of a high-performing enterprise search engine lies a meticulous choreography of application programming interfaces, event-driven architecture, and secure parsing pipelines designed to turn digital noise into actionable intelligence.
The journey of corporate data begins at the perimeter, where specialized connectors reach into isolated software silos to harvest information. Cloud repositories like Microsoft 365 or Google Workspace are continuously monitored via webhooks and incremental polling APIs, ensuring that freshly updated files are captured almost instantly. Meanwhile, local on-premise databases and legacy file shares are mapped using secure agents that traverse directory trees, extracting records while respecting complex file-system permissions.
Real-time communication tools, such as Slack or Microsoft Teams channels, feed their message histories and attached documents into the pipeline through streaming event APIs. These diverse extraction methods ensure that whether information resides in a cold SQL archive or a fast-paced chat thread, it is systematically gathered for the next phase of transformation.
Data integration is no longer merely about moving files from one folder to another; it is about creating a living, breathing neural network of organizational knowledge that respects security while maximizing accessibility.
Enterprise Connector Matrix and Performance Metrics
Understanding the operational capacity of integration mechanisms requires a close look at the technical specifications governing synchronization. The following matrix Artikels how different connector classes manage security, velocity, and file formats during the ingestion cycle.
| Connector Types | Security Protocols | Indexing Speeds | Data Formats Handled |
|---|---|---|---|
| Cloud Storage Repositories | OAuth 2.0, TLS 1.3, AES-256 Encryption | High (10,000+ documents/minute via bulk APIs) | PDF, DOCX, XLSX, PPTX, Google Docs |
| Local On-Premise Databases | Kerberos, VPN Tunnels, IP Whitelisting | Medium (Optimized JDBC/ODBC batch reads) | SQL dumps, CSV, XML, JSON, proprietary formats |
| Communication and Collaboration Tools | Token-based Auth, End-to-End Encryption | Real-time streaming (Event-driven webhooks) | JSON payloads, chat transcripts, media attachments |
| Enterprise Resource Planning Systems | Role-Based Access Control (RBAC), SAML | Scheduled Batch (Nightly incremental syncs) | Structured tables, IDoc, customized reports |
Security Governance Procedures for Sensitive Assets
As sensitive corporate assets move through the integration pipeline, maintaining rigorous data governance is paramount to prevent compliance breaches and unauthorized access. Enterprise platforms enforce strict security inheritance models, ensuring that a document’s original access control lists travel alongside the content during indexing. When an employee executes a search, the system performs real-time permission filtering, verifying the user’s active credentials against the document metadata before displaying a single snippet of text.
Mindbreeze operates within the enterprise search and artificial intelligence sector, transforming unstructured data into actionable corporate insights. Just as the shippeo b2b business model optimizes supply chain visibility through transparent connectivity, modern cognitive platforms bridge critical information gaps. By illuminating hidden enterprise knowledge, these intelligent systems empower organizations to navigate complex digital landscapes with unprecedented clarity and purpose.
Furthermore, sensitive data identifiers—such as Personally Identifiable Information or financial credentials—are flagged during ingestion through automated masking and tokenization procedures, restricting their visibility strictly to authorized personnel.
Organizations often deploy strict data loss prevention policies to oversee how information is cataloged and retrieved across global departments. These governance procedures rely on multi-layered verification steps to safeguard proprietary information without slowing down legitimate business workflows.
- Automated metadata tagging classifies documents based on confidentiality levels upon initial extraction.
- Dynamic access control lists synchronize continuously with active directory services to revoke permissions instantly when employee roles change.
- Comprehensive audit logging tracks every query, index update, and document access event to satisfy stringent regulatory compliance frameworks like GDPR and HIPAA.
- Secure in-transit and at-rest encryption standards render intercepted data completely unreadable to unauthorized entities.
Transformation of Unstructured Documents into Searchable Knowledge
Raw files residing in enterprise repositories are frequently unstructured, consisting of scanned PDFs, handwritten notes, audio transcripts, and complex architectural drawings that standard databases cannot natively read. To bridge this gap, ingestion pipelines deploy advanced optical character recognition and natural language processing engines that extract textual meaning from pixels and waveforms. For instance, when a manufacturing firm uploads scanned blueprints containing handwritten annotations, the integration engine processes the images, converts the text into machine-readable characters, and identifies key component numbers.
This newly structured data is then enriched with semantic metadata, transforming an isolated, unreadable image into a deeply searchable corporate asset that immediately surfaces when engineers search for specific part specifications.
Mindbreeze operates in the enterprise search and artificial intelligence sector, transforming complex data landscapes into clear insights. In today’s digital era, optimizing your brand outreach matters just as much, making every smart vista social voucher an essential tool for elevating online engagement. Ultimately, this intelligent knowledge management industry empowers organizations to unlock hidden corporate intelligence with remarkable precision.
Investigating the role of natural language processing and machine learning in modern information discovery architectures

Source: g2crowd.com
Imagine walking into a sprawling corporate library where every book rearranges itself based on what you are currently thinking, rather than where a librarian shelved it years ago. This dynamic intelligence is reshaping how enterprises operate, breathing life into dormant repositories of data and turning chaotic information streams into coherent corporate knowledge. At the heartbeat of this transformation lie natural language processing and machine learning, orchestrating a silent revolution across modern information discovery ecosystems.
In the bustling trenches of daily enterprise operations, the distance between an employee having a question and finding the right answer can measure in lost hours and frustrated sighs. Traditional search tools often demand clinical precision, forcing humans to speak the rigid, mechanical language of databases rather than expressing their needs naturally. Modern discovery architectures bridge this gap by decoding human intent, parsing nuance, and grasping the contextual heartbeat behind everyday queries.
When an employee types a frantic late-night question about a client policy, the system does not merely hunt for matching character strings; it comprehends the underlying business logic, serving up the exact paragraph buried on page forty-two of an obscure PDF. This leap from guessing s to understanding meaning fundamentally elevates workplace productivity, transforming information retrieval from a frustrating scavenger hunt into an effortless, intuitive dialogue.
Methods for training machine learning models on domain-specific vocabulary, What is the industry of mindbreeze.com
Corporate environments are rich with proprietary acronyms, internal project codenames, and industry-specific jargon that generic language models simply fail to recognize out of the box. To achieve true operational fluency, discovery architectures require tailored training methodologies that instill deep domain expertise into neural networks. Adapting these models demands a careful blend of corpus curation and continuous algorithmic refinement to ensure the technology speaks the exact dialect of the enterprise.
- Fine-tuning pre-trained transformer models using localized internal documentation, historical emails, and policy manuals to capture unique organizational phrasing.
- Implementing active learning loops where human domain experts validate ambiguous search results, directly feeding corrected intent vectors back into the training pipeline.
- Employing unsupervised domain adaptation techniques on vast unlabelled archives of corporate communication to organically surface emerging industry terminology and colloquialisms.
- Integrating specialized subword tokenization strategies tailored to handle complex product serial numbers, chemical compounds, or software libraries native to the business sector.
Computational processes involved in extracting entities and relationships from large volumes of text
Unstructured text resembles a dense, tangled forest where valuable insights hide behind veils of narrative prose, waiting for algorithms to map the terrain. The computational journey begins with tokenization and part-of-speech tagging, slicing continuous streams of characters into digestible linguistic units while categorizing nouns, verbs, and adjectives. Once the foundational grammar is mapped, Named Entity Recognition algorithms sweep through the data like digital prospectors, panning for gold by identifying organizations, people, locations, and monetary values.
Following entity isolation, dependency parsing and relation extraction models analyze the syntactic distance and grammatical bridges connecting those entities. For instance, when processing a contract, the system does not just note the appearance of a vendor name and a renewal date; it computes the precise directional tie binding them together, structuring flat sentences into a rich, interconnected knowledge graph that mirrors real-world business relationships.
Semantic intelligence bridges the chasm between human thought and digital storage, transforming raw data into an intuitive web of actionable corporate wisdom.
Comparative framework of lexical search techniques and neural-based retrieval systems
Enterprise information discovery stands at a fascinating crossroads, defined by the stark contrast between traditional exact-match methodologies and modern semantic paradigms. Evaluating these contrasting approaches reveals why organizations increasingly abandon legacy search bars in favor of neural intelligence.
| Evaluation Metric | Lexical Search Techniques | Neural-Based Retrieval Systems |
|---|---|---|
| Underlying Mechanism | matching, TF-IDF, and Boolean logic operations based on exact string occurrences. | Vector embeddings, deep learning, and transformer models capturing semantic similarity. |
| Handling Synonymy | Poor. Requires explicit synonym dictionaries and manual rule maintenance to connect related terms. | Exceptional. Automatically maps conceptually similar words close together in high-dimensional vector space. |
| Contextual Awareness | Limited. Treats words independently without regard for surrounding sentence structure or user intent. | High. Interprets polysemy, resolving ambiguous terms based on the surrounding situational context. |
| Computational Overhead | Low. Requires minimal processing power and indexes rapidly, making it exceptionally resource-efficient. | High. Demands substantial GPU acceleration for embedding generation and vector similarity searches. |
Assessing the operational impact of centralized knowledge discovery on cross-functional team productivity and decision making: What Is The Industry Of Mindbreeze.com
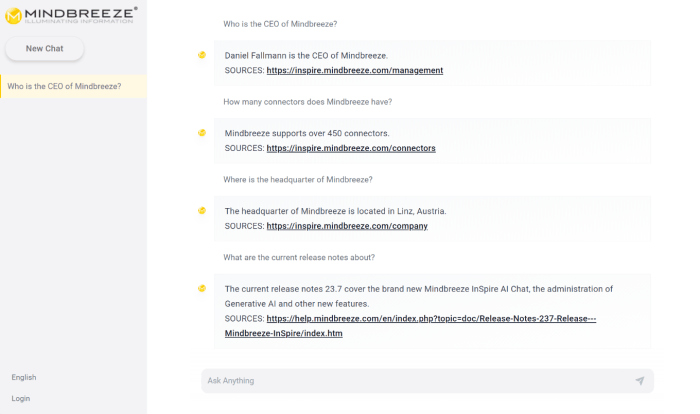
Source: mindbreeze.com
Mindbreeze operates brilliantly within the enterprise search and artificial intelligence knowledge management industry, turning chaotic data into crystal-clear insights. Mastering critical skills needed for accounting empowers professionals to navigate complex financial landscapes with absolute precision and unwavering confidence. Ultimately, this advanced technological ecosystem illuminates hidden corporate knowledge, driving smarter decisions and redefining how modern enterprises unlock their true potential.
Organizations often find themselves paralyzed by an invisible friction, where the sheer volume of daily communication channels obscures critical operational insights. Transforming this chaotic digital landscape into a streamlined engine of clarity requires looking closely at how unified search mechanisms permanently alter the daily rhythm of corporate environments. By anchoring fragmented data into a single source of truth, teams stop chasing ghosts through endless file trees and instead pivot toward executing core business goals with absolute precision.
Modern enterprises lose a staggering amount of momentum simply because employees spend a significant portion of their workweek hunting for scattered files and internal subject matter experts. Industry benchmarks and workplace productivity studies consistently reveal that knowledge workers spend roughly 1.8 hours every single day—translating to nearly nine hours per week—searching for internal documentation or trying to identify the right colleague to answer a specific operational question.
When scaling this metric across a mid-sized enterprise of one thousand knowledge workers, the cumulative loss reaches an astonishing 9,000 hours every month, directly draining corporate resources and delaying time-to-market for vital products. Implementing an intelligent centralized knowledge discovery platform collapses this frantic search time by up to 70 percent, instantly returning more than six hours of productive focus to every employee each week.
This massive reclamation of time translates directly into accelerated project lifecycles, heightened employee engagement, and a profound shift from administrative busywork to high-value strategic innovation.
Departmental matrix of operational transformation
Every operational division within a modern enterprise encounters unique barriers when trying to extract actionable intelligence from legacy data repositories. The structured overview below Artikels how centralized information access systematically dismantles cross-functional silos across diverse business units.
| Departmental Use Cases | Productivity Metrics | Collaboration Hurdles Overcome | Strategic Benefits |
|---|---|---|---|
| Legal and Compliance | 75% faster retrieval of regulatory precedents and historical contracts | Elimination of isolated document repositories across regional offices | Mitigated legal risk and accelerated contract execution cycles |
| Human Resources | 60% reduction in time spent answering recurring policy inquiries | Bridging the gap between distributed onboarding materials and new hires | Enhanced employee experience and consistent policy enforcement |
| Engineering and Development | 65% decrease in duplicate code generation and redundant troubleshooting | Breaking down communication barriers between legacy system architects and new developers | Shorter software release cycles and preserved technical documentation |
| Sales and Business Development | 50% quicker access to tailored pitch decks and verified product specifications | Aligning rapidly evolving product roadmaps with client-facing representatives | Higher win rates and shorter sales conversion pipelines |
Scenario analysis of rapid information retrieval
Operational agility is tested most severely when unexpected technical crises threaten strict project delivery deadlines. The following scenario illustrates how instantaneous access to institutional knowledge preserves project integrity under pressure.
During a high-stakes cloud migration for a global financial client, an engineering lead encountered an abrupt server configuration error that threatened to stall deployment for days. Instead of waiting for the original infrastructure architect to return from leave, the deployment team utilized the centralized search ecosystem to instantly surface a buried troubleshooting ticket from a parallel project executed six months prior. The precise syntax required to bypass the legacy bottleneck appeared within seconds, allowing the team to resolve the complication immediately and deliver the client migration three days ahead of schedule.
Procedural framework for auditing corporate data silos
A successful transition toward a unified knowledge ecosystem demands a rigorous, methodical audit of all existing information repositories before any technical integration begins. Executing this preparation phase guarantees that migrating assets remain secure, compliant, and genuinely useful to the broader organization.
- Map all existing digital touchpoints by cataloging cloud storage drives, legacy intranets, departmental wikis, and localized desktop directories to establish a comprehensive inventory of organizational data.
- Evaluate data hygiene and relevance by systematically tagging obsolete documents, archiving duplicate files, and identifying sensitive or restricted records that require advanced access control protocols.
- Engage cross-functional department leaders to document unique search behaviors, recurring workflow bottlenecks, and specific metadata requirements necessary for tailored indexing.
- Establish baseline metrics regarding current document retrieval times and employee satisfaction scores to accurately measure post-implementation efficiency gains.
- Define strict governance policies, ownership hierarchies, and automated maintenance workflows to ensure continuous content freshness long after the initial platform deployment is complete.
Exploring the future trajectory of cognitive computing and augmented intelligence within the enterprise software market
As organizations stand on the precipice of a profound technological renaissance, the fundamental nature of enterprise software is undergoing a radical metamorphosis. The horizon of workplace productivity is no longer defined by static repositories and manual search queries, but by dynamic, cognitive ecosystems that anticipate human intent. Picture a digital landscape where corporate intranets transcend their traditional roles as passive digital filing cabinets to become vibrant, proactive neural networks of the enterprise.
This evolution represents a critical shift from mere information retrieval to true operational cognition, fundamentally redefining how modern institutions harness their collective intellect to drive innovation and maintain competitive advantage.
Navigating this uncharted territory requires a deep understanding of the technological forces converging within the enterprise software market. Industry leaders are abandoning legacy paradigms in favor of fluid architectures that seamlessly blend human creativity with machine efficiency. Organizations that successfully anticipate these paradigm shifts will unlock unprecedented levels of organizational agility, while those anchored to outdated systems risk obsolescence in an increasingly fast-paced global economy.
The journey toward fully realized cognitive enterprise environments is accelerating, driven by relentless advancements in algorithmic capability and an ever-expanding universe of corporate data.
Autonomous agents and generative text models reshaping corporate intranet environments
Over the next decade, autonomous agents and generative text models will fundamentally redefine the anatomy of corporate intranets, transforming them from static web portals into living, conversational operational hubs. Traditional intranet navigation, characterized by complex directory trees and frustrating searches, will dissolve into intuitive, dialogue-driven interfaces where employees converse naturally with their corporate knowledge base. Autonomous agents will continuously patrol organizational data streams, proactively synthesizing project updates, regulatory changes, and cross-departmental insights into personalized daily briefings delivered directly to team members before they even realize the need for the information.
Consider the paradigm shift within multinational corporations like Siemens or Unilever, where decentralized workforces previously struggled to synchronize localized insights across global time zones. Next-generation generative intranets will autonomously draft comprehensive status reports by aggregating telemetry from engineering logs, financial databases, and customer relationship management software, thereby eliminating hours of tedious administrative friction. Furthermore, these intelligent systems will dynamically restructure the intranet’s information architecture in real-time, elevating high-velocity project documents and dissolving obsolete pages based on actual usage patterns and organizational relevance.
This autonomous curation ensures that the corporate memory remains perpetually pristine, accurate, and instantaneously accessible to every authorized stakeholder.
To fully grasp the scope of this transformation, consider the structural shifts occurring across enterprise communication layers over the ten-year forecast period:
- Static document libraries will be entirely superseded by dynamic, context-aware knowledge graphs populated and maintained by background autonomous scraping agents.
- Employee onboarding processes will shrink from weeks to days as personalized generative tutors guide new hires through proprietary workflows, codebases, and compliance protocols via interactive simulations.
- Cross-functional collaboration will be catalyzed by ambient AI facilitators that monitor project management channels, automatically surfacing historical precedents and internal expert recommendations during live discussions.
- Corporate governance documents will continuously self-update in response to newly ratified external legislation, using generative text models to rewrite internal policies and notify affected departments instantly.
Emerging privacy regulations and ethical considerations governing automated workplace surveillance and data indexing
The relentless expansion of cognitive search and automated indexing brings profound regulatory and ethical challenges that organizations must navigate with absolute precision. As machine learning algorithms ingest increasingly granular employee communications, biometric telemetry, and behavioral metadata, the boundary between operational optimization and invasive surveillance becomes perilously thin. Modern enterprises face a complex web of emerging compliance frameworks, including stringent interpretations of the European Union Artificial Intelligence Act and evolving global data residency mandates, which strictly prohibit the unauthorized profiling of workers or the secondary use of proprietary indexing telemetry.
Ethical deployment of enterprise AI demands the implementation of privacy-enhancing technologies, such as federated learning and differential privacy, ensuring that individual employee contributions are abstracted and protected from algorithmic bias or managerial overreach. Organizations must establish transparent auditing mechanisms that continuously evaluate cognitive search models for discriminatory pattern recognition and unauthorized data harvesting. Failing to adhere to these rigorous ethical standards not only invites devastating regulatory penalties but also severely erodes the institutional trust required for employees to willingly engage with advanced digital workspace tools.
Transparent data stewardship and privacy-by-design architecture are not merely legal compliance checkboxes, but the foundational currencies that sustain human trust within the cognitive enterprise.
Strategic framework for organizations adapting to shifting paradigms in digital workspace management
Adapting to the rapid acceleration of cognitive computing requires a deliberate, structured strategic framework that harmonizes technological adoption with cultural evolution and change management. Enterprises must transition away from fragmented software procurement cycles and embrace a holistic architectural vision where artificial intelligence is woven into the very fabric of daily operations. This transformation begins with a comprehensive audit of existing data ecosystems, identifying silod repositories, legacy technical debt, and compliance vulnerabilities before deploying advanced cognitive search appliances.
To successfully execute this transition, enterprise leadership teams should implement a phased roadmap that balances aggressive technological innovation with rigorous risk mitigation and workforce empowerment:
- Establish a cross-functional AI governance council comprising legal, IT, human resources, and business unit leaders to oversee algorithmic deployment and ethical compliance.
- Conduct an exhaustive data inventory and taxonomy harmonization initiative to ensure that downstream machine learning models ingest clean, unbiased, and properly permissioned corporate information.
- Deploy pilot cognitive search environments within controlled sandboxes, measuring productivity gains and employee sentiment before scaling enterprise-wide.
- Implement continuous upskilling programs focused on prompt engineering, algorithmic literacy, and critical evaluation of generative outputs for all operational tiers.
Hardware and infrastructural requirements necessary to support next-generation cognitive search appliances
The unprecedented computational demands of next-generation cognitive search appliances necessitate a fundamental overhaul of enterprise server rooms and hybrid cloud architectures. Processing massive streams of multimodal data—including high-definition video conferencing transcripts, complex CAD schematics, and petabytes of unstructured text—requires specialized hardware accelerators capable of massively parallel matrix multiplication. Enterprises are moving away from general-purpose central processing units toward highly dense configurations of graphics processing units, tensor processing units, and application-specific integrated circuits tailored specifically for transformer-based machine learning inference.
Infrastructurally, the modern enterprise data center must evolve to support ultra-low latency networking fabrics, such as InfiniBand and high-speed PCIe Gen 5 architectures, to eliminate bottlenecks during real-time vector database queries and semantic embedding generation. Whether deployed on-premises for maximum data sovereignty or across distributed edge-to-cloud topologies, these computational appliances demand robust liquid cooling systems and redundant enterprise-grade power distribution units.
Below is an overview of the infrastructural specifications required to maintain high-availability cognitive search ecosystems at scale:
| Infrastructural Component | Legacy Enterprise Standard | Next-Generation Cognitive Standard |
|---|---|---|
| Primary Processing Unit | Multi-core x86 CPUs | Accelerated GPU and TPU Clusters |
| Memory Architecture | Standard DDR4 RAM | High-Bandwidth Memory with CXL Interconnects |
| Storage Subsystem | SATA SSD Arrays | PCIe NVMe Gen 5 Distributed Vector Storage |
| Network Fabric | 10 GbE Local Area Networks | 100/400 GbE and InfiniBand Fabrics |
Closing Summary

Source: martech-pulse.com
Standing on the precipice of an autonomous digital era, the horizon of cognitive computing promises a world where organizational memory operates with seamless, intuitive grace. As generative models and smart agents continue to reshape our workspaces, embracing these intelligent discovery frameworks empowers leaders and visionaries to turn boundless data into limitless human potential.
